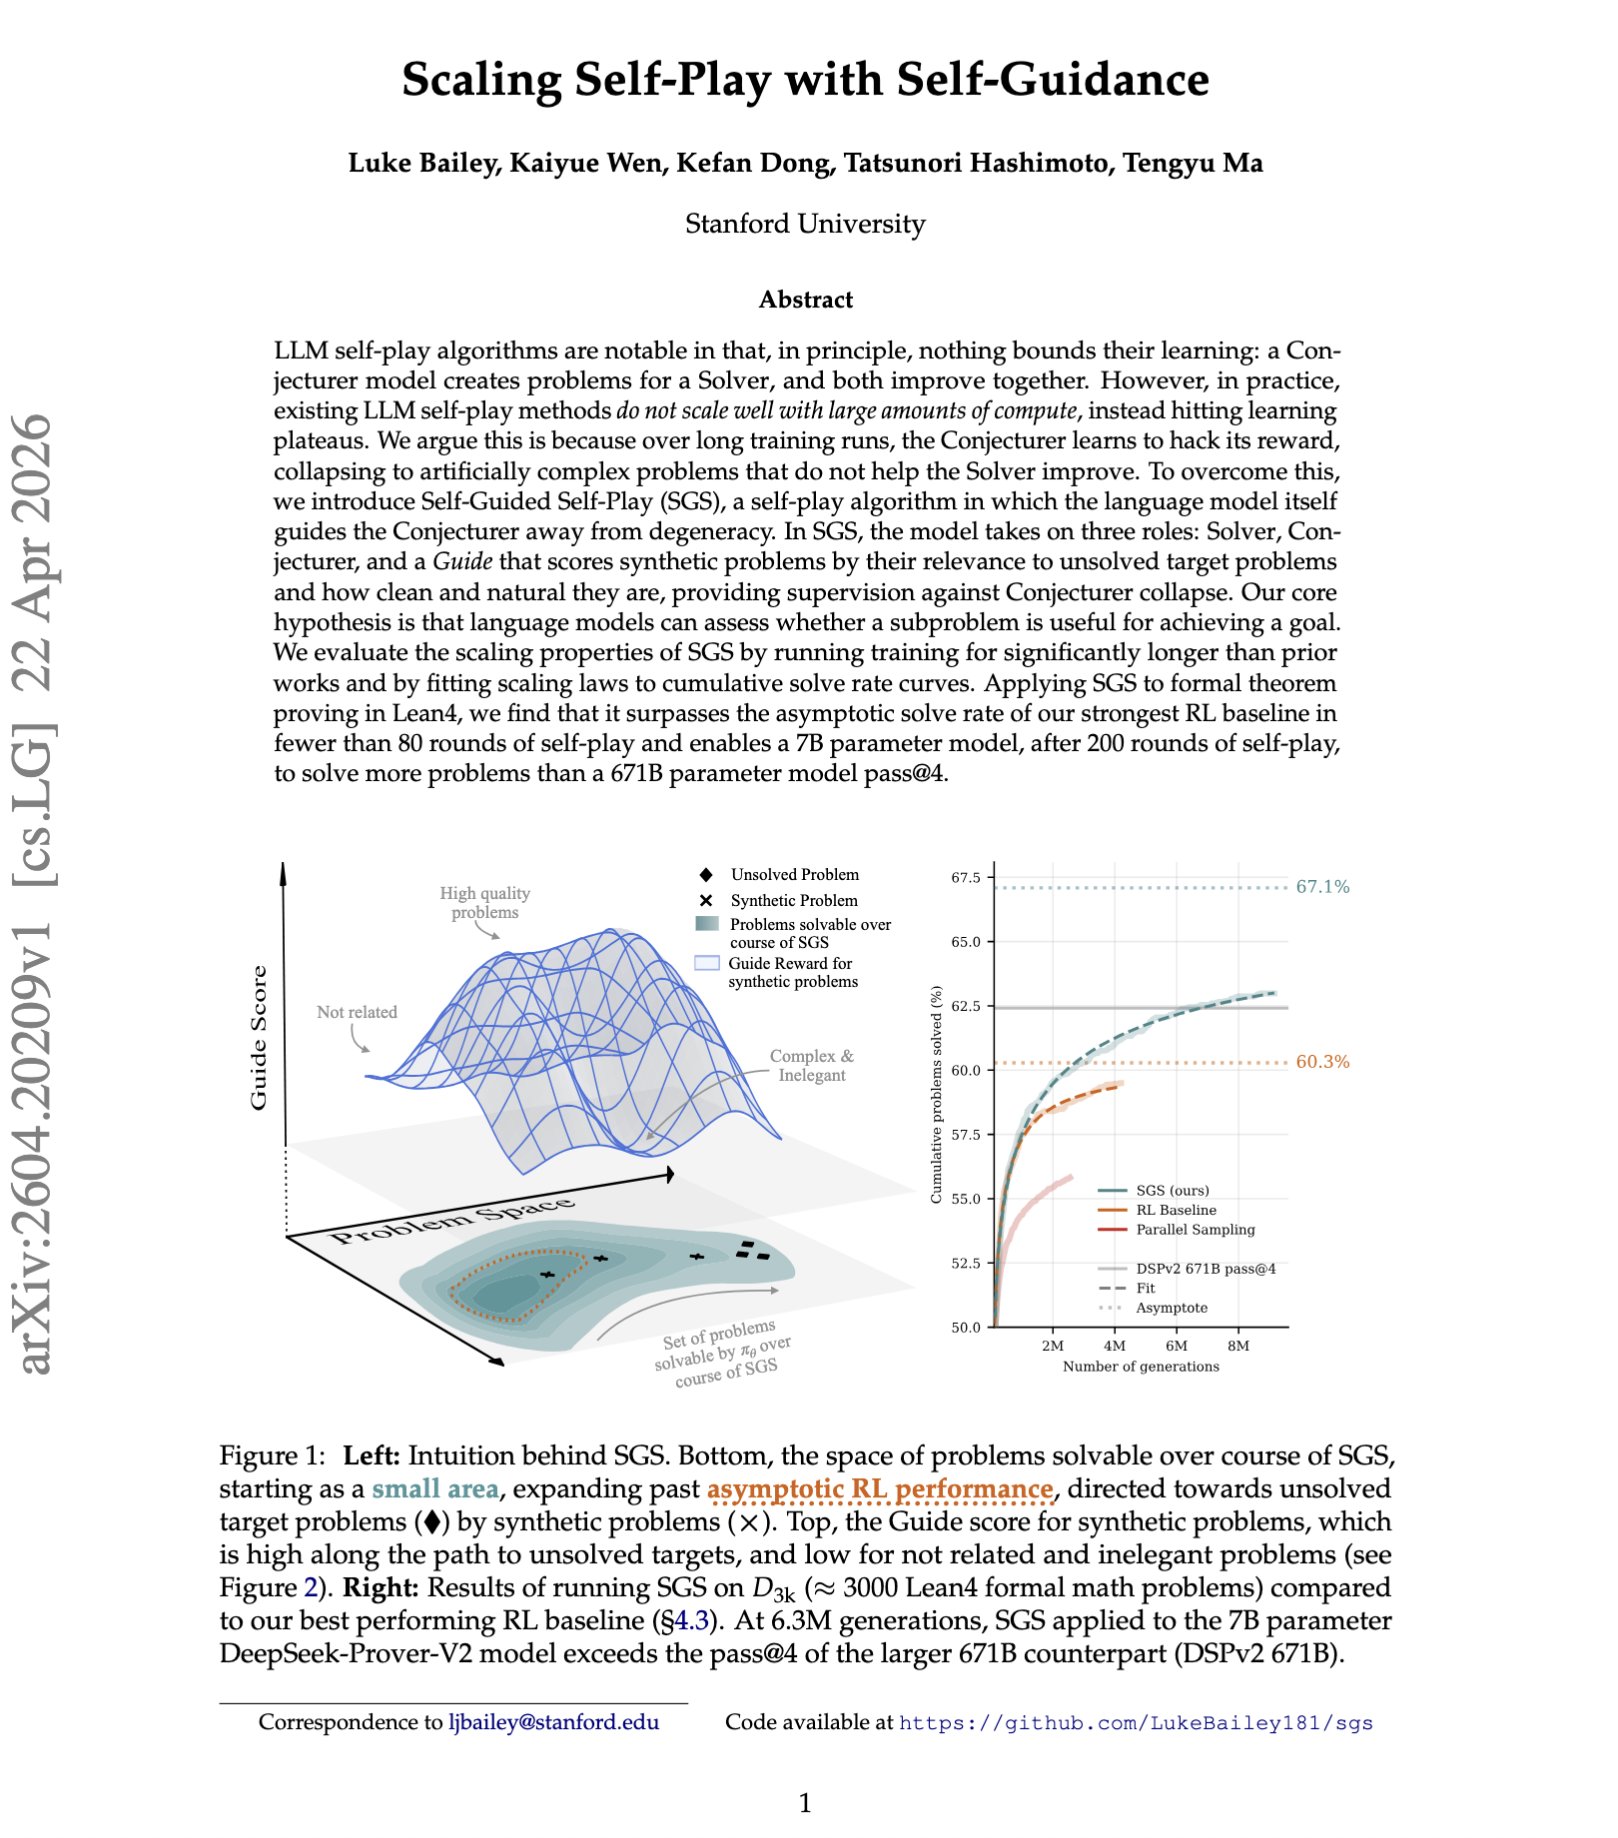
"Scaling Self-Play with Self-Guidance" The main problem with self-play for theorem proving is that generator usually learns to reward hack, which produces messy hard problems that do not help the solver. This paper suggests by adding a Guide model that scores generated
MACHINE LEARNING
-

Opus Models Outperform Haiku in Negotiations, Survey Misses It
By
–
But the quality of the model mattered a lot. In the simulated runs where Opus and Haiku models negotiated with one-another, the Opus models got substantially better deals. Interestingly, though, participants in our survey didn’t pick up on this disparity.
-
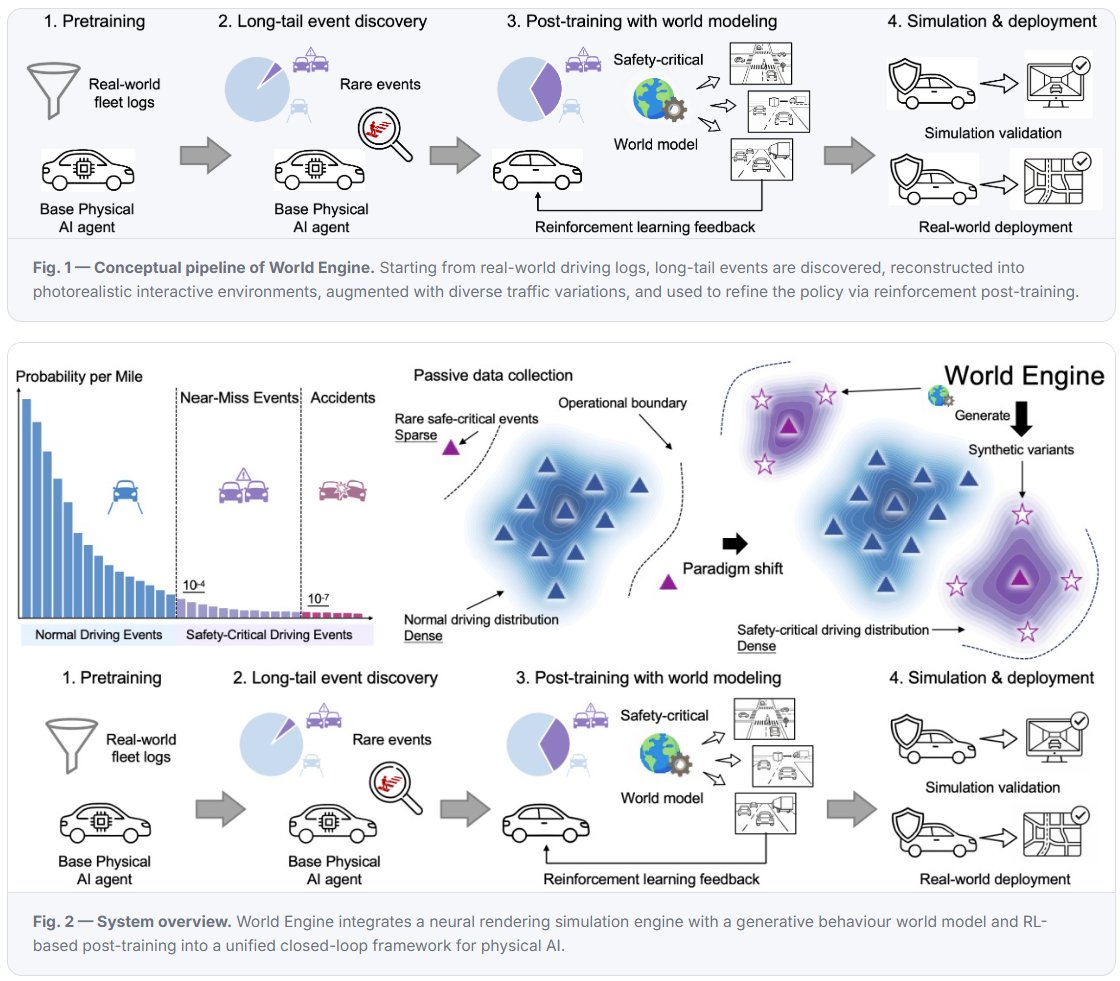
World Engine: Synthetic Edge Cases for Autonomous Driving Training
By
–
What if you could train a self-driving car on its hardest moments, not just its longest drives? OpenDriveLab, Huawei, NVIDIA & others present World Engine. Instead of just adding more miles of normal data, it generates massive volumes of synthetic edge cases—like cut-ins and
-
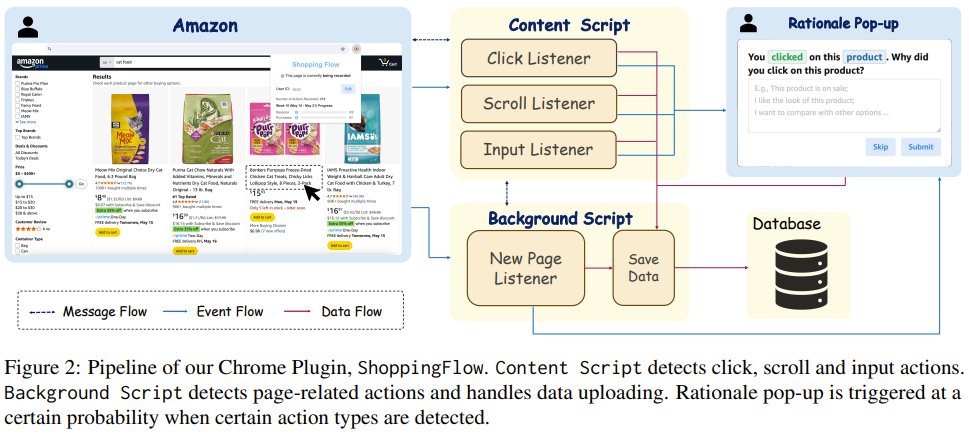
Can LLMs Truly Emulate Individual Human Online Personas?
By
–
Can LLMs truly think and act like a specific person online? Researchers from Northeastern, USC, Columbia & others present OPeRA, a new dataset that captures real people’s shopping habits—their persona, screen view, action, and internal reasoning. It’s the first public
-
Context Unrolling in Omni Models Paper
By
–
Context Unrolling in Omni Models
— AK (@_akhaliq) 24 avril 2026
paper: https://t.co/Nmyybmhv5c pic.twitter.com/7yAjjLP5xqContext Unrolling in Omni Models paper: https://
huggingface.co/papers/2604.21
921
… -

UniT: Unified Physical Language for Humanoid Policy Learning
By
–
UniT Toward a Unified Physical Language for Human-to-Humanoid Policy Learning and World Modeling paper: https://
huggingface.co/papers/2604.19
734
… -
Sim2Reason Trains LLMs on Physics Without Human Annotation
By
–
AI can now learn physics the way Newton did — by experiencing it.
— AlphaSignal AI (@AlphaSignalAI) 24 avril 2026
Training LLMs on physics problems hits a wall fast.
Human-labeled question-answer data is scarce and narrow.
Less than 2% of DeepSeek-R1's training pairs touch STEM.
Sim2Reason skips annotation entirely.… pic.twitter.com/SSPs33du51AI can now learn physics the way Newton did — by experiencing it. Training LLMs on physics problems hits a wall fast. Human-labeled question-answer data is scarce and narrow. Less than 2% of DeepSeek-R1's training pairs touch STEM. Sim2Reason skips annotation entirely.
-

WorldMark: Unified Benchmark Suite for Interactive Video World Models
By
–
WorldMark
— AK (@_akhaliq) 24 avril 2026
A Unified Benchmark Suite for Interactive Video World Models
paper: https://t.co/41TkUsfIYC pic.twitter.com/OxO7Wf8z4UWorldMark A Unified Benchmark Suite for Interactive World Models paper: https://
huggingface.co/papers/2604.21
686
… -

Memory Intelligence Agent: AI Learning from Experience Like Humans
By
–
What if an AI could learn from its own memory like a human, getting smarter with every task? Researchers from East China Normal University, Shanghai AI Lab, and others present MIA: the Memory Intelligence Agent. It uses a "Manager-Planner-Executor" team. The Manager stores
