DeepSeek-V4: Towards Highly Efficient Million-Token Context Intelligence Paper: https://
huggingface.co/deepseek-ai/De
epSeek-V4-Pro/blob/main/DeepSeek_V4.pdf
…
MACHINE LEARNING
-

DeepSeek-V4 Research Paper Released Focusing on Million-Token Context Efficiency
By
–
-

DeepSeek-V4 Technical Report Details New Architecture and Optimizer
By
–
DeepSeek-V4 tech report is here! The team replaced standard attention with a hybrid compressed system and used a new Muon optimizer to make training faster and more stable. They also introduced improved layer connections to help the model handle complex reasoning more
-
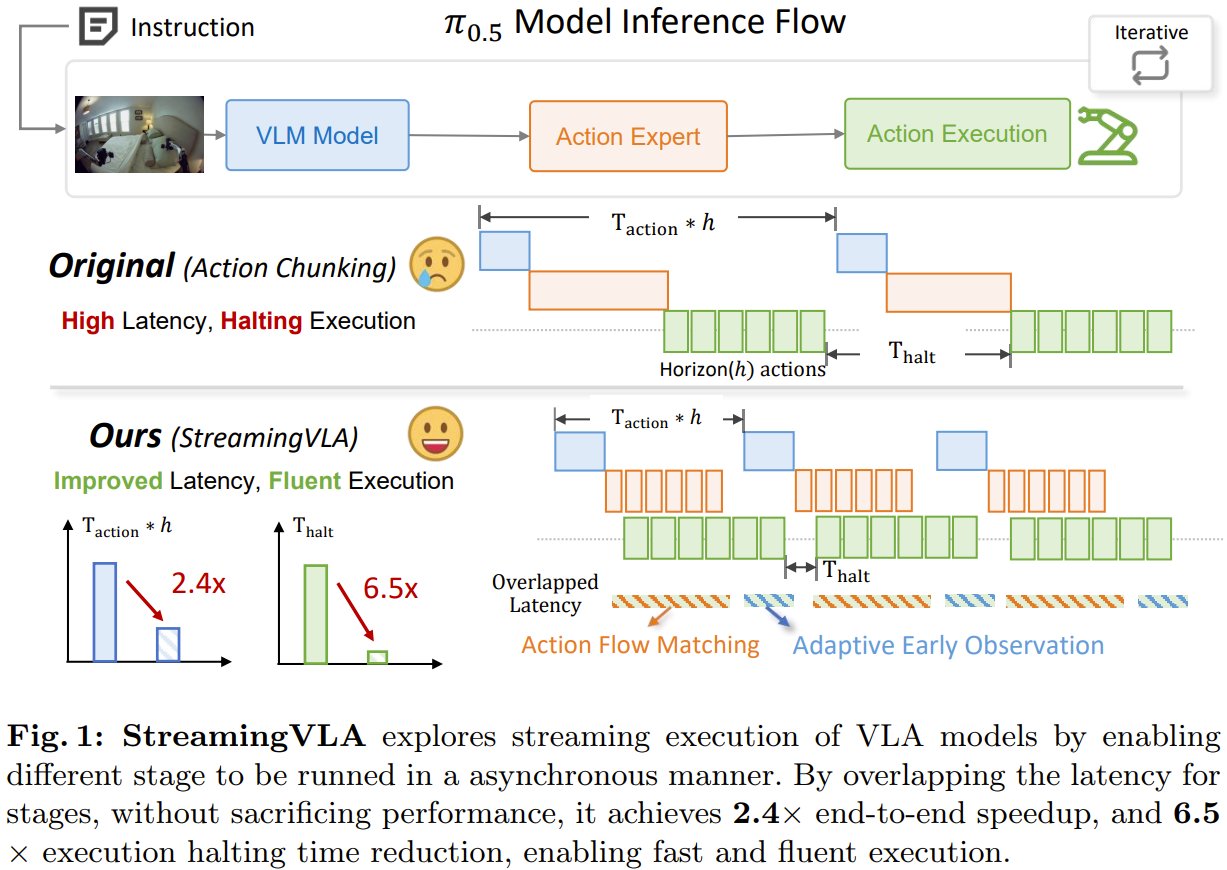
StreamingVLA: Parallel Vision-Language-Action for AI Robots
By
–
What if your AI robot could think and act simultaneously, instead of waiting between steps? Researchers from Tsinghua University & Lenovo present StreamingVLA. The new method lets a vision-language-action model run its "see," "think," and "act" stages in parallel, like a
-
ChatGPT 5.5 Pro generates chess PDF with quiescence search analysis and QR code
By
–
ChatGPT 5.5 Pro (Extended) creates a multi-page PDF report about a chess game it simulates to test its own reimplementation of quiescence search, with its analysis of questionable moves and a QR code for viewing the game in the lichess PGN viewer
-
Deep Reinforcement Learning for Robot Navigation in ROS Gazebo
By
–
Deep Reinforcement Learning for Mobile Robot Navigation Plan: ROS Gazebo Simulator. Using Twin Delayed Deep Deterministic Policy Gradient TD3 Neural Network. A Robot Learns to Navigate to a Random Goal Point in a Simulated Environment While Avoiding Obstacle! #BigData #Analytics
-

GPT-5.5 XHIGH optimizes DeepSeek 4 Flash on 4x DGX Sparks
By
–

GPT-5.5 XHIGH is working hard right now to make vLLM runs DeepSeek 4 Flash on 4x DGX Sparks It got it to load, then had it answer cohesively on the 4x Sparks (though a tad too slow) Now, it optimizes it Letting this run overnight (in an engineered-harness specifically for it)
-
AI evolves faster than language using it as substrate
By
–
Language evolved faster than vision because it used it as its substrate. Likewise, AI is evolving faster than language because it uses it as its substrate.
-

Local RAG AI Stack Overview on RTX 3070 8GB
By
–

Here is a high-level overview of my Local RAG / AI Knowledge Stack All hosted locally on a single RTX 3070 8GB btw Who is interested in a more in-depth breakdown? What would you like for it to cover?
-
Best AI Experts and News Resources Listed
By
–
The best in AI are in this list: https://
x.com/i/lists/195353
6336675365173
… And my AI finds the best in AI here: https://
alignednews.com/ai -
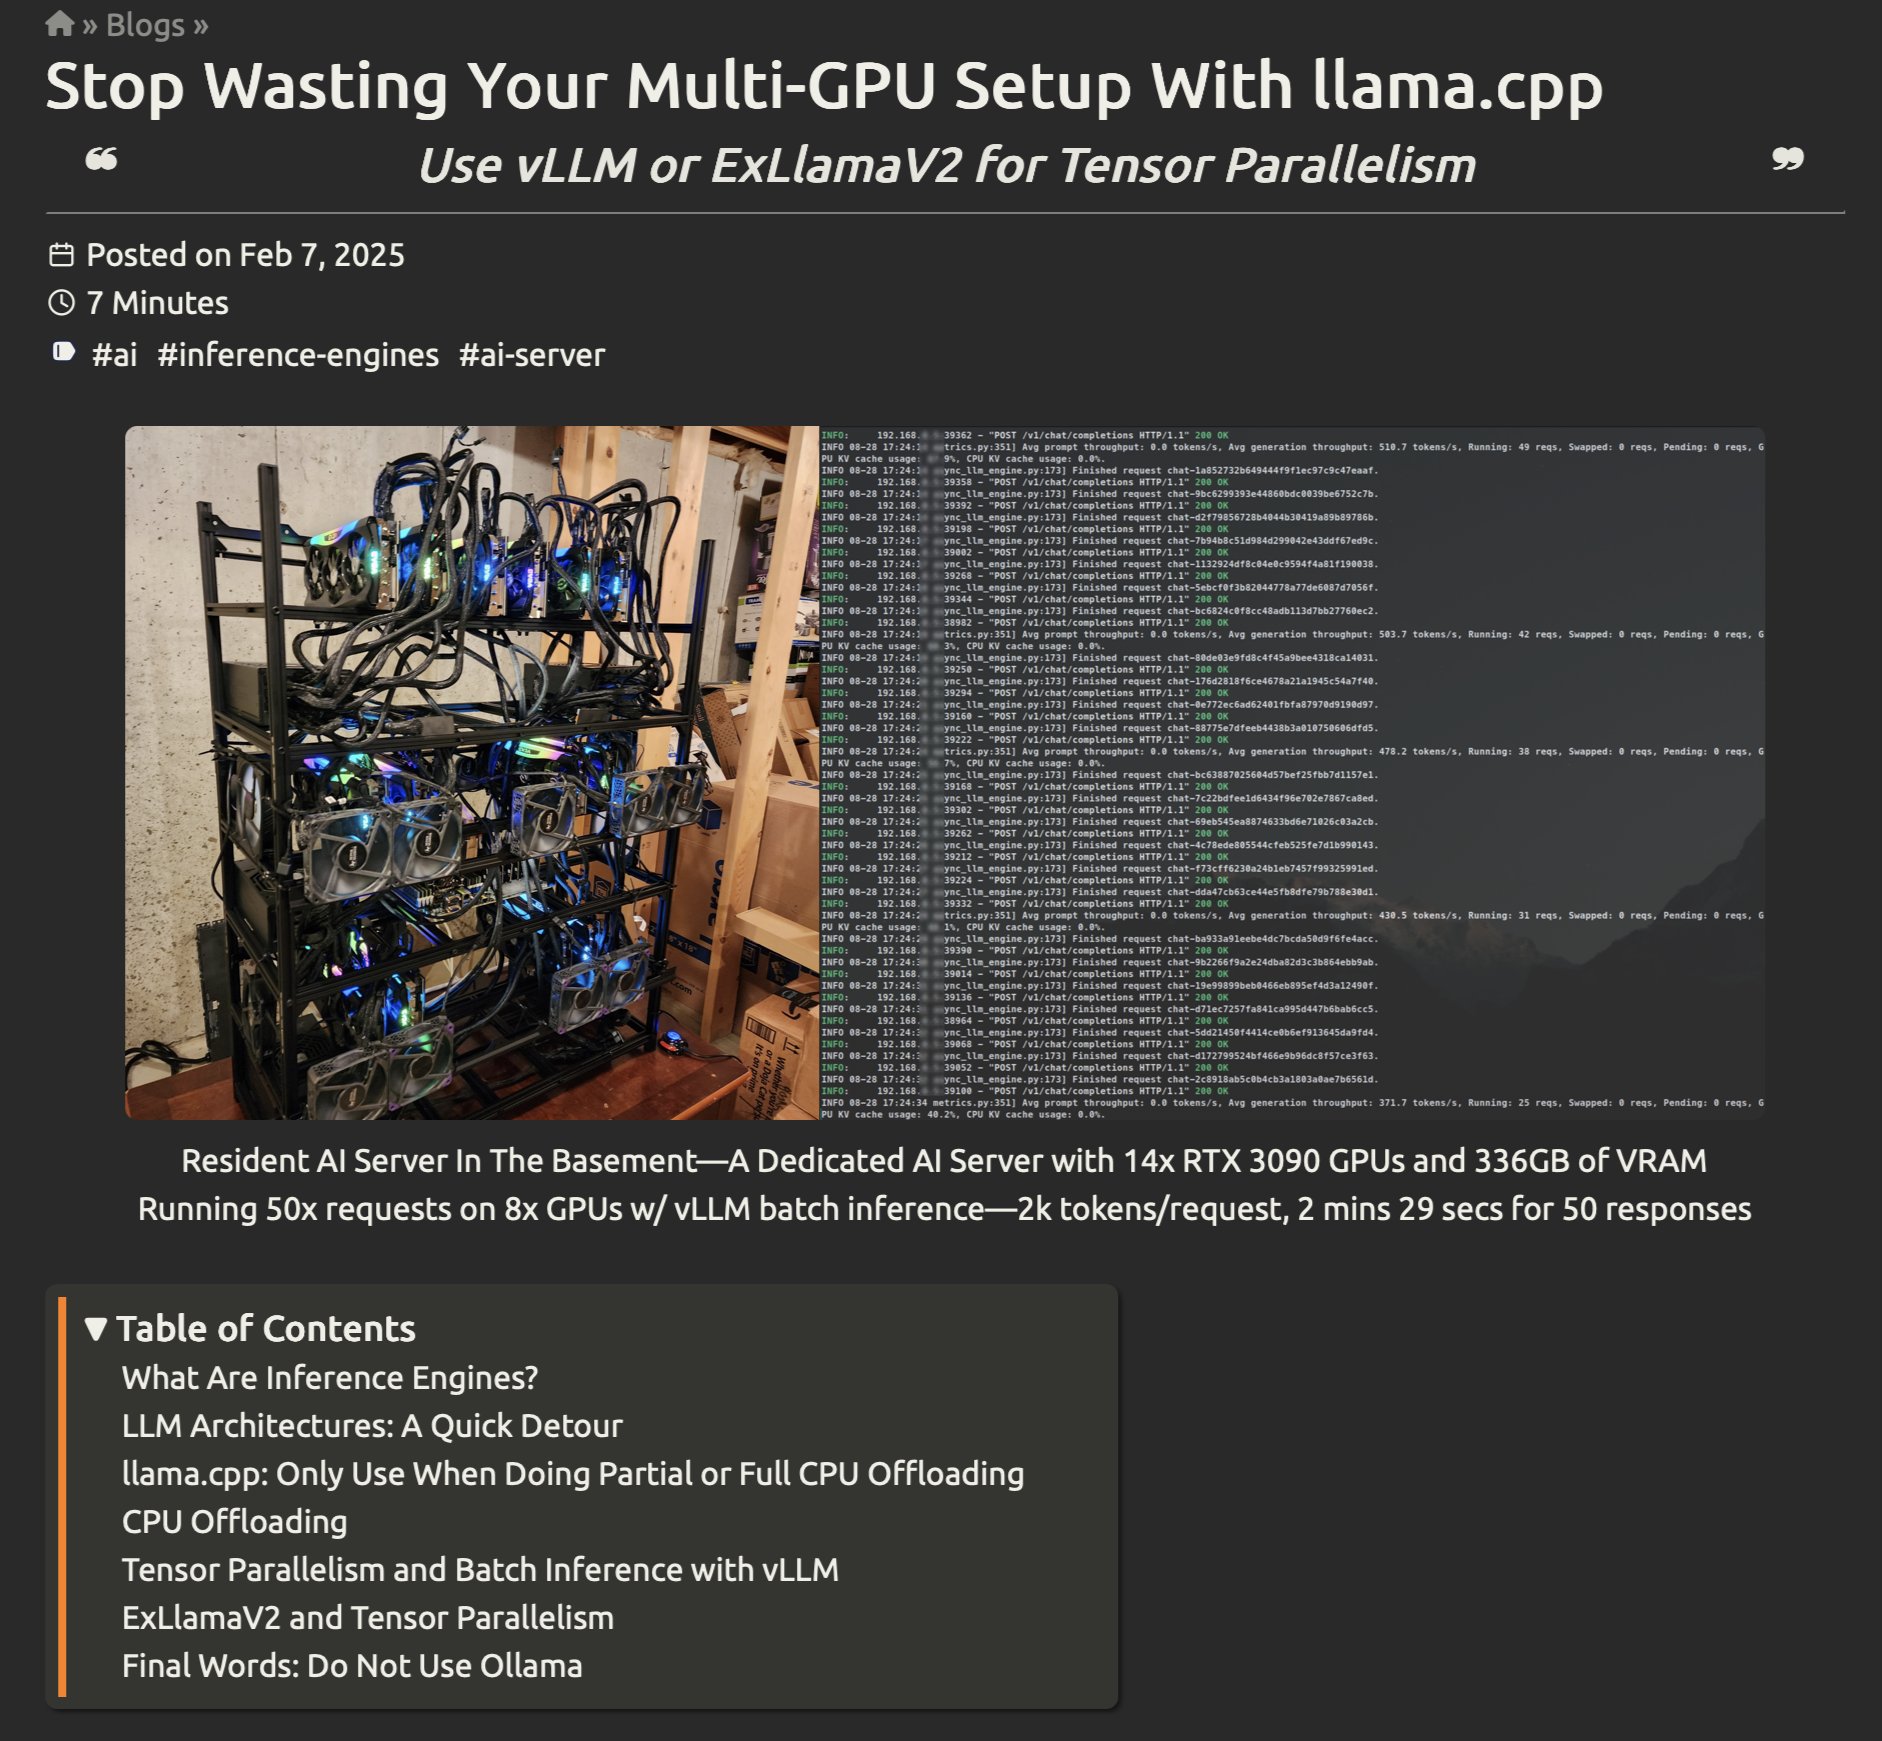
Multi-GPU LLMs slow? Use the right Inference Engine for Tensor Parallelism
By
–
I keep seeing the same thing People with multi-GPUs wondering why local LLMs have slow performance …Because you're using the wrong Inference Engine and it's processing things one GPU at a time This old writeup of mine covers Inference Engines & Tensor Parallelism, go read it