The Arxiv for the new Decoupled DiLoCo paper is now up:
MACHINE LEARNING
-
Joint Embedding Architectures Outperform Generative Models for Sensor Data
By
–
What proves that the generative approach is wrong is oodles of empirical results showing the superiority of joint embedding architectures over generative ones (based on reconstruction) for natural sensor data (e.g. images and video). It's not just for self-supervised learning
-
Large Concept Models: AI Architecture Beyond Token-Level Processing
By
–
Large Concept Models (LCM): A New Frontier in AI Beyond Token-Level Language Models https://
linkedin.com/pulse/large-co
ncept-models-lcm-new-frontier-ai-beyond-giuliano-liguori–dnj3f
… via @ingliguori -

Qwen3 27B Runs Locally Rivaling Claude Opus for Coding Tasks
By
–
This is where we are right now. And i’m not gonna lie it feels pretty magical Qwen3.6 27B running inside of Pi coding agent via Llama.cpp on the MacBook Pro For non-trivial tasks on the @huggingface codebases, this feels very, very close to hitting the latest Opus in Claude
-

AiScientist Runs Autonomous ML Research for Hours or Days
By
–
The best AI research agent doesn't think harder — it just never forgets. A new paper introduces AiScientist, a system that runs ML research autonomously for hours or days. Setup, coding, experiments, debugging. The full loop, unattended. The core idea is simple: Instead of
-
AI Model Limitations and Human-AI Collaboration in Coding
By
–
You're right It's mostly bs Until the models are smart enough to see the grand scheme of things AND have architectural understanding AND taste, it doesn't work A human telling an AI what to code or edit though yes that works great
-
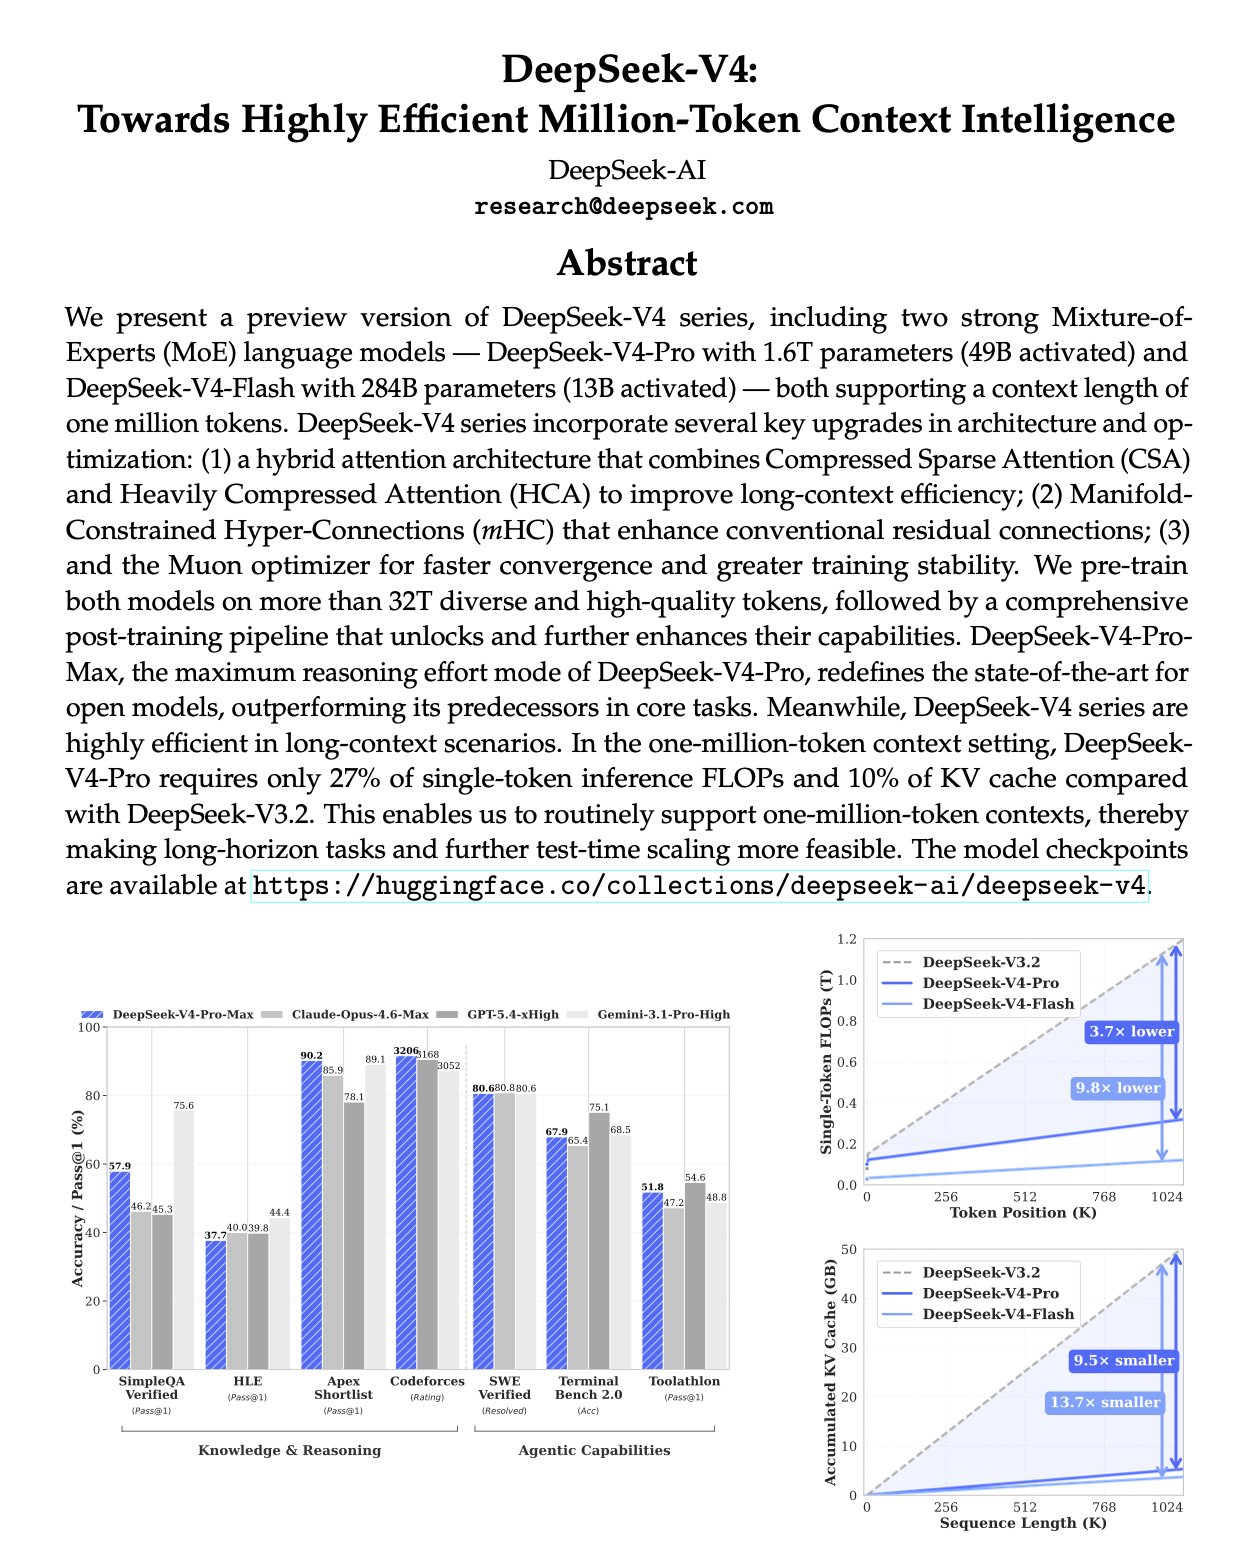
DeepSeek V4: Largest Open-Source MoE Model Released
By
–
DeepSeek just dropped V4! Two open-source MoE models with 1M context windows under MIT license. DeepSeek-V4-Pro: 1.6T total parameters (49B active per token), pre-trained on 33T tokens. This makes it the largest open-source model available – bigger than Kimi K2.6 (1.1T) and
-

DeepSeek-V4 Introduces Advanced Attention Techniques for Million Token Context
By
–
"DeepSeek-V4 Technical Report" A 58 page paper with brand new attention techniques: Heavily Compressed Attention (HCA) & Compressed Sparse Attention (CSA). This hybrid attention setup enables V4 to hit 1 million context. DeepSeek-V4-Pro is now the largest OS model ever, with
-
DeepSeek V4 Paper Release Announcement
By
–
Check out the full paper here! https://
alphaxiv.org/abs/deepseek-v4 -

Cross-Architecture Distillation Recipe for Mamba Models
By
–
Attention to Mamba: A Recipe for Cross-Architecture Distillation Paper: https://
arxiv.org/abs/2604.14191