Sparser, Faster, Lighter Transformer Language Models
MACHINE LEARNING
-
AI Autonomy Levels: Presets, Refined Inputs, and Evaluated Outputs
By
–
increasing levels of autonomy: /skill: preset prompts /plan: human-refined inputs /goal: AI-evaluated outputs
-

ELF: Embedded Language Flows — arXiv paper
By
–
ELF: Embedded Language Flows Hu et al.: https://
arxiv.org/abs/2605.10938 #ArtificialIntelligence #AIAgents -

Embedded Language Flows: New AI Agent Research
By
–
ELF: Embedded Language Flows Hu et al.: https://
arxiv.org/abs/2605.10938 #ArtificialIntelligence #AIAgents -
OpenAI confirms Study Mode still accessible via slash commands
By
–
OpenAI contacted me to say “Study Mode is still live and accessible via /study and /learn shortcuts” so that’s good, although the official study mode page doesn’t mention that. (I don’t think slash commands are a natural thing for the vast majority of people).
-
Debating the existence of world models in AI
By
–
that’s not the logic per se there is no deep comprehension because there are no world models recombination of partial regurgitation is what they do instead
-
Technical updates to AI model evaluation harness
By
–
apparently there's been a lot of bug fixes in the harness but the underlying model has not changed. so a bit of both users + software (but the model is the same)
-
Debating Geoffrey Hinton’s Perspective on LLM Memorization Processes
By
–
this quote does not mean the same thing. Hinton is trying to saddle me with saying the memorization is the only operative process and I never said that and don’t say it in this quote. there is not “that is all” here putting together bits of text is not the same pure
-
Depth Anything V2: Technical Capabilities and Model Specifications
By
–
-
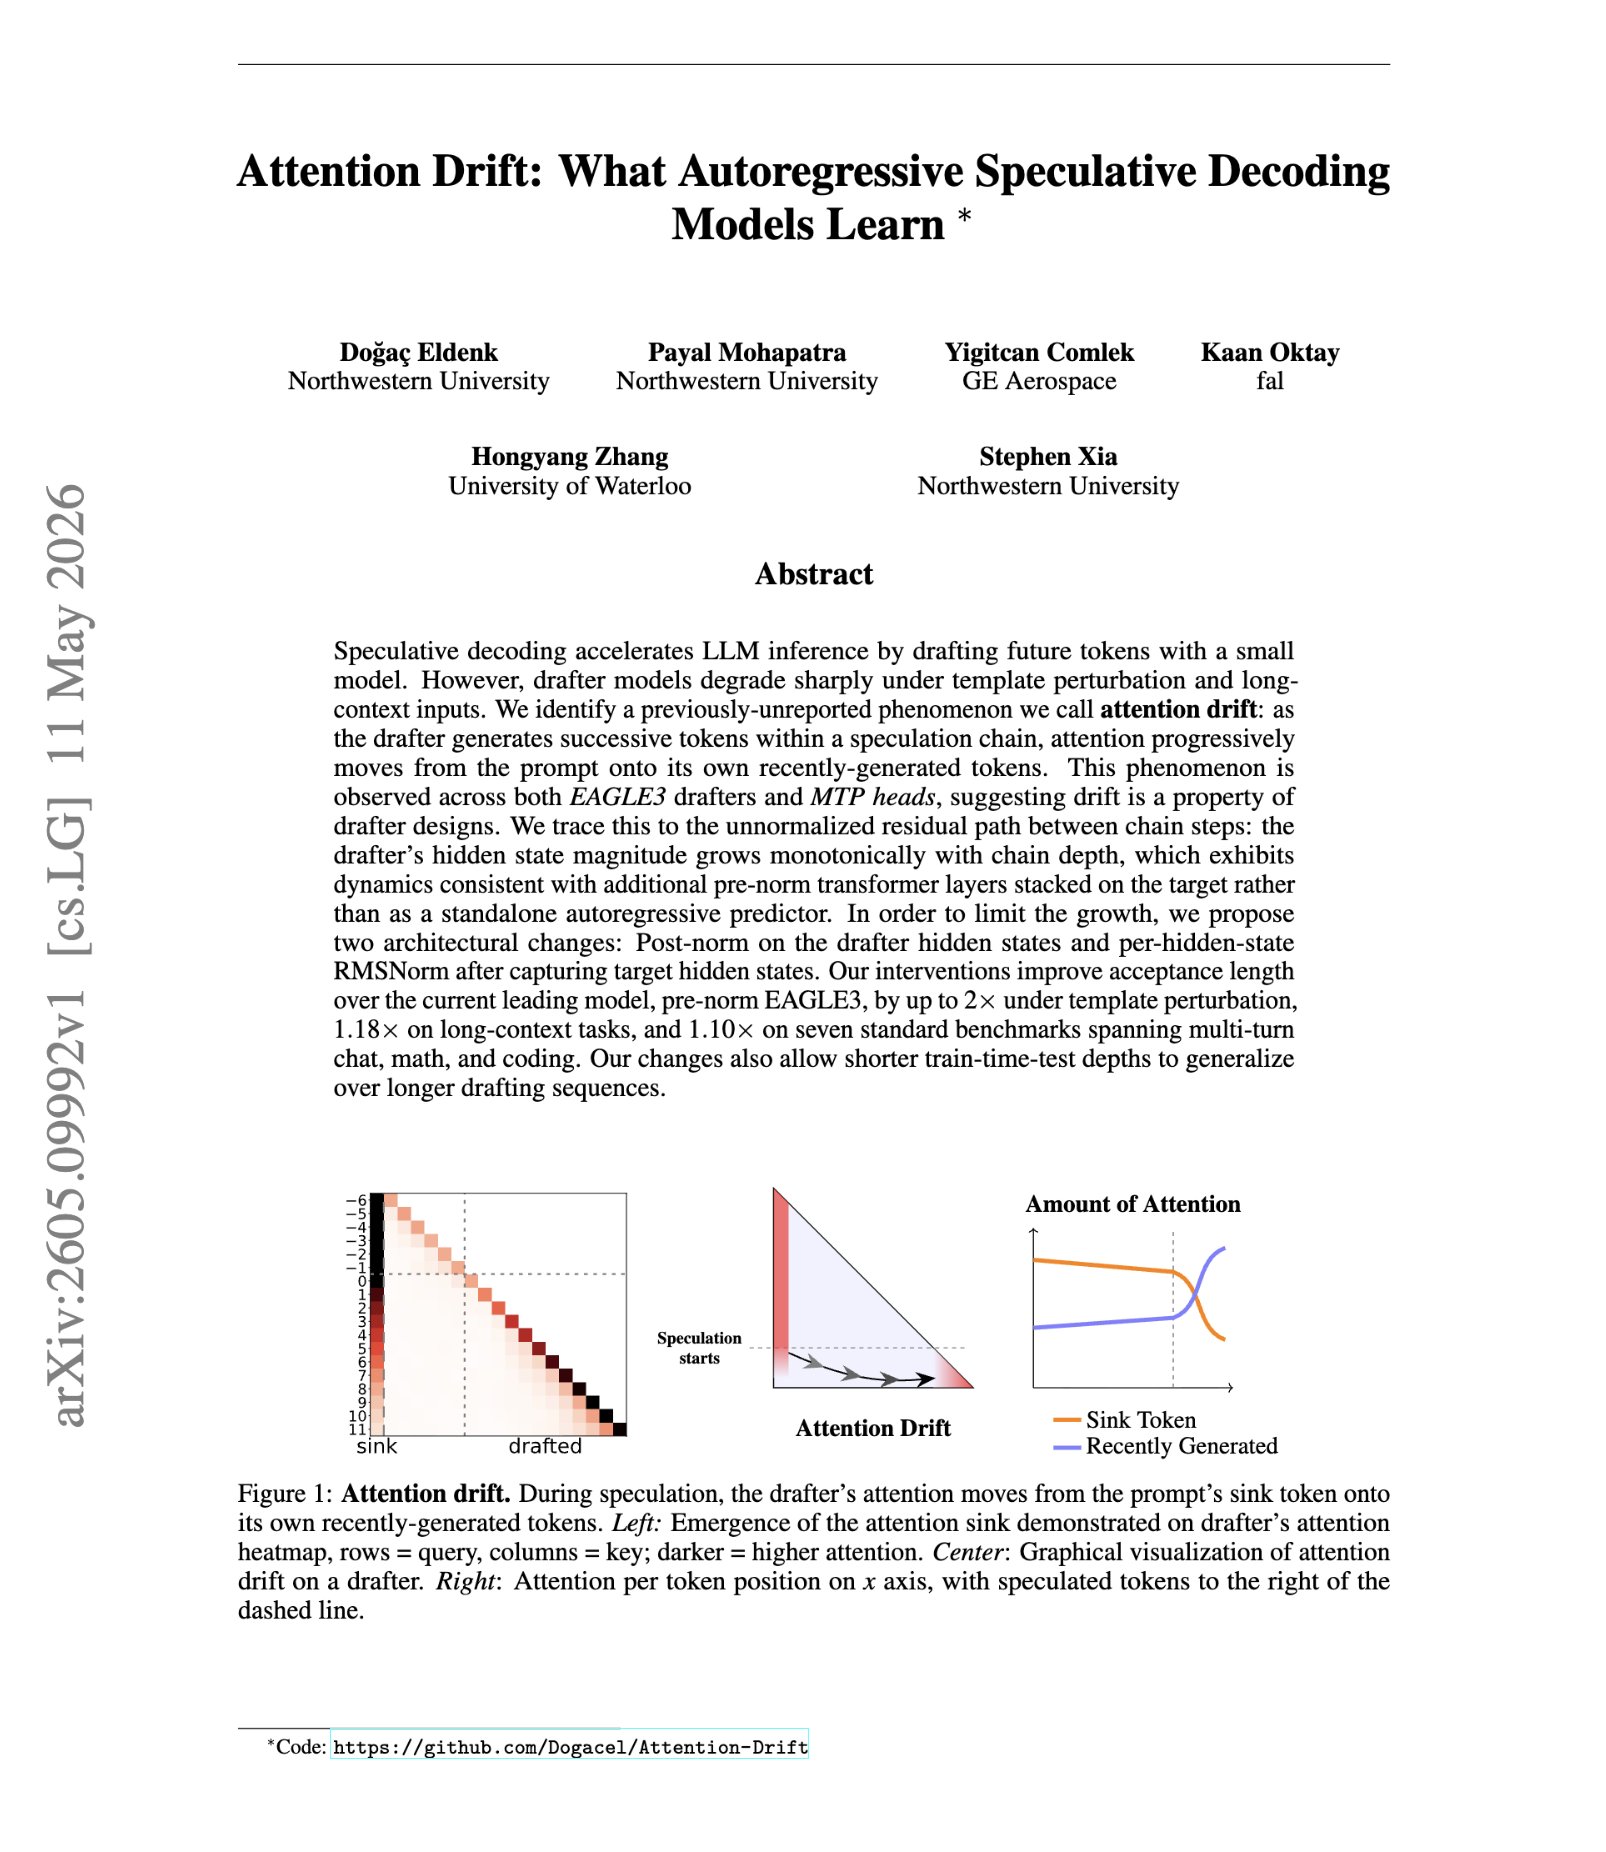
Technical Analysis of Attention Drift in Speculative Decoding Models
By
–
“Attention Drift: What Autoregressive Speculative Decoding Models Learn” Speculative decoding makes LLM inference faster, but drafters break under small template changes and long context. But why? This paper shows that as the drafter predicts more tokens, its attention drifts