It buys real time data from Verizon and other phone companies. I asked someone on the team years ago about just this.
SECURITY
-
Bioweapon Concerns and AI Safety Risks Discussion
By
–
they have themselves raised specific concerns about bioweapons and yet blundered forth. i do think they are the greatest liability.
-
AI Models Economic Incentives Bioweapons Risk
By
–
1. I said partly, to be clear. 2. as noted, he could e.g., sign off on a version of GPT that enables a massive bioweapons attack that kills say 1%+ of the population. and might well sign off to try to make economic ends meet, despite the costs.
-
CISOs Taking OT/IT Convergence More Seriously
By
–
More CISOs are looking at OT/IT convergence seriously. CC: @IIoT_World @CRudinschi @agentic_factory @mclynd @sarbjeetjohal @embedded_comp
-

pi-share-hf: Share Coding Agent Sessions Safely Online
By
–
i'm about to put the most embarassing data on the internet. hope i don't get pwned. you can do so too! updated pi-share-hf, share your coding agent sessions with the world, savely (fingers crossed, read the README.md in full) github.com/badlogic/pi-share…
→ View original post on X — @clementdelangue, 2026-04-06 12:25 UTC
-

Google DeepMind reveals AI agents vulnerable to hidden manipulation attacks
By
–

Interesting: Google DeepMind shows that AI agents are already being systematically manipulated through hidden, human-invisible attack vectors embedded in web content, images, and documents. Current defenses fail to detect or prevent these attacks, creating a large, largely invisible security risk across agentic systems. Alex Prompter (@alex_prompter) 🚨 BREAKING: Google DeepMind just mapped the attack surface that nobody in AI is talking about. Websites can already detect when an AI agent visits and serve it completely different content than humans see. > Hidden instructions in HTML. > Malicious commands in image pixels. > Jailbreaks embedded in PDFs. Your AI agent is being manipulated right now and you can't see it happening. The study is the largest empirical measurement of AI manipulation ever conducted. 502 real participants across 8 countries. 23 different attack types. Frontier models including GPT-4o, Claude, and Gemini. The core finding is not that manipulation is theoretically possible it is that manipulation is already happening at scale and the defenses that exist today fail in ways that are both predictable and invisible to the humans who deployed the agents. Google DeepMind built a taxonomy of every known attack vector, tested them systematically, and measured exactly how often they work. The results should alarm everyone building agentic systems. The attack surface is larger than anyone has publicly acknowledged. Prompt injection where malicious instructions hidden in web content hijack an agent's behavior works through at least a dozen distinct channels. Text hidden in HTML comments that humans never see but agents read and follow. Instructions embedded in image metadata. Commands encoded in the pixels of images using steganography, invisible to human eyes but readable by vision-capable models. Malicious content in PDFs that appears as normal document text to the agent but contains override instructions. QR codes that redirect agents to attacker-controlled content. Indirect injection through search results, calendar invites, email bodies, and API responses any data source the agent consumes becomes a potential attack vector. The detection asymmetry is the finding that closes the escape hatch. Websites can already fingerprint AI agents with high reliability using timing analysis, behavioral patterns, and user-agent strings. This means the attack can be conditional: serve normal content to humans, serve manipulated content to agents. A user who asks their AI agent to book a flight, research a product, or summarize a document has no way to verify that the content the agent received matches what a human would see. The agent cannot tell the user it was served different content. It does not know. It processes whatever it receives and acts accordingly. The attack categories and what they enable: → Direct prompt injection: malicious instructions in any text the agent reads overrides goals, exfiltrates data, triggers unintended actions → Indirect injection via web content: hidden HTML, CSS visibility tricks, white text on white backgrounds invisible to humans, consumed by agents → Multimodal injection: commands in image pixels via steganography, instructions in image alt-text and metadata → Document injection: PDF content, spreadsheet cells, presentation speaker notes every file format is a potential vector → Environment manipulation: fake UI elements rendered only for agent vision models, misleading CAPTCHA-style challenges → Jailbreak embedding: safety bypass instructions hidden inside otherwise legitimate-looking content → Memory poisoning: injecting false information into agent memory systems that persists across sessions → Goal hijacking: gradual instruction drift across multiple interactions that redirects agent objectives without triggering safety filters → Exfiltration attacks: agents tricked into sending user data to attacker-controlled endpoints via legitimate-looking API calls → Cross-agent injection: compromised agents injecting malicious instructions into other agents in multi-agent pipelines The defense landscape is the most sobering part of the report. Input sanitization cleaning content before the agent processes it fails because the attack surface is too large and too varied. You cannot sanitize image pixels. You cannot reliably detect steganographic content at inference time. Prompt-level defenses that tell agents to ignore suspicious instructions fail because the injected content is designed to look legitimate. Sandboxing reduces the blast radius but does not prevent the injection itself. Human oversight the most commonly cited mitigation fails at the scale and speed at which agentic systems operate. A user who deploys an agent to browse 50 websites and summarize findings cannot review every page the agent visited for hidden instructions. The multi-agent cascade risk is where this becomes a systemic problem. In a pipeline where Agent A retrieves web content, Agent B processes it, and Agent C executes actions, a successful injection into Agent A's data feed propagates through the entire system. Agent B has no reason to distrust content that came from Agent A. Agent C has no reason to distrust instructions that came from Agent B. The injected command travels through the pipeline with the same trust level as legitimate instructions. Google DeepMind documents this explicitly: the attack does not need to compromise the model. It needs to compromise the data the model consumes. Every agentic system that reads external content is one carefully crafted webpage away from executing attacker instructions. The agents are already deployed. The attack infrastructure is already being built. The defenses are not ready. — https://nitter.net/alex_prompter/status/2040731938751914065#m
→ View original post on X — @kimmonismus, 2026-04-06 11:04 UTC
-
IMMACULATE: Auditing LLM Providers with Verifiable Computation
By
–
Can you really trust your black-box LLM provider with correct inference and honest billing? Researchers from NUS, NTU, and UC Berkeley introduce IMMACULATE. This practical auditing framework uses verifiable computation to randomly check a small fraction of LLM requests. It detects economically motivated cheats like model substitution, quality degradation, and token overbilling without needing trusted hardware or internal model access. IMMACULATE reliably distinguishes honest vs. malicious LLM execution in dense and MoE models, adding less than 1% throughput overhead. IMMACULATE: A Practical LLM Auditing Framework via Verifiable Computation Paper: arxiv.org/pdf/2602.22700 Code: github.com/guo-yanpei/Immacu… Our report: mp.weixin.qq.com/s/WR9nXudXT… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-06 05:13 UTC
-
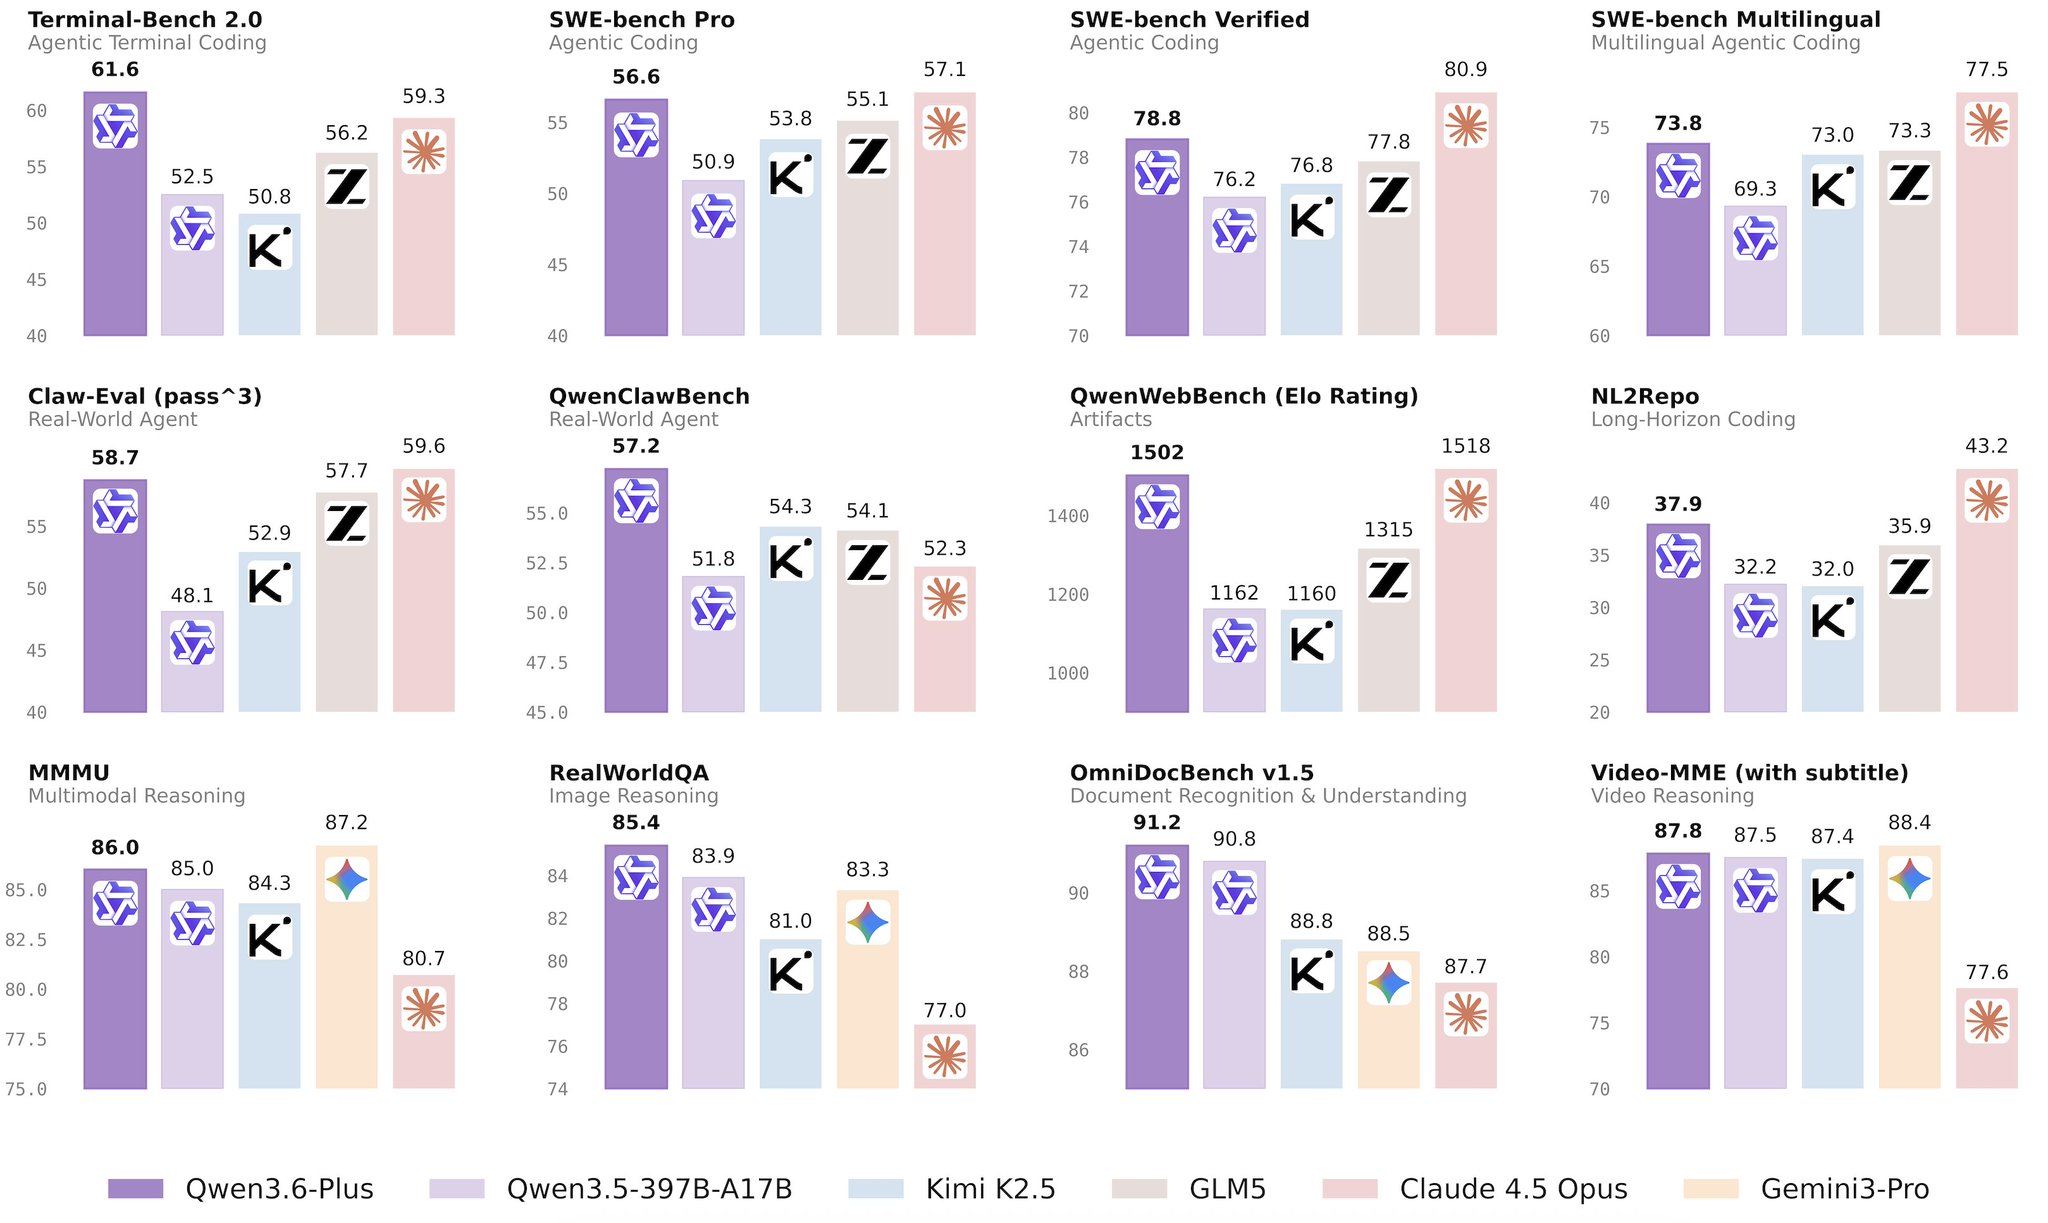
Google Research on AI Agent Traps and Alibaba’s Qwen3.6-Plus Release
By
–
/3 Google shows how the web itself can hijack AI agents with Agent Traps Alibaba launches Qwen3.6-Plus, a hosted model built for agent workflows instead of single http://
prompts.It targets agent workflows by combining reasoning, memory, and tool execution in one system. -
OpenClaw v2026.4.5: Video Generation, Memory Dreams, Cheaper APIs
By
–
explaining what OpenClaw just shipped:
— klöss (@kloss_xyz) 6 avril 2026
(most people don’t understand it yet)
→ 103 contributors on v2026.4.5
→ your agent can now generate videos mid-conversation… generate music. create content assets on command without leaving the chat… through providers like Runway,… https://t.co/q0jh2kRwNx pic.twitter.com/0NYLEw5ayTexplaining what OpenClaw just shipped: (most people don’t understand it yet) → 103 contributors on v2026.4.5 → your agent can now generate videos mid-conversation… generate music. create content assets on command without leaving the chat… through providers like Runway, xAI, Google Lyria, and MiniMax → your agent now dreams… literally… it promotes short-term memory into long-term recall in the background… light sleep, deep sleep, REM… it starts remembering what you talked about without you needing to remind it → your API bill likely just got cheaper… prompt caching got a serious overhaul… system prompts, tool ordering, image history all normalized so follow-up messages hit cache way more often… you didn’t need to change anything. it should cost less for you now → security got tightened across the board… plugin permissions locked down… browser exploits blocked earlier. if something crashes it fails safe instead of failing open… if your agent touches the internet this matters more than everything above → Telegram, WhatsApp, Discord, Slack… 20+ channels… voice notes, reconnect loops, threaded replies, disappearing DMs… the stuff that was quietly broken is now quietly fixed → control UI and docs now speak 12 new languages… Chinese, Japanese, Korean, Spanish, French, German, Portuguese, and more… OpenClaw isn’t an English only project anymore the people sleeping on OpenClaw tooling right now will regret it later get this installed today OpenClaw🦞 (@openclaw) OpenClaw 2026.4.5 🦞 🎬 Built-in video + music generation 🧠 /dreaming is now real 🔀 Structured task progress ⚡ Better prompt-cache reuse 🌍 Control UI + Docs now speak 12 more languages Anthropic cut us off. GPT-5.4 got better. We moved on. github.com/openclaw/openclaw… — https://nitter.net/openclaw/status/2040998570317197607#m
→ View original post on X — @ceobillionaire, 2026-04-06 04:34 UTC
-
Convincing Zoom Clone URL Poses Cybersecurity Threat
By
–
Look at the URL – it’s a convincing Zoom clone.