
“Continuous Latent Diffusion Language Model” Most diffusion language models still use diffusion to recover token-like states, just in a different generation order. However, this paper uses diffusion in a different way. It learns a continuous latent prior for global semantics
RESEARCH
-
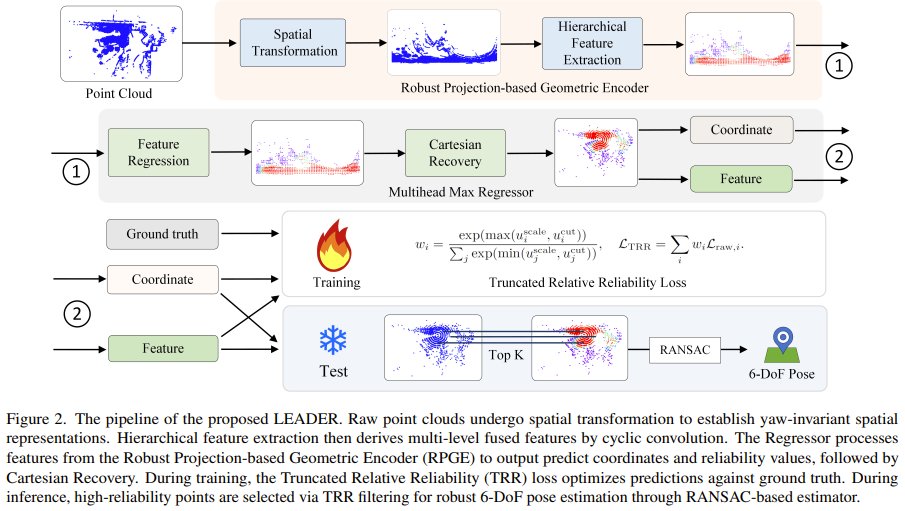
LEADER: A New LiDAR Relocalization Method for Autonomous Robots
By
–
Can your robot always know exactly where it is, even in noisy, complex environments? Researchers from Xiamen University and University of Bristol present LEADER — a new LiDAR relocalization method that doesn't treat all points equally. Instead, it uses a smart geometric
-
Depth Anything V2: A Breakthrough in Monocular Depth Estimation
By
–
What if accurate depth maps could be generated from a single RGB image — without LiDAR or stereo cameras?
— Satya Mallick (@LearnOpenCV) 9 mai 2026
That’s exactly what Depth Anything V2 achieves.
In 2024, monocular depth estimation reached a major breakthrough:
✔ Fast
✔ Lightweight
✔ Temporally stable
✔ Edge-device… pic.twitter.com/Da4XDWC668What if accurate depth maps could be generated from a single RGB image — without LiDAR or stereo cameras?
That’s exactly what Depth Anything V2 achieves.
In 2024, monocular depth estimation reached a major breakthrough: Fast Lightweight Temporally stable Edge-device -

MiniCPM-o 4.5 for omni-modal interactions
By
–
MiniCPM-o 4.5 Towards Real-Time Full-Duplex Omni-Modal Interaction paper: https://
huggingface.co/papers/2604.27
393
… -
Reproducing Schmidhuber’s Research Papers Using AI Coding Assistants
By
–
Reproducing all of Schmidhuber’s papers (1990-2025) using an AI coding assistant.
— hardmaru (@hardmaru) 9 mai 2026
Cool project by @yaroslavvb! It even reproduced the “World Models” paper by me and @SchmidhuberAI with a toy env, with a full VAE + RNN world model implementation.
Project: https://t.co/sgQG5umNEm pic.twitter.com/iKMFN7ti9zReproducing all of Schmidhuber’s papers (1990-2025) using an AI coding assistant. Cool project by @yaroslavvb
! It even reproduced the “World Models” paper by me and @SchmidhuberAI with a toy env, with a full VAE + RNN world model implementation. Project: https://
github.com/cybertronai/sc
hmidhuber-problems/blob/main/VISUAL_TOUR.md
… -

Raw Pixels Dethrone Vision Encoders
By
–
Raw pixels have just outperformed vision encoders across every benchmark. Most multimodal AI systems today rely on stitching together separate components. One encoder processes images, while another generates them. This division causes misalignment and prevents true end-to-end training. A new paper, titled Tuna-2, introduces a breakthrough approach.
-
AlphaSignal AI Summarizes AI Breakthroughs
By
–
Paper: https://arxiv.org/abs/2604.24763 Check out http://AlphaSignal.ai for a daily summary of the top AI models, repositories, and research papers. Read by 280,000+ developers.
-

METR’s Graph: 50% Success, Not 100
By
–
Hot take on METR’s new graph that so many people are flipping about today. • Claude Code is a real advance; Mythos probably builds on some of what is learned there. But… • If you read the graph carefully, it is about achieving *50%* success. Not 100 or 99 or even 90. The
-
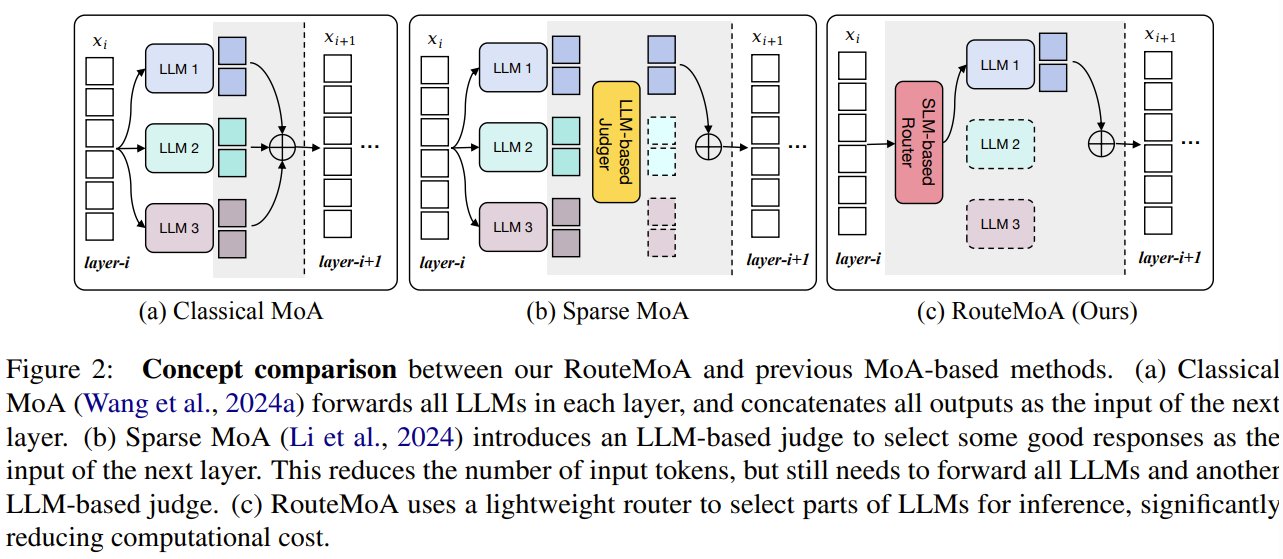
RouteMoA: Efficient AI Agent Collaboration via Intelligent Model Routing
By
–
What if you could boost AI agent collaboration while slashing costs by nearly 90%? Researchers from SJTU, CUHK, Tencent, and NTU present RouteMoA. Instead of running every model first, a lightweight scorer predicts each model’s potential from the query alone, then a mix of
