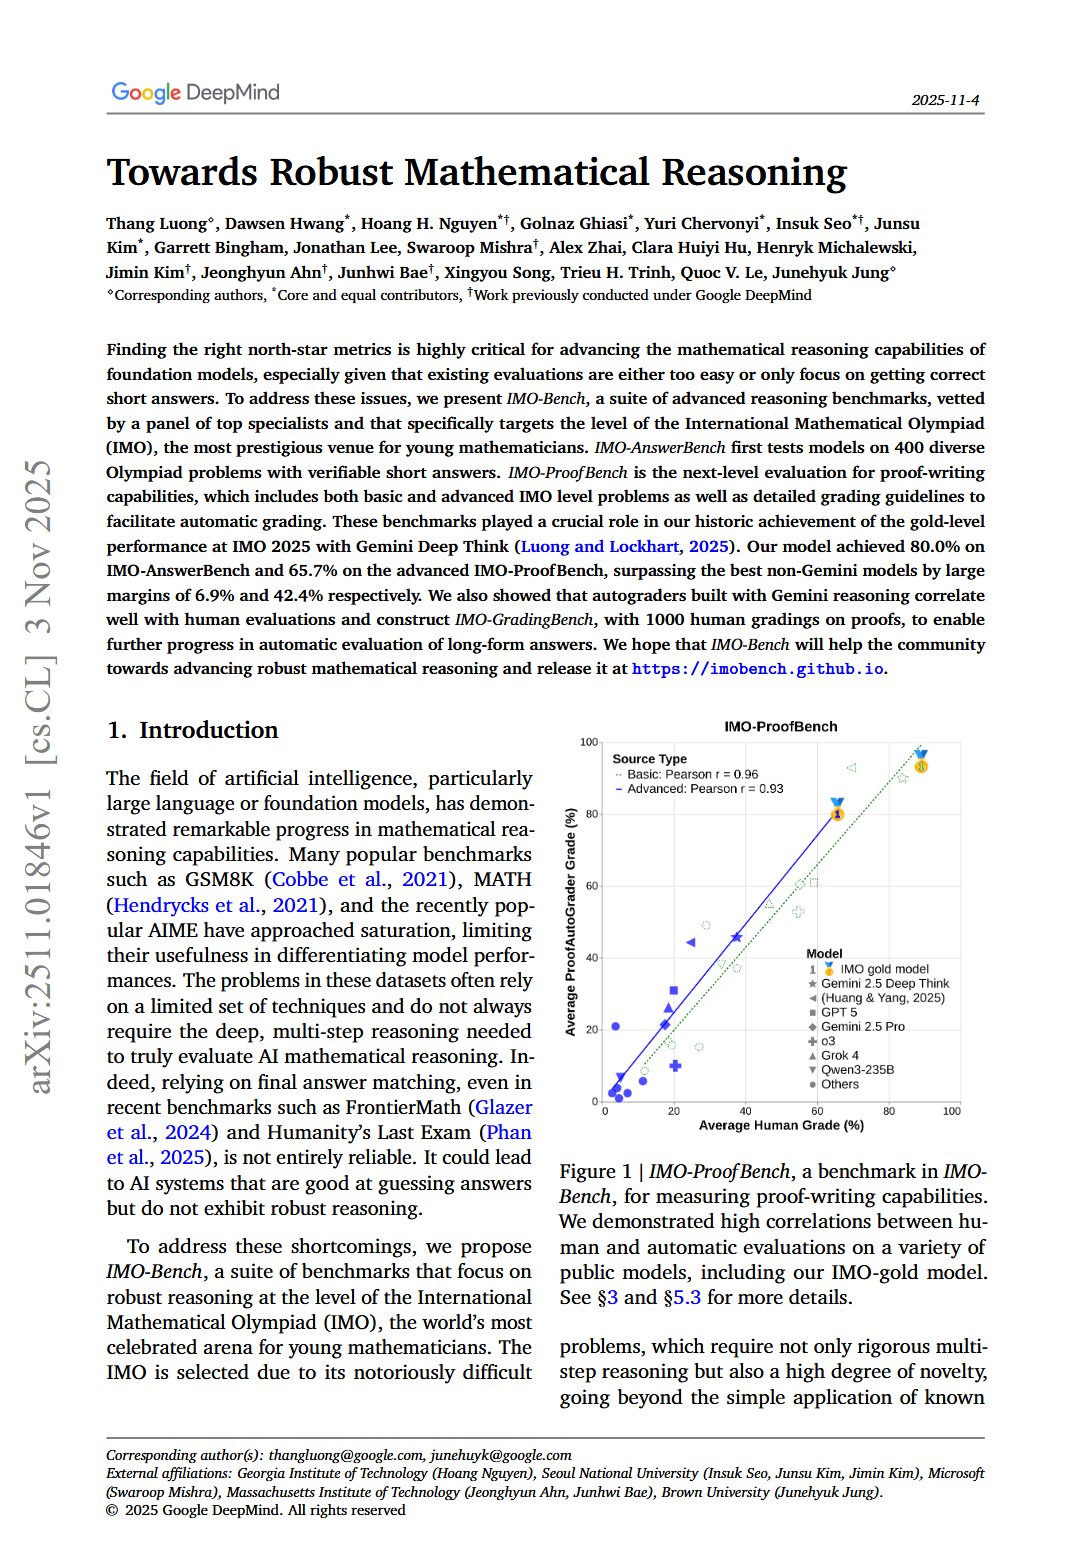
1. Towards Robust Mathematical Reasoning Google DeepMind introduces IMO-Bench, a comprehensive suite of benchmarks vetted by IMO medalists targeting International Mathematical Olympiad-level reasoning.
RESEARCH
-
Top AI Research Papers: Agents, LLMs, and Mathematical Exploration
By
–
Top AI Papers of the Week (Nov 3 – 9): – Tool-to-Agent Retrieval
– Context Engineering 2.0
– Mathematical Exploration at Scale
– Petri Dish Neural Cellular Automata
– Enhancing Long-Term Memory in LLMs
– Diffusion LMs are Super Data Learners
– Towards Robust Mathematical -
Symbol Manipulation Component Essential for Advanced AI Systems
By
–
without a symbol-manipulation component, i just don’t see it.
-
AI Humanoid Robots Still 5-10 Years From Human-Level Task Completion
By
–
The reality of the true state of robotics today! Still at least 5- 10 years away from AI enabled humanoid robots successfully completing tasks (goals) as humans would require.
-

RAG Systems: Indexing and Retrieval Are Not the Same
By
–
Here's a common misconception about RAG! Most people think RAG works like this: index a document → retrieve that same document. But indexing ≠ retrieval. What you index doesn't have to be what you feed the LLM. Once you understand this, you can build RAG systems that
-
AI is Not the New Calculator: Debunking a Circulating Misconception
By
–
https://
linkedin.com/posts/fabiomoi
oli_ai-leadership-education-activity-7393248684500488192-BXNq
… 𝐓𝐡𝐢𝐬 𝐩𝐡𝐨𝐭𝐨 𝐤𝐞𝐞𝐩𝐬 𝐜𝐢𝐫𝐜𝐮𝐥𝐚𝐭𝐢𝐧𝐠 — 𝐛𝐮𝐭 𝐀𝐈 𝐢𝐬 𝐍𝐎𝐓 𝐭𝐡𝐞 𝐧𝐞𝐰 𝐜𝐚𝐥𝐜𝐮𝐥𝐚𝐭𝐨𝐫! -

Logan Kilpatrick from Google DeepMind joins AI Chitchat
By
–
Mark your calendars for Tuesday, 6pm CET. This is an event you dont wanna miss! Logan Kilpatrick from Google Deepmind will join me in AI Chitchat!
-

Chinese AI Models Optimized for Cheaper GPU Hardware
By
–
Side effect of blocking Chinese firms from buying the best NVIDIA cards: top models are now explicitly being trained to work well on older/cheaper GPUs. The new SoTA model from @Kimi_Moonshot uses plain old BF16 ops (after dequant from INT4); no need for expensive FP4 support.
-

PhysToolBench: Testing MLLMs’ Physical Tool Understanding
By
–
Can AI truly understand tools like humans do? Researchers introduce PhysToolBench, the first benchmark testing MLLMs’ grasp of physical tools—from recognizing and explaining how they work to creatively inventing new ones when none are available. Tests on 32 leading models show
-
AI Hype vs Reality: Beyond the Religious Narrative
By
–
Posts like this never get 1 tenth of 1 percent of posts claiming the opposite. AI has become a religion. Reality is more complicated: