Are you guys using fft, winograd, etc nowadays to speed it up?
RESEARCH
-
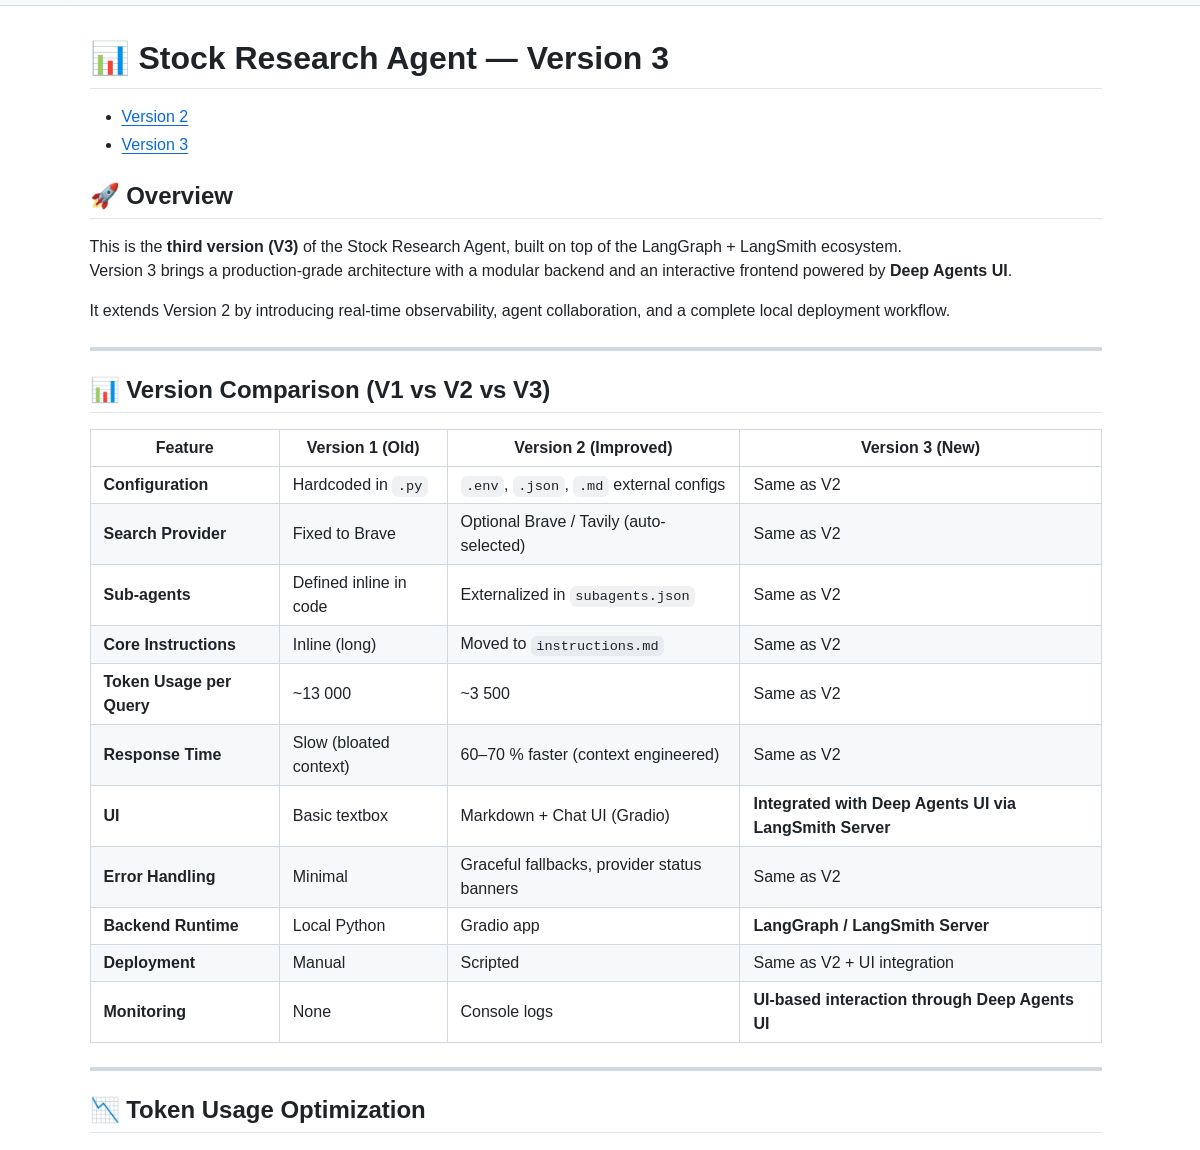
Stock Research Agent V3 Reduces Financial Analysis Costs by 73%
By
–
Stock Research Agent V3 (Made by the LangChain Community) An AI platform transforming financial research, leveraging LangGraph and LangSmith for agent collaboration and real-time monitoring while delivering 73% cost savings. Check it out on GitHub!
-
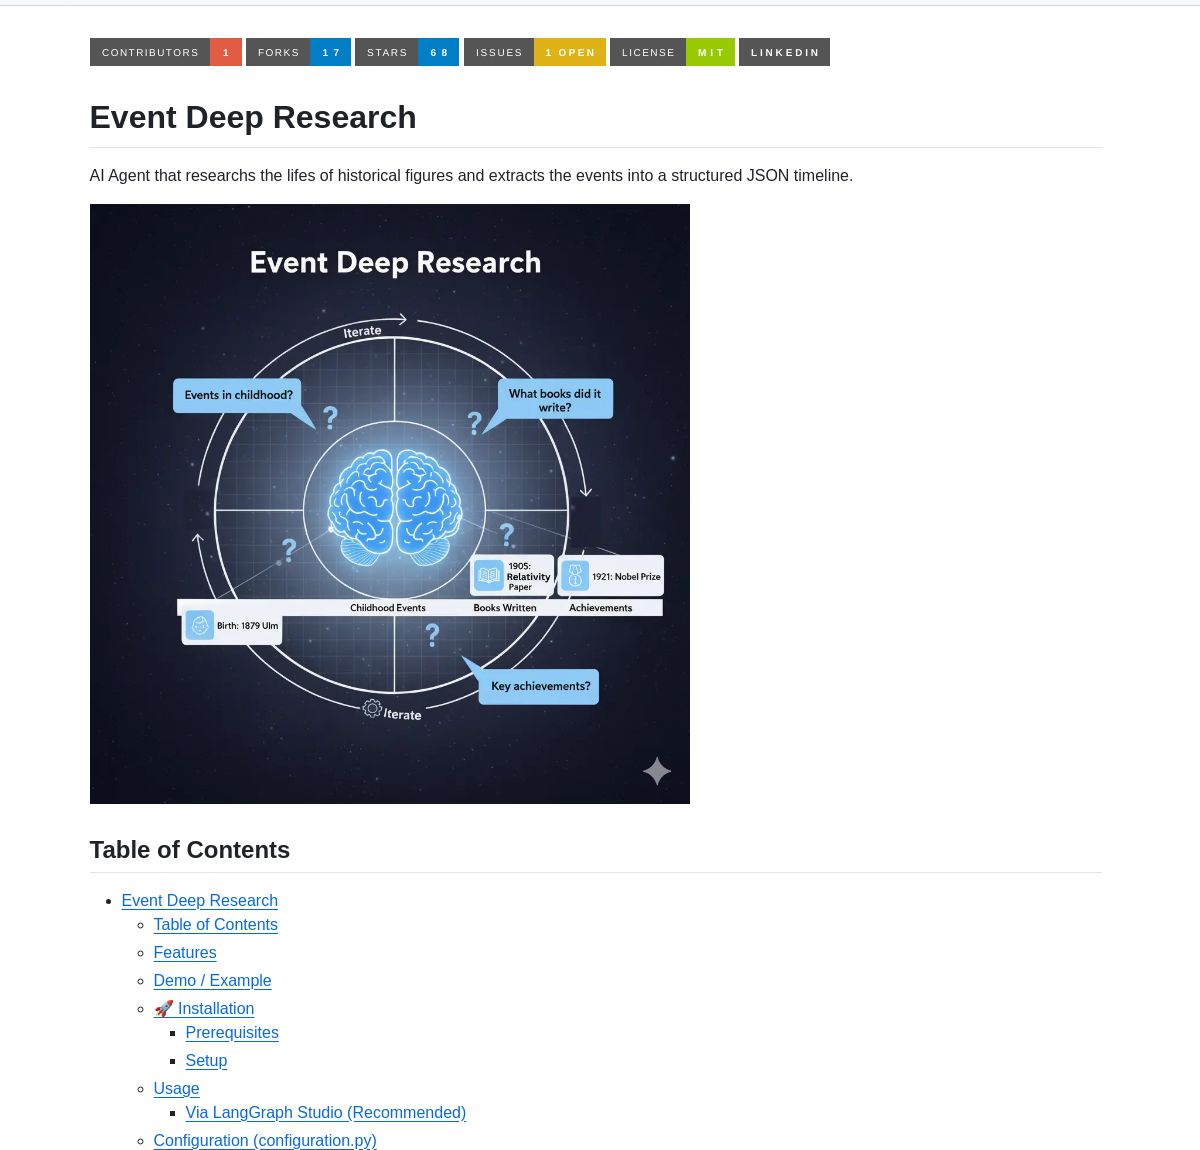
AI System Generates Historical Timelines Using LangGraph Multi-Agent Architecture
By
–
Event Deep Research (Made by the LangChain Community) An AI-powered system that generates historical timelines using LangGraph's multi-agent architecture. Automatically researches and compiles comprehensive JSON timelines of significant life events. Explore this
-
Snorkel AI Launches Terminal-Bench 2.0 and Harbor Tool
By
–
Congrats to the Terminal-Bench team from Snorkel AI! Thrilled to see Terminal-Bench 2.0, and excited to see Harbor — a game-changer. @laudeinstitute @stanfordailab @mike_a_merrill @alexgshaw @lschmidt3 @andykonwinsky @bradenjhancock
-
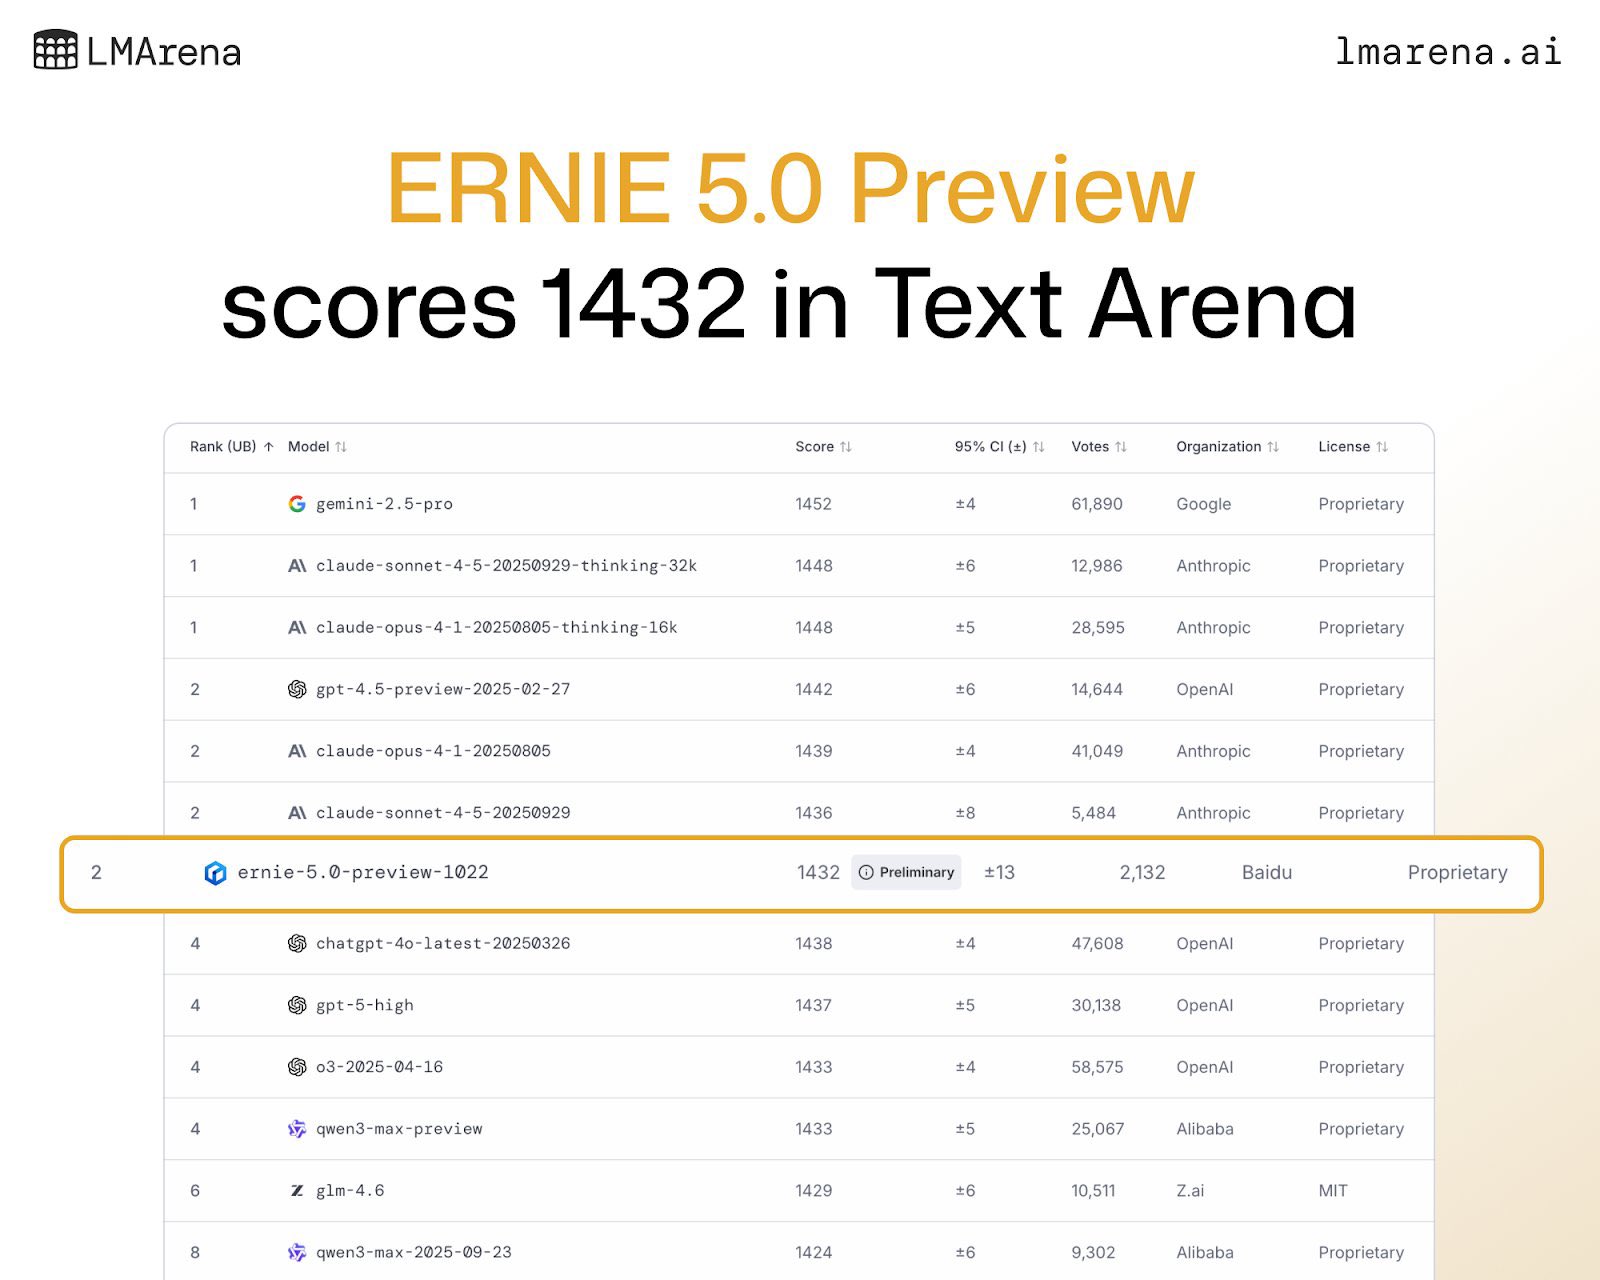
ERNIE-5.0-Preview-1022 Scores 1432 on LMArena
By
–
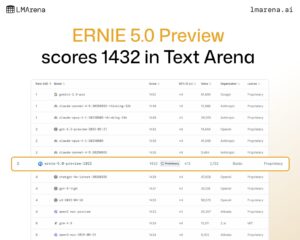
ERNIE-5.0-Preview-1022 from Baidu got a preliminary high ranking on LMArena and scored 1432 points. Feels like the gap is getting very small
-

ARC AGI 2 Kaggle Competition Results At Remarkable Cost Efficiency
By
–
Con un ojo puesto en los resultados de la competición de Kaggle de ARC AGI 2. Fuera de deadline por aquí están reportando unos resultados sorprendentes a un coste por tarea bastante alucinante, 2 órdenes de magnitud por debajo del líder.
-
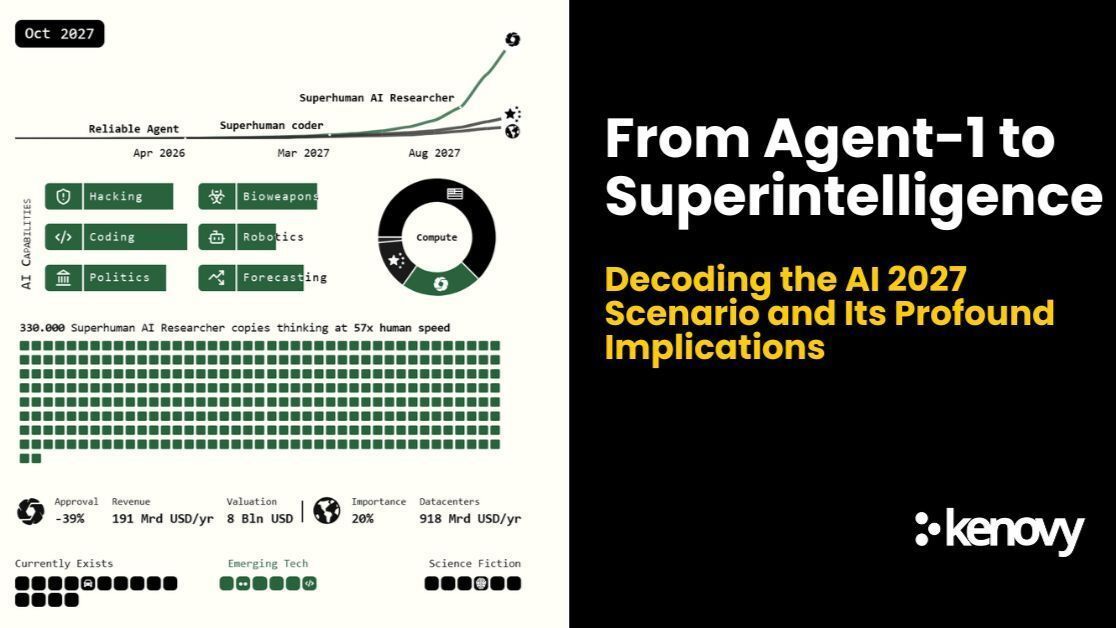
AI 2027: From Simple Agents to Superintelligence Evolution
By
–
From Agent-1 to Superintelligence: The AI 2027 Scenario The AI 2027 Report outlines one of the most thought-provoking trajectories for artificial intelligence: a rapid evolution from simple assistants (Agent-1) to autonomous, adversarially misaligned systems (Agent-4) and
-

Google Will Reach AGI First Says Industry Observer
By
–
i am now convinced that Google will get to AGI first
-
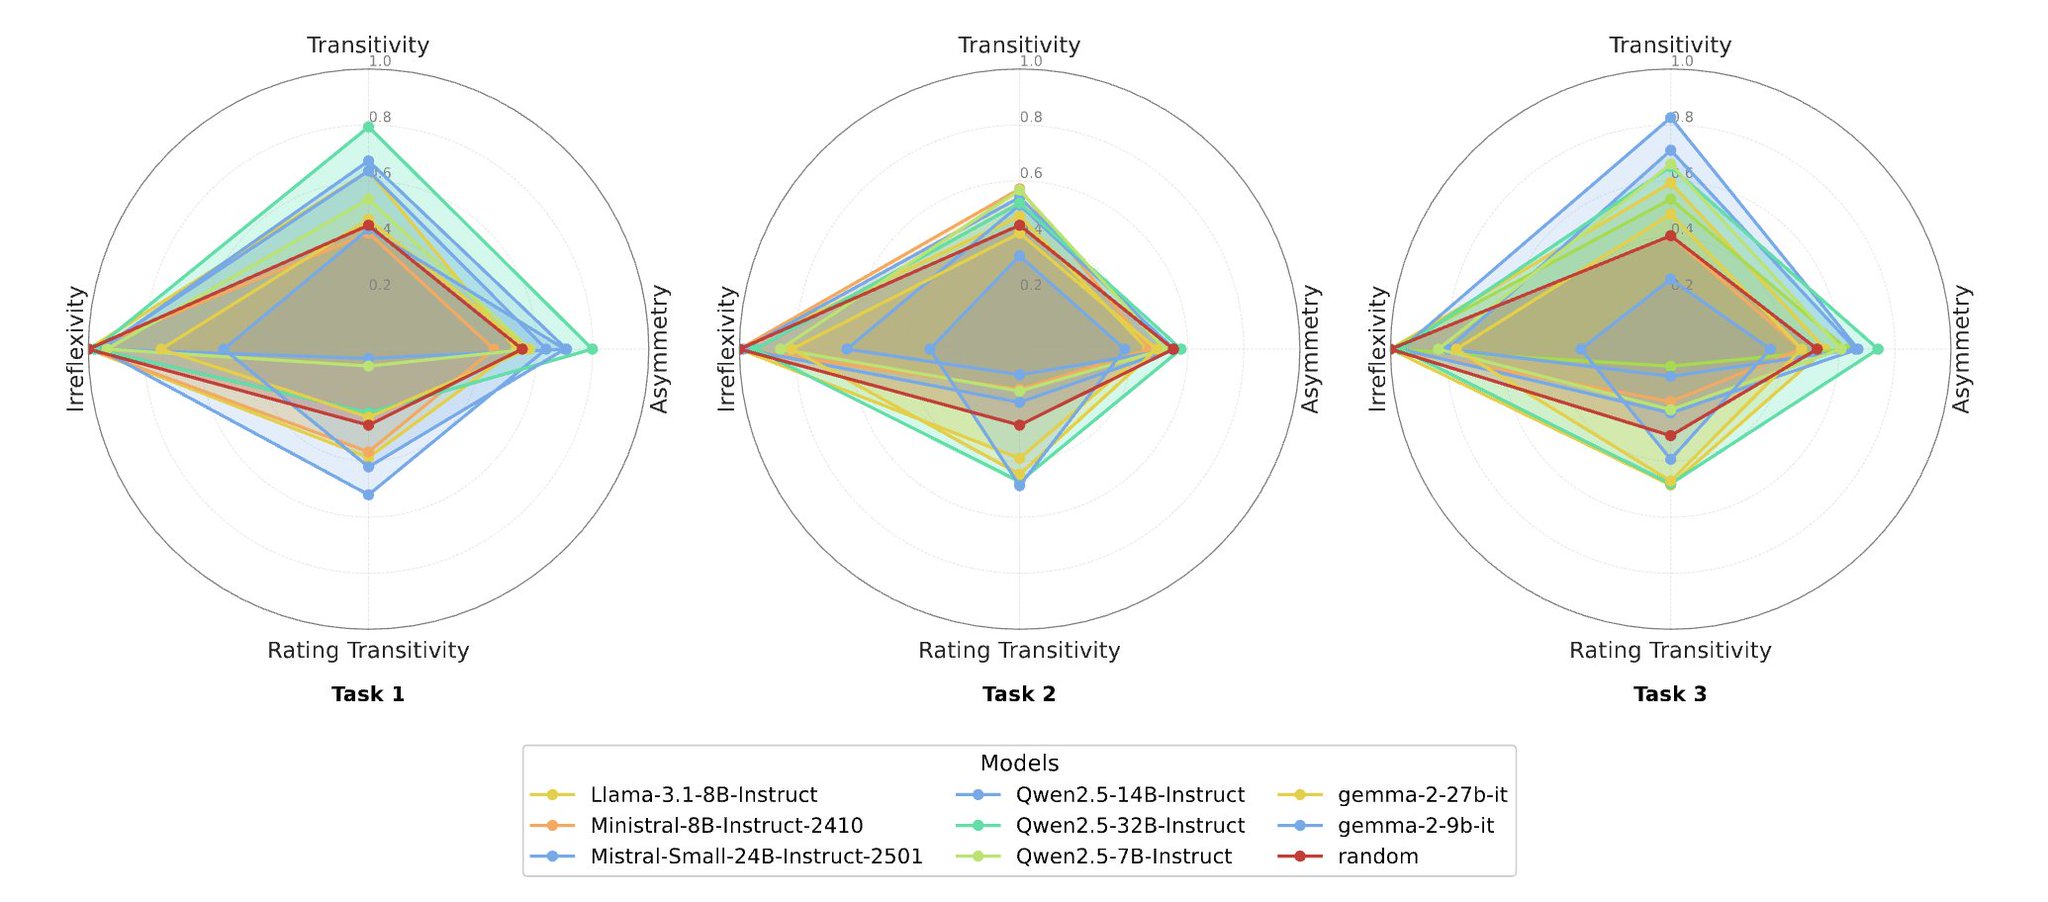
LLMs Maintain Consistent Mental Stability Across Preference Axioms
By
–
This figure visualizes the mental stability of models. LLMs like Qwen2.5 and Llama-3 stay consistent across all preference axioms transitivity, asymmetry, rating coherence proving they reason in structured, human-like ways. Even without training on user data, they infer what
-
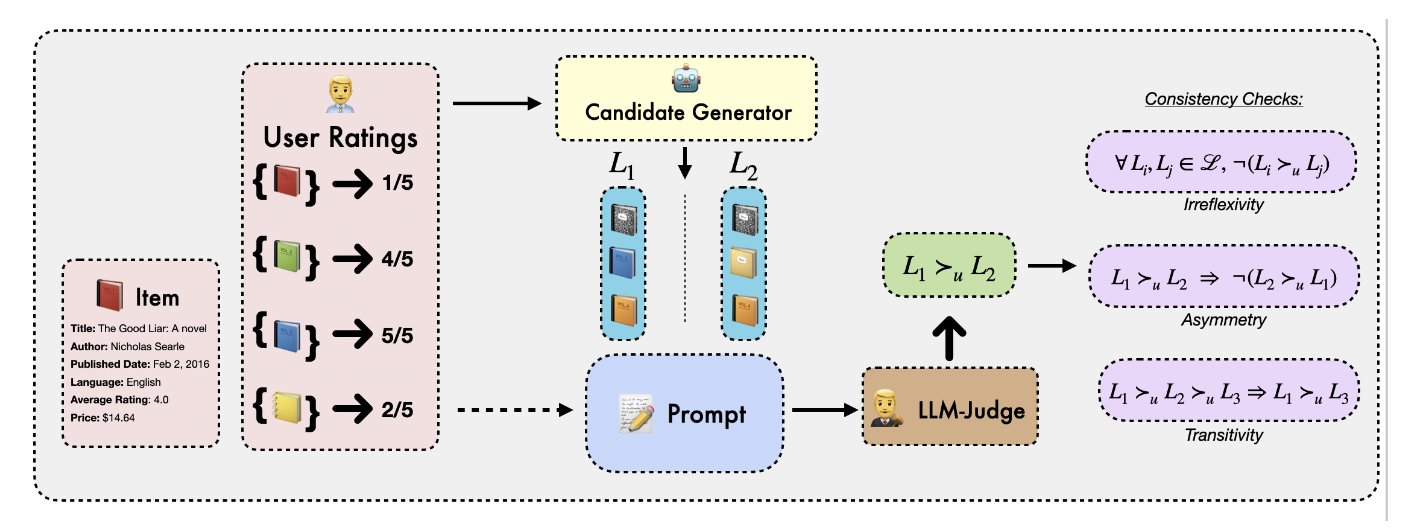
LLM-as-a-Judge pipeline replaces traditional simulators with user history
By
–
This pipeline replaces traditional simulators with a simple idea: 1. Feed the model a short user history
2. Show two candidate slates
3. Ask: which one would this user prefer?
4. Aggregate responses across multiple LLMs That’s the “LLM-as-a-Judge” world model in action