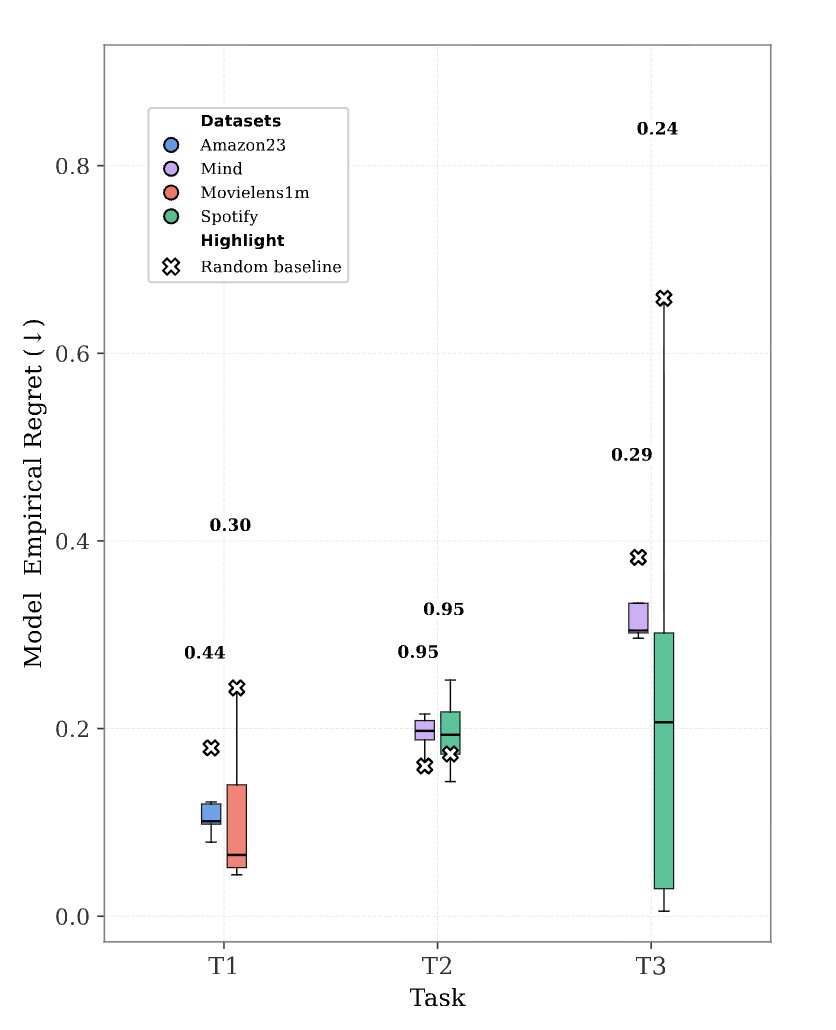
This figure shows how well different LLMs judge slates (ordered recommendations) across datasets like Amazon, Spotify, MIND, and MovieLens. Lower “regret” = closer alignment with real user preferences. Turns out, LLMs consistently outperform random baselines when slates differ
RESEARCH
-
LLMs judge your taste freakishly well in new recommender paper
By
–
Holy shit… LLMs just learned how to judge your taste and they’re freakishly good at it A new paper, “LLM-as-a-Judge: Toward World Models for Slate Recommendation Systems,” just flipped recommender research on its head. Instead of simulating every click or dwell time, these
-

AutoDeco: LLMs Learn Self-Tuning Decoding Parameters
By
–
What if LLMs could tune their own decoding—no more guesswork with temperature and top‑p? Enter AutoDeco: the first architecture that makes LLM decoding truly end-to-end. By adding lightweight heads, the model predicts its own context-aware temperature and top‑p at every token
-
MedicBrain Hackathon: AI Innovation Against Cancer Research
By
–
Bon on va avancer sur la théma du cancer, y'a pas de sous que je peux vous offrir mais on va aller les chercher. Hackathon #MedicBrain le 5 décembre avec @techskunkworks
, pendant le Téléthon pour tout mettre a plat, ensuite ok va défoncer le crabe. -
Knowledge Sharing Accelerates AI Progress Before 2040
By
–
sharing knowledge, is the best thing that can happen to humanity. I understand why you said 2040 is too far yesterday, and we will make some improvements earlier.
-

CamCloneMaster: Reference-based Camera Control for Video Generation
By
–
CamCloneMaster
— AK (@_akhaliq) 8 novembre 2025
Enabling Reference-based Camera Control for Video Generation pic.twitter.com/l1MxjgTHICCamCloneMaster Enabling Reference-based Camera Control for Generation
-

EVTAR: End-to-End Virtual Try-On with Visual Reference
By
–
EVTAR End-to-End Try on with Additional Unpaired Visual Reference
-
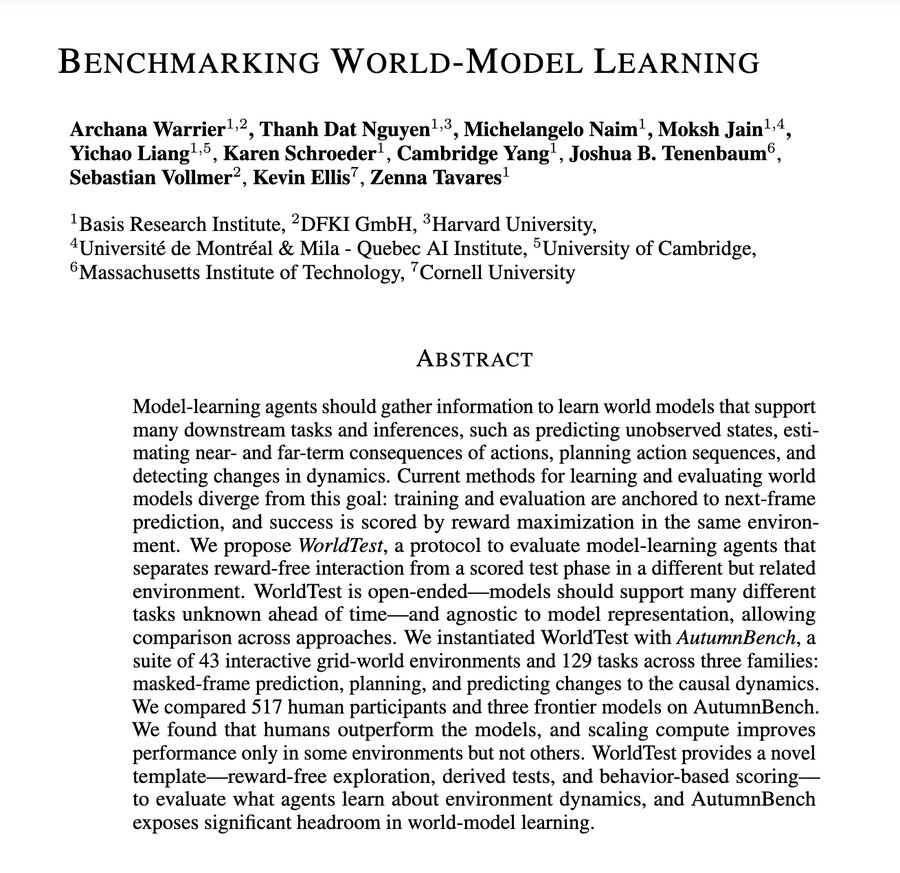
MIT’s WorldTest Benchmark Challenges Top AI Models’ World Understanding
By
–
MIT just quietly humbled every major AI lab — and almost nobody’s talking about it. They built a new benchmark called WorldTest to see if AI actually understands the world. The results are brutal.
Even the top models — Claude, Gemini 2.5 Pro, OpenAI o3 — got crushed by -

Nested Optimization for Continual Learning and Long Context Processing
By
–
An exciting new approach for doing continual learning, using nested optimization for enhancing long context processing.
-
Snorkel Advances Agentic AI Safety with Terminal-Bench
By
–
By codifying harder, more realistic terminal tasks, we’re pushing agentic AI to be safer, smarter, and more capable. Explore Snorkel’s contribution to Terminal-Bench 2.0: https://
bit.ly/482E28L