They’re not gone. Most Chinese AI companies are still building on architectures derived from DeepSeek.
If you actually read the research papers, it’s obvious. Hype cycles move fast.
Architectural influence lasts much longer.
OPEN SOURCE
-
DeepSeek’s Architectural Legacy Dominates Chinese AI Development
By
–
-

OpenClaw’s rapid growth and safe setup guide
By
–
OpenClaw hit 145K GitHub stars and became the fastest-growing open-source AI project in history. But 90% of people installing it have no idea how to set it up safely. That's why I built the OpenClaw Starter Guide. It covers:
→ Full architecture breakdown (Gateway, Agent, -

Joyfl v0.6: Runtime Language Server with JSON Protocol
By
–
joyfl — v0.6: Runtime Language Server Lots of features small and big, most important is a simple language server + protocol (JSON over stdin/stdout) for easier integration into modern tools. Also migrated over to Codeberg, for all the reasons: https://
codeberg.org/creativeai/joy
fl
… -

Mozilla President Discusses Responsible AI and User Control
By
–
Heads up: My new @FastCompany story has a few @starwars references! I recently interviewed @mozilla president Mark Surman about the new "State Of Mozilla" report, the role of user choice and control with AI, and his vision for a "rebel alliance" focused on responsible tech.
-

ModelScope’s Mass Auto Re-upload of Hugging Face Content
By
–
modelscope's mass auto re-upload of content from HF is a bit annoying
-
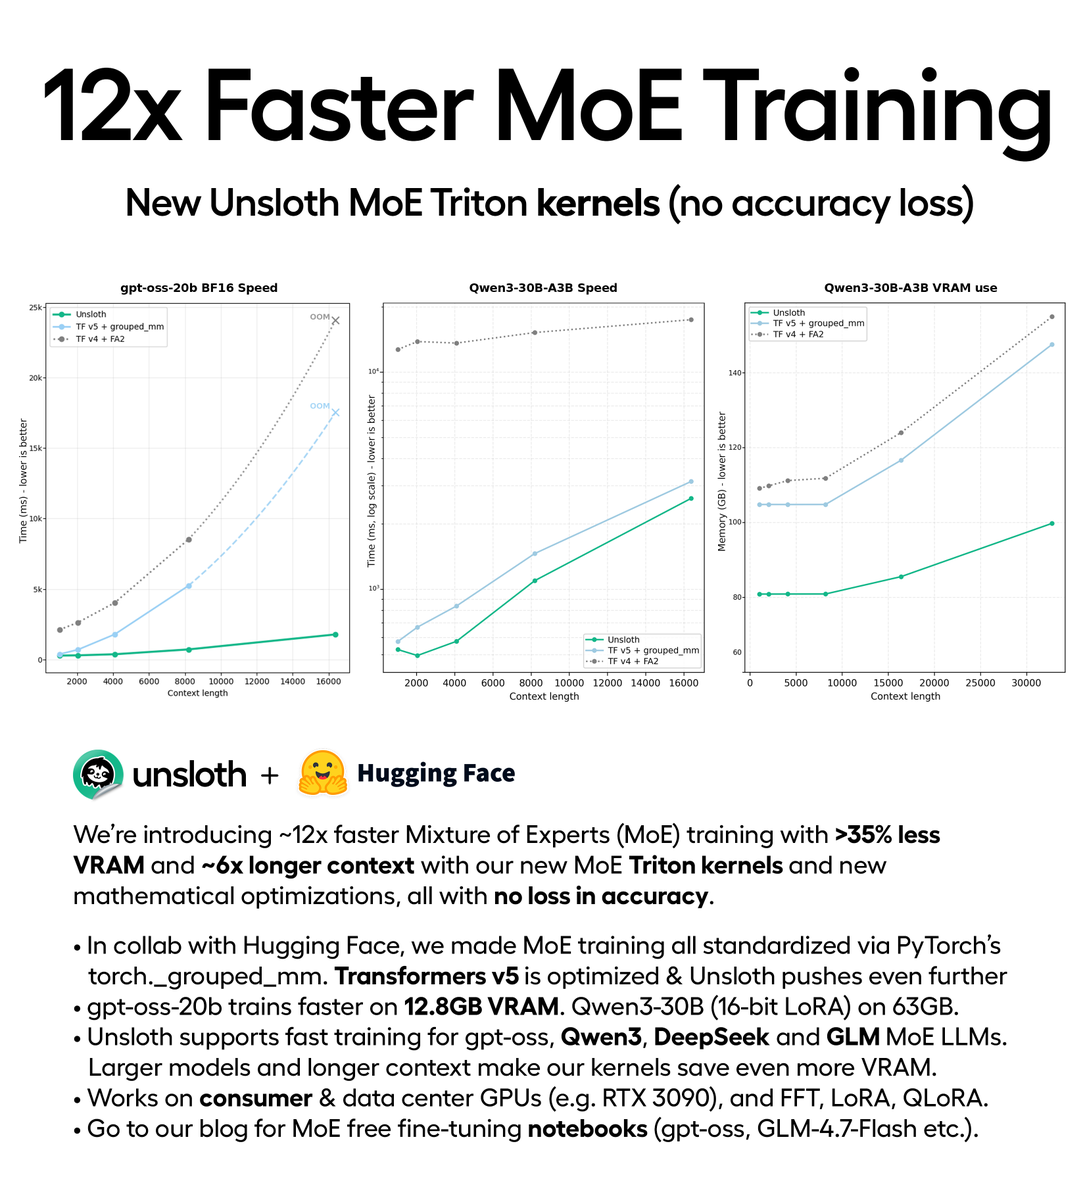
Unsloth achieves 12× faster MoE model training with 35% less VRAM
By
–
You can now train MoE models 12× faster with 35% less VRAM via our new Triton kernels (no accuracy loss). Train gpt-oss locally on 12.8GB VRAM. In collab with @HuggingFace, Unsloth trains DeepSeek, Qwen3, GLM faster. Repo: github.com/unslothai/unsloth Blog: unsloth.ai/docs/new/faster-m…
→ View original post on X — @abhi1thakur, 2026-02-10 15:25 UTC
-
Auto-Tune vLLM Config Doubles Throughput and Halves Latency
By
–
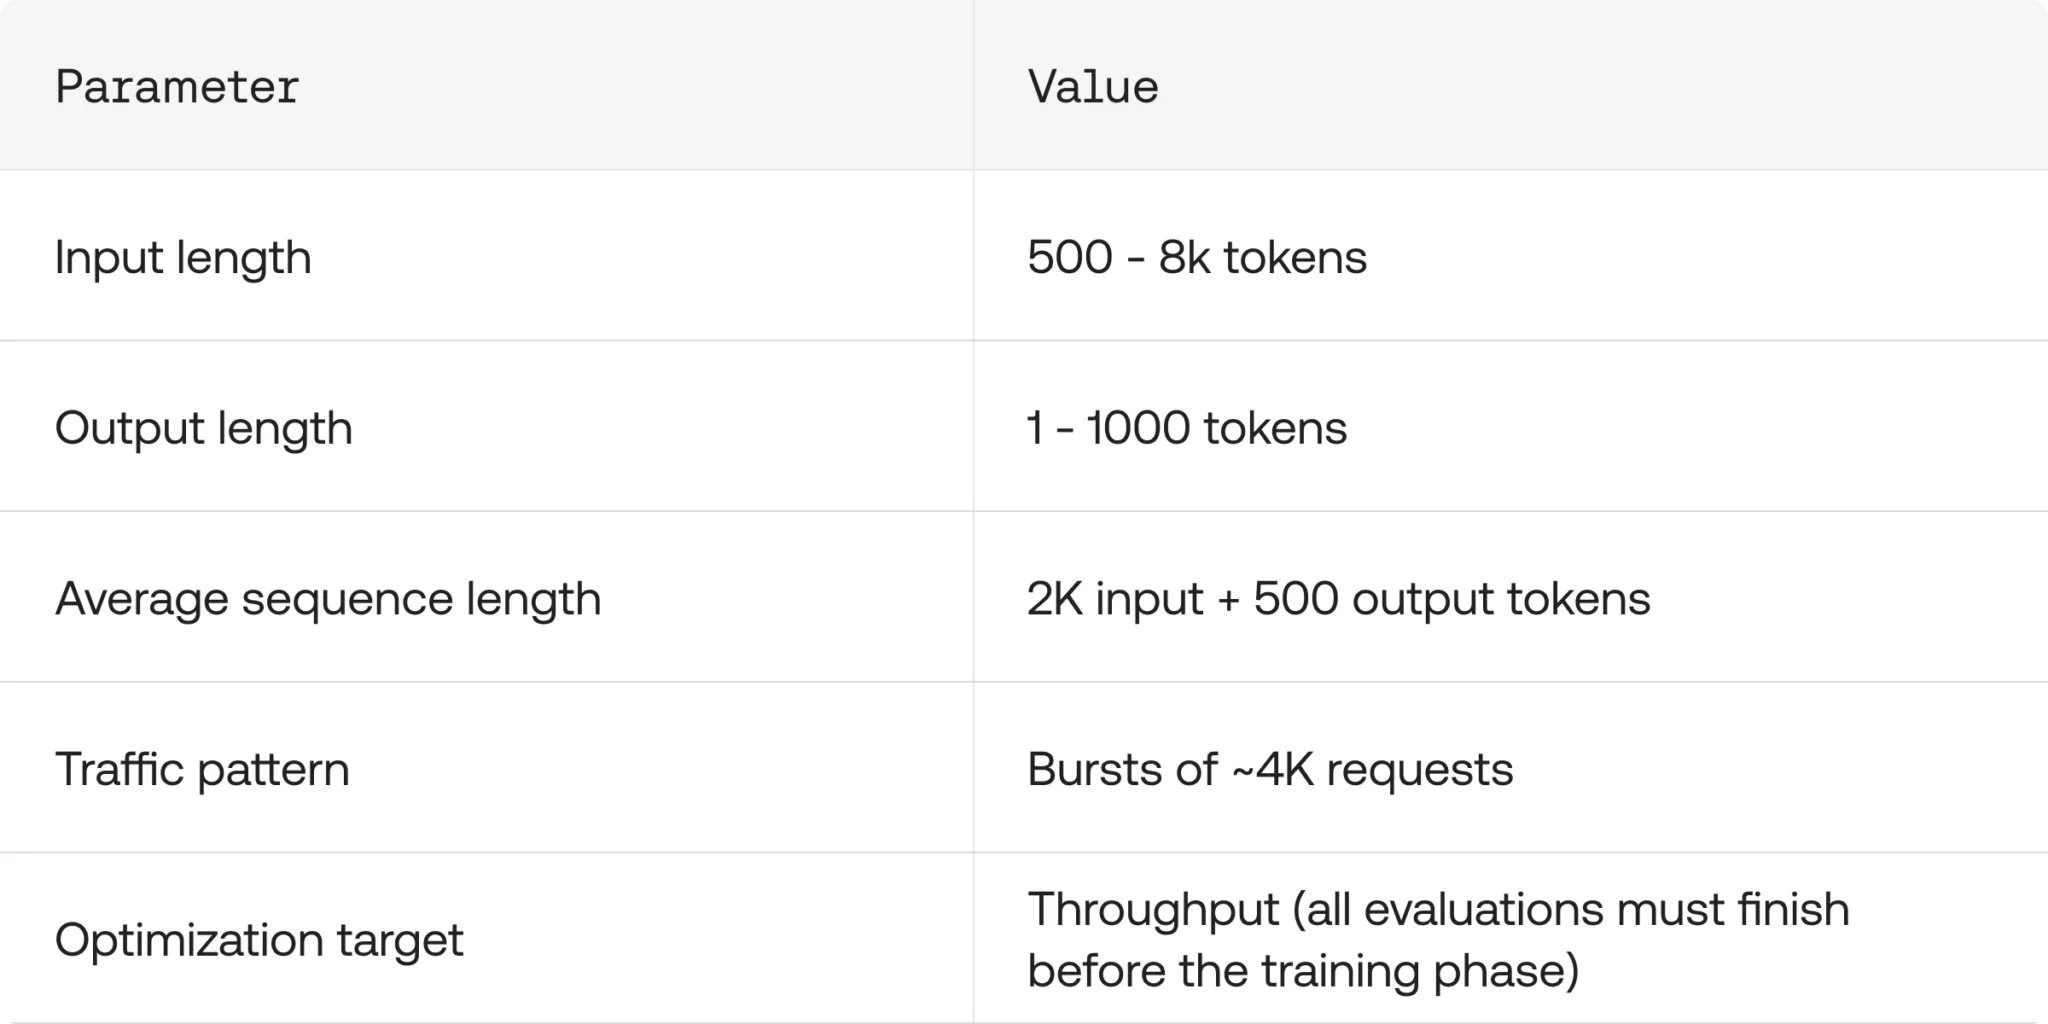
3/5 The vertical fix: auto-tune vLLM config Our old settings were way too conservative. After tuning with Auto-Tune vLLM + GuideLLM we got: ~2× throughput, 2× lower latency, same GPU budget @VLLM @Openshift
-

HunyuanOCR Technical Report on Advanced Character Recognition
By
–
HunyuanOCR Technical Report https://
bit.ly/4bkGbyA
#AI #MachineLearning #DeepLearning #LLMs #DataScience -
The contradiction of open source projects relying on closed cloud APIs
By
–
"100% open source and local" but uses api keys for all the biggest cloud models … make it make sense !