Impressive deep dive! It’s great to see the vLLM team maximizing the GB200’s potential. These kinds of kernel-level optimizations are exactly why the PyTorch ecosystem continues to be the foundation for next-gen inference performance.
OPEN SOURCE
-
Era of sharing AI ends, trade war takes over
By
–
And above all, it says something even stronger: the era of "sharing" AI is over, the era of "bravo" to others for your model is abolished. The stakes have become too big and too grand. Make way for trade war by every means necessary.
-

OpenScholar Scientific Deep Research Agents Accepted to Nature
By
–
Thrilled to share: OpenScholar – our work on scientific deep research agents for reliable literature synthesis -has been accepted to Nature! 🎉 Huge thanks to collaborators across institutions who made this possible!
-
Voxtral Mini 4B Realtime: Fast Streaming ASR with vLLM Support
By
–
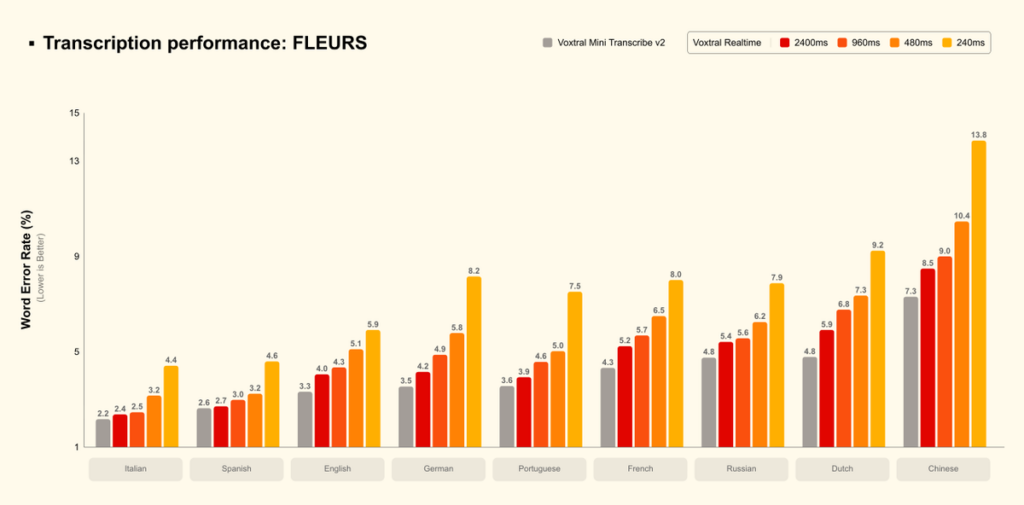
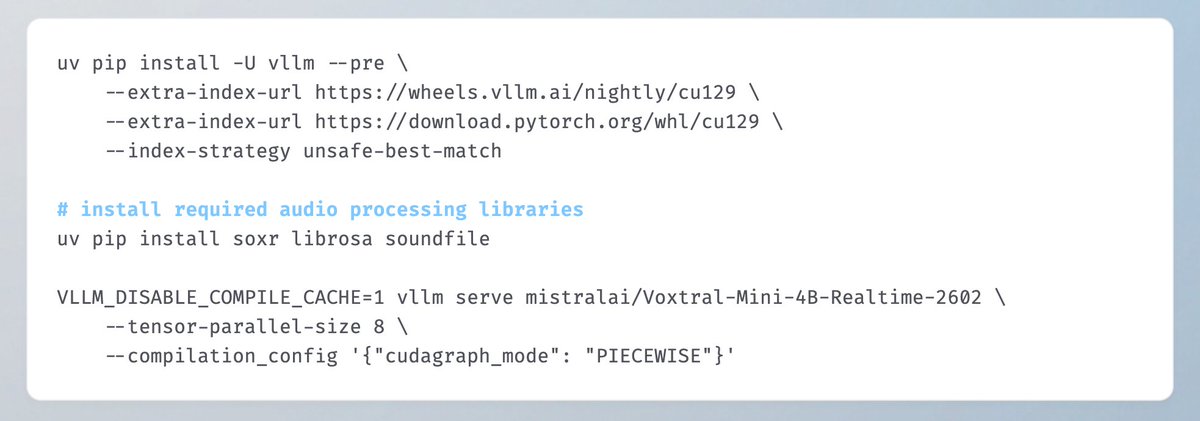
Congrats to @MistralAI on releasing Voxtral Mini 4B Realtime! 🎉 Day-0 support in vLLM! A 4B streaming ASR model achieving <500ms latency while matching offline model accuracy, supporting 13 languages. vLLM's new Realtime API `/v1/realtime` provides audio streaming – optimized for voice assistants, live subtitles, and meeting transcription! Thanks to the close collaboration between the vLLM community and @MistralAI for making this production-grade support possible 🤝 📑Model & Usage: huggingface.co/mistralai/Vox… Mistral AI (@MistralAI) Voxtral Realtime is built for voice agents and live applications. Its natively streaming architecture delivers latency configurable to sub-200ms. And at 480ms, it stays within 1-2% WER of our offline model. We release the model as open weights under Apache 2.0. — https://nitter.net/MistralAI/status/2019068828257333466#m
→ View original post on X — @guillaumelample, 2026-02-04 17:51 UTC
-
Mistral Launches Voxtral Transcribe 2 with Affordable API Pricing
By
–
Mini Transcribe 2 via API at $0.003/min.
Realtime via API at $0.006/min, plus open weights. Blogpost: https://
mistral.ai/news/voxtral-t
ranscribe-2
… HuggingFace (weights + realtime demo): https://
huggingface.co/mistralai/Voxt
ral-Mini-4B-Realtime-2602
… Get started: http://
console.mistral.ai/build/audio/sp
eech-to-text
… -

Voxtral Realtime: Ultra-Fast Open Source Streaming Voice Model
By
–
Voxtral Realtime is built for voice agents and live applications. Its natively streaming architecture delivers latency configurable to sub-200ms. And at 480ms, it stays within 1-2% WER of our offline model. We release the model as open weights under Apache 2.0.
-

Voxtral 2 Release: Real-time and Mini Transcription Models
By
–
Very excited to release Voxtral 2! Voxtral 2 comes with two powerful new models: Voxtral Realtime: a SOTA real-time transcription model released under an Apache 2 license, with latency configurable to sub-200 ms Voxtral Mini Transcribe 2: a SOTA transcription model with
-
Jamba2: Open Source Model for February On-Device Applications
By
–
Model to try out in February: Jamba2. Fully open source under Apache 2.0, includes 3B (dense) model for on-device apps, intended for grounded QA workflows that don't call for the heavy “thinking token” overhead of reasoning models. Further details:
-
Jamba2: Open Source Model for On-Device QA Applications
By
–
Model to try out in February: Jamba2. Fully open source under Apache 2.0, includes 3B (dense) model for on-device apps, intended for grounded QA workflows that don't call for the heavy “thinking token” overhead of reasoning models. Further details:
-

Claude Sonnet 5 Leak: Specs and SWE-Bench Score
By
–
vertex AI just leaked "fennec" in an error log claude sonnet 5 reportedly drops tomorrow the rumored specs:
> 50% cheaper than opus 4.5
> still 1M context window but faster
> can spawn parallel sub-agents from terminal
> allegedly hitting 80.9% on SWE-bench the wildest part: