
"DiffusionBlocks: Block-wise Neural Network Training via Diffusion Interpretation" End to end backprop stores activations through every layer, which is why deep Transformers is expensive to train. This paper reinterprets residual blocks as diffusion denoising steps, so each
MACHINE LEARNING
-

ChatGPT vs Gemini vs Claude vs Grok vs Perplexity
By
–
ChatGPT Vs Gemini Vs Claude Vs Grok Vs Perplexity
by @Khulood_Almani #GenerativeAI #ArtificialIntelligence #MI #MachineLearning -
Managed Deep Agents for Long-Horizon AI Tasks and Tool Use
By
–
Managed Deep Agents is built for agents that need to work over long time horizons, use tools, preserve context, and produce artifacts. A few examples of what teams are building: Support + triage agents Research agents Coding agents Data analysis agents Internal
-
5-second video generation in 4.2s on single Blackwell GPU open-sourced
By
–
You should read this thread.
— NVIDIA AI (@NVIDIAAI) 27 mai 2026
It used to take about 25 seconds to generate a 5-second video on 8 Blackwell GPUs. The legends at @haoailab brought that down to just 4.2 seconds on a single Blackwell GPU… and then open sourced the tech behind it. https://t.co/egQnhx0N1eYou should read this thread. It used to take about 25 seconds to generate a 5-second video on 8 Blackwell GPUs. The legends at @haoailab brought that down to just 4.2 seconds on a single Blackwell GPU… and then open sourced the tech behind it.
-

Heima Hidden Llama speeds reasoning with abstract thinking tokens
By
–
AI could reason faster by thinking in abstract tokens instead of full sentences! Researchers from Zhejiang University, Adobe, and Northeastern University introduce Heima (Hidden Llama). It compresses lengthy Chain-of-Thought reasoning into a compact set of “thinking tokens,”
-

JudgmentBench: First Public Benchmark for AI Quality Assessment Released
By
–
Congratulations to @StanfordLaw liftlab on the release of JudgmentBench, the first publicly available benchmark in a high-judgment domain where both methods for assessing quality are solicited over the same tasks. Snorkel was proud to contribute as research and data partners on
-
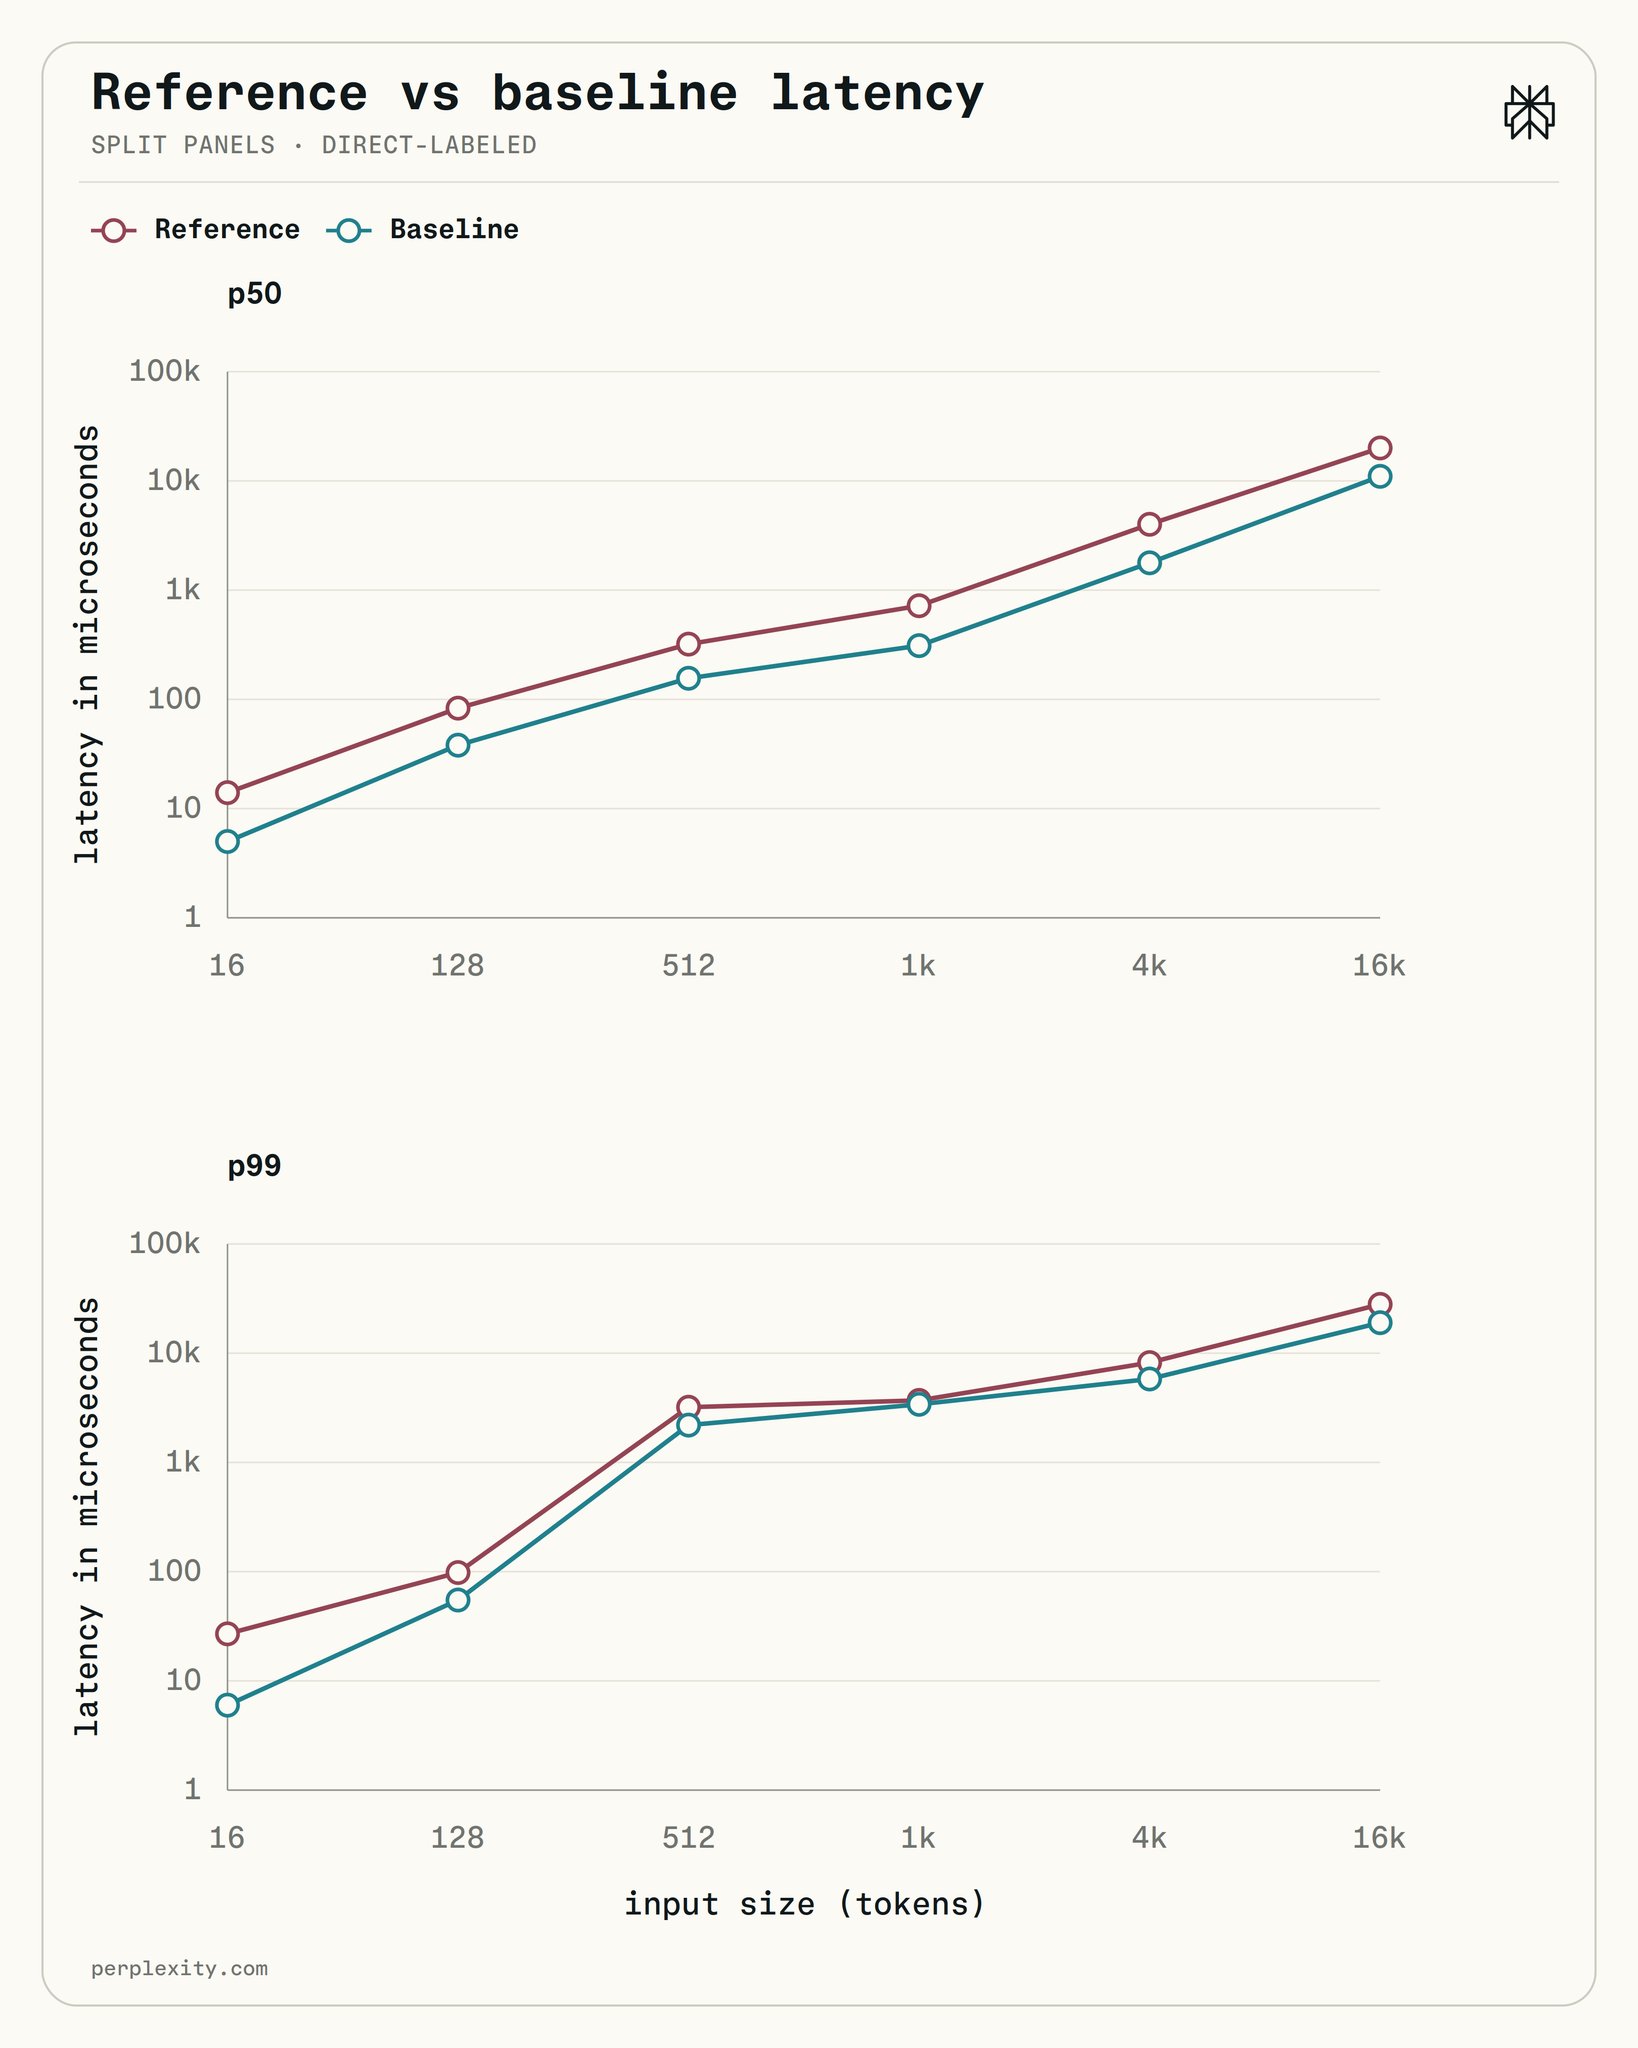
Open sourcing tokenizer more efficient than HuggingFace and SentencePiece
By
–
Every millisecond matters. We’re open sourcing the tokenizer we built and deployed on production; that’s far efficient than huggingface and sentencepiece.
-

The Expensive Hobby Mistake: Why AI Projects Fail and How to Succeed
By
–
The Expensive Hobby Mistake: Why #AI Projects Fail and How to Succeed
by @Khulood_Almani #ArtificialIntelligence #MachineLearning #ML #DL -
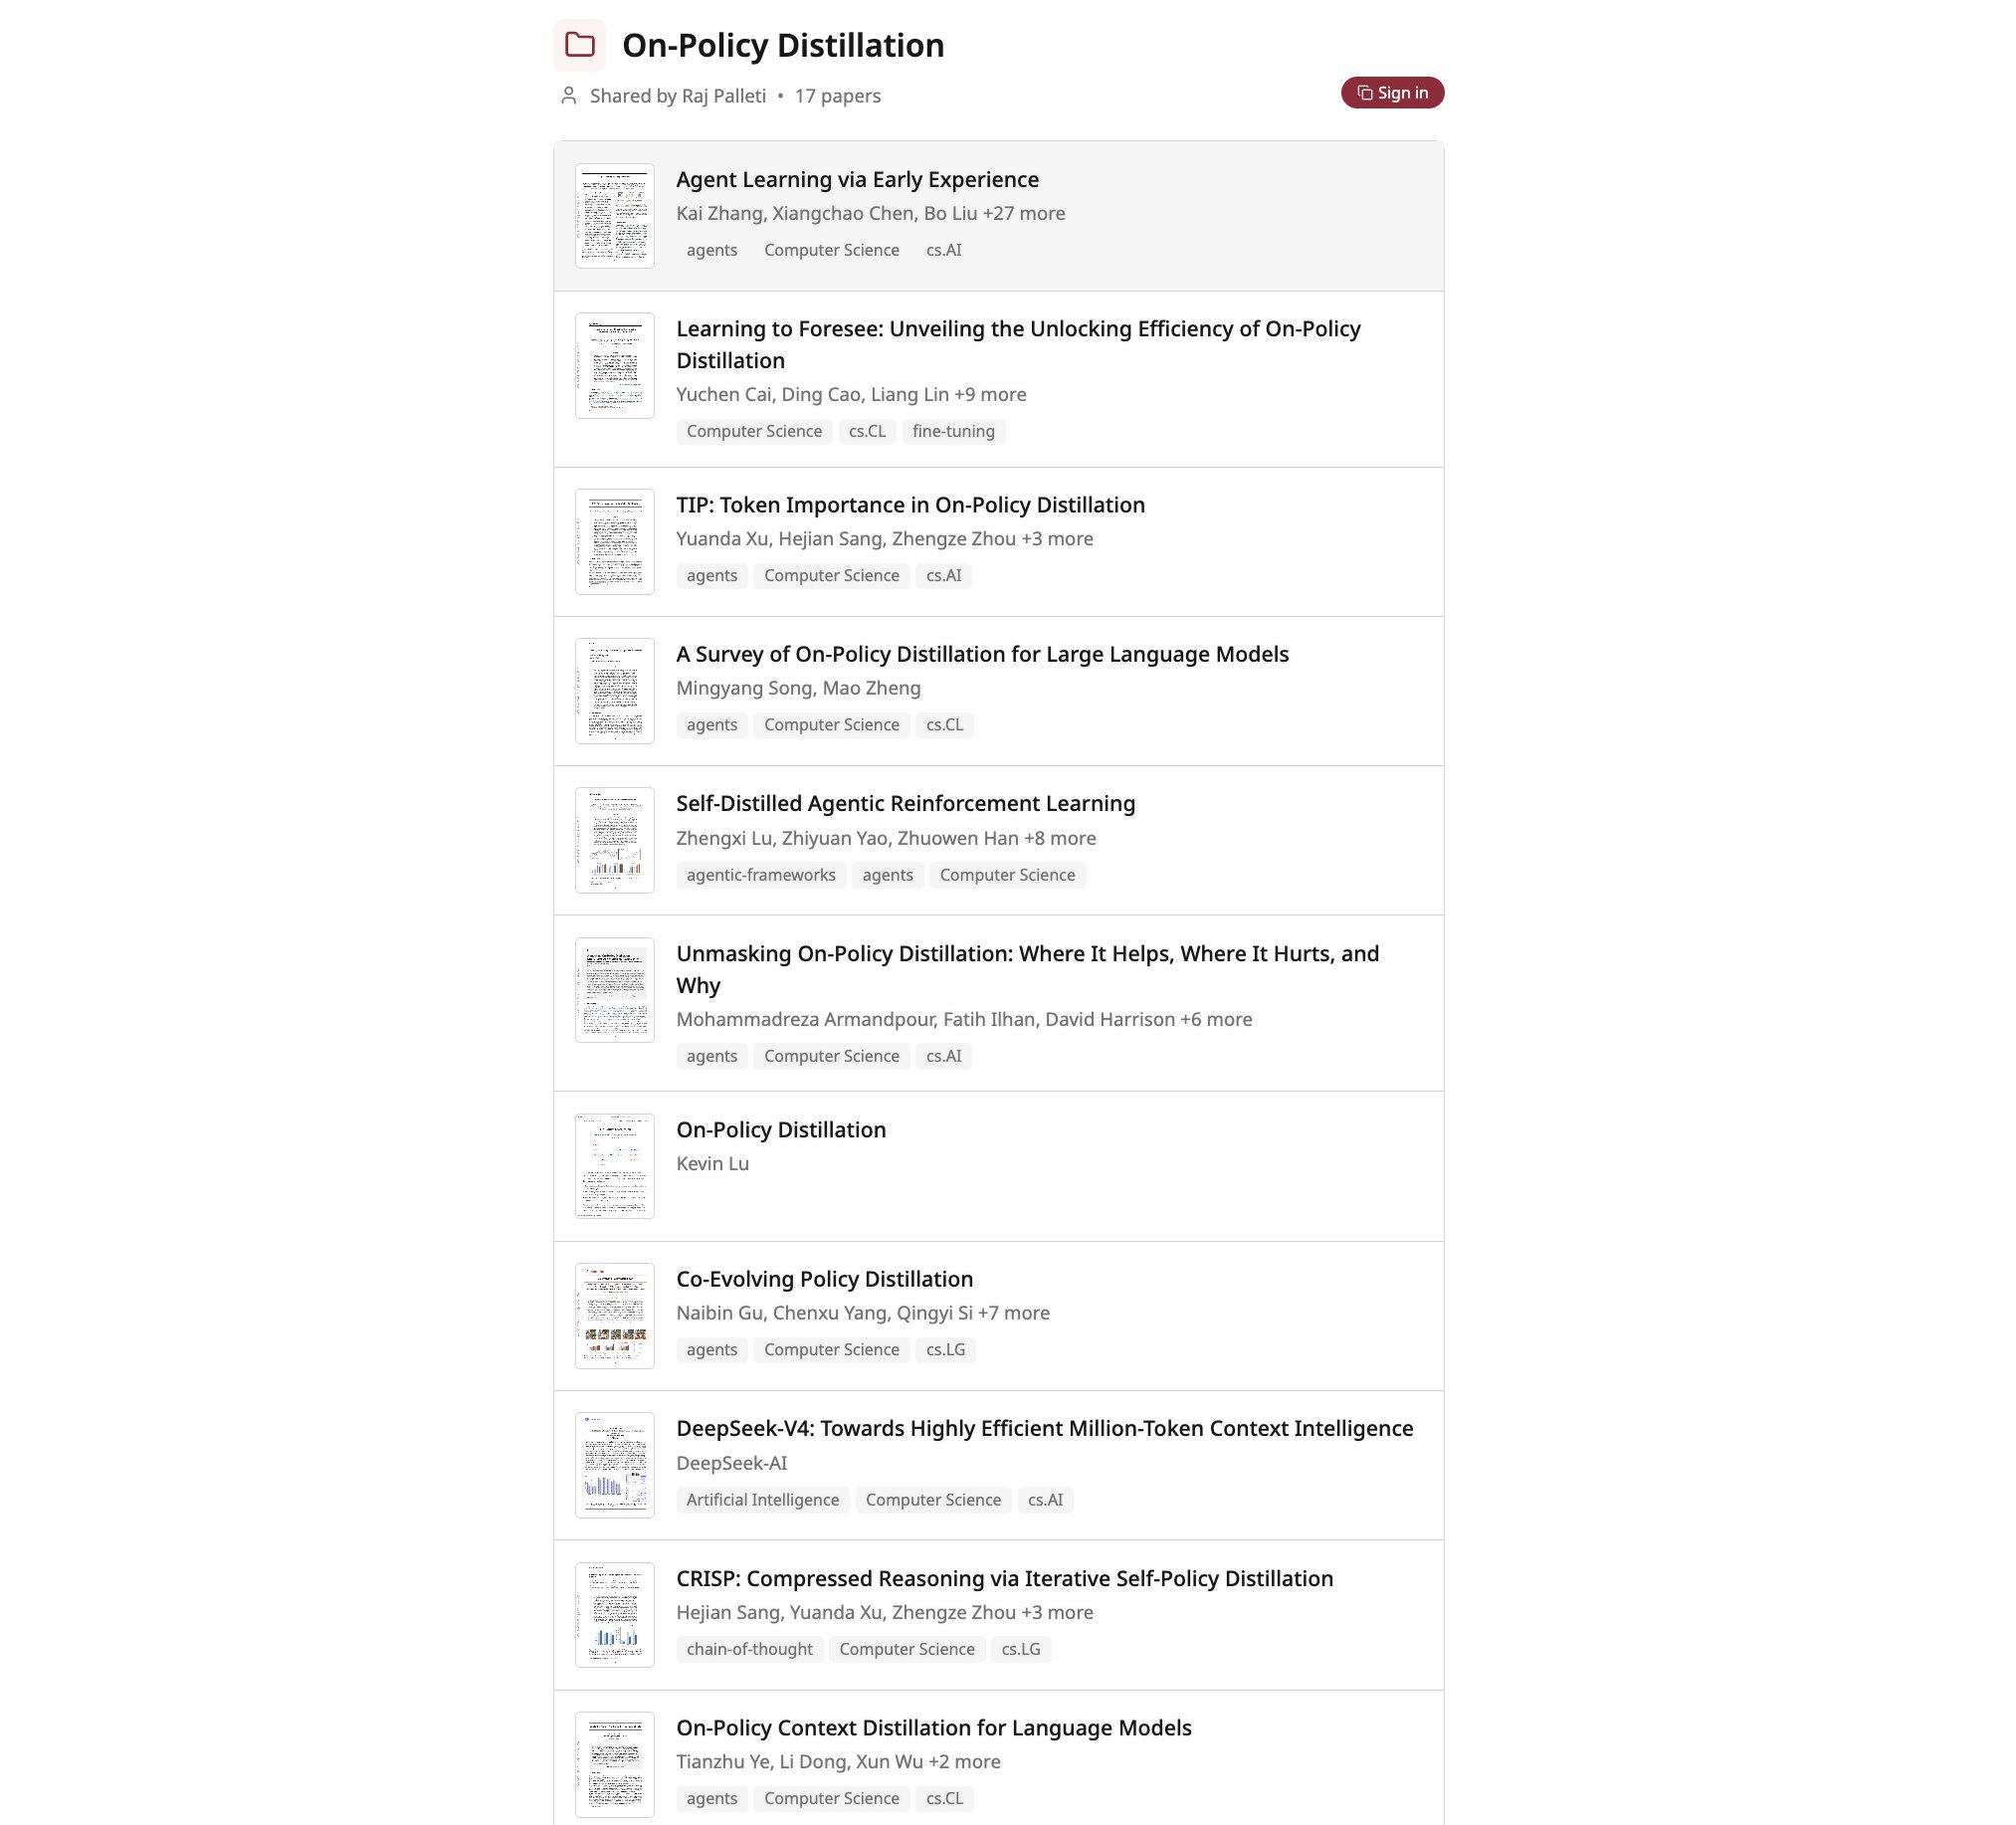
On-Policy Distillation: Emerging AI Post-Training Method
By
–
A new class of post-training method is emerging in 2026: On-Policy Distillation (OPD). It’s already showing up across frontier open-weight model releases, and it’s quickly becoming a technique worth understanding. To help you get up to speed, we’ve compiled a list of the most
-
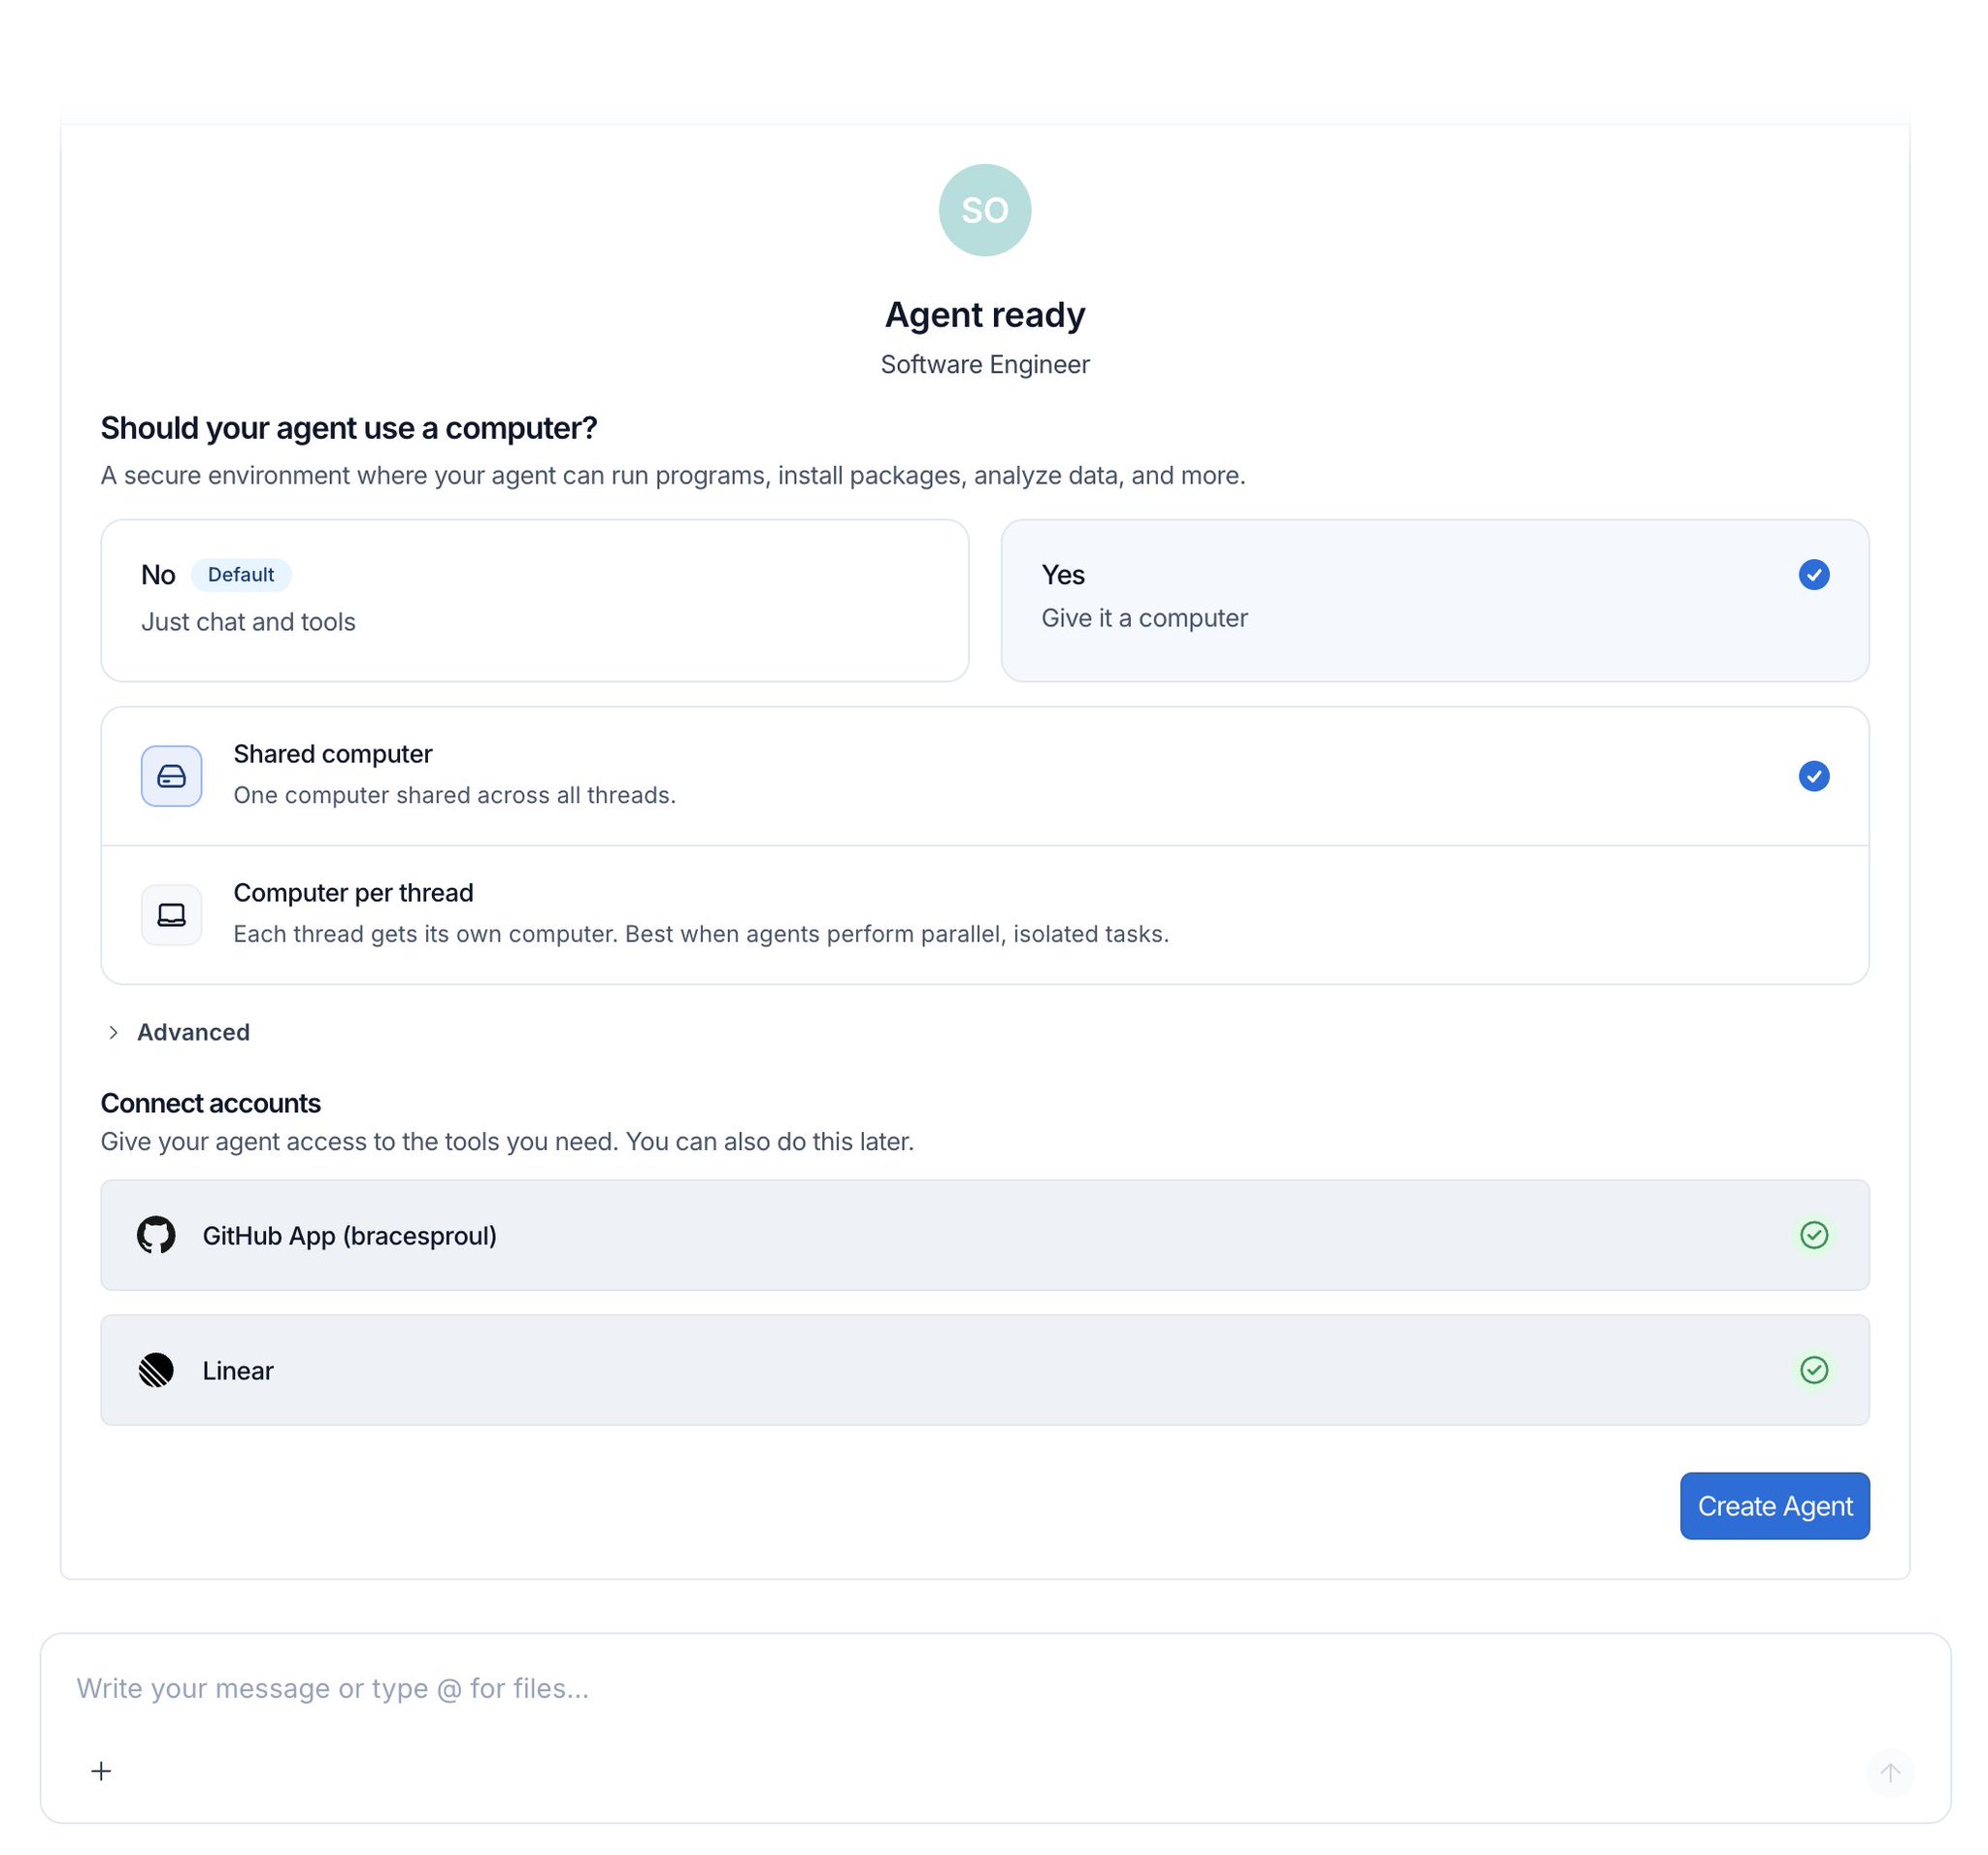
Fleet AI Agents Now Capable of Secure Code Execution and Analysis
By
–
Fleet agents can now securely write and run code. With computer use in LangSmith Fleet, agents get isolated execution environments. Analyze data, transform files, generate & write code, and run shell commands all within a secure virtual computer. Now in public beta.