
This paper shows that you can predict actual purchase intent (90% accuracy) by asking an LLM to impersonate a customer with a demographic profile, giving it a product & having it give its impressions, which another AI rates. No fine-tuning or training & beats classic ML methods.
MACHINE LEARNING
-
Neural Network Implementation in NumPy with Manual Backpropagation
By
–
Been there, done that . But how about a a neural net in NumPy with manual backprop? https://
github.com/rasbt/python-m
achine-learning-book/blob/master/code/ch12/neuralnet.py
… That was 10 years ago, makes me feel so old now -
Jamba Reasoning 3B: Tiny Open-Source Model Excels at Reasoning Tasks
By
–
@VentureBeat spotlights Jamba Reasoning 3B, our tiny open-source model that outperforms others across reasoning benchmarks and runs securely on-device. Read the feature
-

BAIR Researchers Win Outstanding Paper Award at COLM2025
By
–
Congratulations to BAIR Researchers from @trevordarrell lab whose paper "Hidden in plain sight: VLMs overlook their visual representations," was awarded an Outstanding Paper Award at #COLM2025 this week in Montreal, Canada. @xkungfu @tylerraye @databoydg
-
Build Autograd Engine, Mini-GPT, and LoRA Fine-tuning From Scratch
By
–
– build an autograd engine from scratch
– write a mini-GPT from scratch
– implement LoRA and fine-tune a model on real data
– hate CUDA at least once
– cry
– keep going the roadmap – 5 phases
– if you already know something? skip
– if you're lost? rewatch
– if you’re stuck? use -
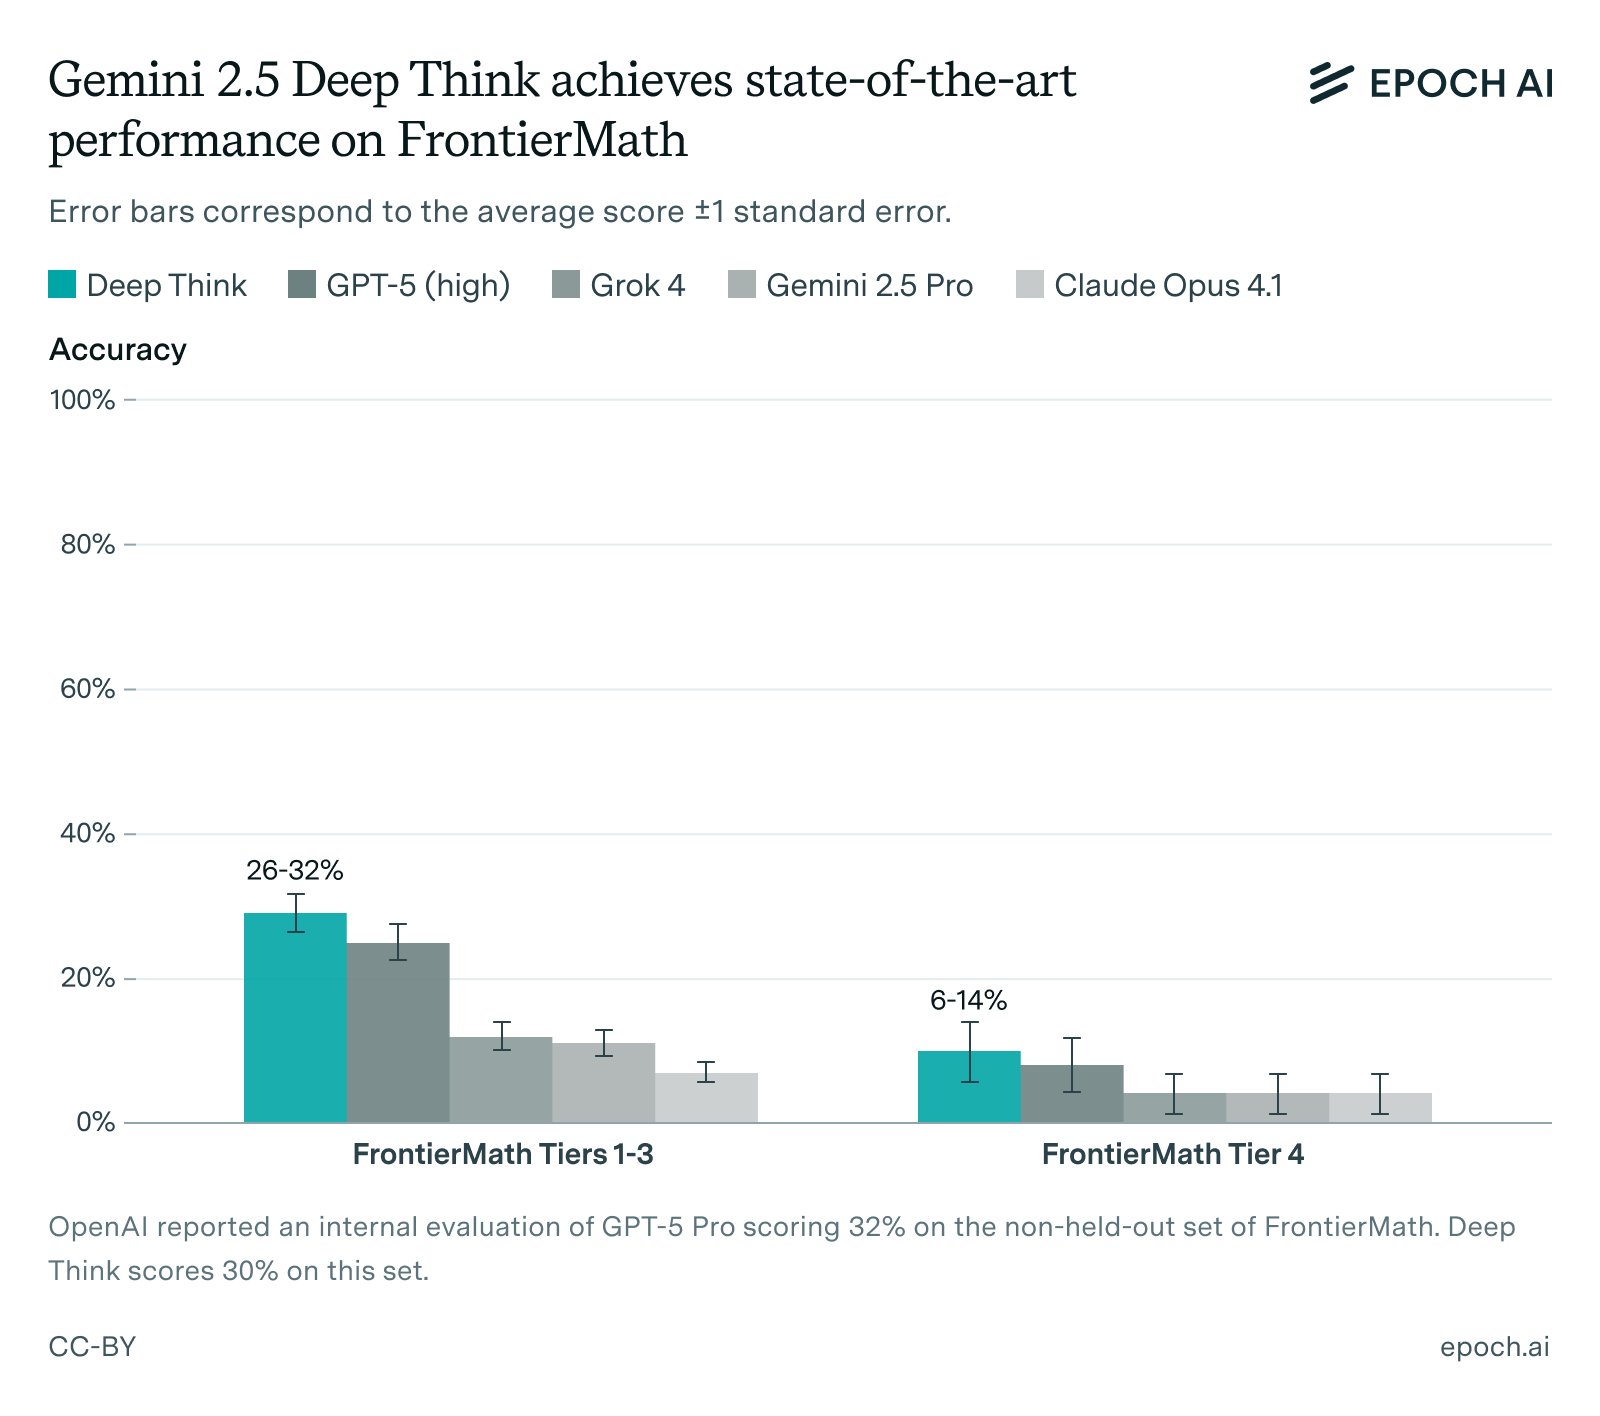
DeepThink IMO Gold Model Achieves State-of-the-Art FrontierMath Results
By
–
Very cool to see this new state-of-the-art result on FrontierMath achieved by the #DeepThink IMO Gold model that we built 3 months (a long time) ago 🙂 The fact that is evaluated externally using a publicly available API is a strong testament that what we built generalizes beyond
-
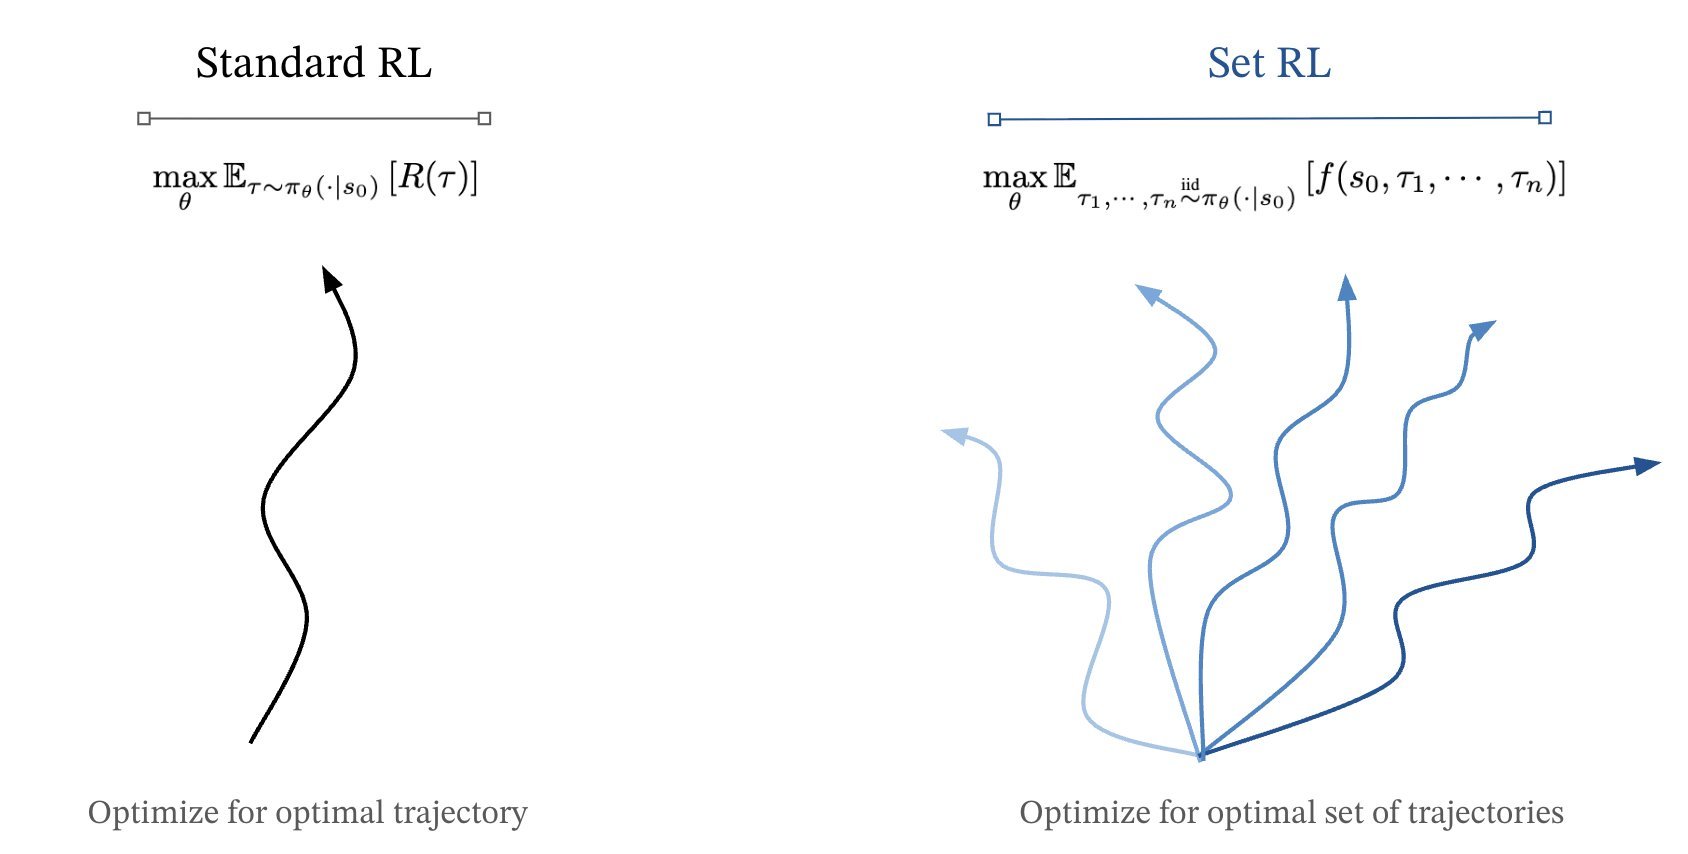
Multiple RL Trajectories Improve Agent Strategy Diversity
By
–
We have always been using 1 RL trajectory for training. Why not use more? In this research: Polychromic Objectives for RL, they train their model on sets of trajectories and reward both success & diversity, so the agent keeps MULTIPLE strategies alive all at once.
-
Sequential Decoding Behavior in Diffusion Language Models
By
–
interesting, if it is a DLM why does it seem to decode sequentially?
