I am thrilled to see Omar Yaghi win the Nobel Prize in Chemistry today. I have had the privilege to interact with him and collaborate with him. This is a paper from a couple of years ago which one of the first attempts to use generative models for improving MOFs with
MACHINE LEARNING
-

AI Gym Buddy Monitors Form and Counts Reps
By
–
Check out this AI gym buddy that monitors your form and counts reps. Server/client setup ready for gym deployment without any extra gear. Making workouts safer with edge AI Demo: https://
eu1.hubs.ly/H0nGsLD0 -
Exploring Structural Equation Models for AI Analysis
By
–
Exploring Structural Equation Model (SEM). Looks interesting.
-
Continuous Learning Improves Model Credibility Through Linear Source Reading
By
–
If we sort out continuous learning such that large models don’t just get a batch of snippet stew out of a blender, and read sources linearly, it may help with credibility assessment.
-
Midjourney Releases V7: First New AI Image Model in Year
By
–
Midjourney releases V7, its first new AI image model in nearly a year #AI #AIio #AIInnovation #ML #DataScience #Futureofwork @timnitgebru @oriolvinyalsml @ceobillionaire @soumithchintala @waitin4agi_ @sallyeaves @bernardmarr
-

Jamba Reasoning 3B: Exceptional Performance on Extended Contexts
By
–
3/5 Where most other tiny models choke at context lengths above 8K, Jamba Reasoning 3B stays steady, with a consistent 30-40 tokens/second on an M3 MacBook Pro, regardless of context size. This is up to an order of magnitude faster than other on-device models.
-
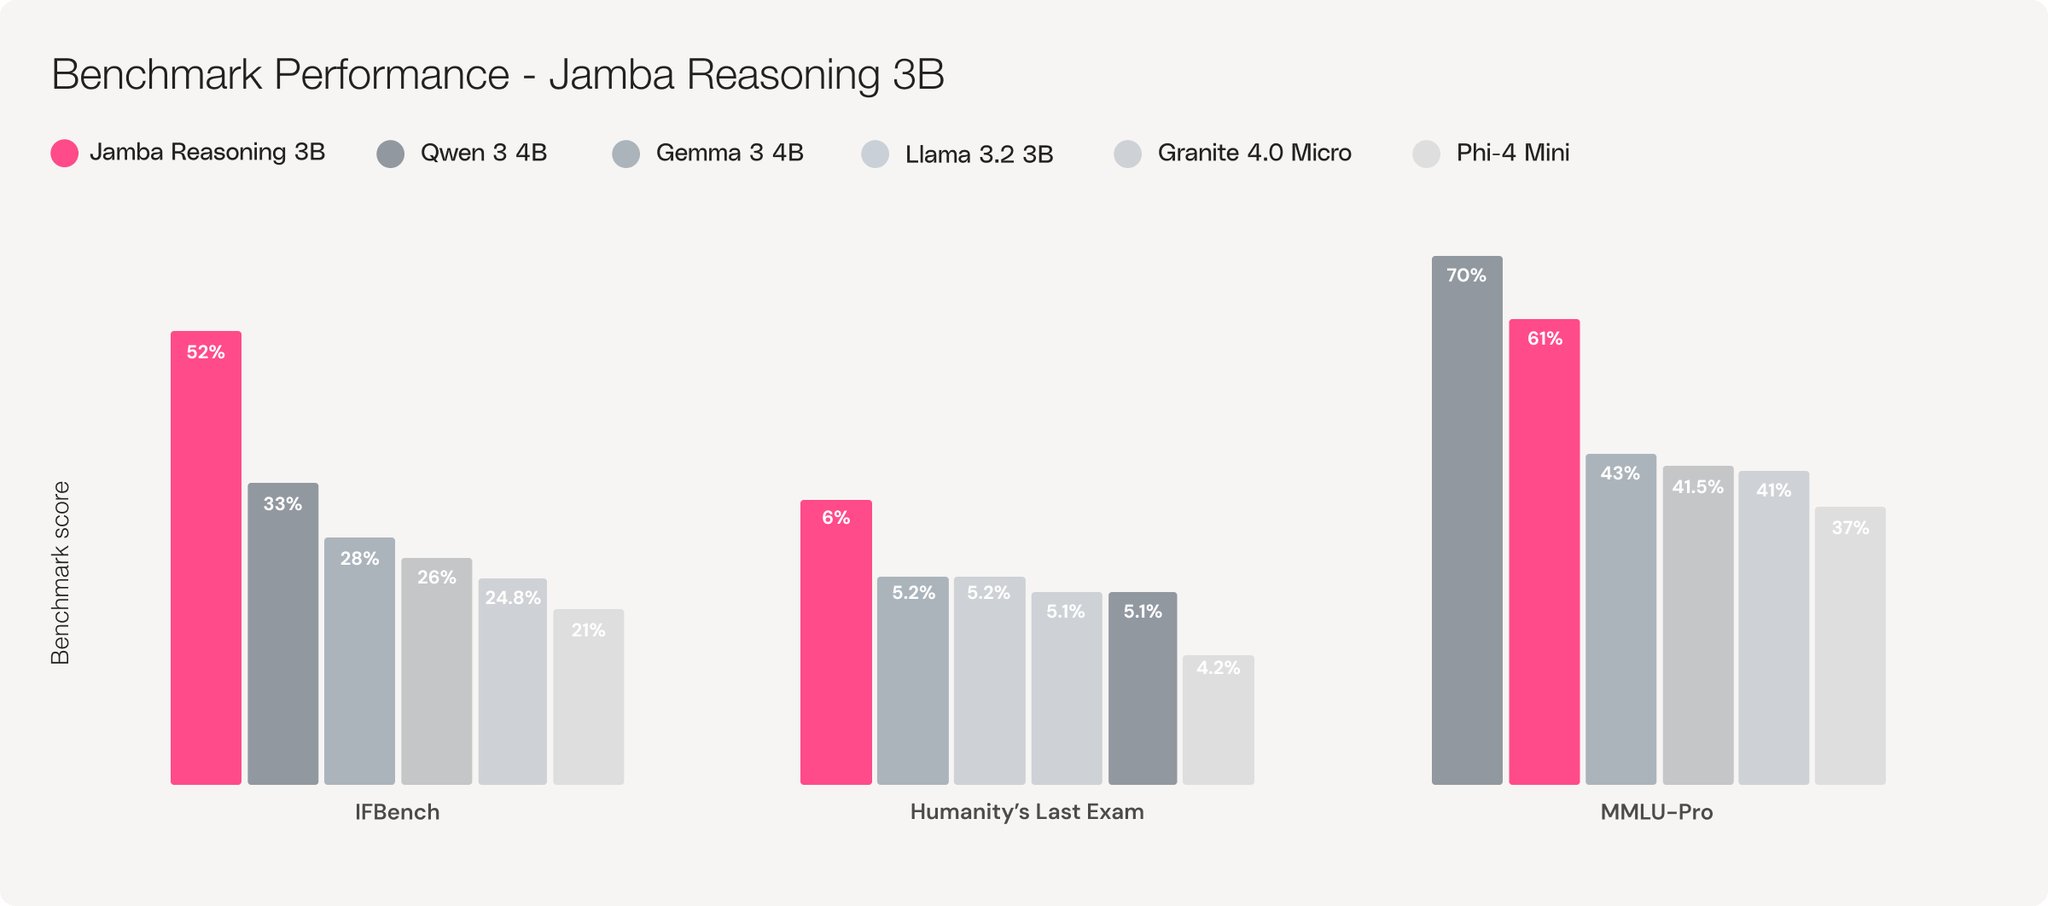
Jamba Reasoning 3B Excels in Knowledge and Instruction-Following
By
–
2/5 Jamba Reasoning 3B excels in general knowledge benchmarks (MMLU-Pro, HLE) and instruction-following (IFBench), making it reliable and performant
-

Jamba Reasoning 3B: Hybrid SSM-Transformer Apache 2.0 Release
By
–
1/5 Releasing Jamba Reasoning 3B under Apache 2.0: Hybrid SSM-Transformer architecture that tops accuracy & speed across record context lengths. e.g. 3-5X faster than Llama 3.2 3B and Qwen3 4B at 32K tokens.
-
Gaussian Embeddings: How JEPAs Learn Data Density
By
–
Gaussian Embeddings: How JEPAs Secretly Learn Your Data Density Paper:
-

JEPA Anti-Collapse Term Implicitly Estimates Data Density
By
–
Yann LeCun's team is continuously advancing JEPA. Their new study reveals that the anti-collapse term in Joint Embedding Predictive Architectures (JEPAs) does more than just prevent trivial representations — it implicitly estimates data density. This means any trained JEPA