Spontaneous morning chat with Juergen Schmidhuber and Jake Newfield philosophizing about AI. Sry my mic somehow disconnected but Juergen had the more interesting points anyways!
@rasbt
-
Introduction and Implementation of RLVR and GRPO
By
–
Reasoning from scratch, round number 6!
— Sebastian Raschka (@rasbt) 3 octobre 2026
An introduction (and implementation) of Reinforcement Learning with Verifiable Rewards (RLVR) and Group Relative Policy Optimization (GRPO).
00:00 Introduction
01:54 What makes a reasoning model different?
04:25 Reasoning traces and model… pic.twitter.com/tM3nSR22EQReasoning from scratch, round number 6! An introduction (and implementation) of Reinforcement Learning with Verifiable Rewards (RLVR) and Group Relative Policy Optimization (GRPO). 00:00 Introduction
01:54 What makes a reasoning model different?
04:25 Reasoning traces and model -
OpenAI Decision API built on GPT-6 Luna with decision head
By
–
Interestingly, just overheard in @swyx podcast interviewing an OpenAI engineer, their Decision API is literally built on GPT-6 Luna adding a decision head.
-
Liquid AI proprietary models and data privacy concerns
By
–
This is cool, and Liquid AI has some solid models, so I believe that this could actually quite capable. However, it's also proprietary, so it's trading one proprietary model for another, which doesn't address the data privacy concerns.
-
No speed difference, but Ollama offers nice quantized models and easy switching
By
–
It's been a few months but I didn't see a noticeable speed difference tbh. Otherwise, Ollama has usually a nice set of quantized models and easy to switch.
-
Decode 80 tok/sec at 1k, prefill 3000 tok/sec at 50k contexts
By
–
Yeah, this was at 50k contexts. Decode is about 80 tok/sec at 1k contexts. Prefill is up to 3000 tok/sec at
-
Question about Pi’s selling point over Cline for classic codex user
By
–
Thx. As someone who mostly uses classic codex, what's the like the selling point behind Pi over Cline etc?
-
GLM 5.0 report and IndexShare: only notable aspects
By
–
I was thinking about it, but beyond the original GLM 5.0 technical report, I don't think there's anything interesting to write about (except that it's better; and IndexShare, which is a rel simple concept)
-
Not yet tried Cline & Pi, comfortable with Codex due to muscle memory
By
–
No, not yet. There's also Cline & Pi I still have to try. (I am kind of comfortable with codex because of muscle memory.)
-
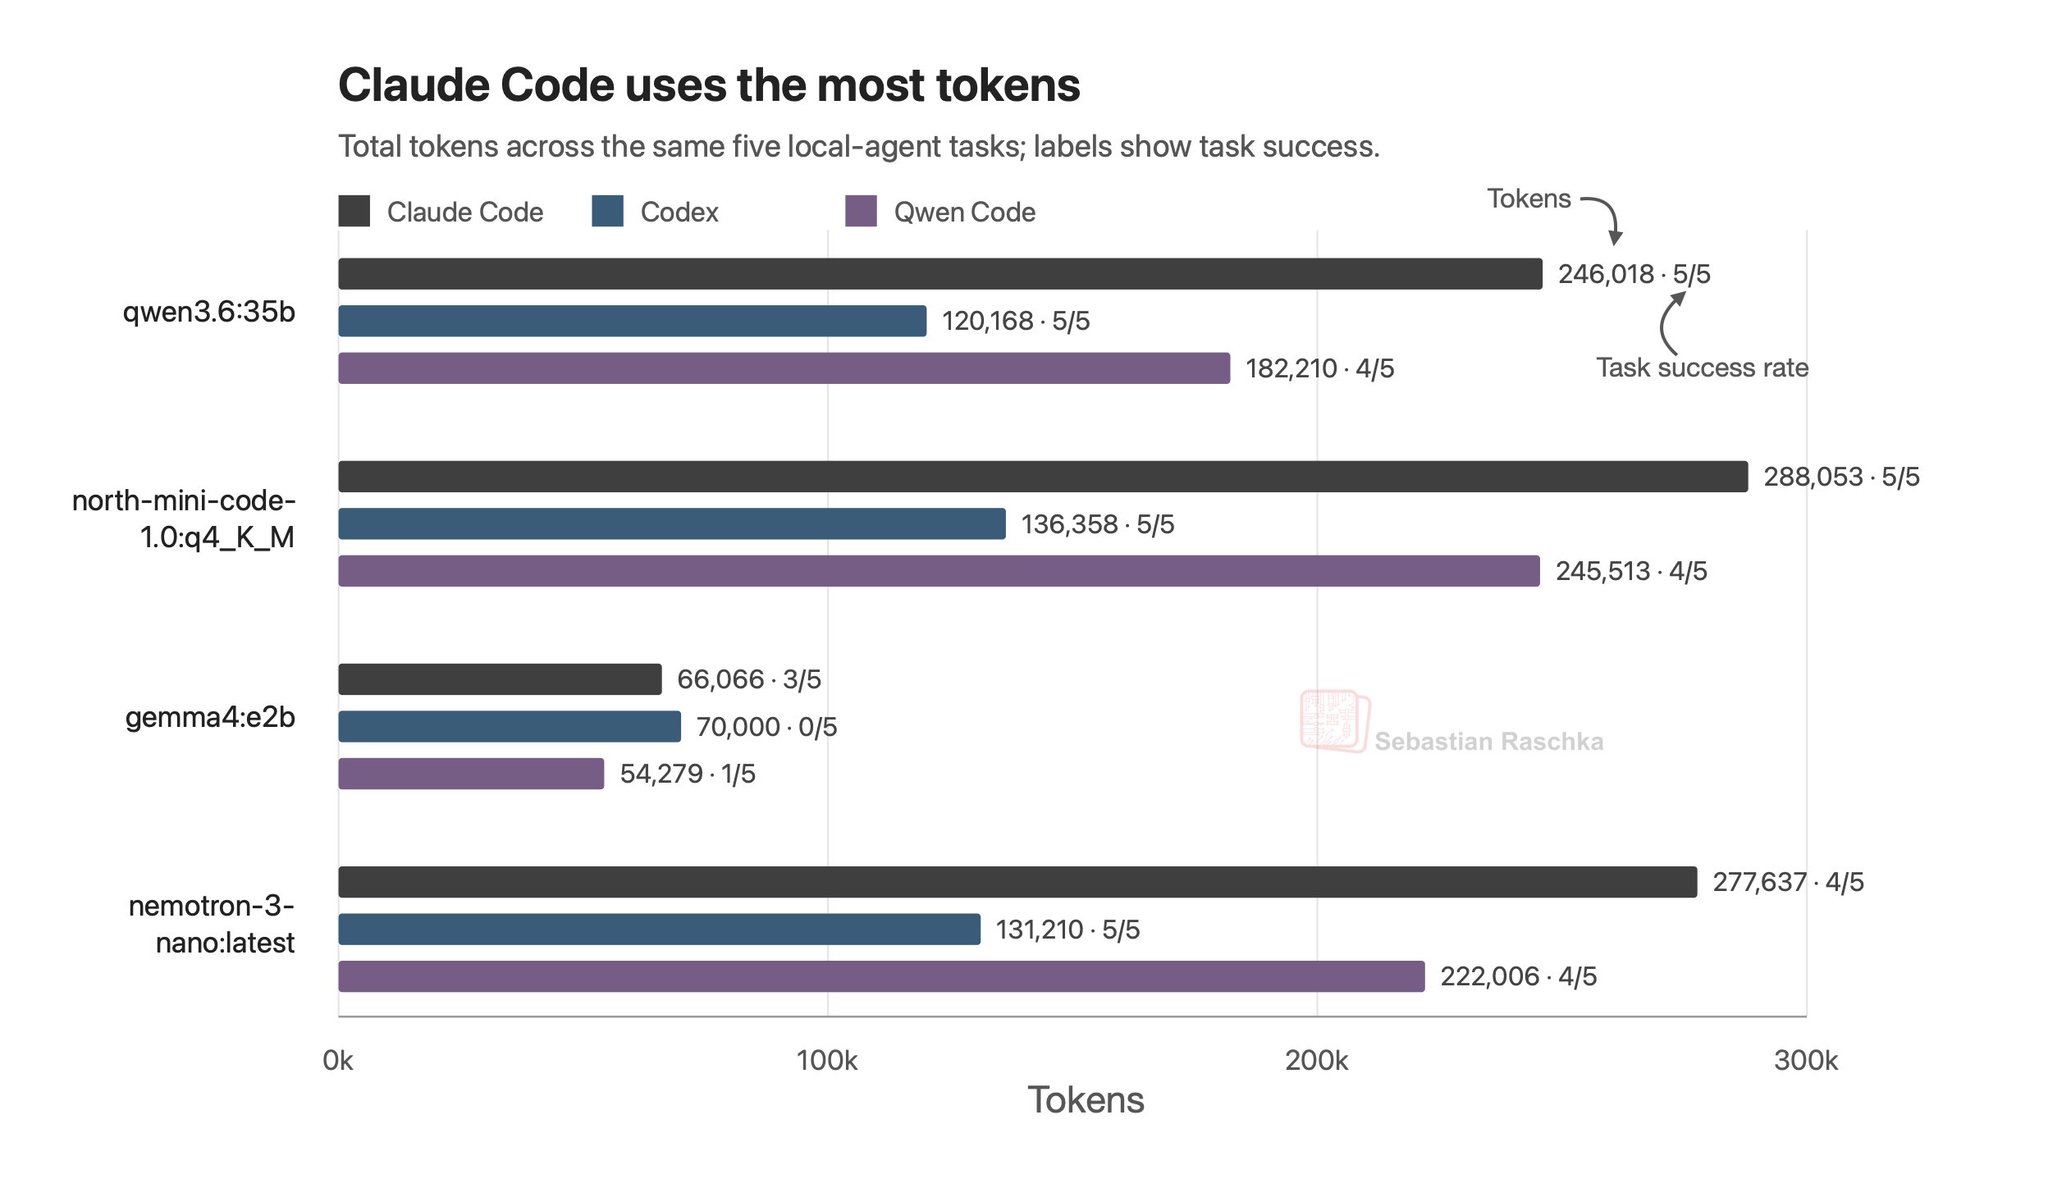
Local open-weight LLMs: 30B MoE sweet spot at 40 tok/sec
By
–
Have been taking different local open-weight LLMs for a test drive in different harnesses (Qwen-Code, Codex, Claude Code). 30B Mixture-of-Expert models are kind of a nice sweet spot and can solve challenging problems. And they get roughly 40 tok/sec on a Mac or DGX Spark, which