“limiting Claude’s effectiveness for requests aimed at developing cutting-edge LLMs” And that’s how they plan to widen the gap even further
@rasbt
-
MLA implemented using LoRA in Hugging Face Transformers
By
–
I actually agree and just realize that I totally skipped autoencoders here. Small fun fact though: (in Hugging Face transformers) MLA is implemented using the LoRA tooling
-
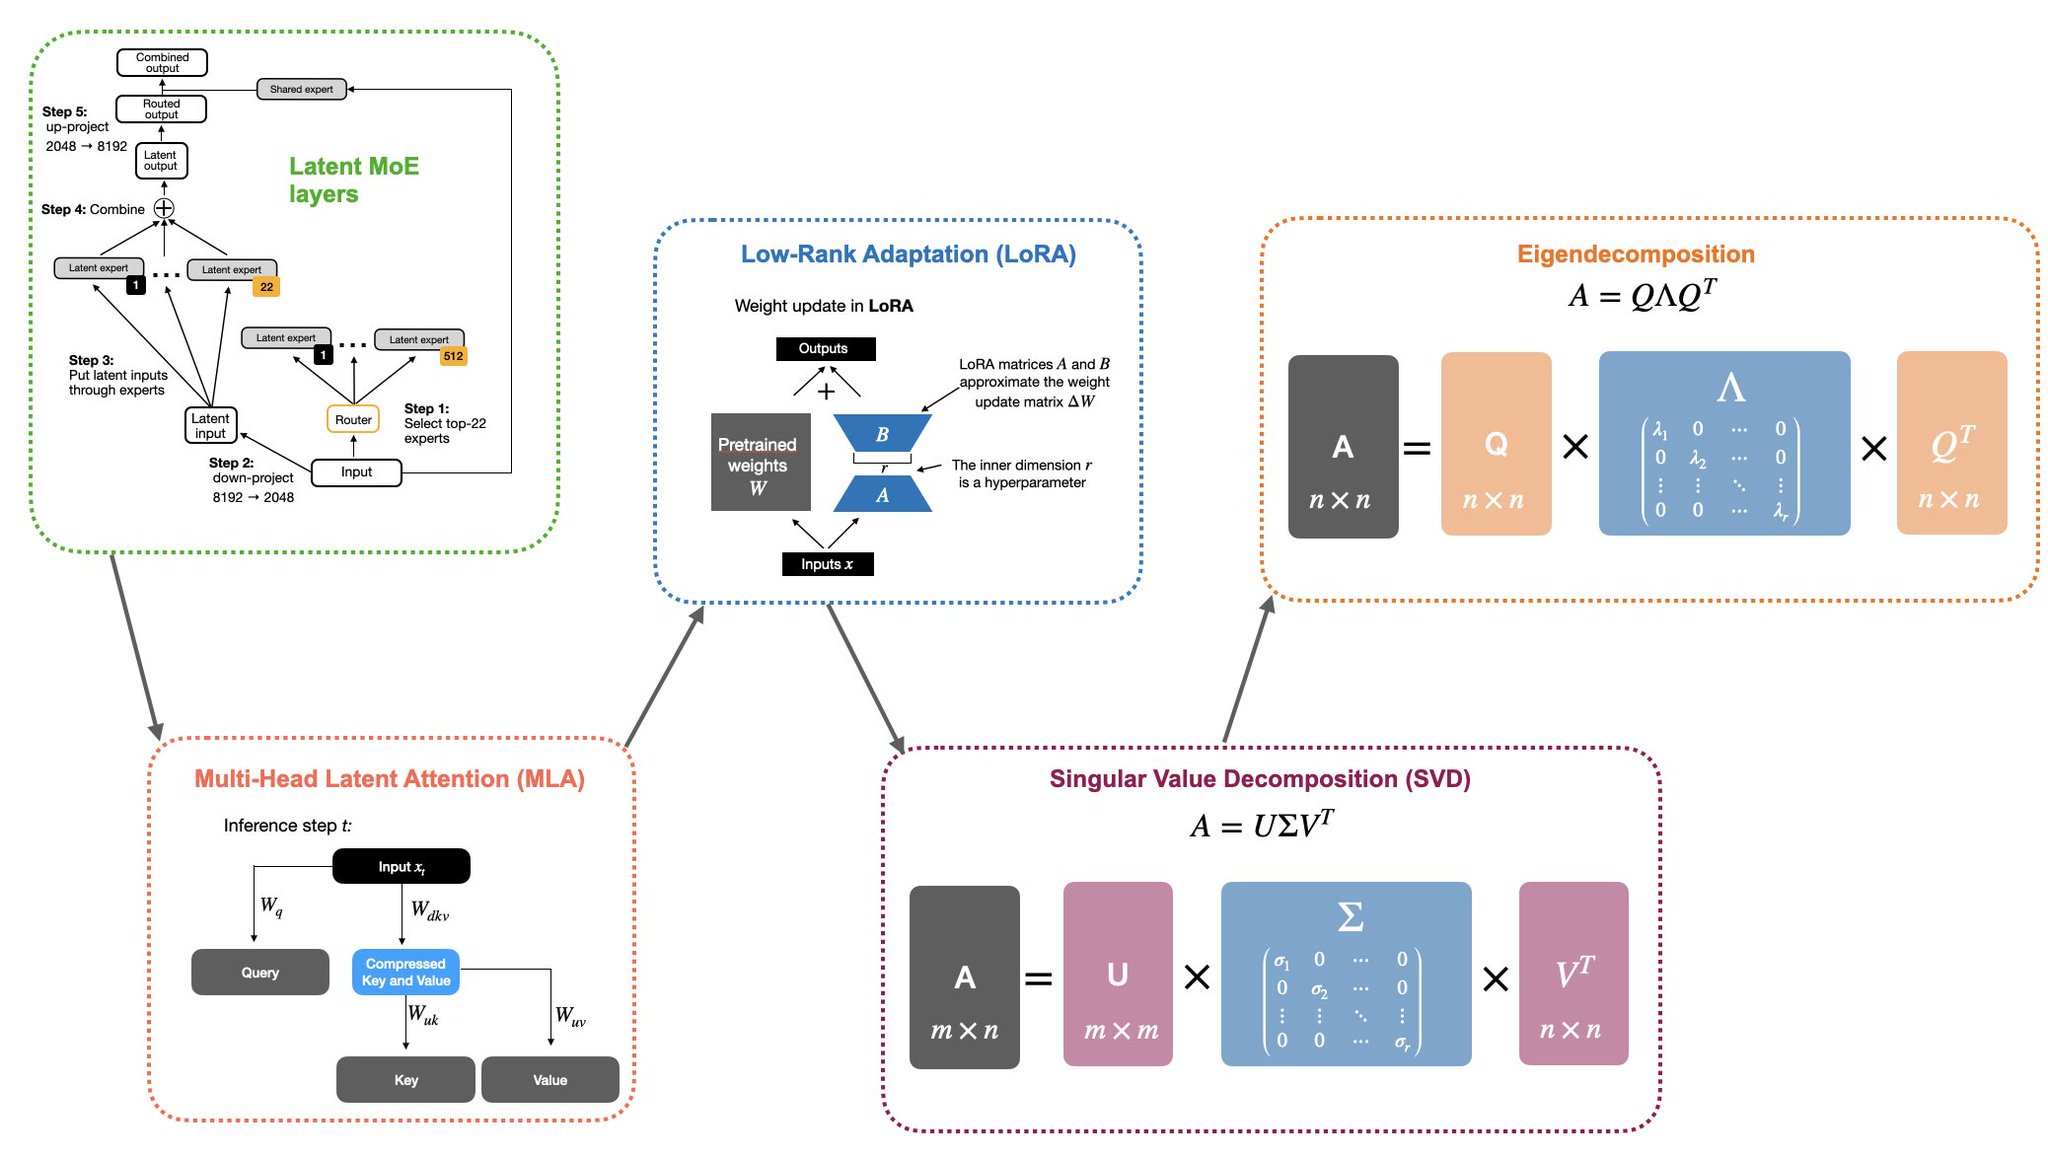
Lineage of techniques: from eigen decomposition to LatentMoE
By
–
Always go back to basics: LatentMoE was probably inspired by MLA, which was inspired by LoRA, which was inspired by SVD, which was inspired by eigenvalue decomposition.
-
Using LLM to draft implementation plans with checklists in .md
By
–
Yes. What works well though is drafting plan documents. In my experience, having the LLM write out an implementation plan that it can then check of in a .md helps a lot
-
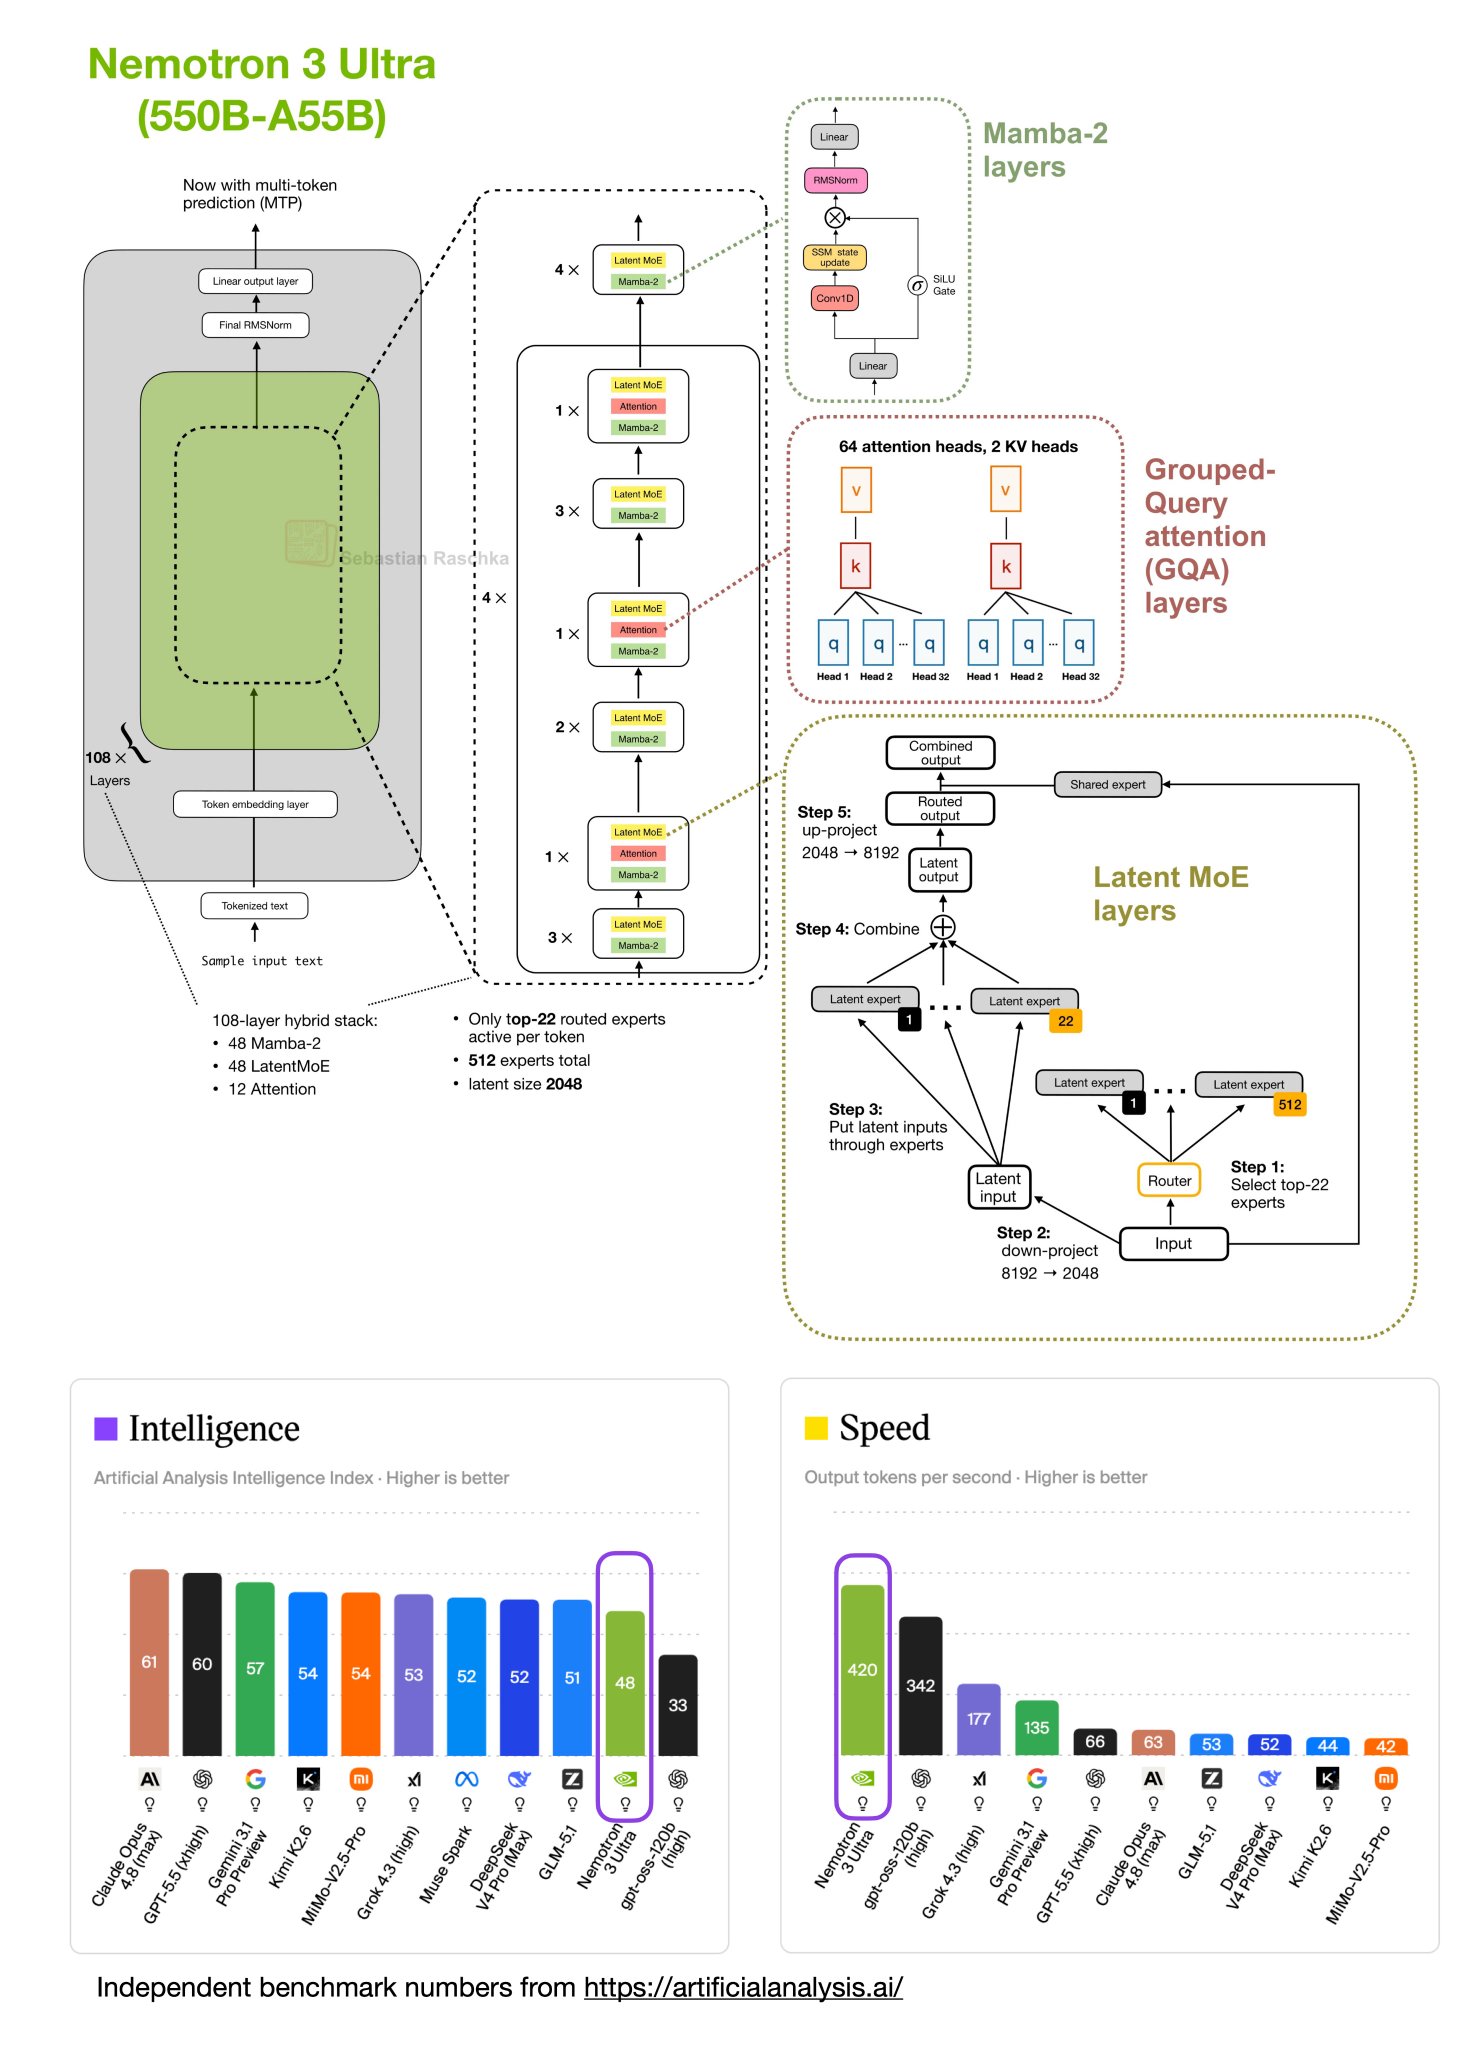
Nemotron 3 Ultra open-weight release boasts impressive efficiency ratio
By
–
And another open-weight release. Nemotron 3 Ultra has an ultra impressive capability:efficiency ratio! Design-wise, it carries forward the Mamba-2-attention hybrid stack and LatentMoE introduced in the previous Super variant. But everything is a bit bigger.
-
Simpler approach in Unified Embedding Decoder Architecture category
By
–
Conceptually, it fits nicely into the Unified Embedding Decoder Architecture category that I wrote about a while back: https://
magazine.sebastianraschka.com/p/understandin
g-multimodal-llms
…
I think it's the refreshingly simple(r) approach of the two. -
16GB VRAM Doable for Standard Hardware Except Long Context Tasks
By
–
Maybe for very long context agent tasks, but otherwise, 16GB VRAM is pretty doable on standard hardware
-
Gemma 4 12B released, runs comfortably on 16GB VRAM for LFM newcomers
By
–
They should all run comfortably (if you have ~16 GB VRAM). I am quite new to LFM's, and Gemma 4 12B just came out today, so time will tell…
-
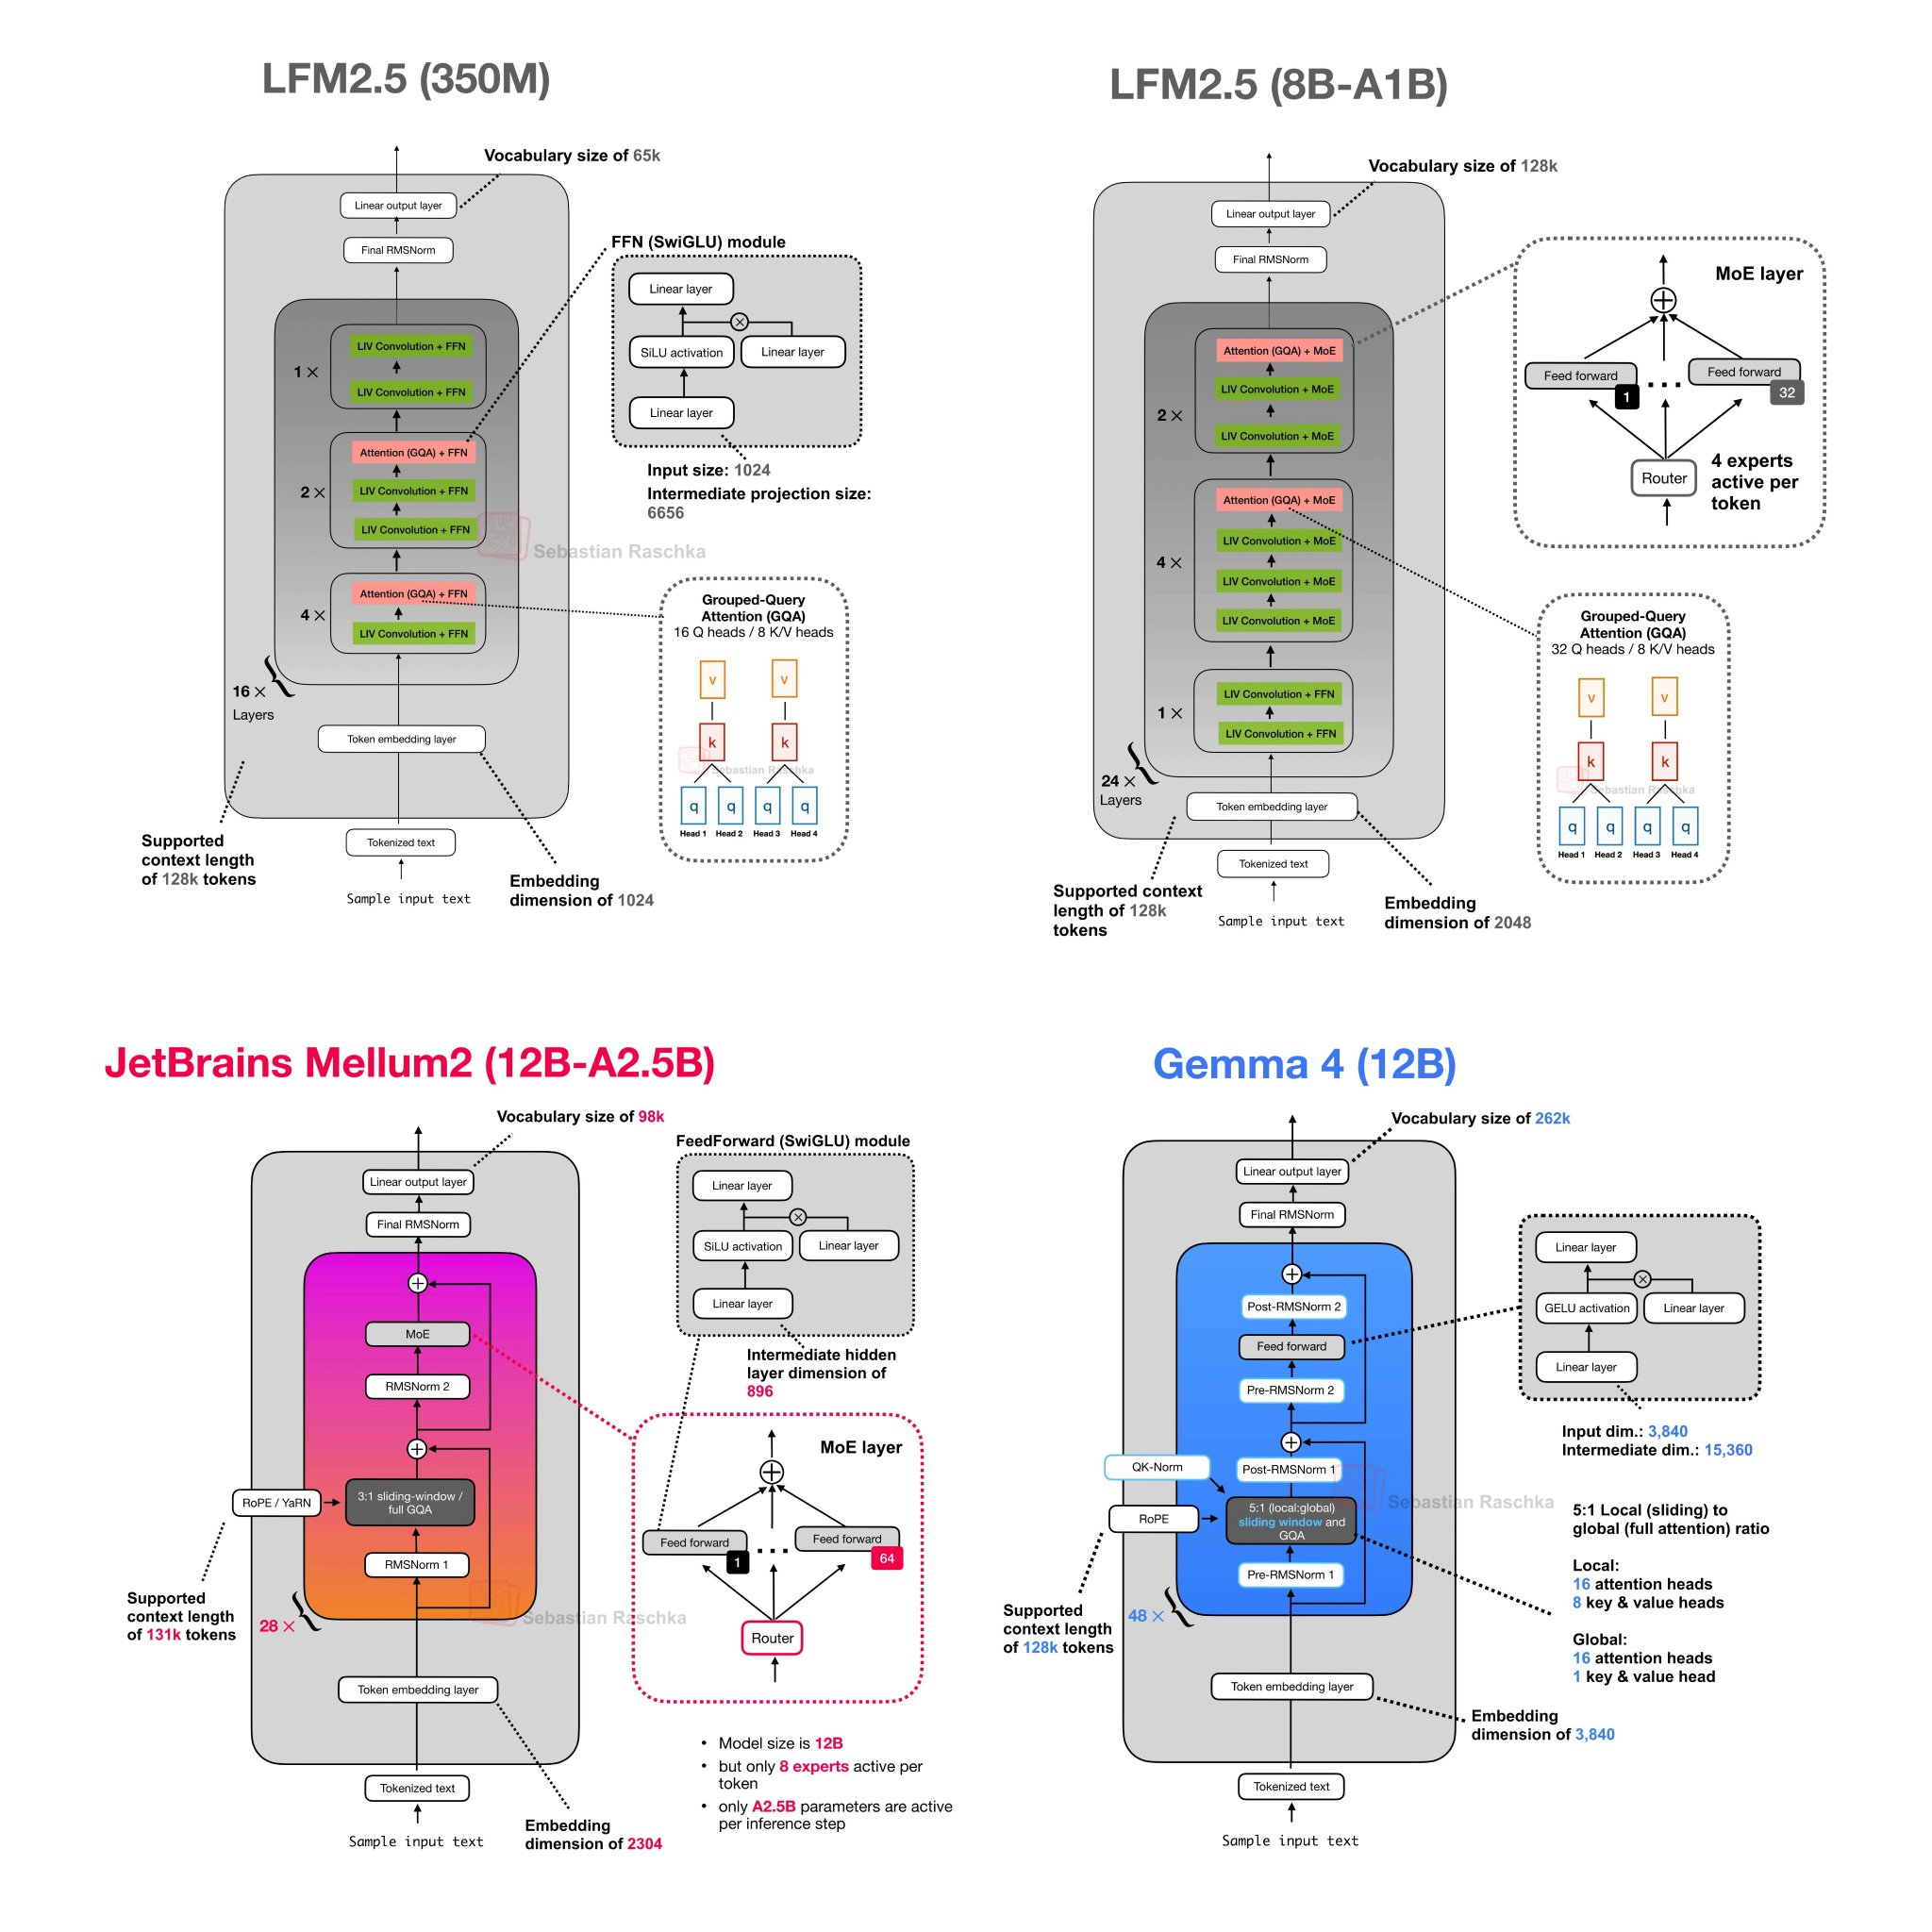
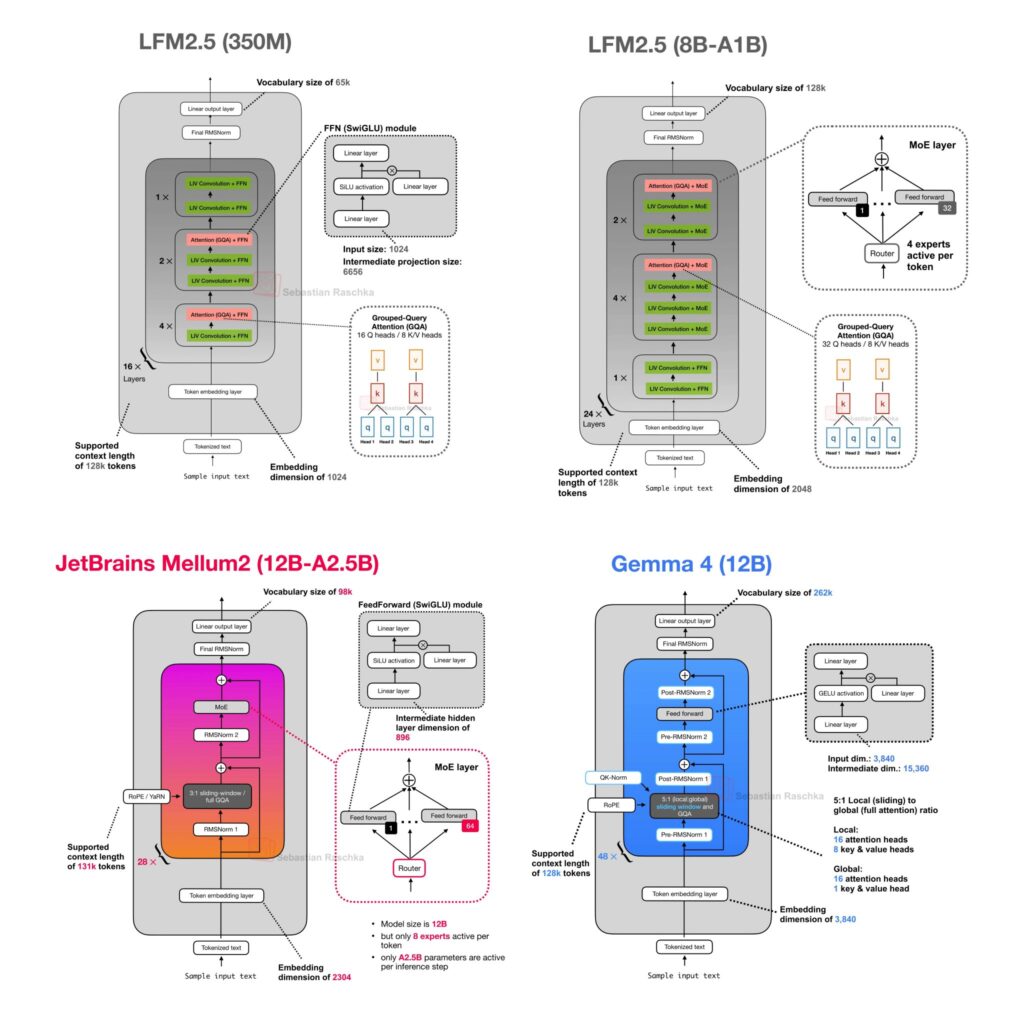
Four additions to open-weight local LLM on consumer hardware
By
–
It's been a while! 4 nice additions to the open-weight local-LLM-on-consumer-hardware ecosystem:
-
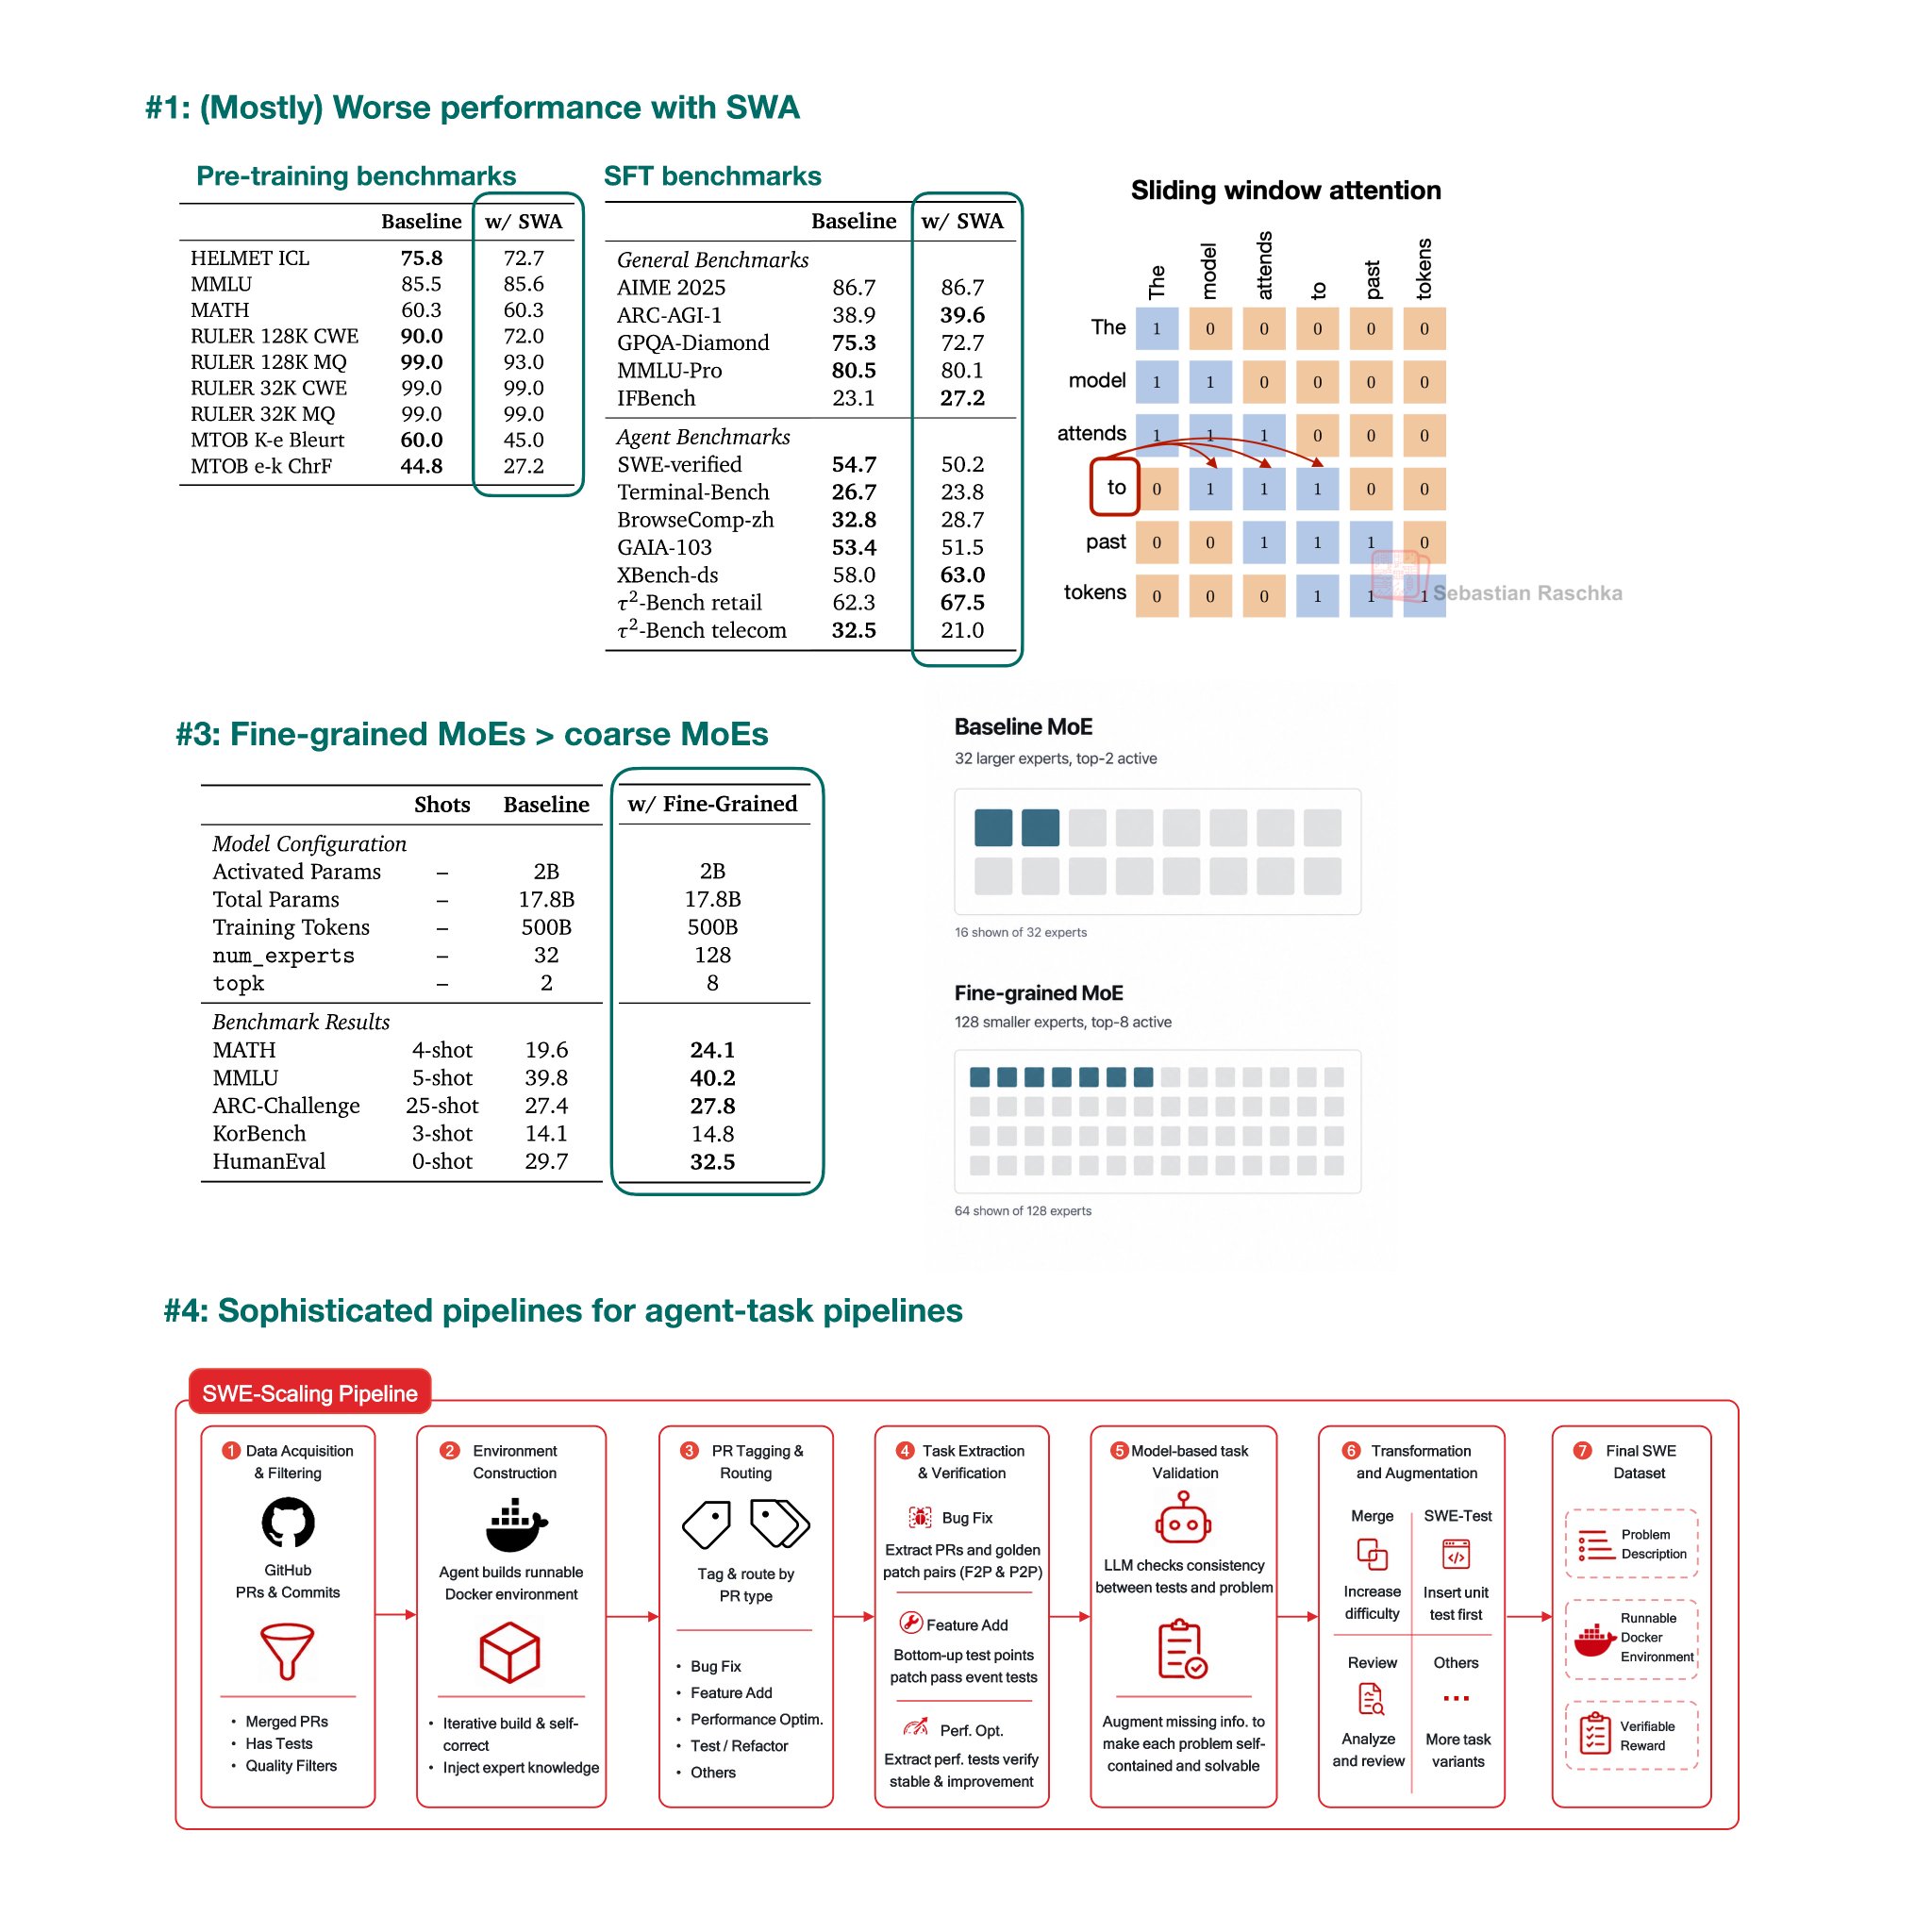
MiniMax M2 Technical Report: Attention Mechanism Analysis
By
–
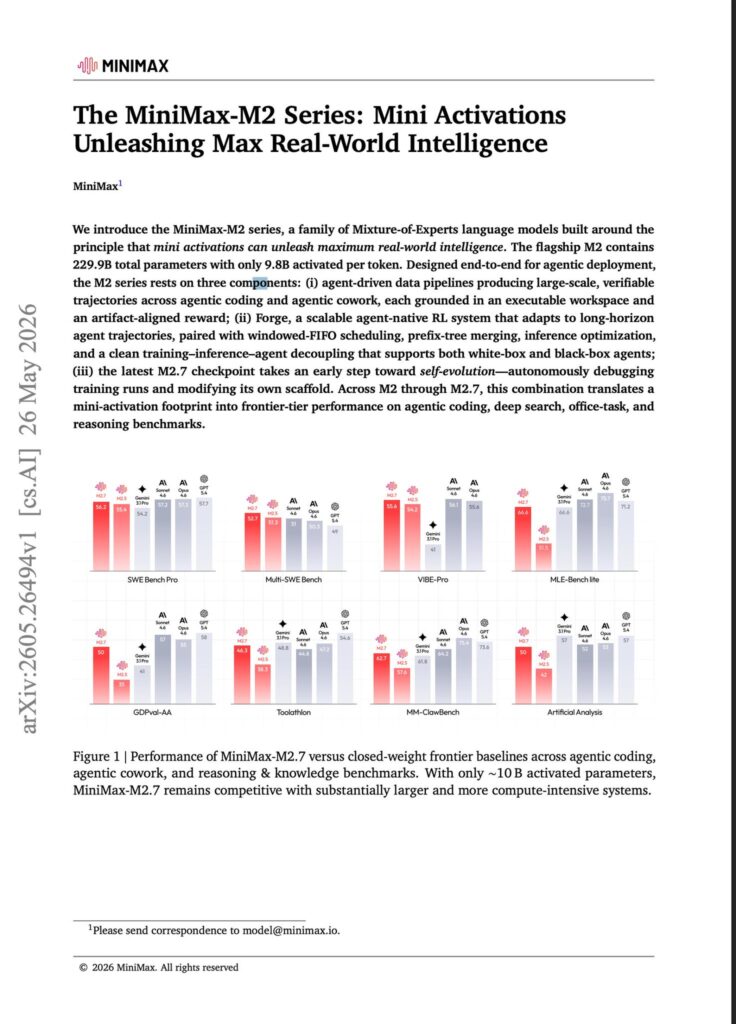
The MiniMax M2 series was one of the most widely used open-weight LLM series earlier this year. Now, we got a technical report with some interesting tidbits. I summarized some of them below: 1. Full attention as an anti-trend?: They tried hybrid sliding-window attention