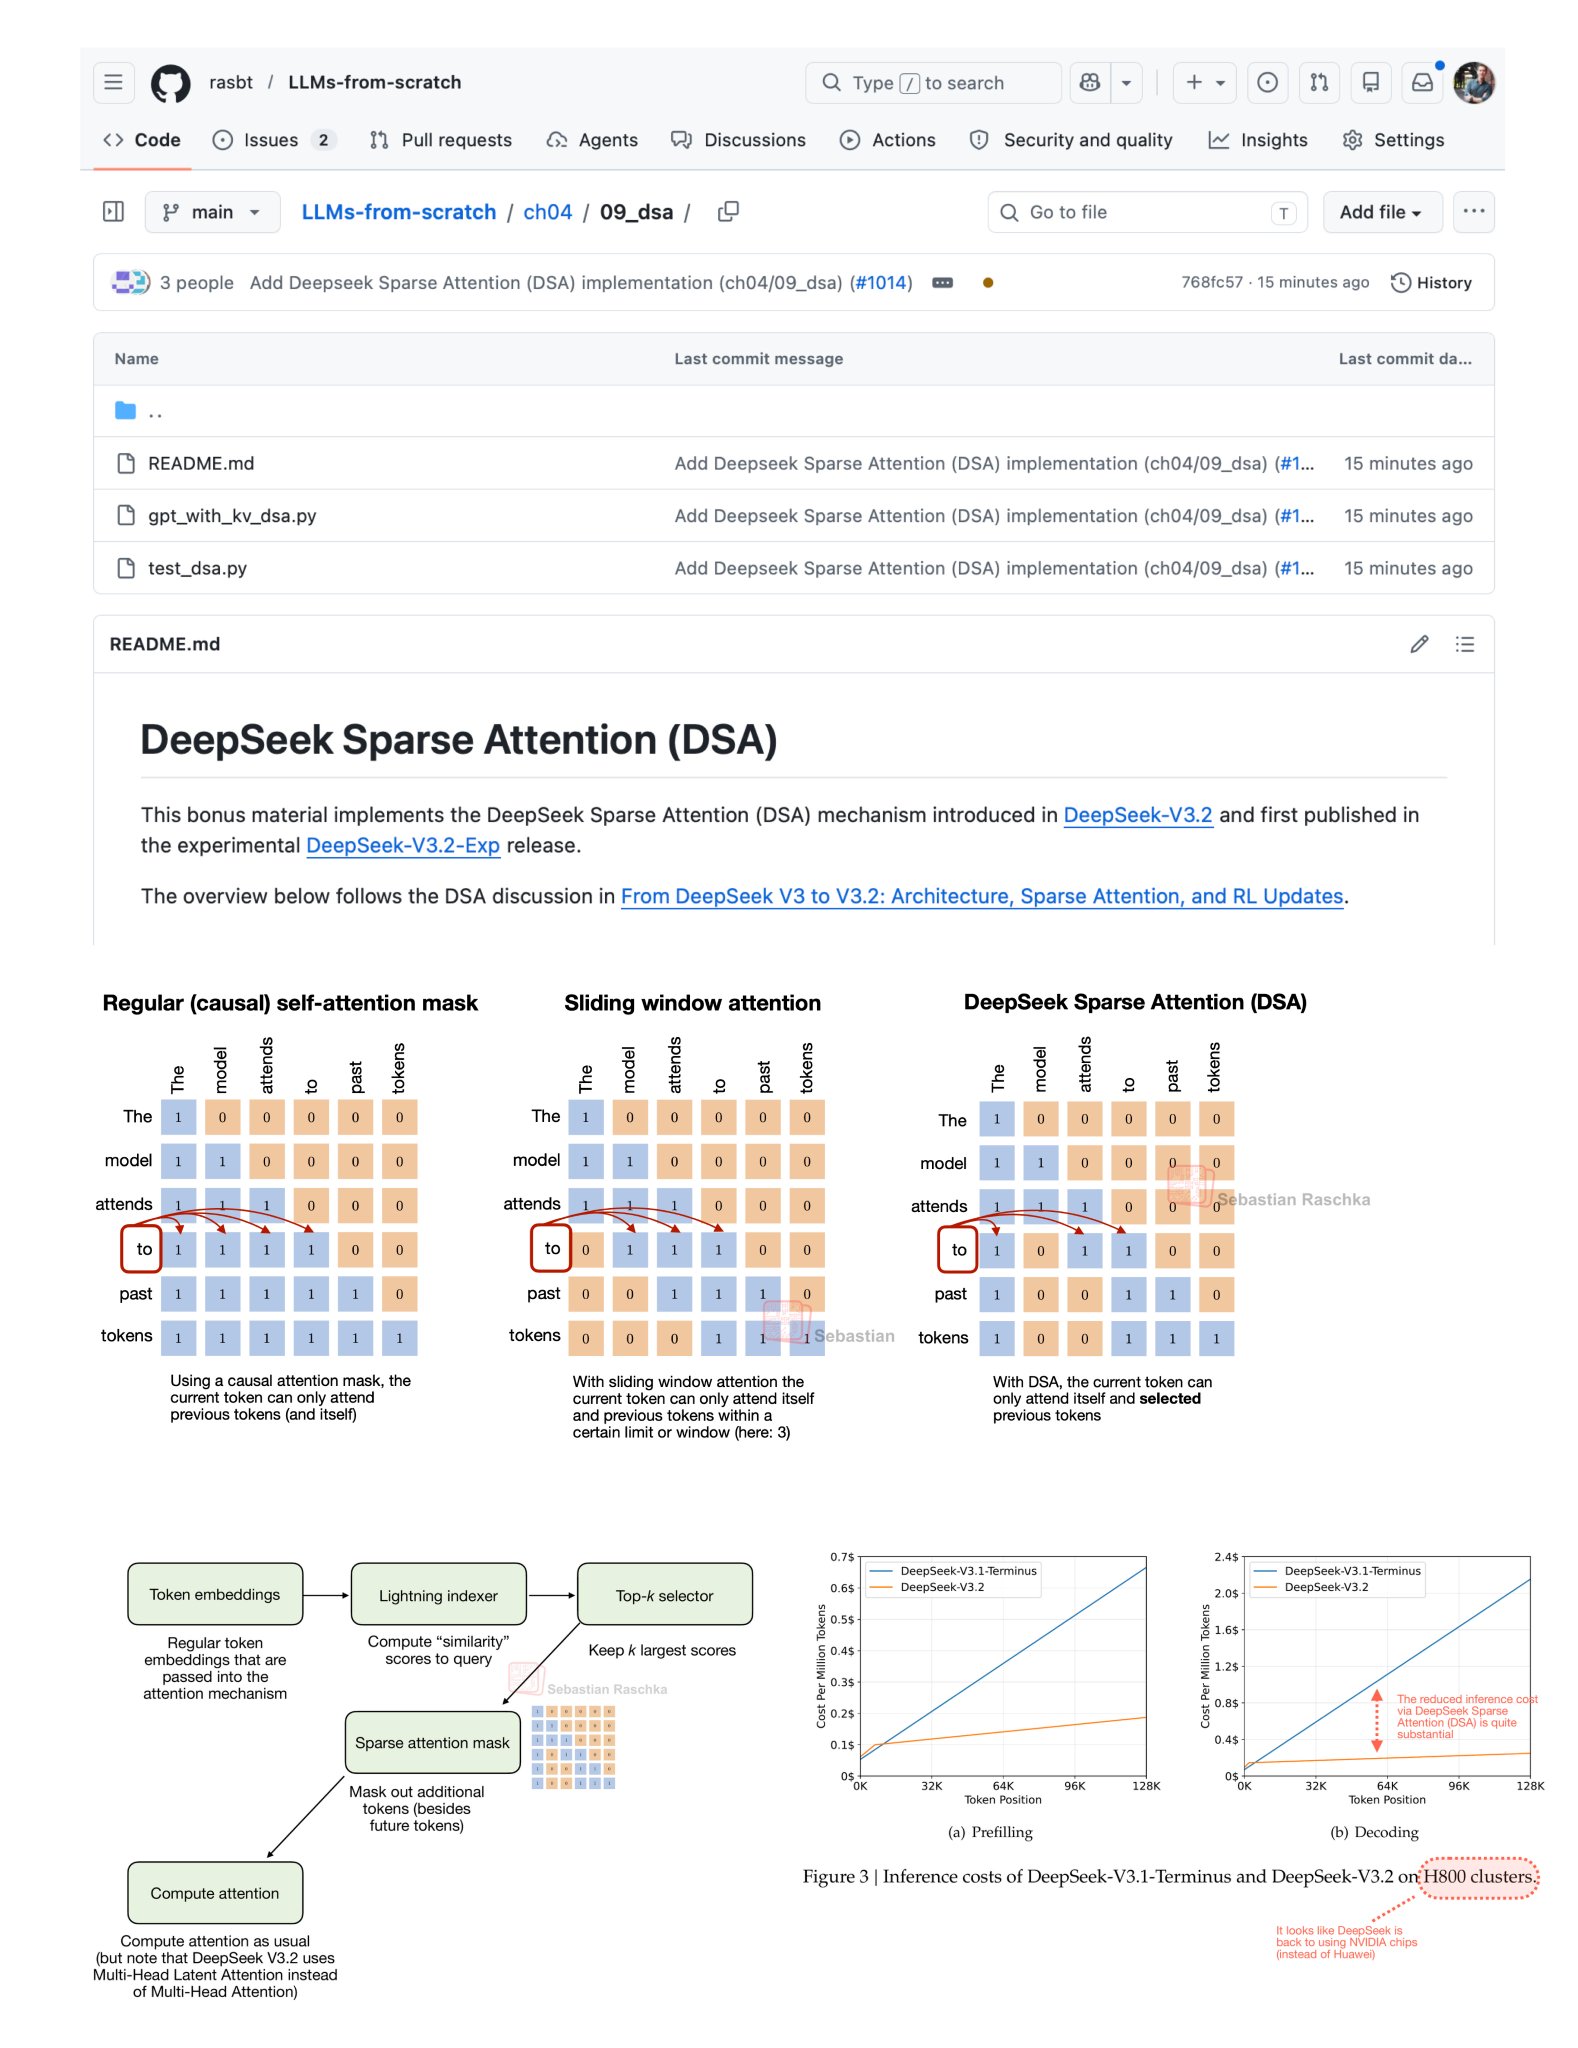
It’s just demoing the inference-time DSA top-k selection path at this point. The Lightning Indexer has trainable parameters, but this version does not train them (yet)
@rasbt
-
DeepSeek Sparse Attention Implementation in LLMs Repository
By
–
Added a DeepSeek Sparse Attention (DSA) from-scratch implementation to my LLMs-from-scratch repo thanks to an awesome new reader contrib. With motivation, overview, and GPT-style model reference implementation as standalone example code: https://
github.com/rasbt/LLMs-fro
m-scratch/tree/main/ch04/09_dsa
… -

Gated DeltaNet-2: Hybrid Attention Architecture Advancement
By
–
Gated DeltaNet has been one of my favorite "hybrid attention" newcomers in the good old transformer stack.
Excited to see Gated DeltaNet-2. Adding it to my reading stack. In the meantime, I have a primer on Gated DeltaNet here: https://
magazine.sebastianraschka.com/i/177848019/26
-gated-deltanet
… -
FFN Architecture Patterns in Mixture-of-Experts Models
By
–
It’s interesting. I’ve seen hidden -> wider -> hidden FFNs and hidden -> narrower -> hidden FFNs.
But Command A+ seems tu use 4096 -> 4096 -> 4096 for each expert FFN, which I haven’t seen before (as far as I remember) -
Technical training efficiency insights from the Tiny Aya model report
By
–
I think so. In their 3.35B Tiny Aya report, they say "We use parallel Transformer blocks, which lead to a signifi-
cant improvement in training efficiency without hurting model quality." -

Technical Analysis of Parallel Block Design in LLM Architectures
By
–
It's been *almost* a bit quiet around LLM architecture releases in the past two weeks Interesting tidbit is the parallel block design. Via the Cmd-A the tech report "equivalent performance but significant improvement in throughput compared to the vanilla transformer block."
-
A Visual Tour of Recent LLM Architecture Advances
By
–
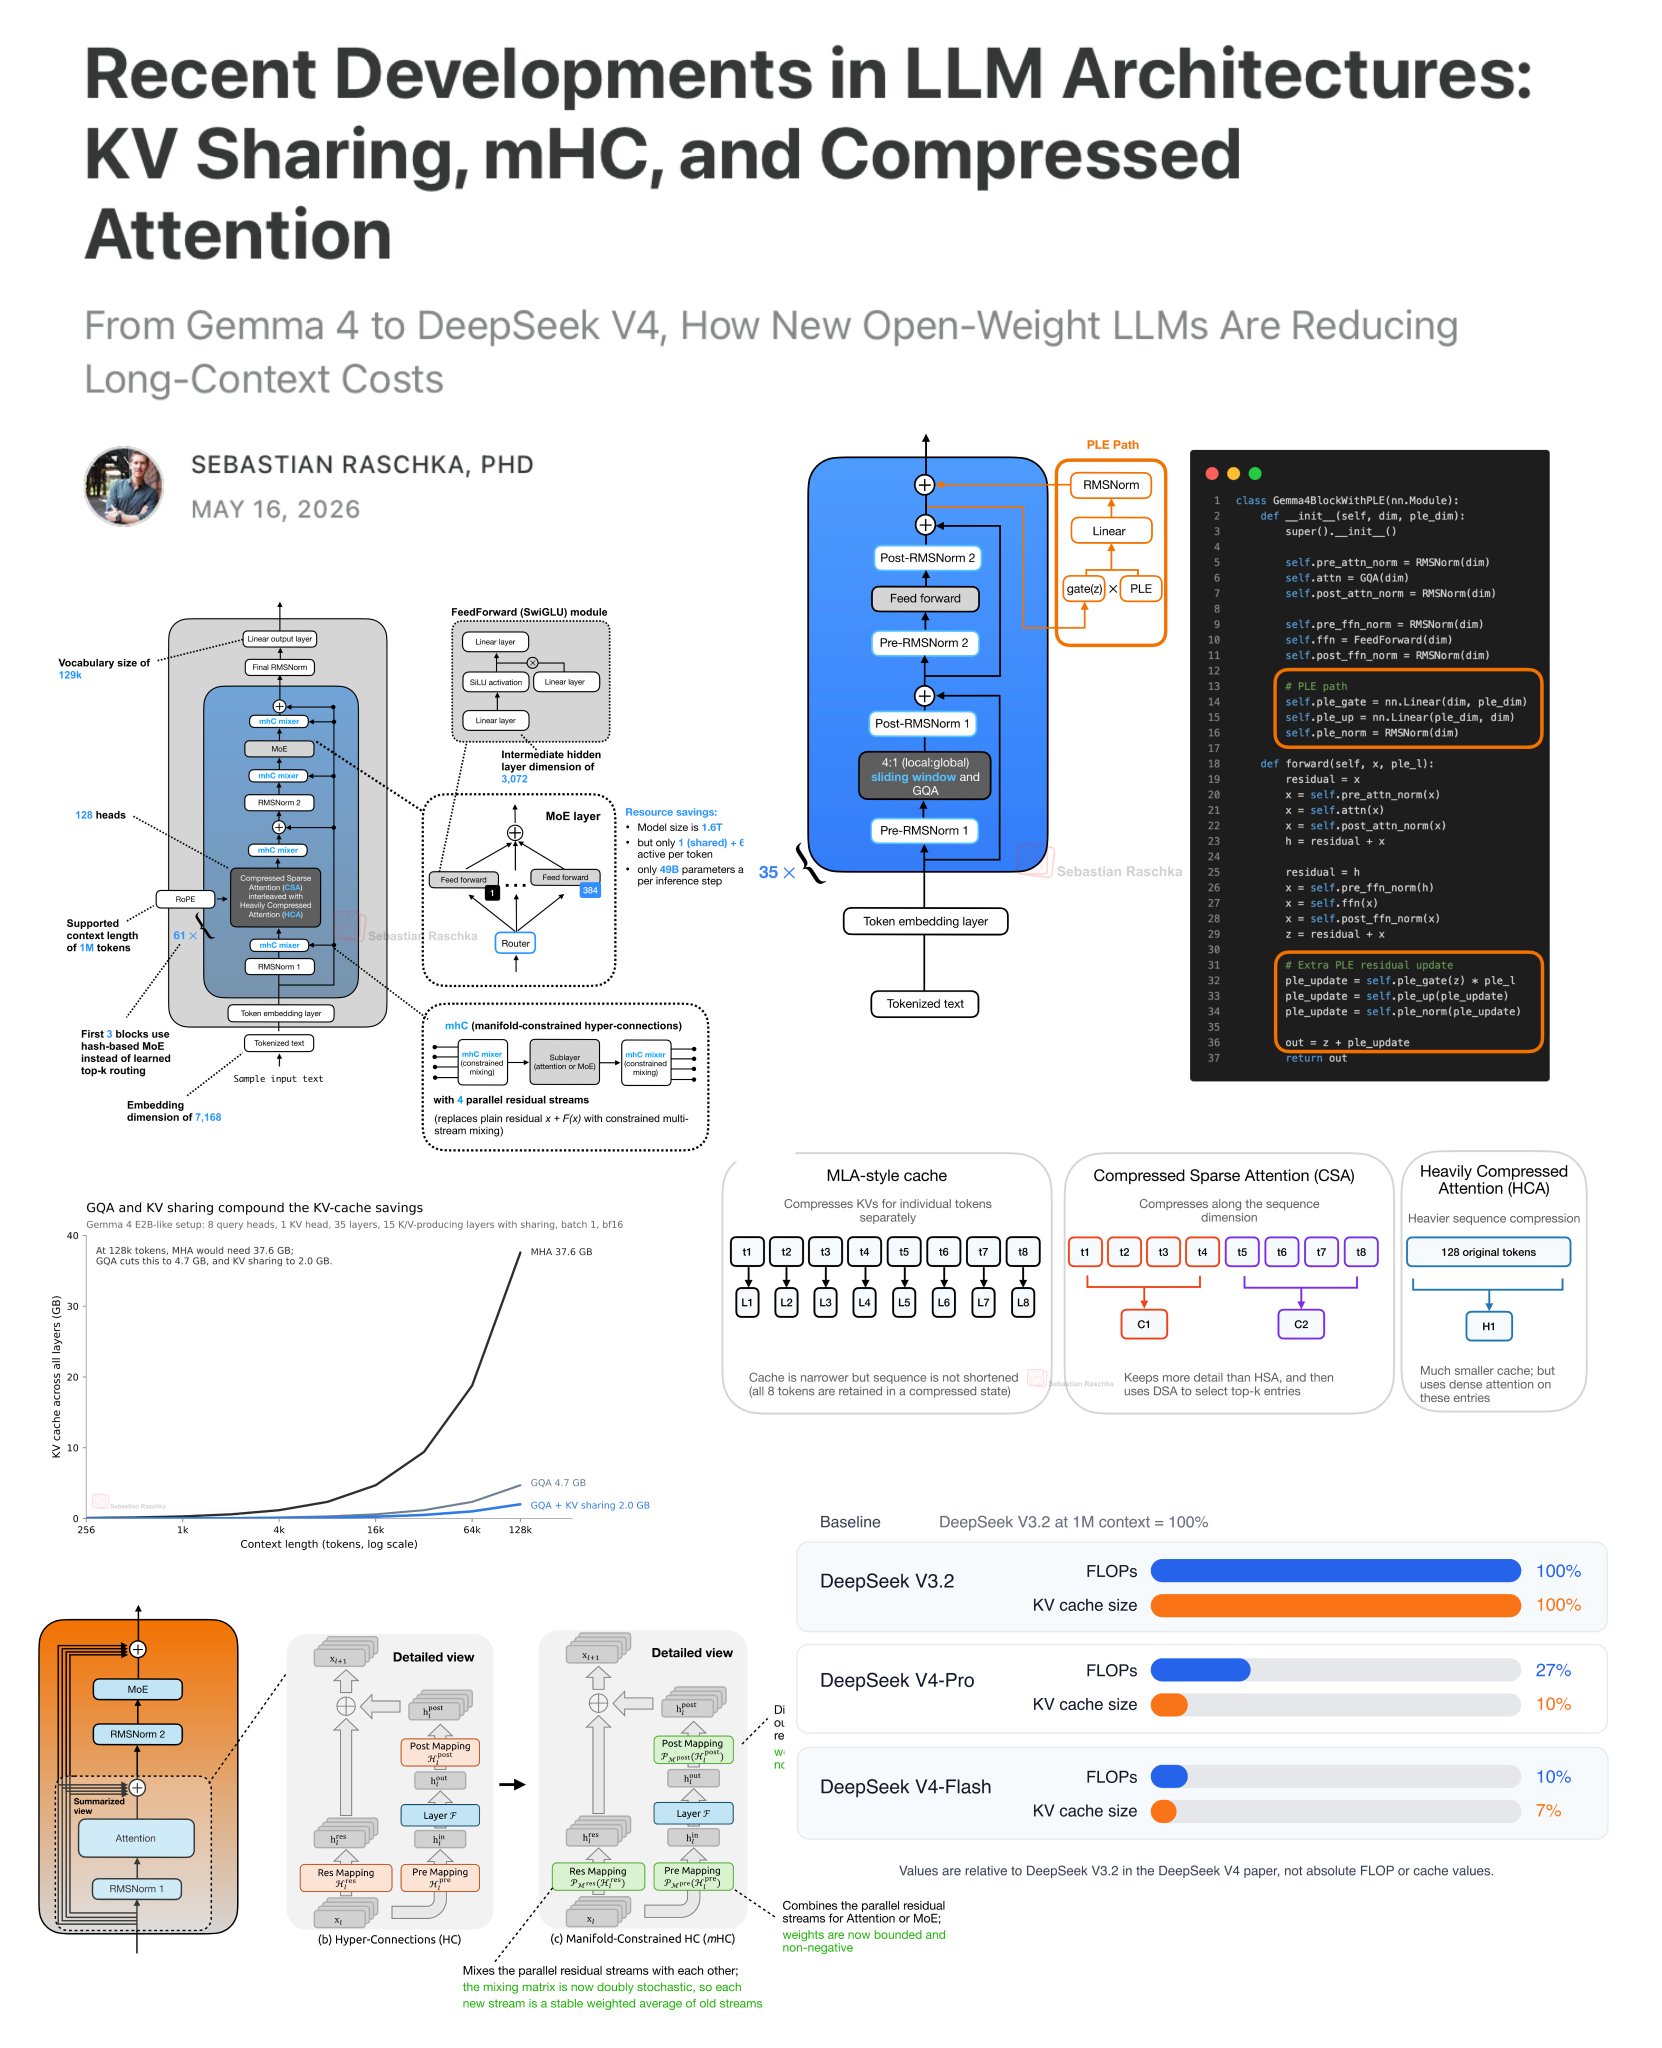
New article: a visual tour of recent LLM architecture advances, from Gemma 4 to DeepSeek V4. I focus on long-context efficiency tweaks like KV sharing, per-layer embeddings, layer-wise attention budgets, compressed attention, and mHC. Link: https://
magazine.sebastianraschka.com/p/recent-devel
opments-in-llm-architectures
… -
Comparative analysis of GQA, MLA, and Gated DeltaNet model architectures
By
–
Yes! It would be interesting whether this happens in GQA:SWA models only though or also in MLA or Gated DeltaNet models, for example.
-
Learning LLM Architectures Through Scratch Implementation and Model Evaluation
By
–
A little talk on what we can learn from implementing LLM architectures from scratch in Python and PyTorch. And how I approach new open-weight models, compare them against reference implementations etc:
-
Low-commitment attention modification for model training
By
–
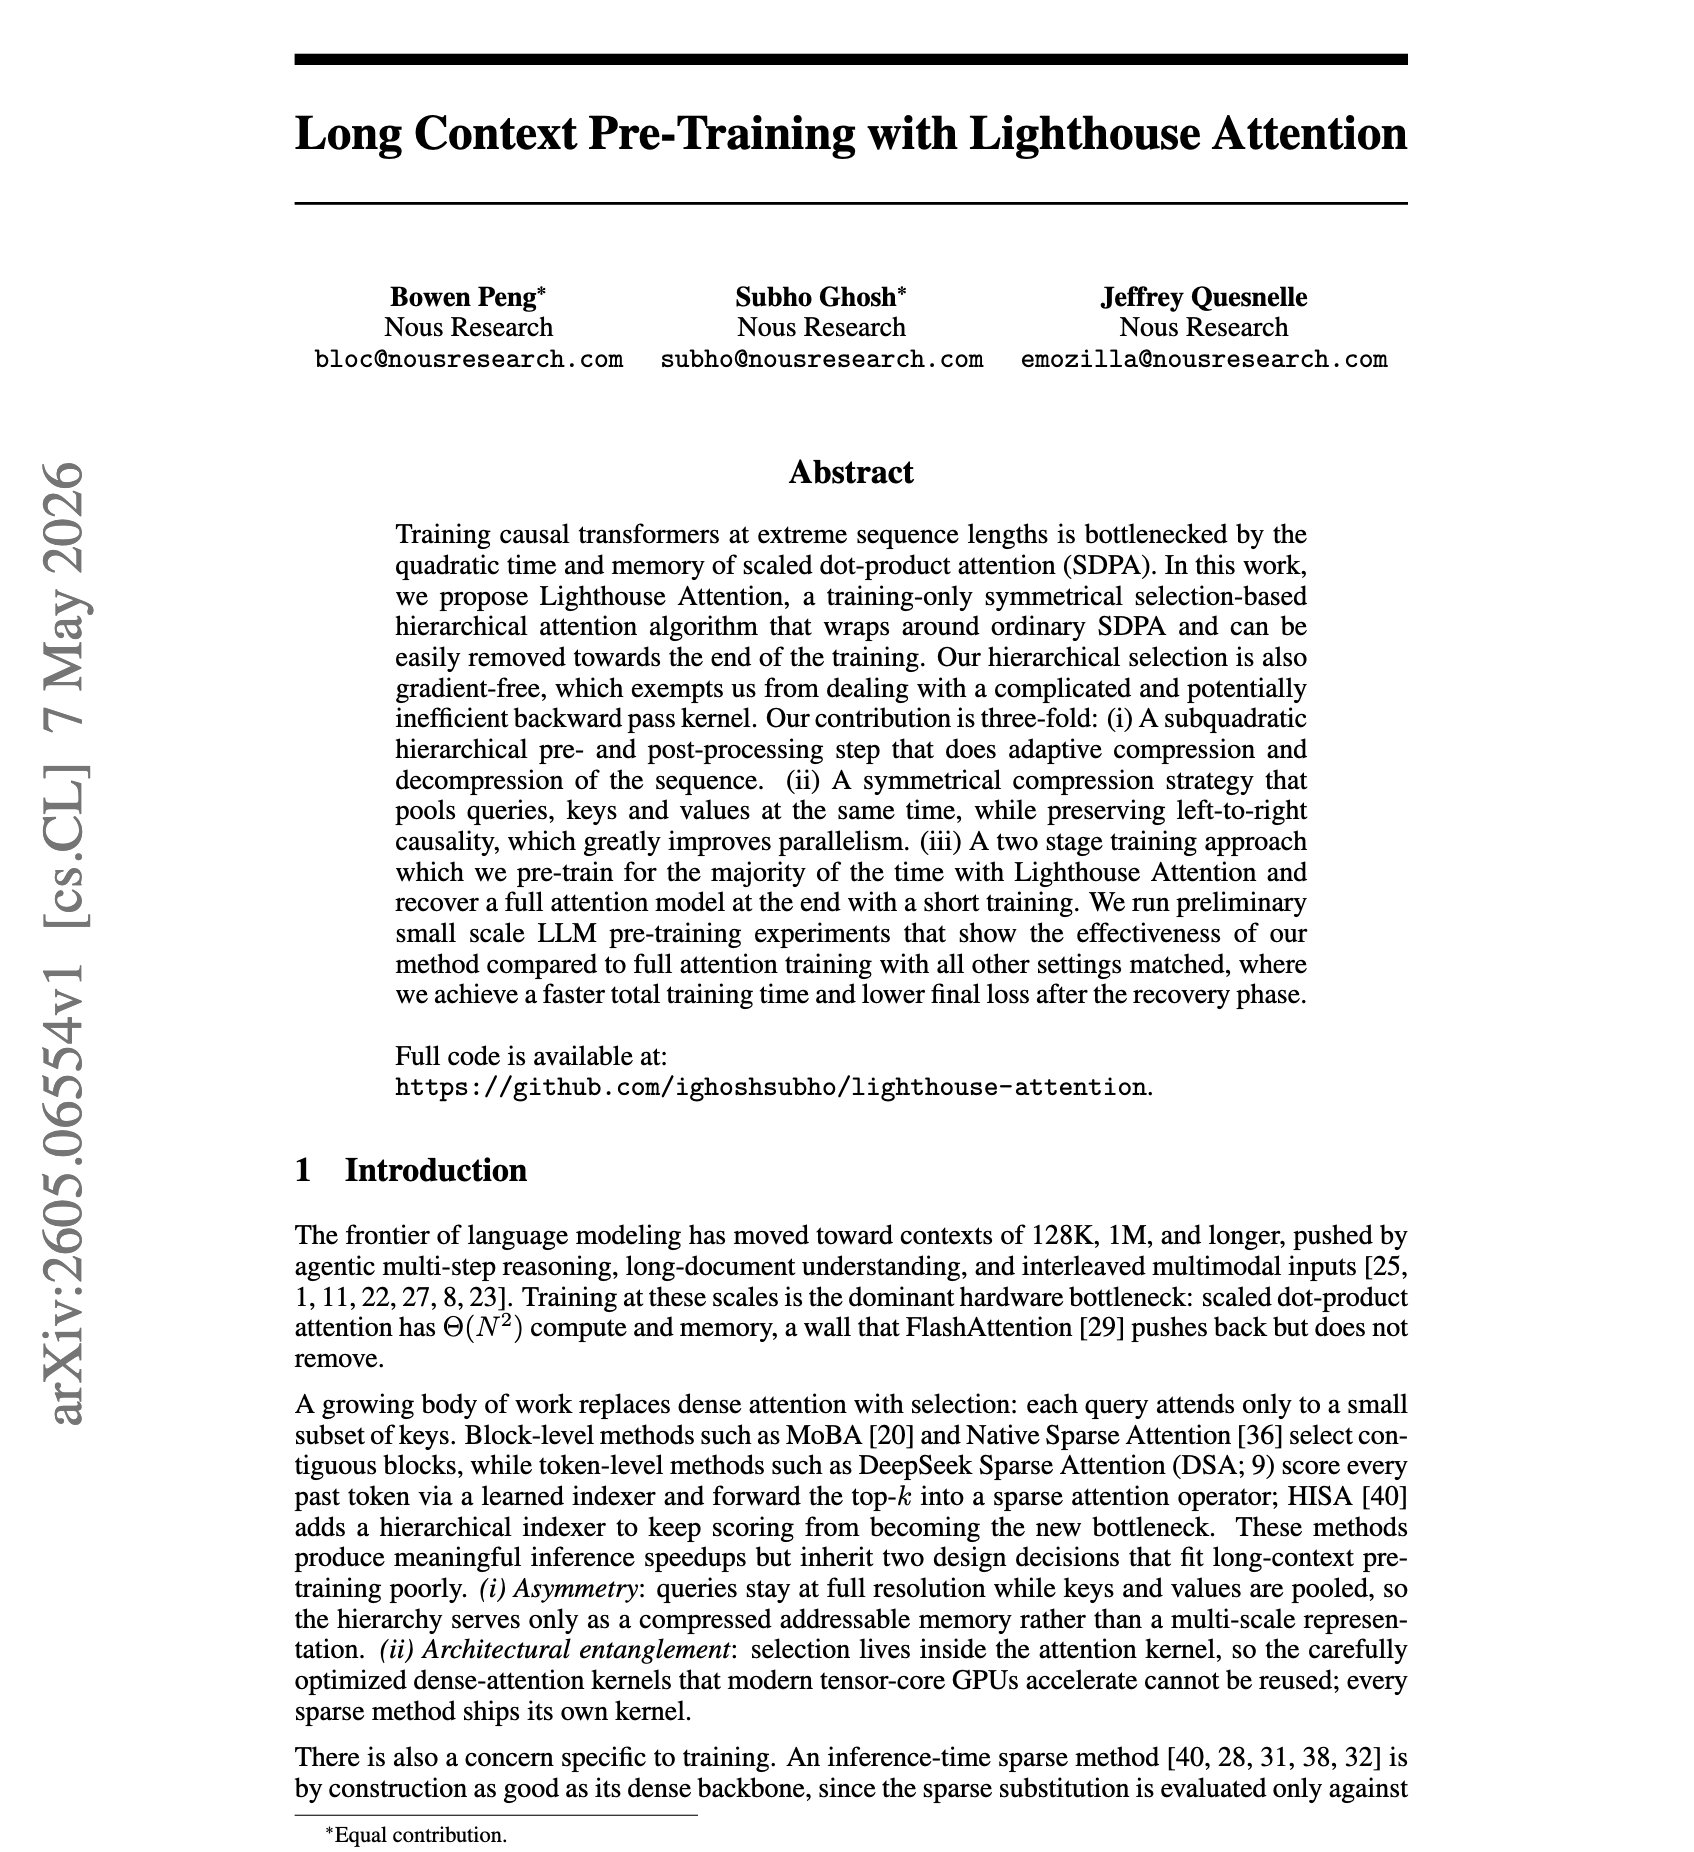
Interesting paper. What I like about this is that it is a relatively low-commitment attention modification. I.e., one can use it during most of training, switch back to vanilla attention near the end, and recover roughly the same modeling performance as if full attention had