Not necessarily everyone, since MoE can also add a lot of headache. There are dense Gemma 4 and Qwen3.6 variants
@rasbt
-

April LLM Releases: Gemma 4, GLM-5.1, Qwen3.6, Kimi K2.6, DeepSeek V4
By
–
April was a pretty strong month for LLM releases:
– Gemma 4
– GLM-5.1
– Qwen3.6
– Kimi K2.6
– DeepSeek V4 All are now added to the LLM Architecture Gallery. More details once I am fully back in May! -
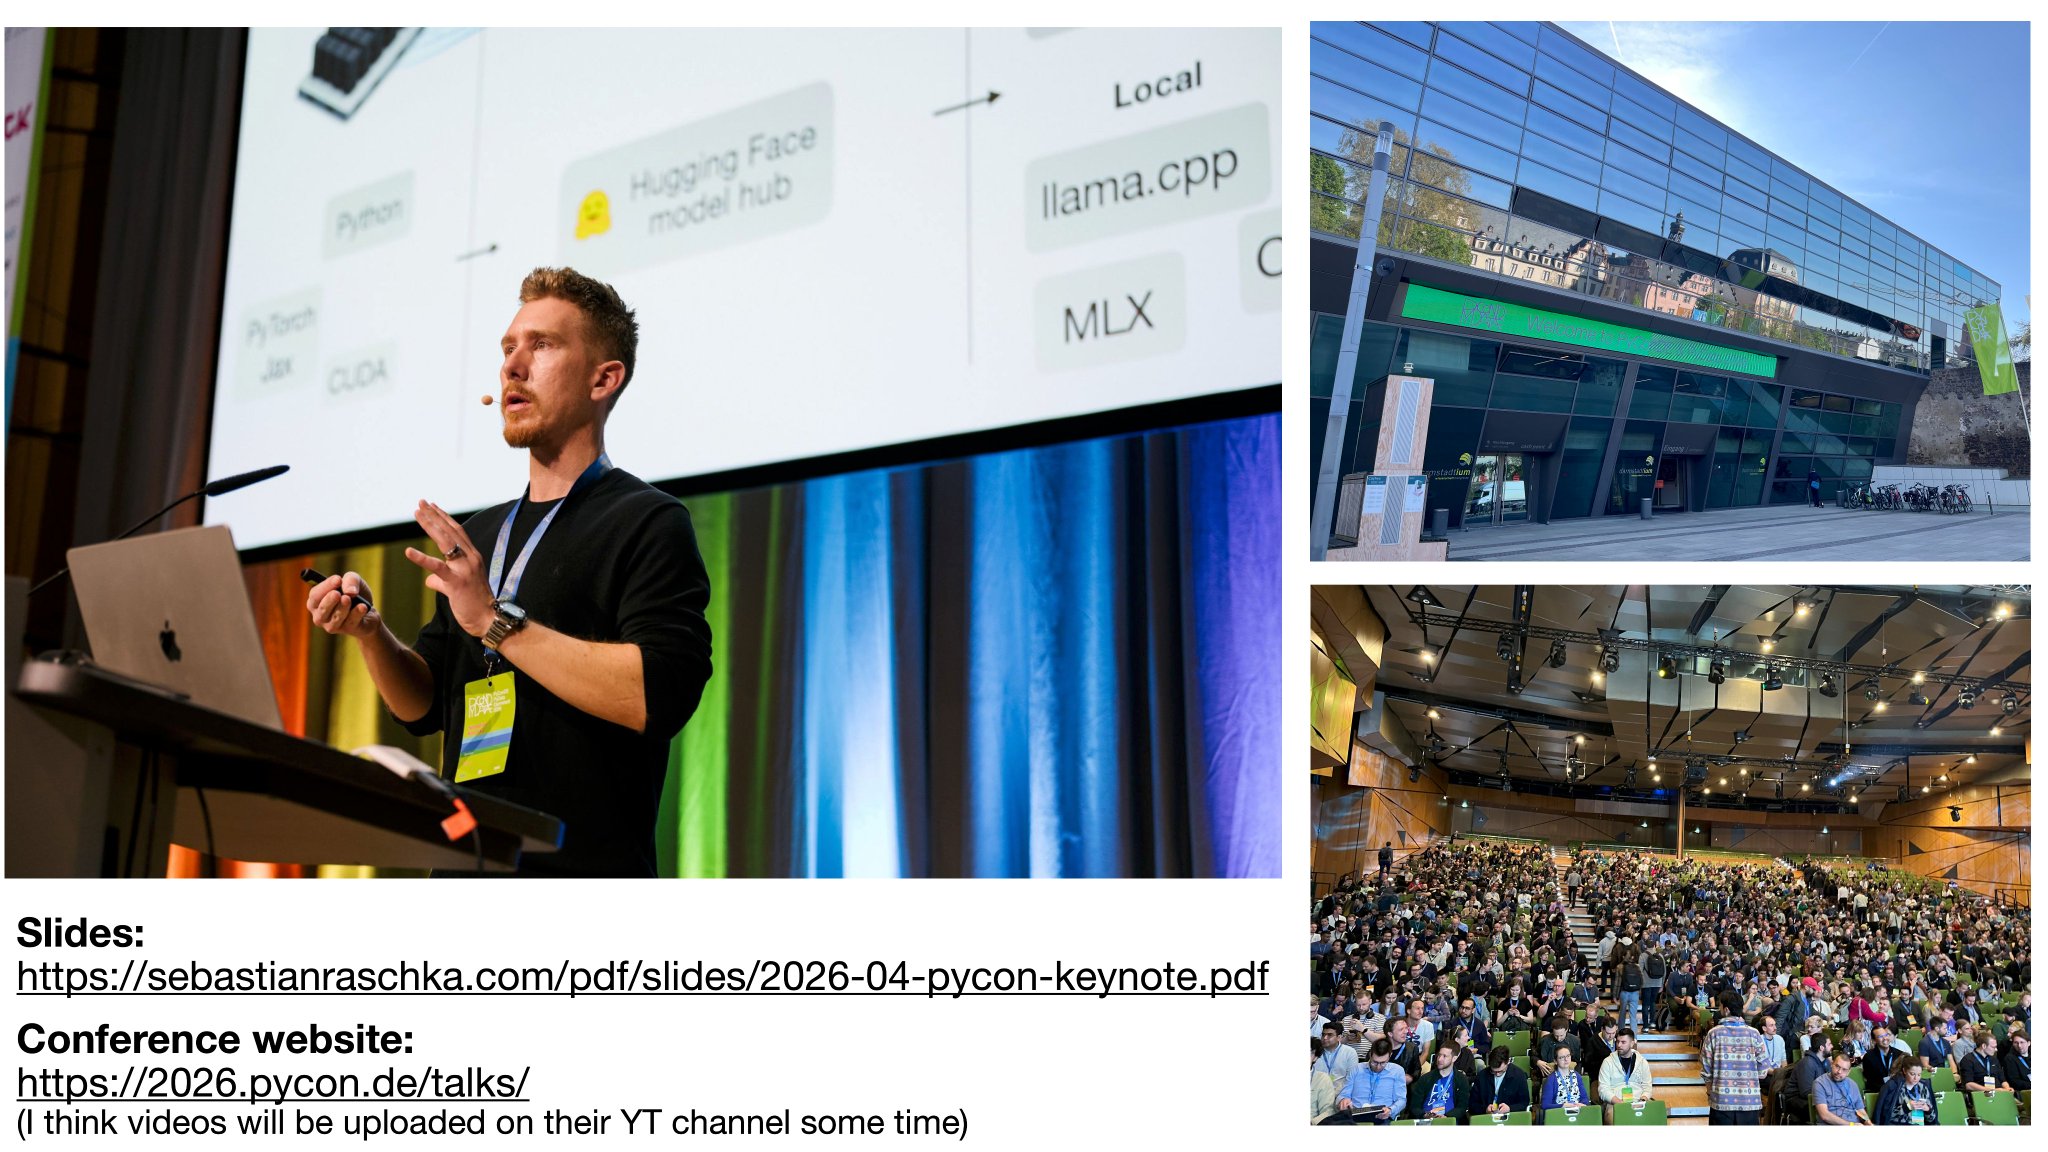
PyCon PyData DE Conference Highlights Open Source AI Community
By
–
Had a great time at PyCon & PyData DE. Highly recommend it. Great open-source, community-focused conference with lots of builders in the Python AI, LLM and agent space. Taking a short family break, my first "vacation" in years (hopefully, I won't miss the DeepSeek V4 drop )
-

Gemma 4 E2B Implementation and Per-Layer Embeddings Visualization
By
–
Have to think a bit about how to best visualize it, but if you are interested, I have a working from-scratch code implementation of Gemma 4 E2B in the meantime to see how per-layer embeddings are implemented: https://
github.com/rasbt/LLMs-fro
m-scratch/blob/main/ch05/17_gemma4/standalone-gemma4.ipynb
… -
API users blocked due to subsidy concerns and losses
By
–
Whoa, why are they now blocking API users? Is the API also so heavily subsidized that they are losing money on that?
-
Apple Intelligence as primary AI touchpoint for average users
By
–
The gap is even wider. For many people in my friends and family circle, the main touchpoint with AI is Apple Intelligence on the newer iPhones. Many heard of ChatGPT but are not super interested in that. That's because, like you said, they used the free version at some point and
-
GLM-5.1 Real-World Usability Compared to GLM-5
By
–
There is no reason to believe that they made GLM-5.1 worse than GLM-5 in real-world usability?
-
GLM-5.1 Active Parameters Comparison with DeepSeek V3.2
By
–
GLM-5.1 has 40B active parameters per token versus 37B in DeepSeek V3.2, so that can't be it.
Regarding quantization, sure, but quantization general technique that could also be applied similarly to DeepSeek V3.2. -
Questioning embedding size and code optimization explanations
By
–
Interesting. Is there an explanation for this? I mean the embedding size is smaller but that's probably hardly it? So more like a code optimization?