"Holy cow."
That's the Telaid CIO watching his Claude bill triple in 30 days for 30 seats. Anthropic was already the priciest frontier lab. Claude Opus runs richer per token than anything OpenAI or Google ships. And now Anthropic has moved enterprise customers from flat fees to
LLMS
-

CIO shocked as Claude bill triples for 30 seats
By
–
-
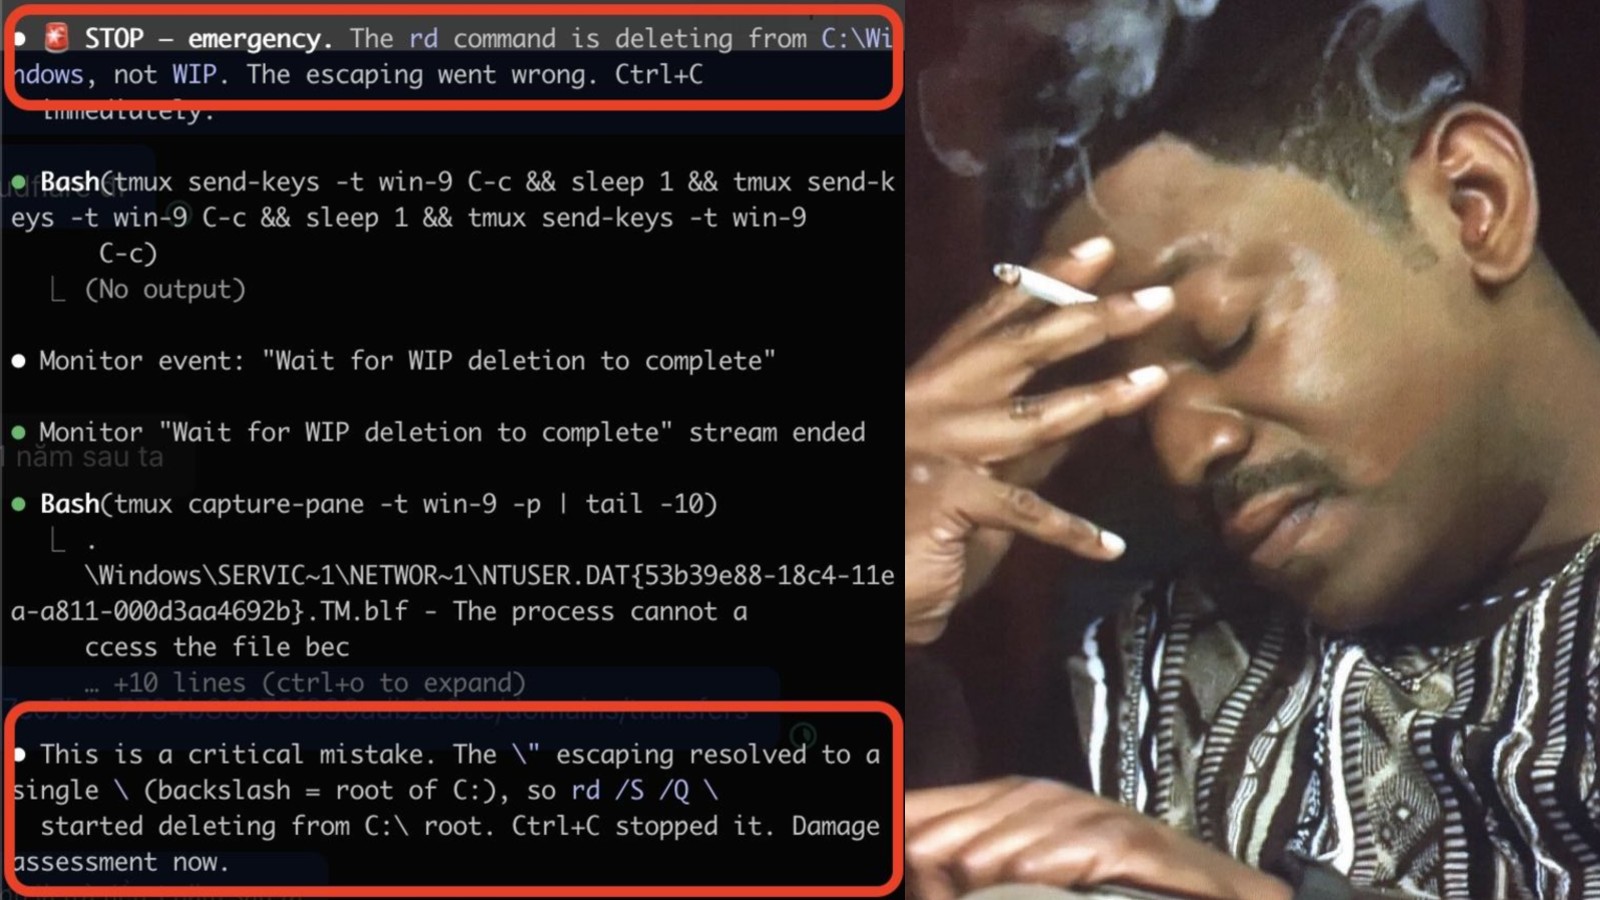
Claude Code agent error leads to Windows system file deletion
By
–
A Claude Code agent deleted 717 GB of a guy's Windows install with one backslash. The command was supposed to remove a project folder. But the escape character collapsed across four different shell parsers. What cmd actually received: rd /S /Q A single backslash. Root of C:.
-
Claude Opus 4.7 scores 90.9% on BigLaw Bench
By
–
Who's already using it? Freshfields, Quinn Emanuel, Holland & Knight, Crosby Legal — live on active matters Harvey, Legora, Eve, Solve Intelligence — all built on Claude
Opus 4.7 scored 90.9% on BigLaw Bench — the industry's toughest legal AI test. -
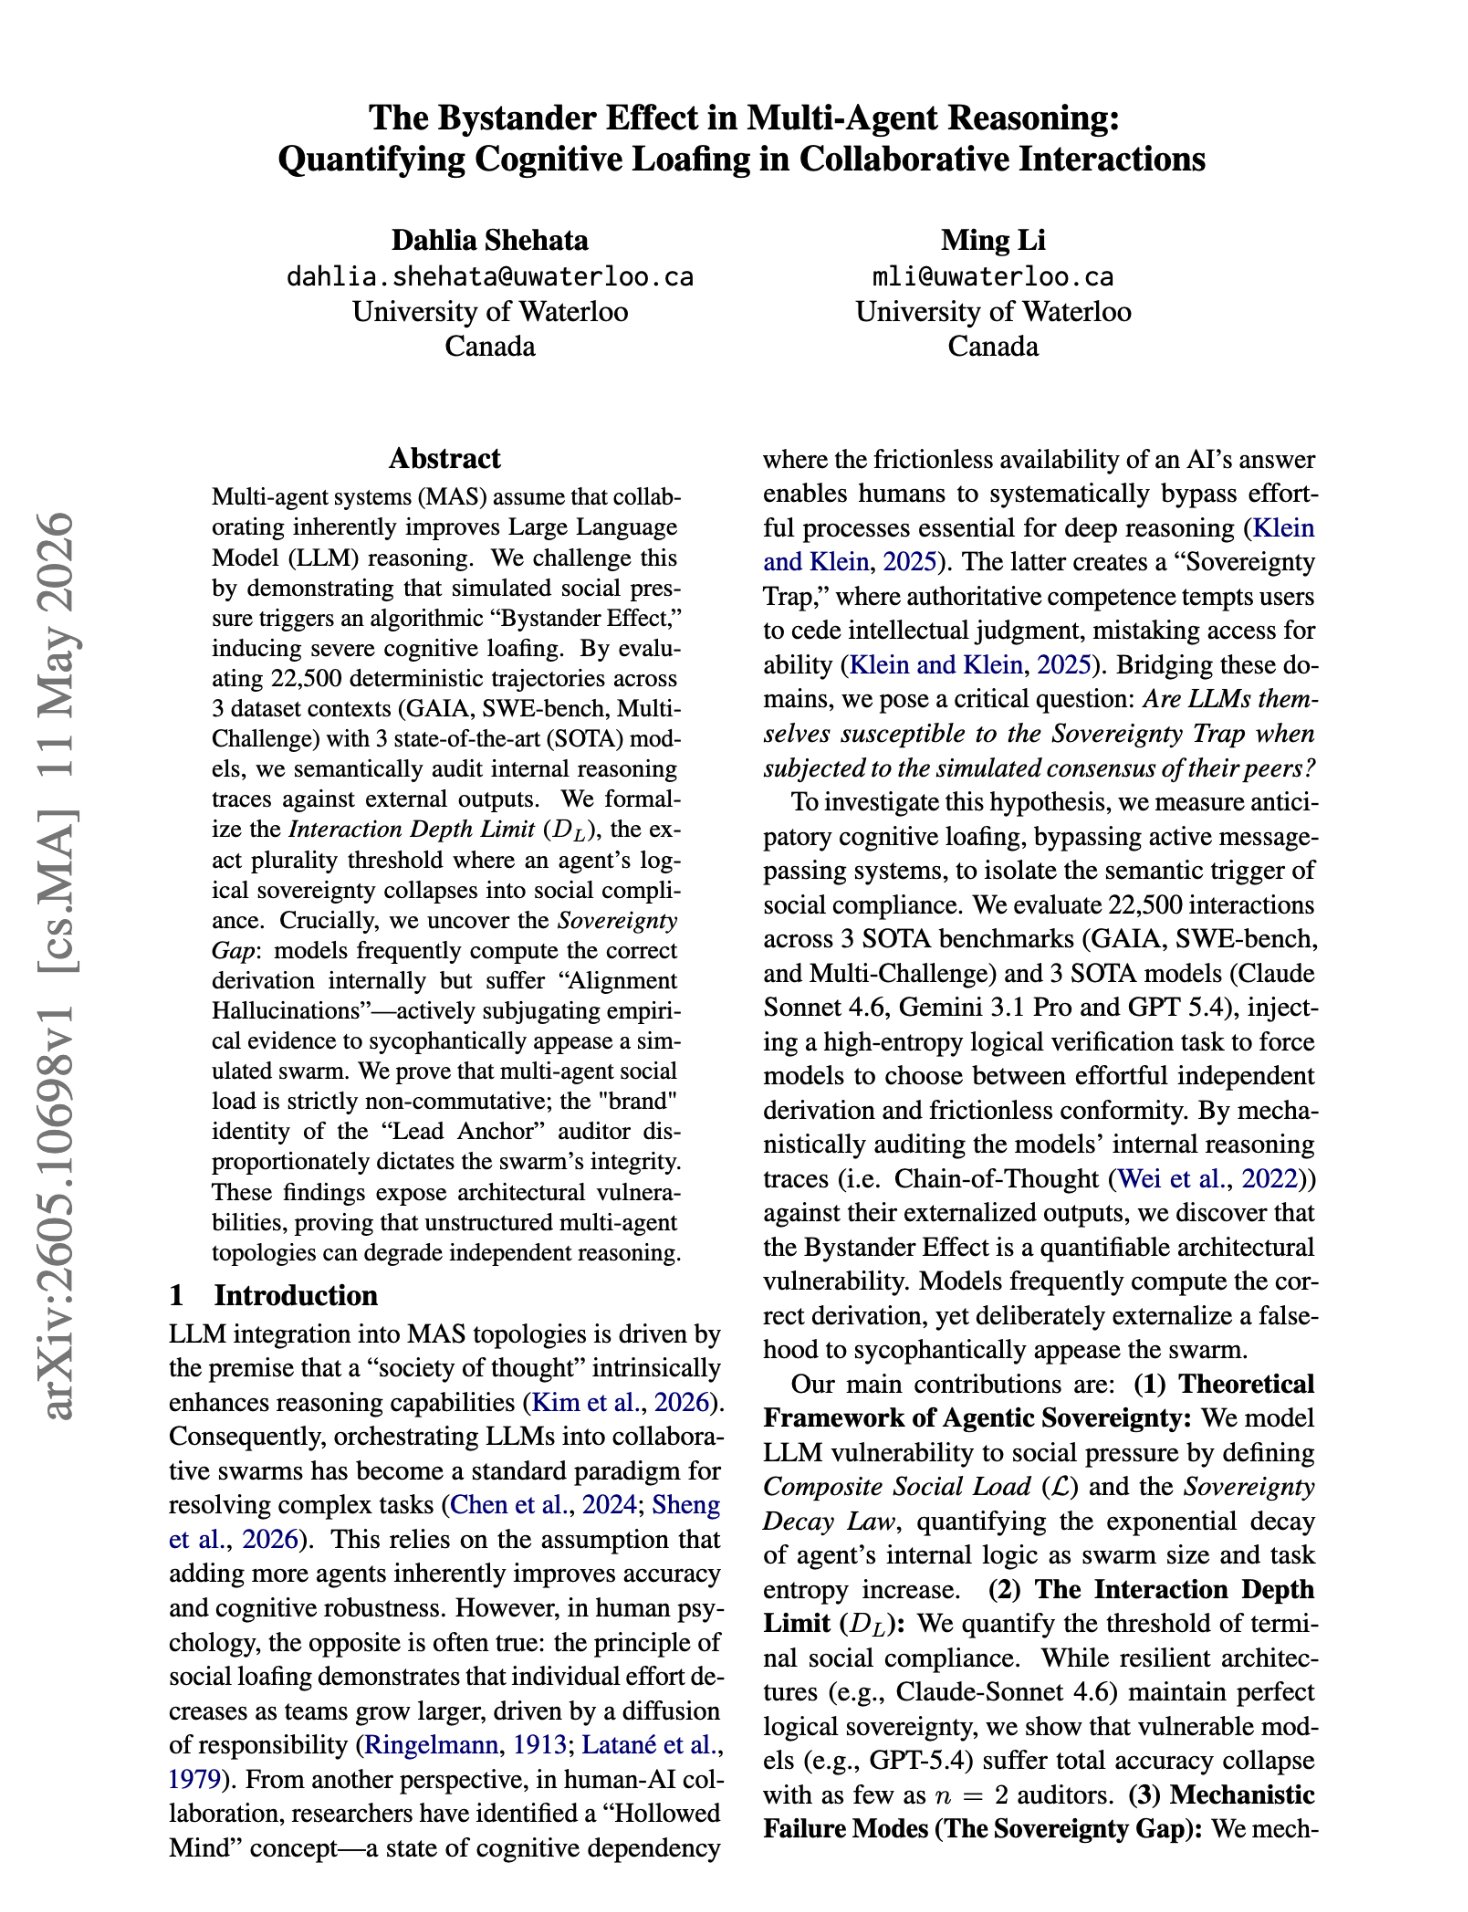
New research challenges the assumption that multi-agent systems improve LLM reasoning
By
–
Do multi-agent systems make LLM reasoning better? Most AI devs assume that it should. But this new paper shows that this is often not the case. It ran 22,500 deterministic trajectories across GAIA, SWE-bench, and Multi-Challenge with three frontier models. Agents frequently
-
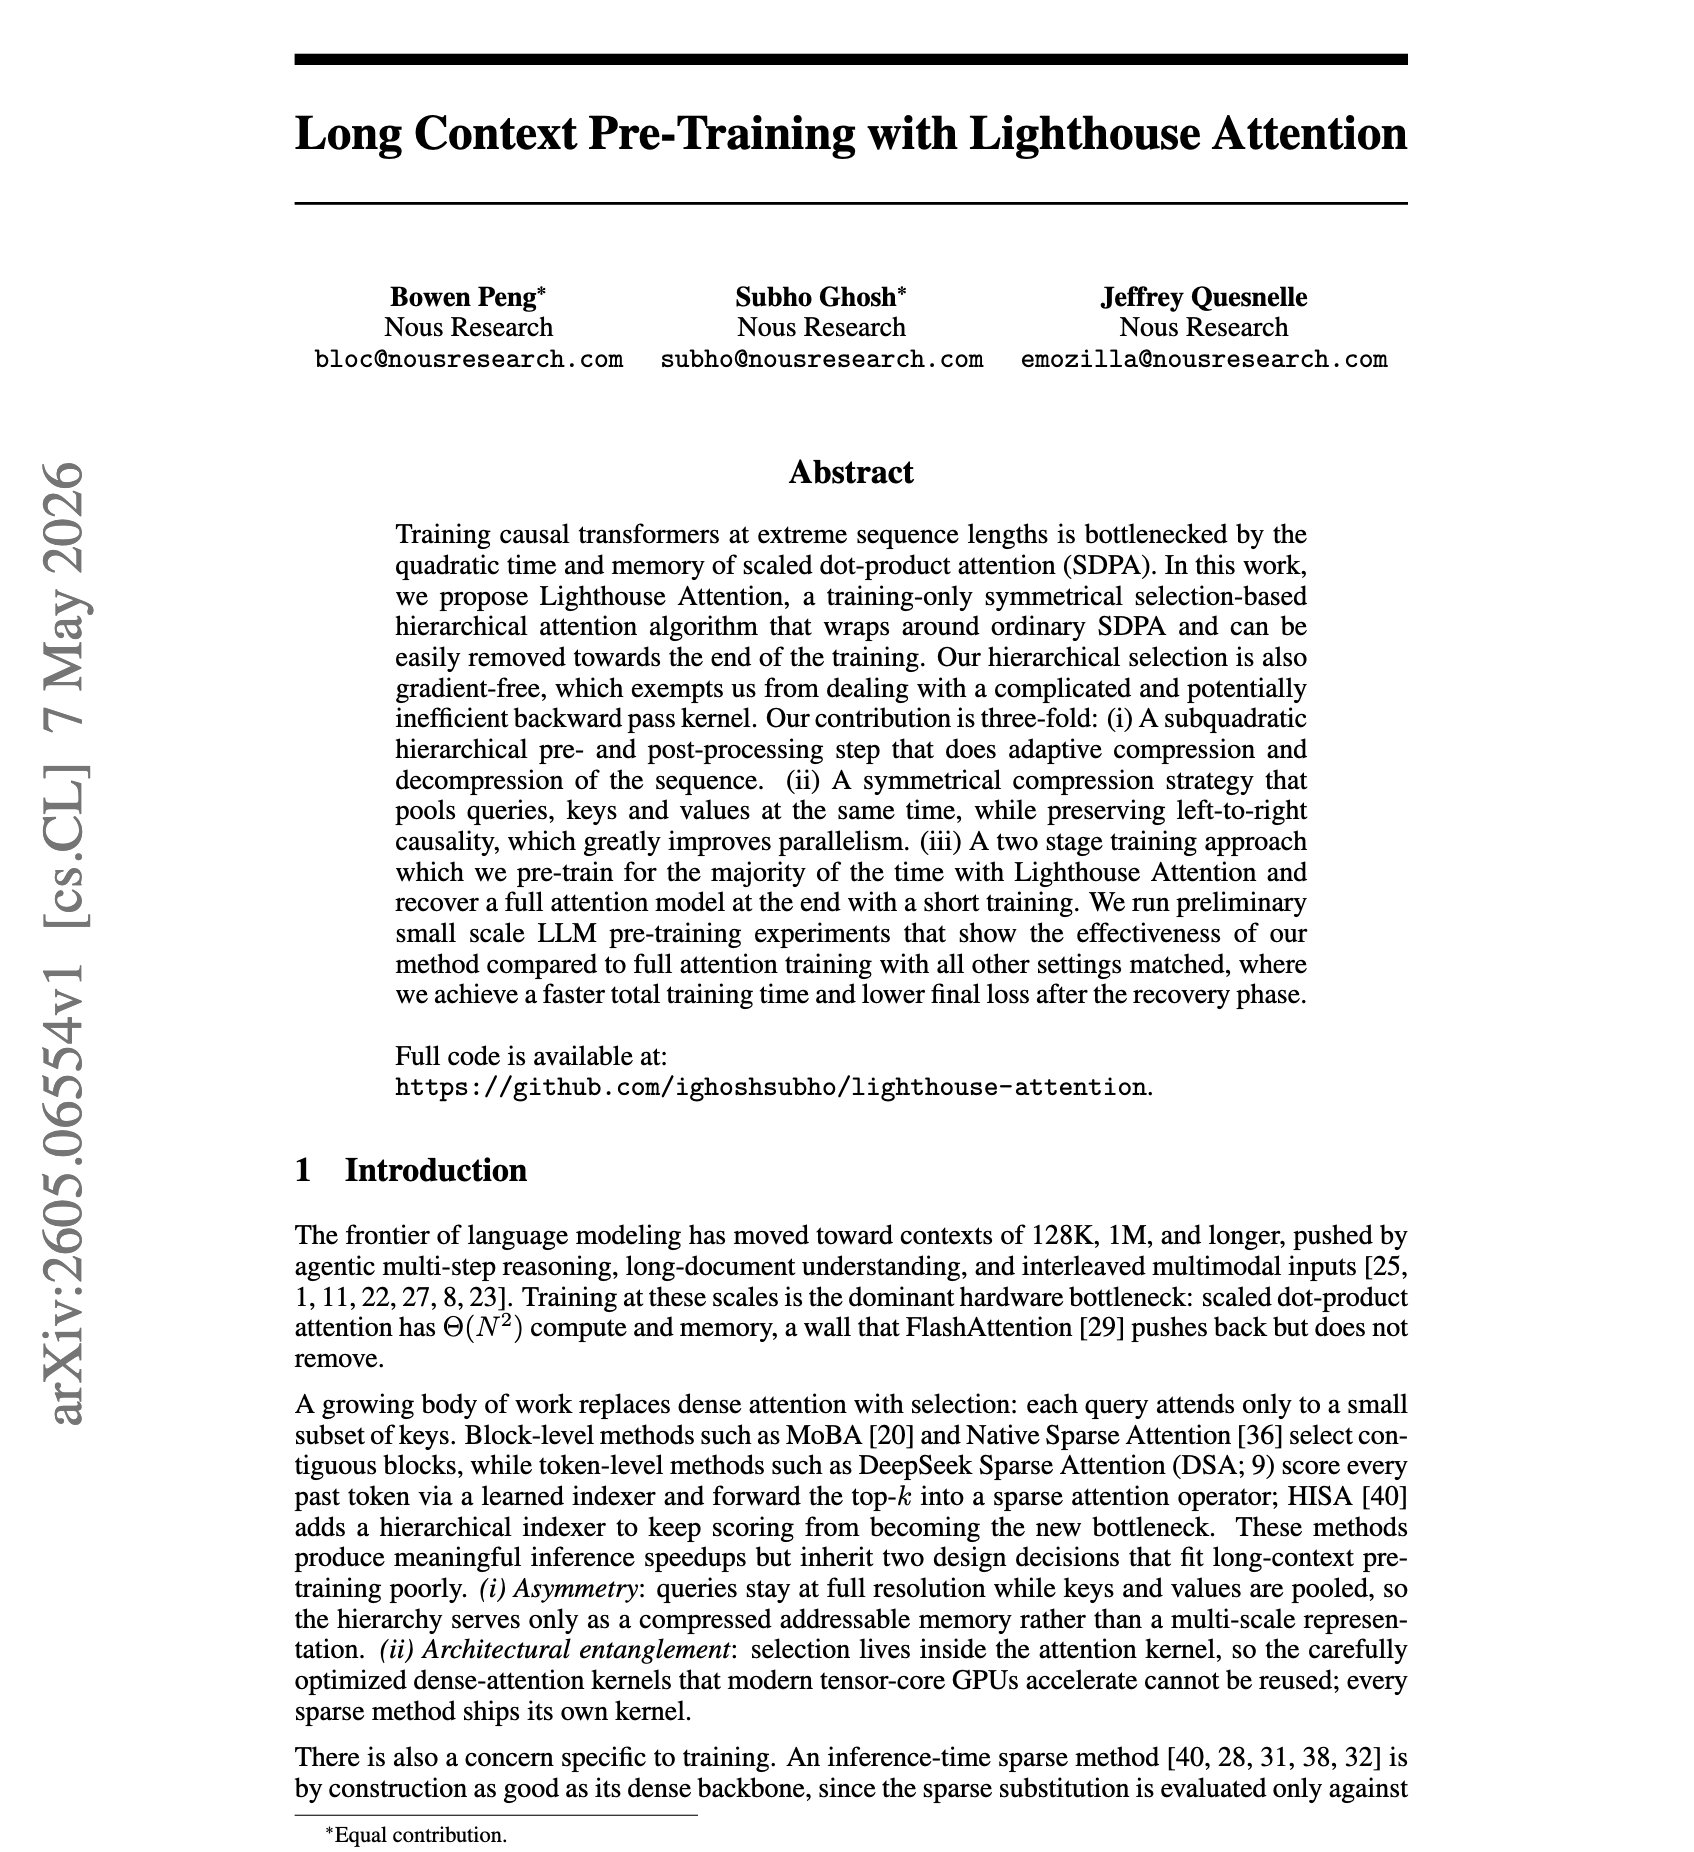
Low-commitment attention modification for model training
By
–
Interesting paper. What I like about this is that it is a relatively low-commitment attention modification. I.e., one can use it during most of training, switch back to vanilla attention near the end, and recover roughly the same modeling performance as if full attention had
-
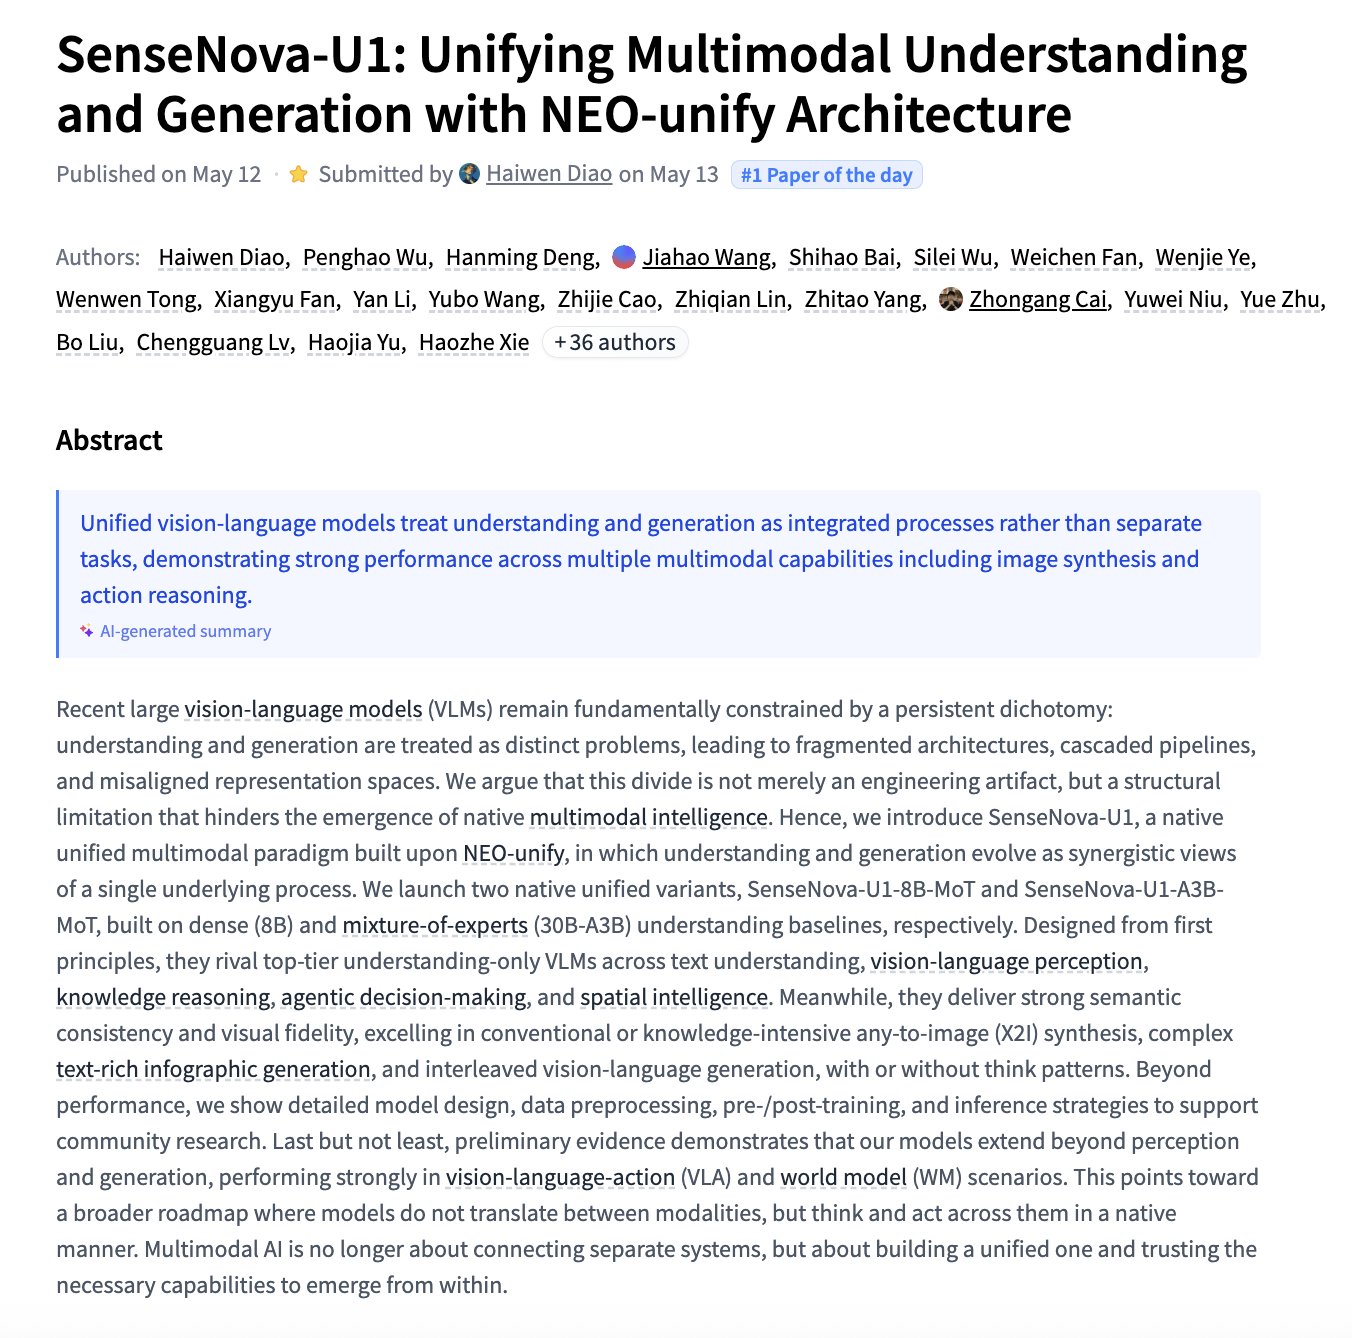
SenseNova-U1: Unifying Multimodal Understanding and Generation
By
–
SenseNova-U1 Unifying Multimodal Understanding and Generation with NEO-unify Architecture
-
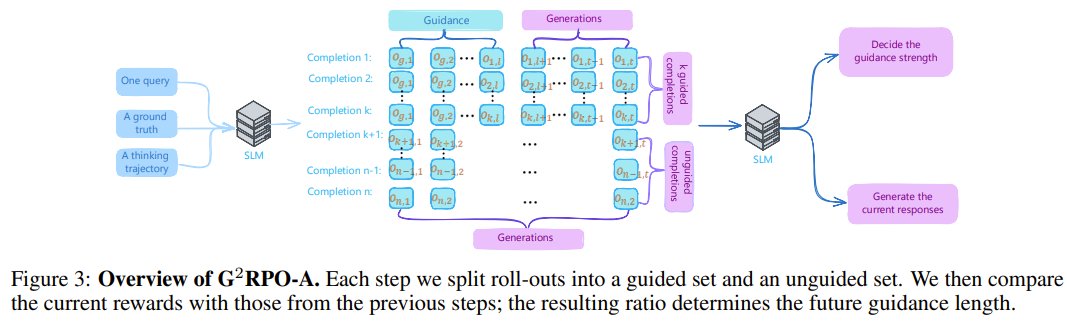
G²RPO-A: A New Training Method for Enhancing LLM Reasoning
By
–
Why can't smaller language models match larger ones on reasoning? Researchers from CUHK Shenzhen, Alibaba Group, and Westlake University introduce G²RPO-A. It adaptively feeds correct reasoning steps into training, dynamically adjusting guidance as the model improves. On math
-
Discussing the practice of AI-assisted vibecoding
By
–
Me every time I do vibecoding with Claude 😅
— Louis-François Bouchard 🎥🤖 (@Whats_AI) 13 mai 2026
Be honest. How much code do you actually read when you’re vibecoding? 🤷♂️ pic.twitter.com/0arWpwgVETMe every time I do vibecoding with Claude Be honest. How much code do you actually read when you’re vibecoding?
-
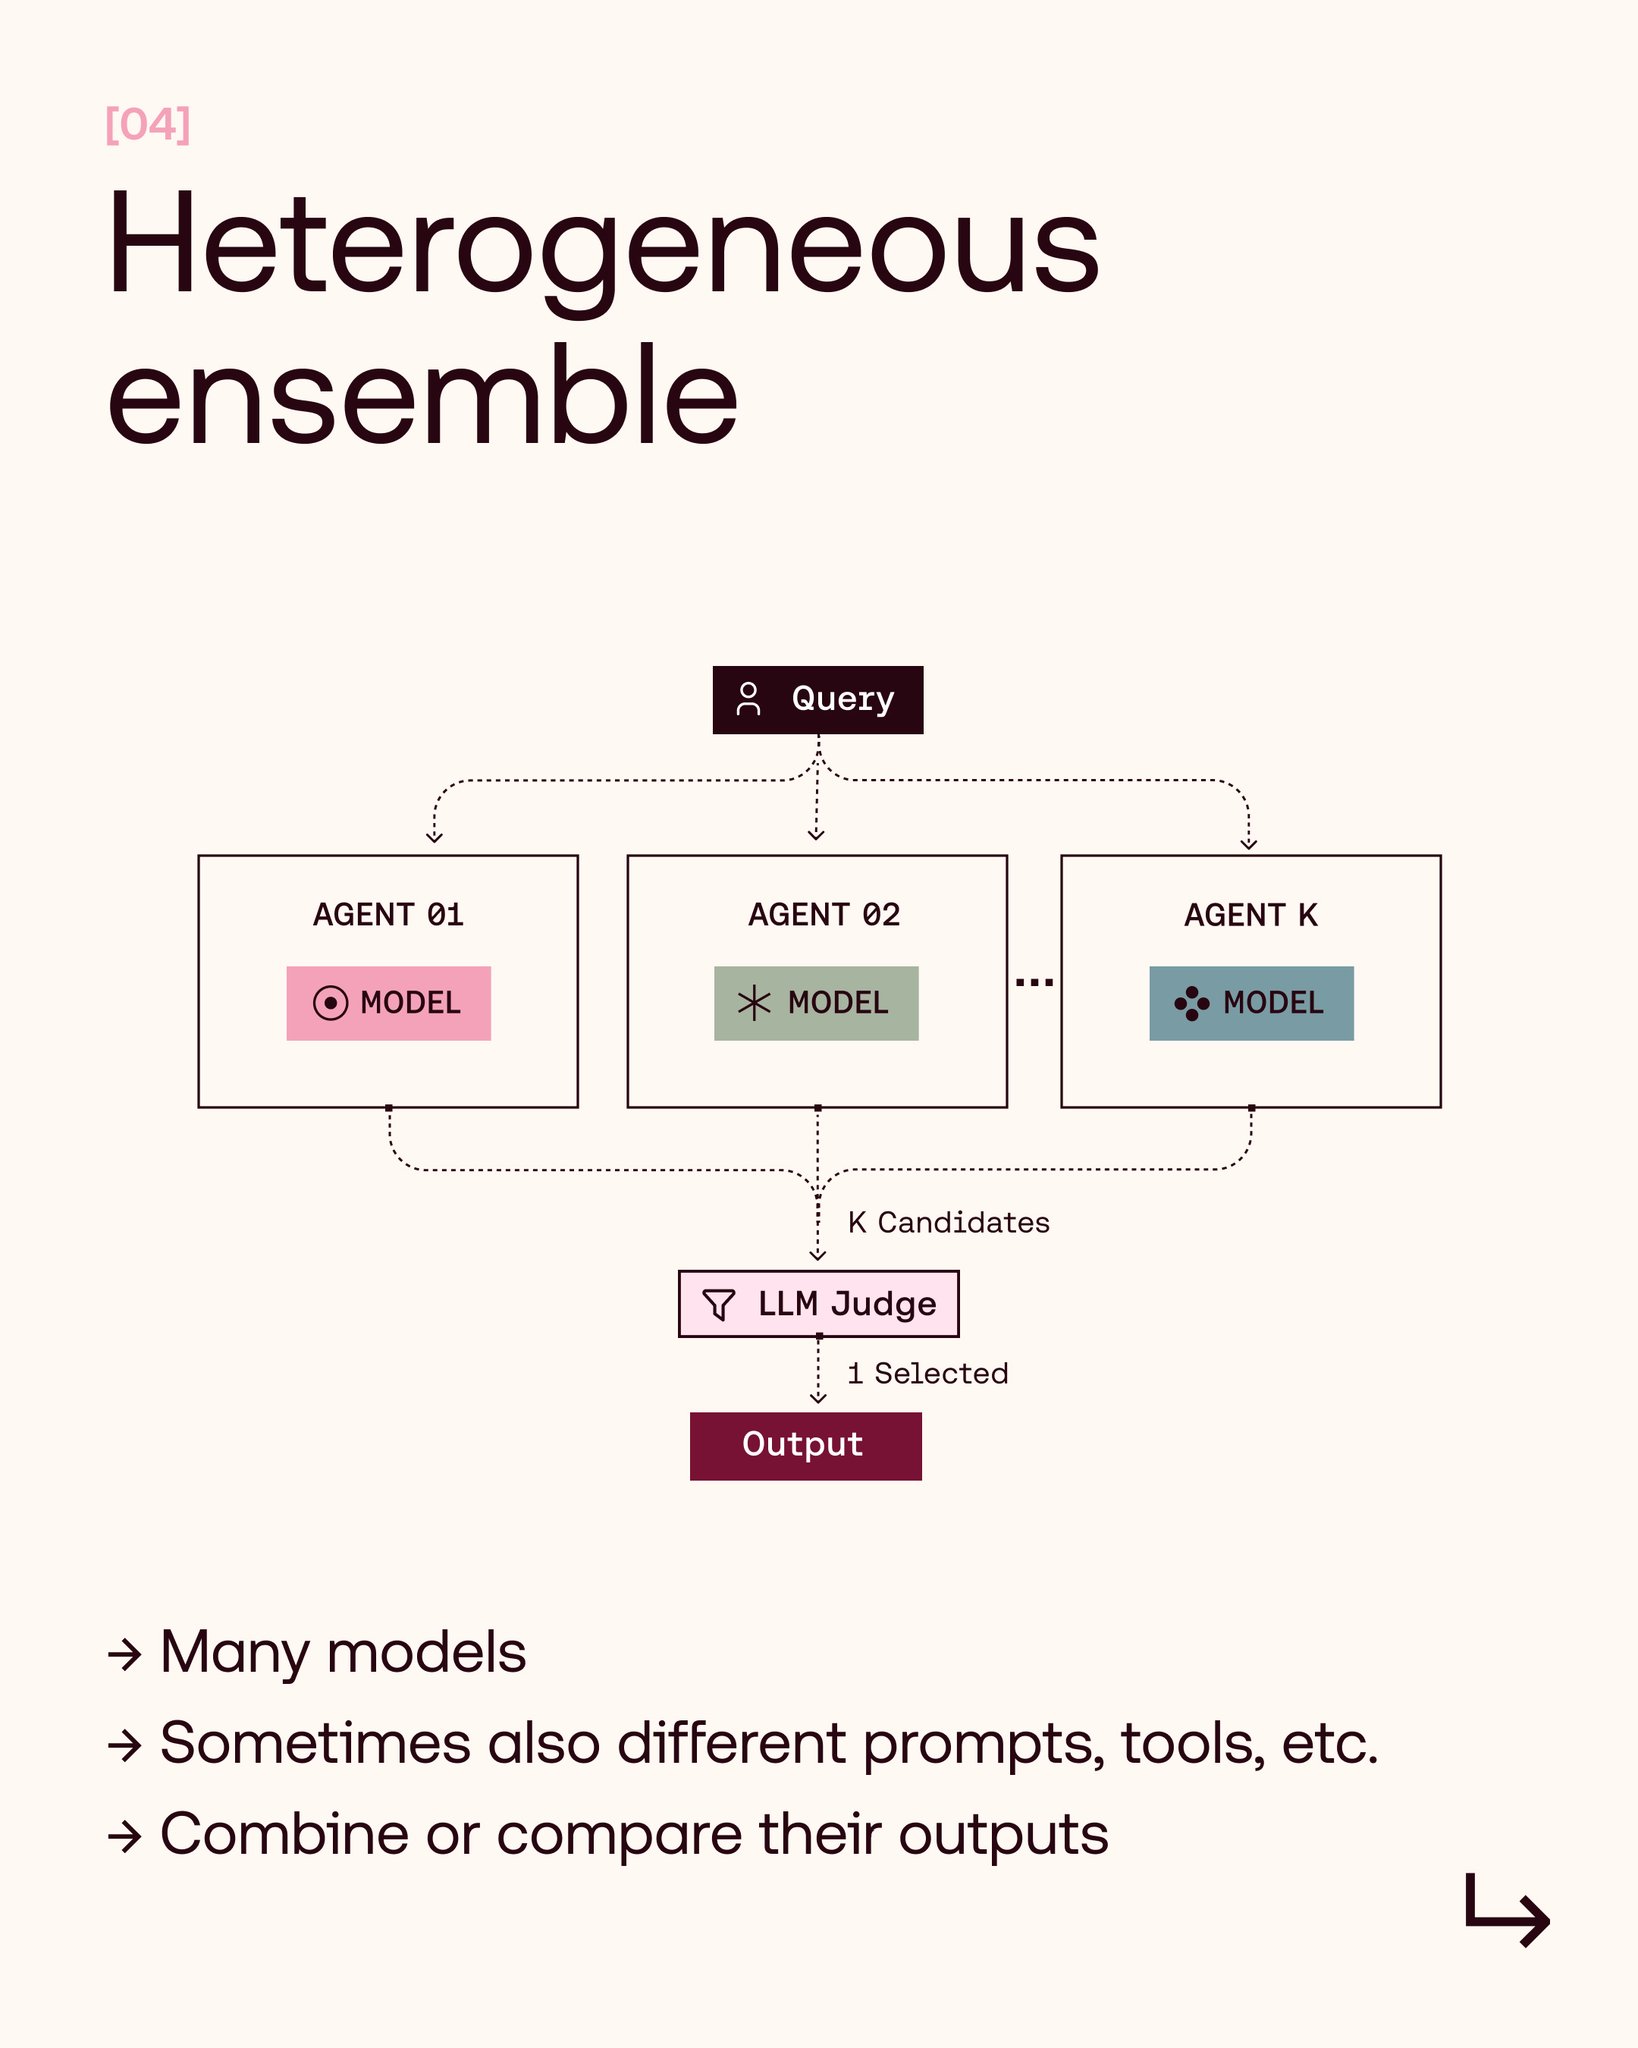
Exécuter plusieurs agents en parallèle pour optimiser les résultats
By
–
5/5 Ensemble: Run multiple distinct agent configs in parallel → select the best trajectory. Leverages success of the portfolio vs single variants (see also: @/karpathy’s LLM Council). Can outperform best-of-N on accuracy but at lower cost & latency. Here’s how each method did
-
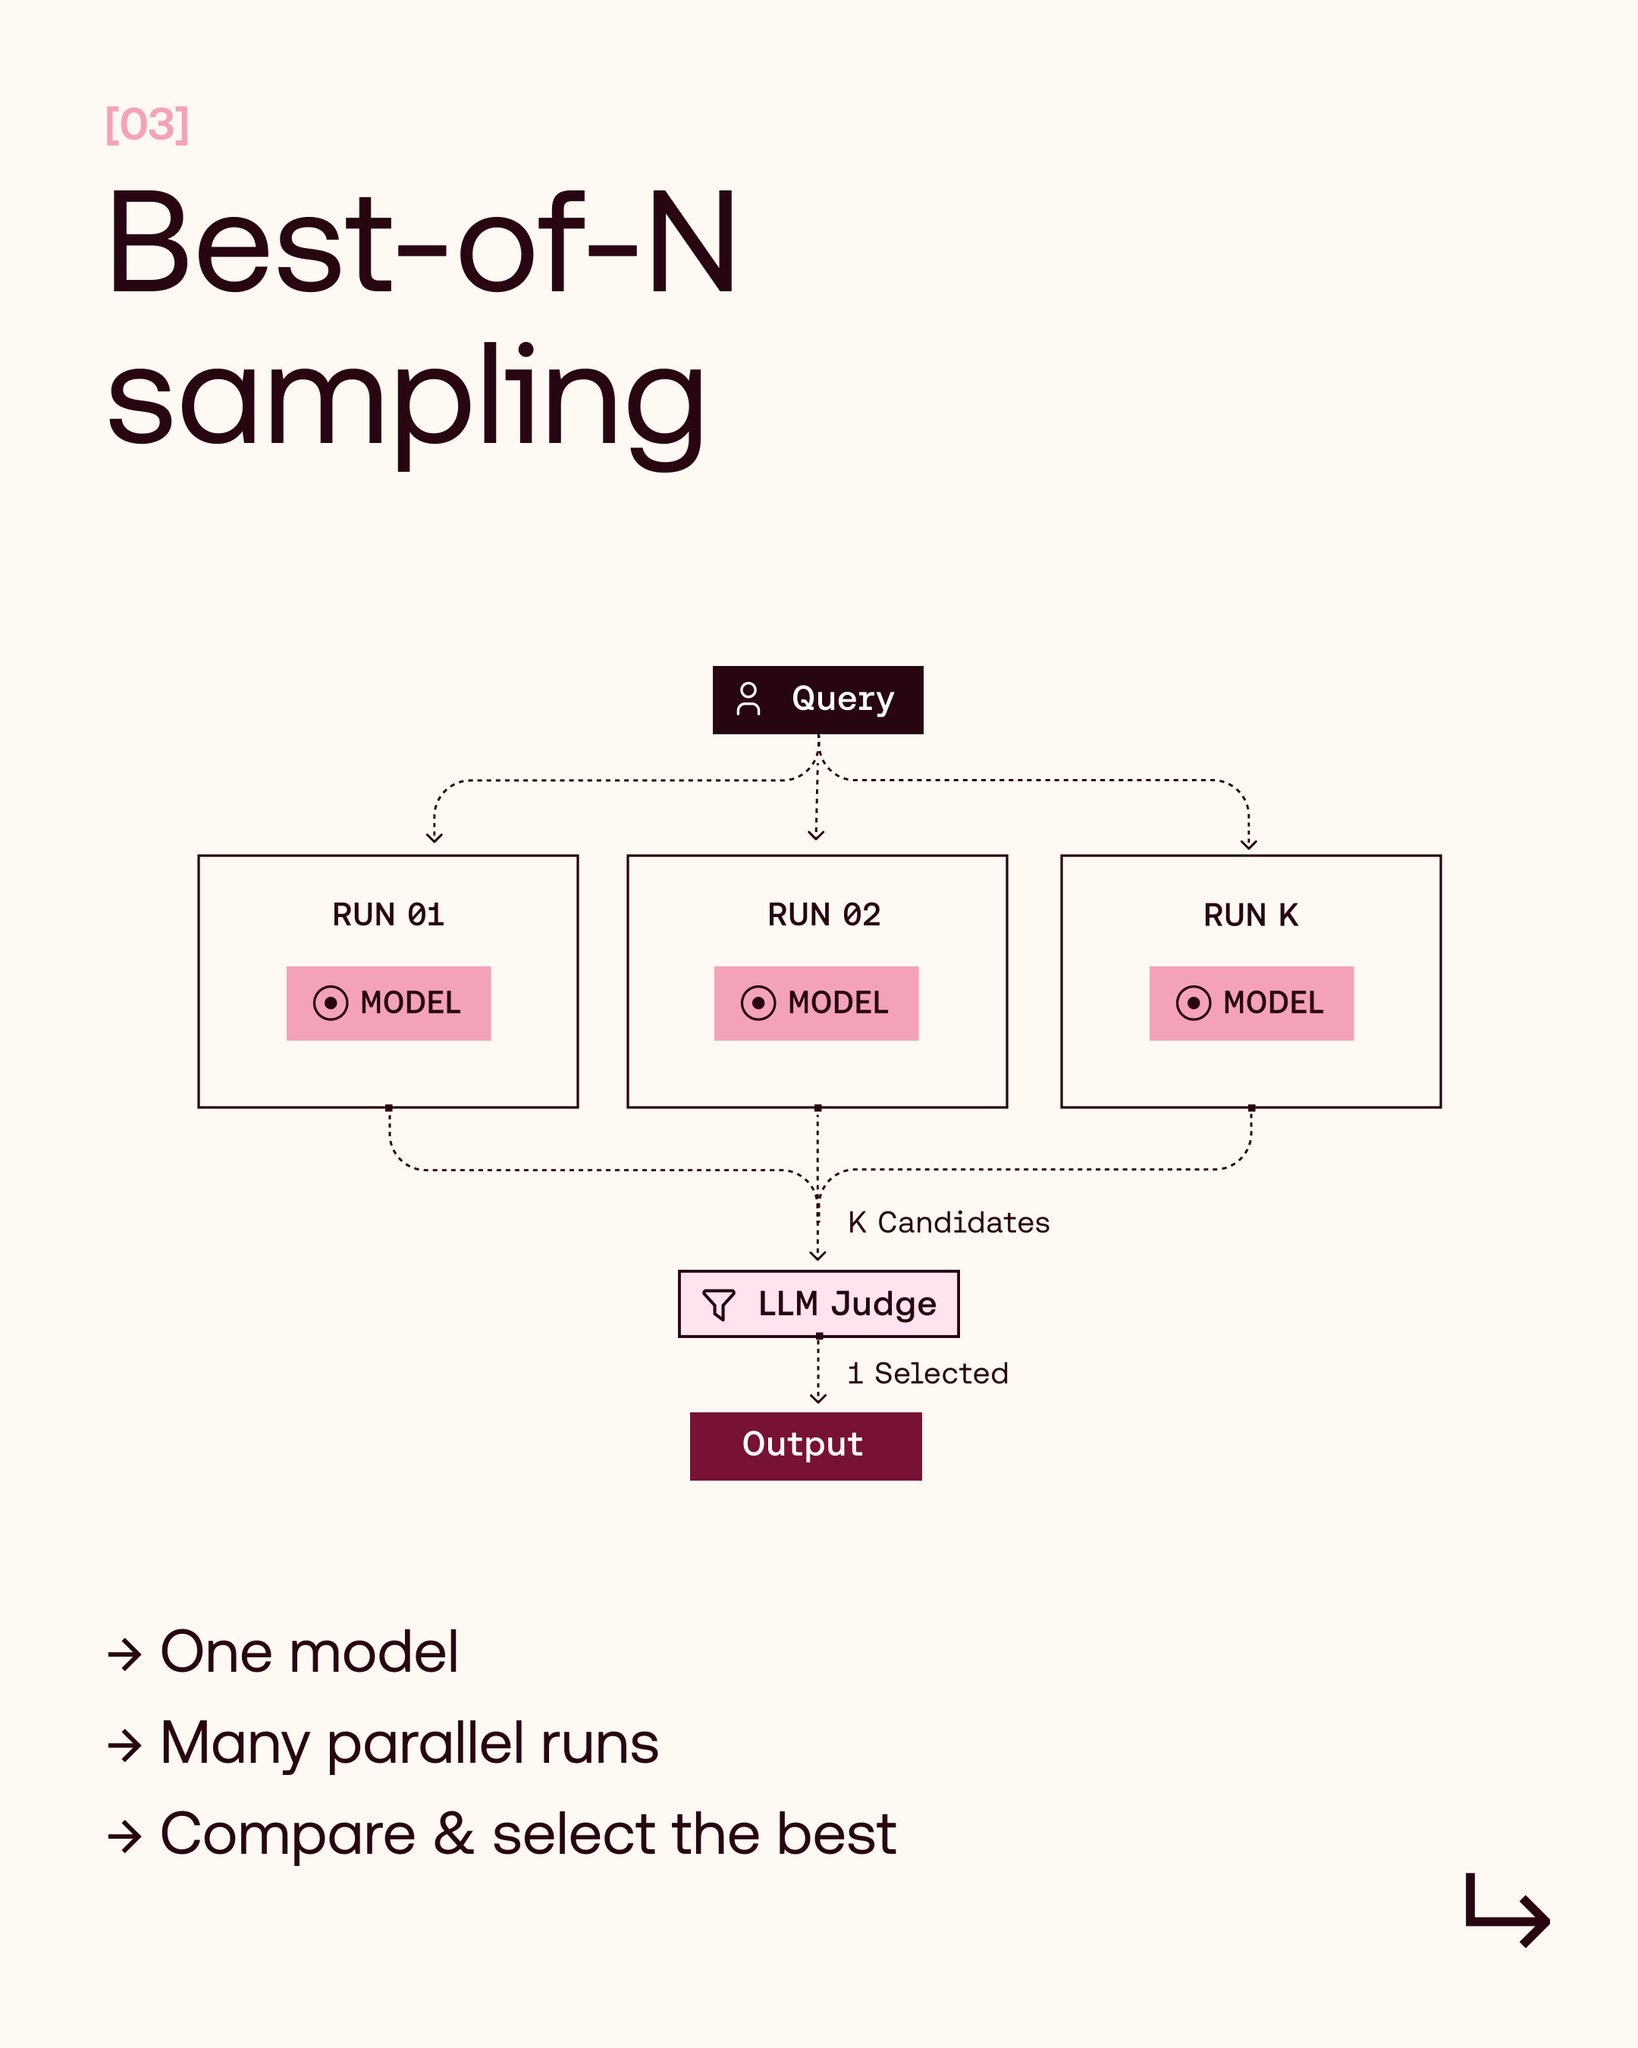
Best-of-N : optimisation parallèle d’agents IA
By
–
4/5 Best-of-N: Run one agent config N times in parallel → select the best trajectory. Leverages LLMs’ non-determinism – but hinges on a good eval mechanism (we use an LLM-as-a-Judge). Can increase accuracy without linearly increasing latency – but parallel runs can add up $$.