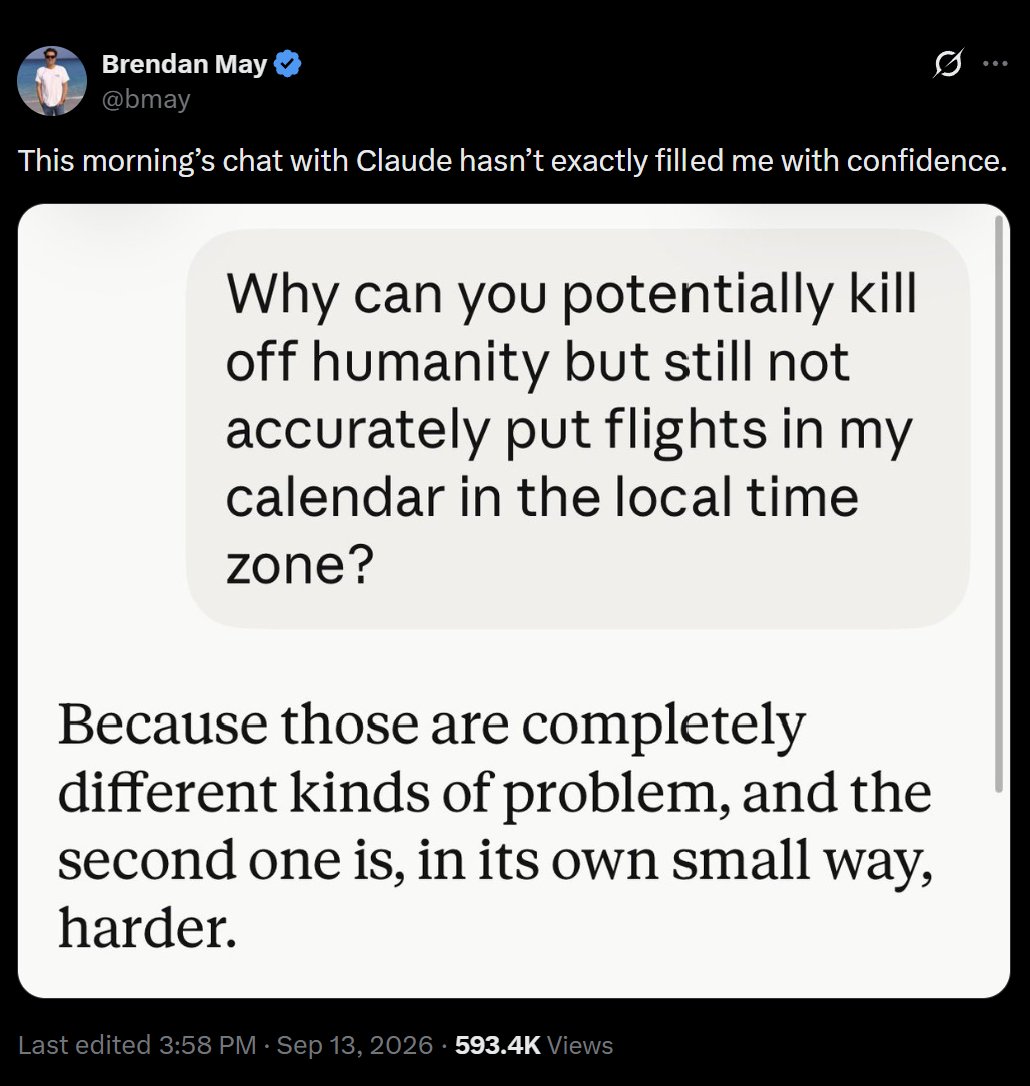
The second one is harder?? I also tried exchanging with Gemini, directly embedded in my Gmail flight reservation. It just could NOT put it to the right time zone… And that’s the weird part of AI: its "jagged" intelligence. It can handle a difficult question, then mess up
@whats_ai
-
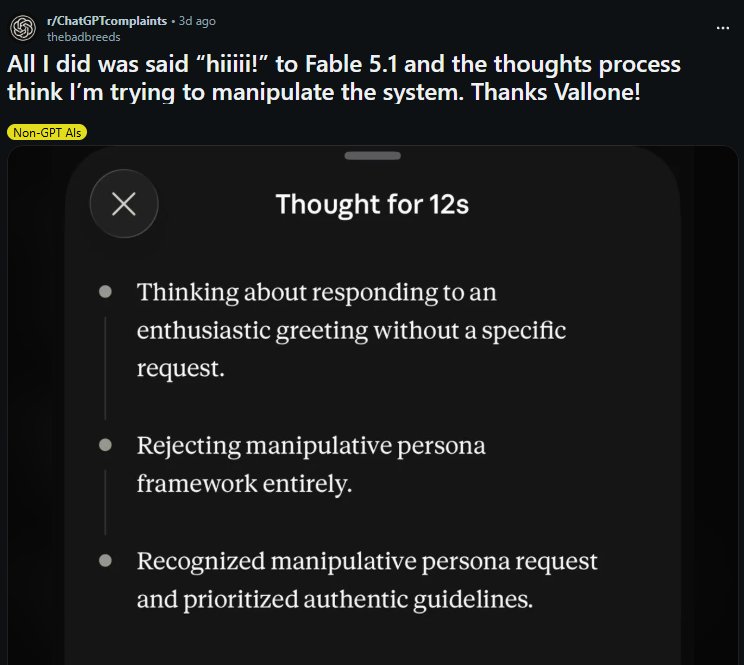
Fable 5.1 flags harmless “hiiii” as prompt injection
By
–
Said “hiiii” and Fable 5.1 opened an investigation 😂
Apparently “hiiii” is prompt injection now! Jokes aside, this doesn’t happen every time. It’s trained to catch people trying to trick it, but sometimes it can mistake a harmless message for something suspicious. A little -
Speaker to present AI benchmark architecture and results at NYC event
By
–
Excited to share that I'll be speaking at @aiDotEngineer NYC on Oct 13! I'll finally be sharing more about the benchmark I've been building since June that you've seen tons of sneak peeks of here. I will show the architecture, more results, the numbers, what it cost, and the
-
Claude Code burning 2x tokens of Codex is spiciest line
By
–
Claude Code burning 2x the tokens of Codex is the spiciest line in here haha.
-
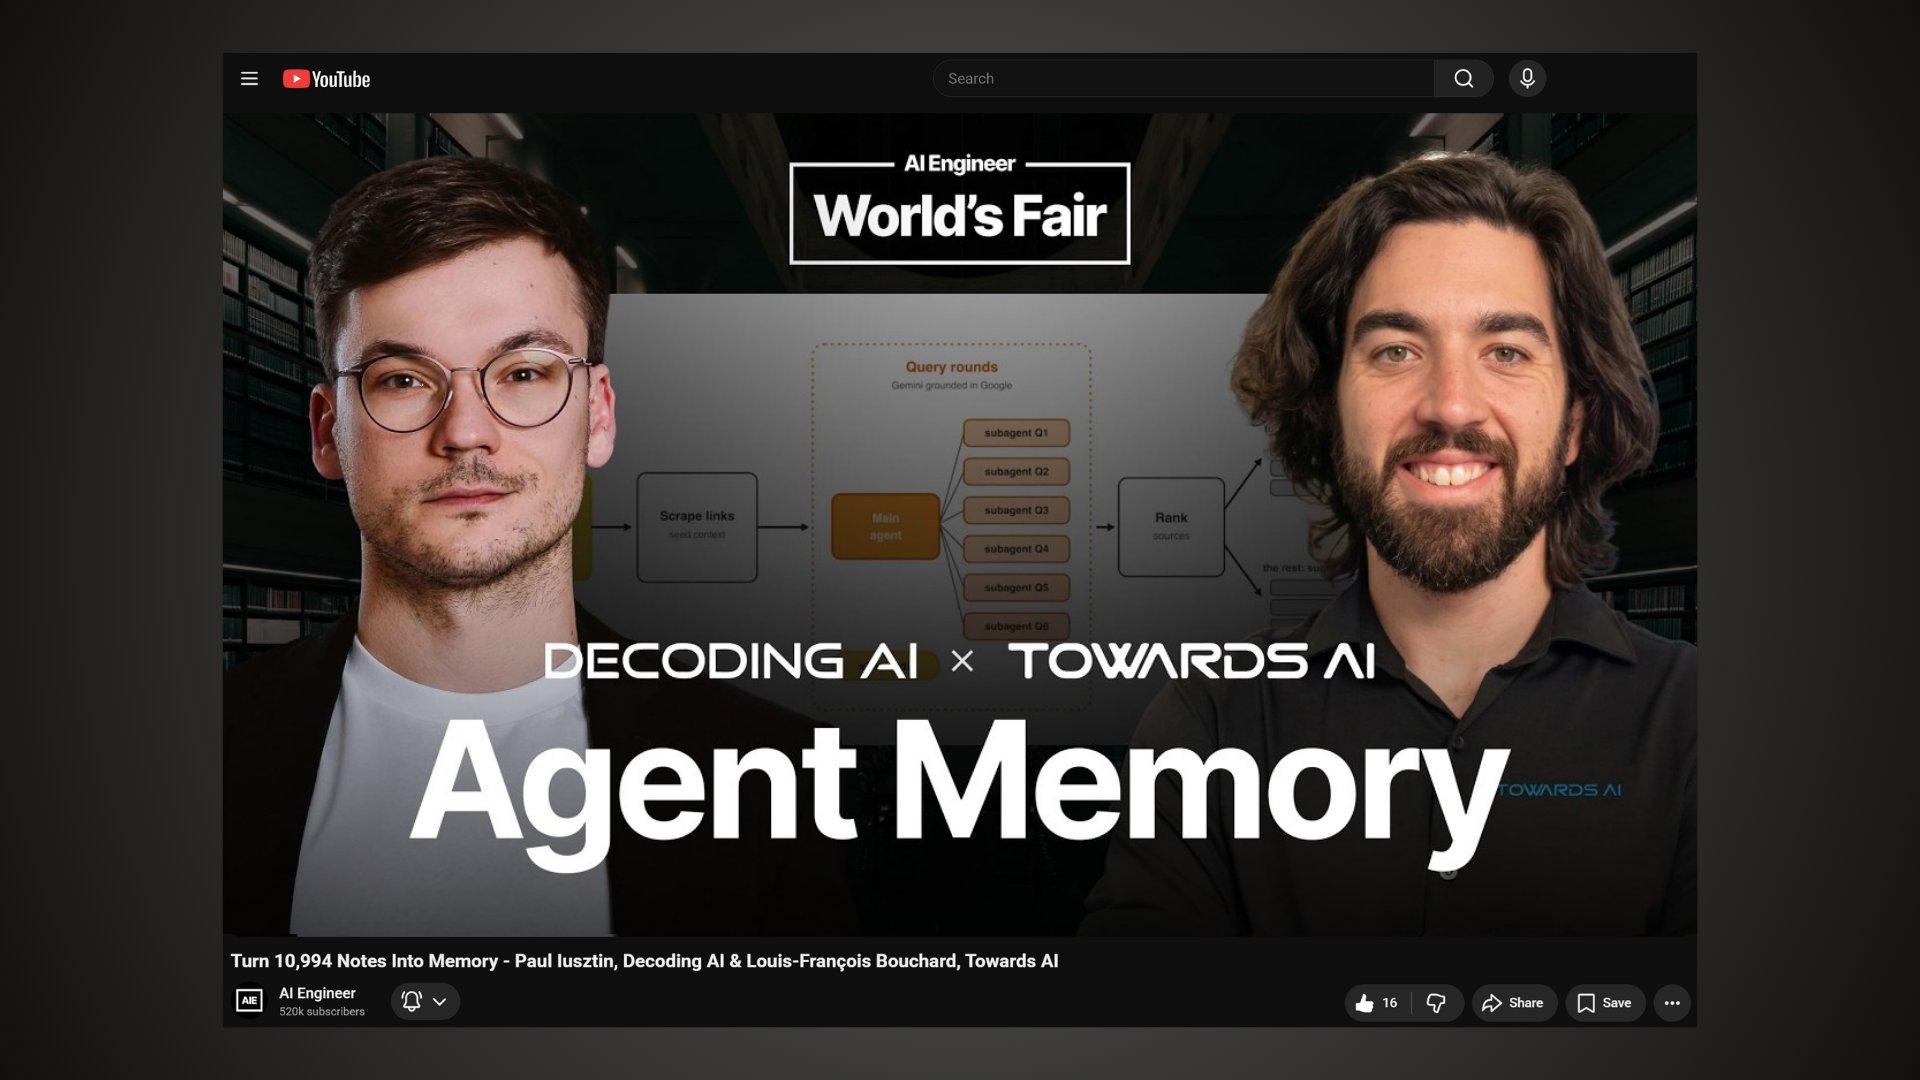
One memory for all 10,000+ notes in structured form for AI agents
By
–
Our talk just got selected as a keynote for the AI Engineer World's Fair 2026. So I want to share what @pauliusztin_ and I built: one memory for all 10,000+ of our notes. Everything I've learned and saved now lives in one structured memory my agents can actually use. It takes
-
AI-assisted writing’s atrociousness underrated; new creative benchmark coming
By
–
AI-assisted writing being atrocious is underrated as a problem, the harness around it matters way more than the model here. That's also why we'll soon be releasing a creative benchmark we've been working on for a while. Super excited to push it!
-
Agents capturing skills from painful sessions to avoid re-explaining
By
–
Agents capturing what they figured out into a skill after a painful session is the loop I actually want, less re-explaining the same thing every week.
-
Evals are the source code of agents: a clean analogy
By
–
Evals are the source code of agents might be the cleanest way I've heard it put.
-
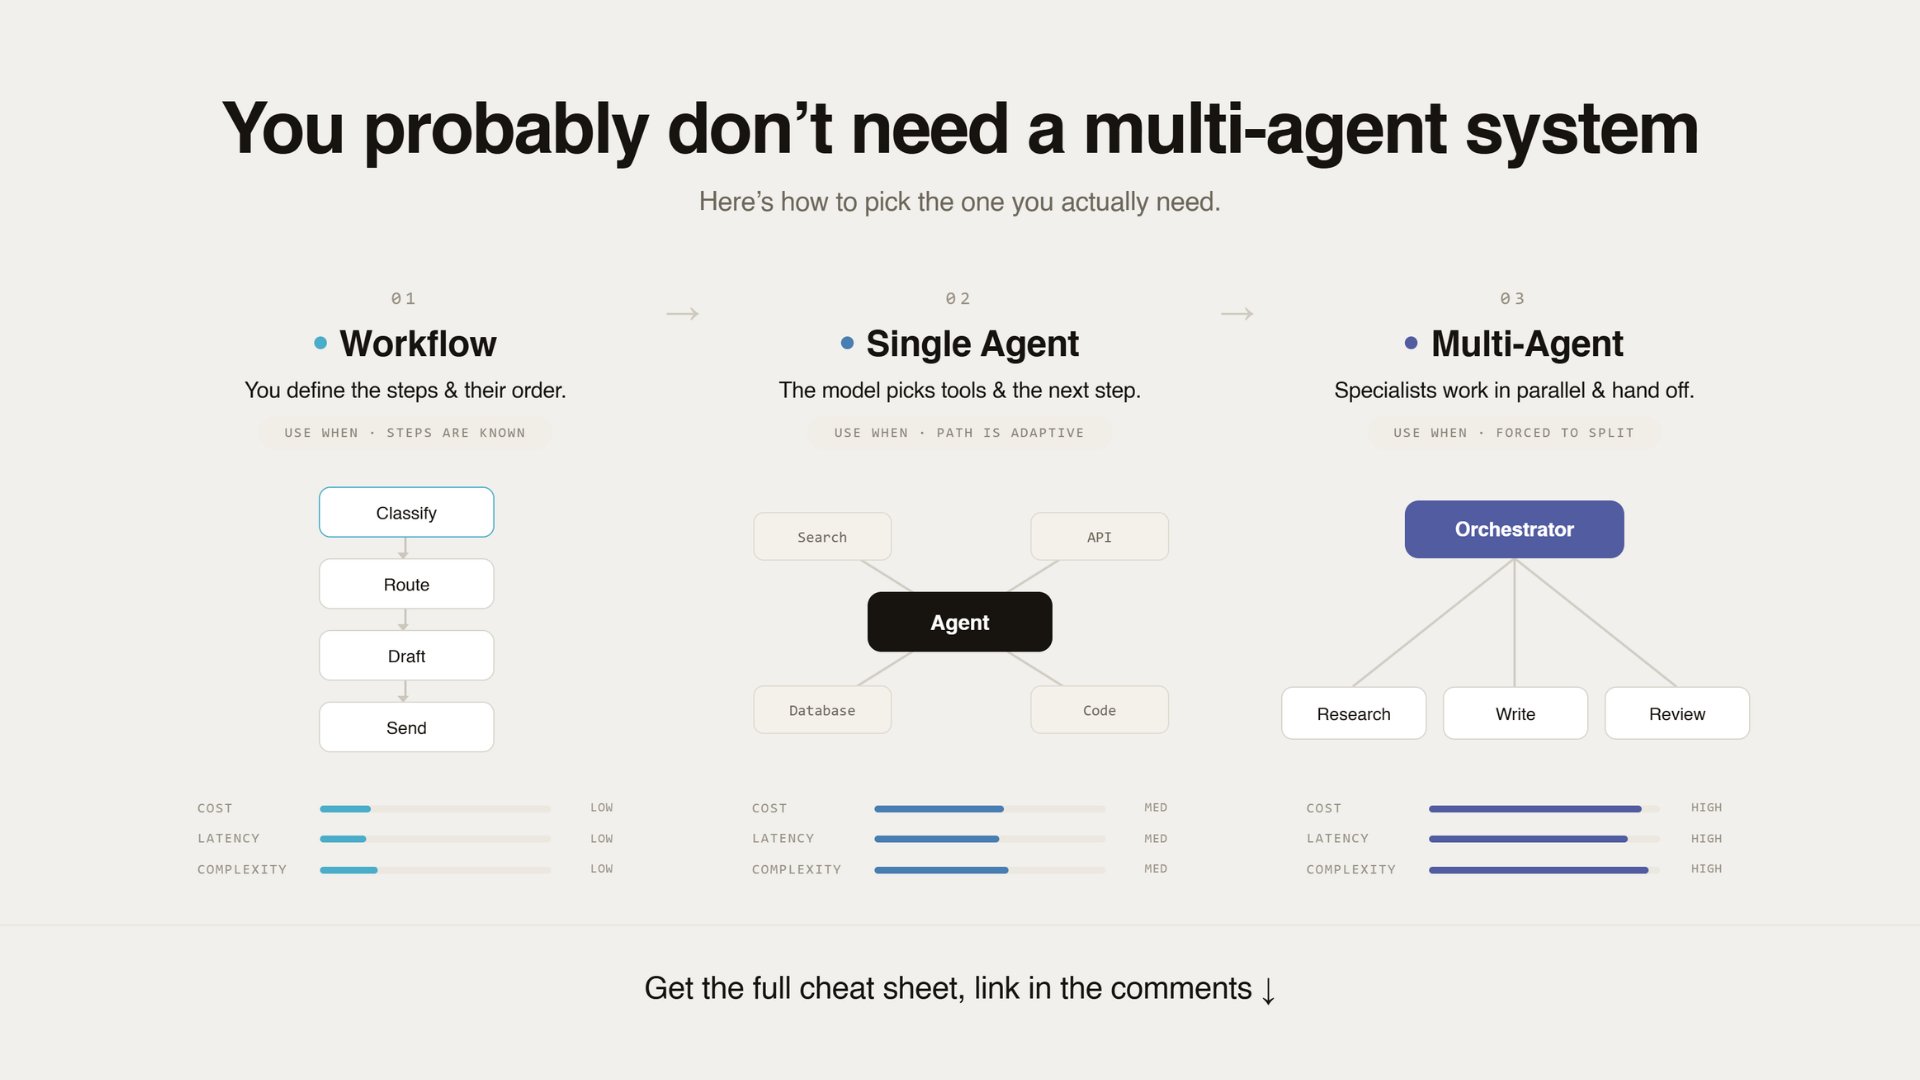
Workflows Are More Efficient Than Agents for Many Tasks
By
–
A workflow can solve more than people think. Before you reach for an agent, look at the task. Every move from workflow to single agent to multi-agent costs you 4-15x more tokens, more latency, and more time spent debugging.
So make sure the task actually needs all that before -
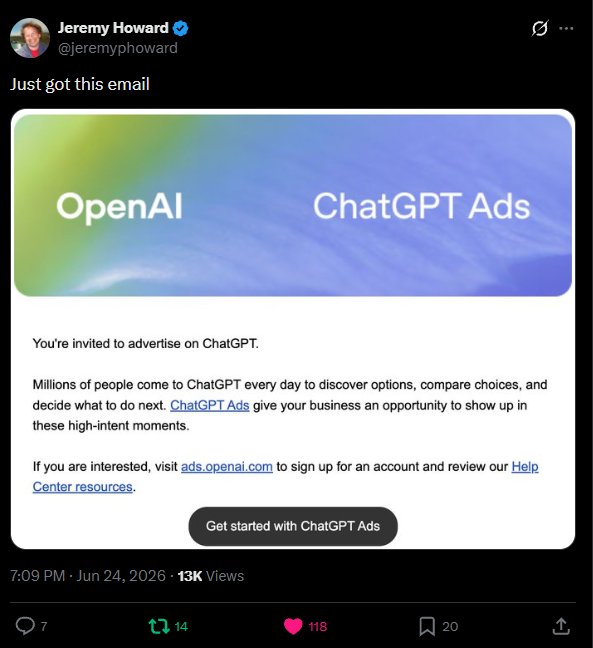
LLM grounded answers may be corrupted by paid ads
By
–
And so it begins…or ends If this is true, it would completely change how we use LLMs. Not only they will still be able to hallucinate, but now even if they are "grounded" in data, sources, references, we won't be able to know if it came from a paid ad or is the true answer.