
BREAKING : OpenAI is planing to launch a Super App that would unify ChatGPT, Codex and Atlas into one, as reported by WSJ. OneAI

By
–
BREAKING : OpenAI is planing to launch a Super App that would unify ChatGPT, Codex and Atlas into one, as reported by WSJ. OneAI
By
–
One thing I wonder about APL is whether the right-to-left precedence would cause problems for an LLM. In practice folks tend to write APL using a number of steps of creating small blocks then building them up. Perhaps LLMs need some tooling to help them…

By
–

ah bon où ca ? ca c'est les deux autres graphiques, il y a un benchmark qui ne mesure pas de capacité de code, et un graphique de comparaison speed / price.

By
–

Wait a minute… Franchement, ça devient indécent les communications autour des graphiques et des benchmarks. Tout le monde fait du cherry-pick. Ça devient ridicule, à un moment. Maintenant on invente même ces propres benchmarks "interne" pour avoir un joli grpahique où on
By
–
MiniMax-M2.7 is live on Poe! A next‑gen self‑evolving model built for autonomous software engineering and agent workflows. M2.7 can iteratively improve its own agent scaffolds, optimize task performance over repeated runs, and deliver major gains on real-world coding benchmarks

By
–
The future of AI isn't being built in a vacuum. 🤝 NVIDIA Founder and CEO Jensen Huang sat down with the builders from AMP PBC, @bfl_ml, @Cursor_ai, @LangChain, @MistralAI, @EvidenceOpen, @Perplexity_ai, @Reflection_AI, @Thinkymachines & @Allen_ai to discuss the rapid rise of open frontier models. 🔗 Learn more: blogs.nvidia.com/blog/gtc-2026-news/#open-models-panel [Translated from EN to English]
By
–
Introducing GLM 5 Turbo for understanding research papers 🚀
— alphaXiv (@askalphaxiv) 19 mars 2026
Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references pic.twitter.com/WKPGQP3ExM
Introducing GLM 5 Turbo for understanding research papers Highlight any section of a paper to ask questions and “@” other papers for quick context, comparisons, and benchmark references
By
–
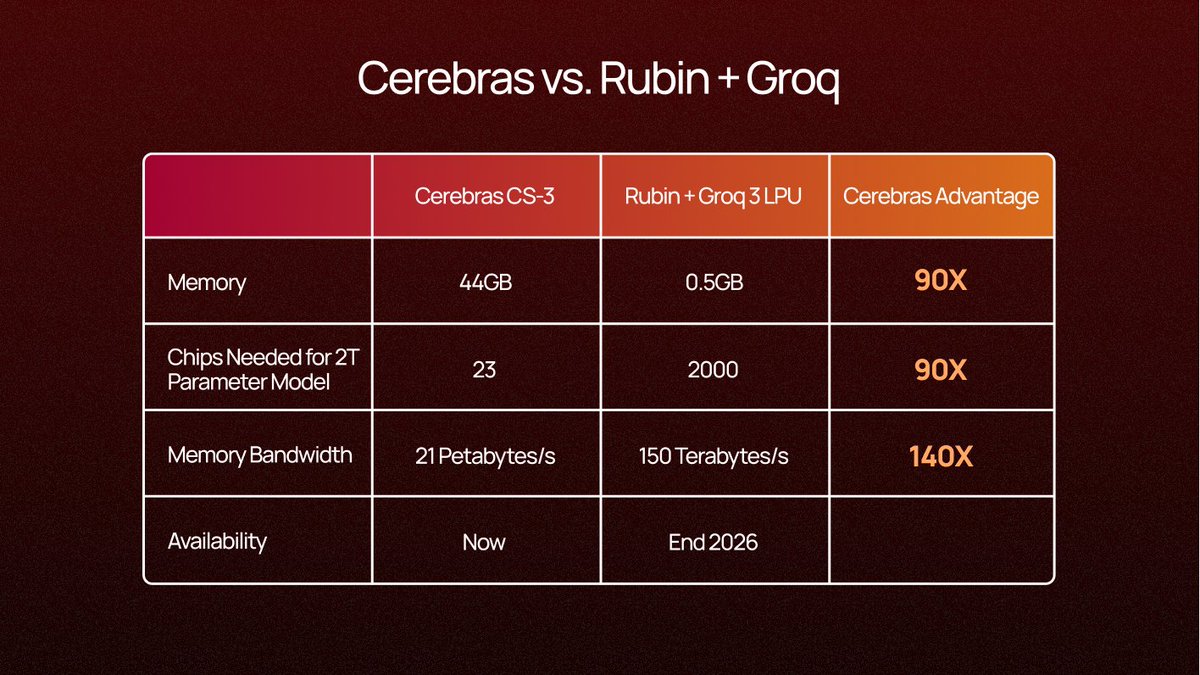
Problem solved. ✅ Andrew Feldman (@andrewdfeldman) NVIDIA's biggest GTC announcement was a $20 billion bet on the same problem we solved 6 years ago. Their next-gen inference chip – not available yet – has 140x less memory bandwidth than @cerebras. To run a single 2 trillion parameter model, you need 2,000+ Groq chips. On Cerebras, that's just over 20 wafers. Even paired with GPUs, Groq maxes out at ~1,000 tokens per second. We run at thousands of tokens per second today. And every day. In production now. Why? When you connect 2,000 chips together, every interconnect has latency. Every cable has overhead. It doesn't matter what your memory bandwidth is on paper if you're bottlenecked by the wiring between thousands of tiny chips. We solved this with wafer scale. One integrated system. Little interconnect tax. Jensen told the world that fast inference is where the value is. He’s right – it’s why the world’s leading AI companies and hyperscalers are choosing Cerebras. — https://nitter.net/andrewdfeldman/status/2034015373595672594#m
By
–
50 ML projects to understand LLMs — Investigate transformer mechanisms through data analysis, visualization, and experimentation: http://
amzn.to/4aPfP7q
—————
#AI #GenAI #MachineLearning #DataScientist #DataScience