
Static orchestration is the silent killer of multi-agent RAG systems. The query changes, but the agent topology stays the same. The work introduces HERA, a framework that jointly evolves multi-agent orchestration and role-specific agent prompts. At the global level, it optimizes query-specific agent topologies through reward-guided sampling. At the local level, it refines individual agent behaviors via credit assignment and dual-axes prompt adaptation. On six knowledge-intensive benchmarks, HERA achieves an average improvement of 38.69% over recent baselines. Why does it matter? As multi-agent RAG systems scale, the gap between fixed pipelines and adaptive orchestration will only grow. HERA shows that letting the system learn its own coordination structure produces compact, high-utility agent networks. Paper: arxiv.org/abs/2604.00901 Learn to build effective AI agents in our academy: academy.dair.ai/
CODE
-
Abacus AI Simplifies OpenClaw Agent Deployment Without Setup
By
–
OpenClaw is overhyped. Most people can’t even run it properly – setup is messy, security is risky, and it breaks easily Abacus AI fixed that. Run OpenClaw-style agents with Abacus AI Agent. no setup, no configs, just real workflows running end-to-end.
-
mngr: Open Source Tool for Managing Parallel Claude Code Sessions
By
–
mngr: programmatically manage 100s of claude code sessions in parallel 🤖 open source today. lets you do things like: — for each open GitHub issue, create a PR — for each flaky test in the past week, fix it — for each rule in style guide, scan codebase & fix all instances runs any agent: @claudeai, codex, @opencode, etc. runs on any compute: locally, @modal, @Docker, or anything you can ssh into.
-
Hiring Exceptional Engineers Across Speech Data Coding and RL
By
–
We are hiring exceptional speech, data, coding, RL and inference engineers, as well as exceptional new graduates. Also, high-performance numerical computing engineers that can build libraries for new chips. We want generalists that can do anything and put the team above ego.
-
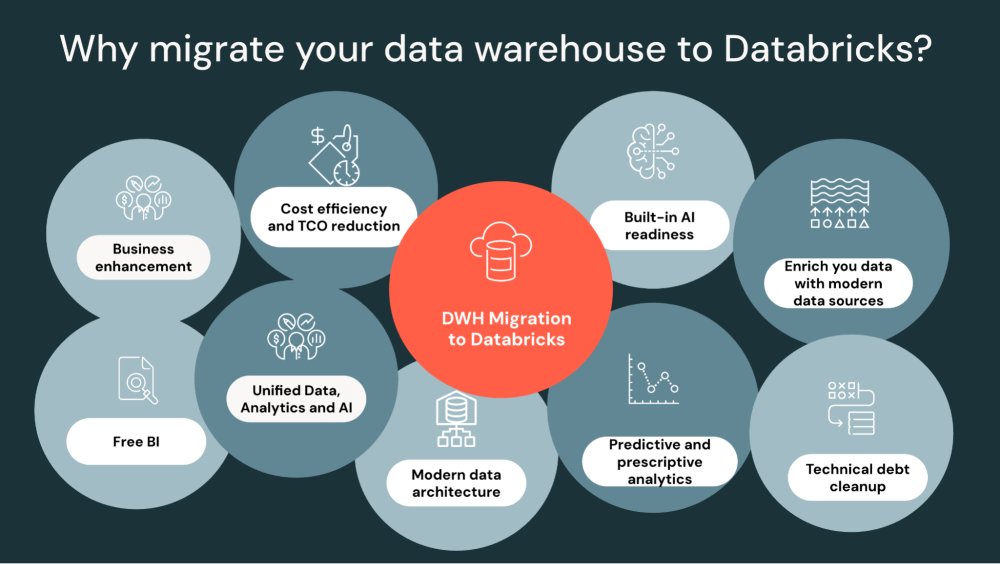
Data Warehouse Migration: Beyond Cost and SQL Conversion
By
–
Data warehouse migrations are often slowed down by the wrong assumptions. Focusing only on cost, treating it as SQL code conversion, or migrating all legacy objects can increase cost, extend timelines, and carry forward unnecessary technical debt. The reality is different.
-
Open-source plugin optimizes Claude Code with multi-agent coordination
By
–
Your Claude Code setup is 3x slower than it could be right now.
— AlphaSignal AI (@AlphaSignalAI) 2 avril 2026
An open-source plugin can now run 32 specialized AI agents inside Claude Code.
Zero new tools. Zero learning curve.
The project is called oh-my-claudecode.
It coordinates Claude, Gemini, and Codex through tmux… pic.twitter.com/XdA0p71JIEYour Claude Code setup is 3x slower than it could be right now. An open-source plugin can now run 32 specialized AI agents inside Claude Code. Zero new tools. Zero learning curve. The project is called oh-my-claudecode. It coordinates Claude, Gemini, and Codex through tmux
-
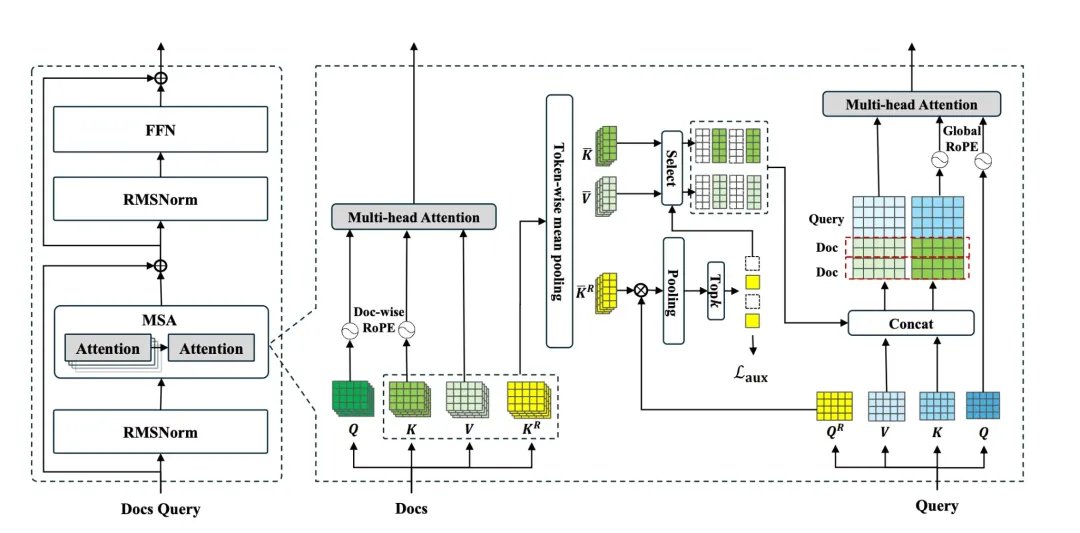
Memory Sparse Attention Framework Enables 100M Token Processing
By
–
Can AI models finally process context the size of a lifetime? Evermind, Shanda Group, and Peking University present Memory Sparse Attention (MSA)! This new framework gives AI a massively scalable, end-to-end trainable long-term memory. It uses an innovative sparse attention architecture and other techniques to handle hundreds of millions of tokens with linear efficiency, maintaining exceptional precision. MSA processes 100M tokens on 2xA800 GPUs with less than 9% precision degradation from 16K. It significantly outperforms frontier LLMs, SOTA RAG systems, and leading memory agents in long-context benchmarks, paving the way for lifetime-scale AI memory. MSA: Memory Sparse Attention for Efficient End-to-End Memory Model Scaling to 100M Tokens Code: github.com/EverMind-AI/MSA Paper: zenodo.org/records/19103670 Our report: mp.weixin.qq.com/s/FHJA4kALc… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-02 14:25 UTC
-

Kilocode VS Code Extension Updates with Open-Source Core
By
–
Holy Moleyyy @kilocode just dropped a massive update to their VS Code extension Going with an open-source core (OpenCode) is a bold move. ..but spinning up multiple agents on isolated git worktrees so they don't step on each other's code? Too cool!
-
PSF Security Reports LiteLLM and Telnyx Supply Chain Attacks
By
–
PSF Security developers have published incident reports on the LiteLLM & Telnyx #supplychain attacks. Read what happened, who's affected, and what developers & maintainers can do to prepare and protect themselves from future incidents. #security #python blog.pypi.org/posts/2026-04-…
-

LLaMA-Factory: Fine-Tune 100+ LLMs Without Coding
By
–
If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/203… Sumanth (@Sumanth_077) Fine-Tune 100+ LLMs without writing a single line of code! LLaMA-Factory lets you train and fine-tune open-source LLMs and VLMs without writing any code. Here's why it's a game changer for fine-tuning: • Fine-tune 100+ LLMs/VLMs with built-in templates (LLaMA, Gemma, Qwen, Mistral, DeepSeek, and more). • Zero-code CLI & Web UI for training, inference, merging, and evaluation. • Supports full-tuning, LoRA, QLoRA, freeze-tuning, PPO/DPO, OFT, reward modeling, and multi-modal fine-tuning. • Speeds up training/inference with FlashAttention-2, RoPE scaling, Liger Kernel, and vLLM backend. • Integrates experiment tracking via LlamaBoard, TensorBoard, Weights & Biases, MLflow, and SwanLab. It's 100% Open Source Link to the Github Repo in the comments! — https://nitter.net/Sumanth_077/status/2039701710659272775#m
→ View original post on X — @sumanth_077, 2026-04-02 13:50 UTC