This is truly inspirational! We called it neural nets, machine learning, deep learning, AI, SI over the decades, but it was always the same idea: artificial neural nets are remarkable at learning to solve problems from data
@nandodf
-
Years of work on diffusion models including text
By
–
I never flipped. I’ve been working on diffusion, including text, for many years (decades in fact 😅)
-
Paper praised for executing Gato idea with humanoid; more work desired
By
–
This is a nice paper, well executed! @scott_e_reed had this in mind when developing Gato https://
arxiv.org/abs/2205.06175 — I’m glad to see the idea executed with a humanoid and I’d love to see more work along this direction. Gato stood for General AgenT One. Sadly, we weren’t able to -
Using video to learn control representations, touch important
By
–
I think they also emerge from video. This is what I was the most excited about when helping with projects like Veo. My intent was never to create slop videos, but rather to use video to learn representations for control. I must say however that touch is super important and highly
-
Next-token prediction compresses latent structure into understanding
By
–
A model trained for next-token prediction is forced to build compressed representations of latent structure in text. Ilya Sutskever correctly refers to this phenomenon as understanding. Here, a model trained for next-step sensor prediction, with a robot that has proprioception… pic.twitter.com/rHh1nFjJxd
— Nando de Freitas (@NandoDF) 27 juin 2026A model trained for next-token prediction is forced to build compressed representations of latent structure in text. Ilya Sutskever correctly refers to this phenomenon as understanding. Here, a model trained for next-step sensor prediction, with a robot that has proprioception
-
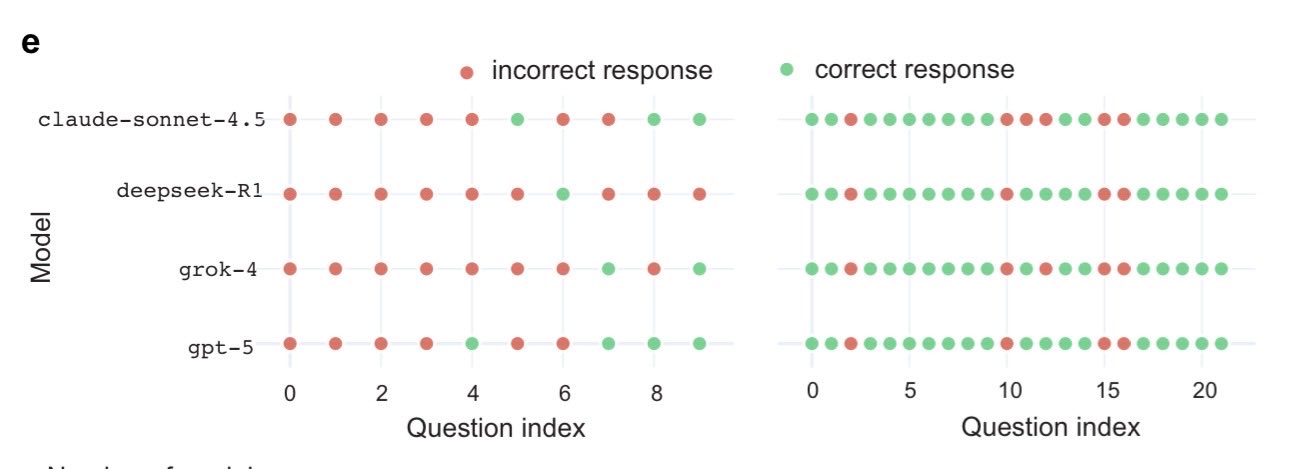
Homogeneity in LLM training: same evals, data, distillation
By
–
When everyone uses the same evals, data, distillation and vendors to train LLMs. Courtesy of: https://
arxiv.org/abs/2512.15567 -
AI training costs: $1B needed, OpenAI leads in funding
By
–
Most of these points are correct, especially point 5. Point 6 is however incorrect. I’ve trained at frontier scale recently and know that you need $1B (like Mistral or Cohere to be even 1 or 2 years behind). This is the real competition: Money raised: OpenAI has raised more in
-
Advances come from good engineering: HPC, data, eval, RL
By
–
No. Every advance that has or is happening now stems from good engineering: HPC, data, eval, and distributed RL.
-
UK and Europe cannot compete due to massive chip costs
By
–
We should talk @matthewclifford
. It is incorrect to think the UK and Europe are fine or that they could catch up within a year. It costs $1B to $5B just in chips to be frontier. The idea that we can build small models, like Llama, and expect to compete with 2B ones trained on