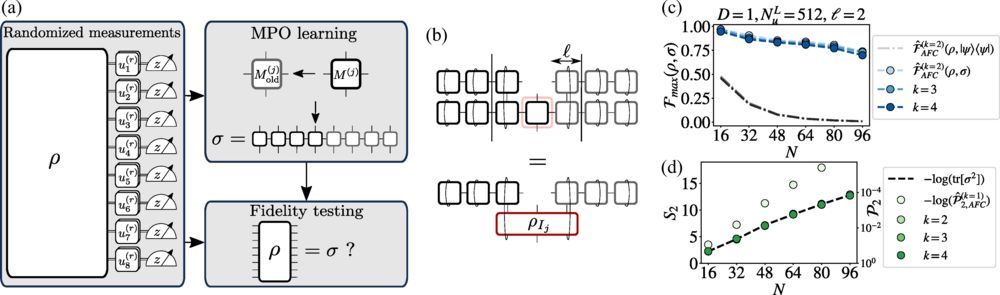
Novel Protocol Reconstructs Quantum States with 96-Level Learning! #BigData #Analytics #AI #MachineLearning #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode
CODE
-
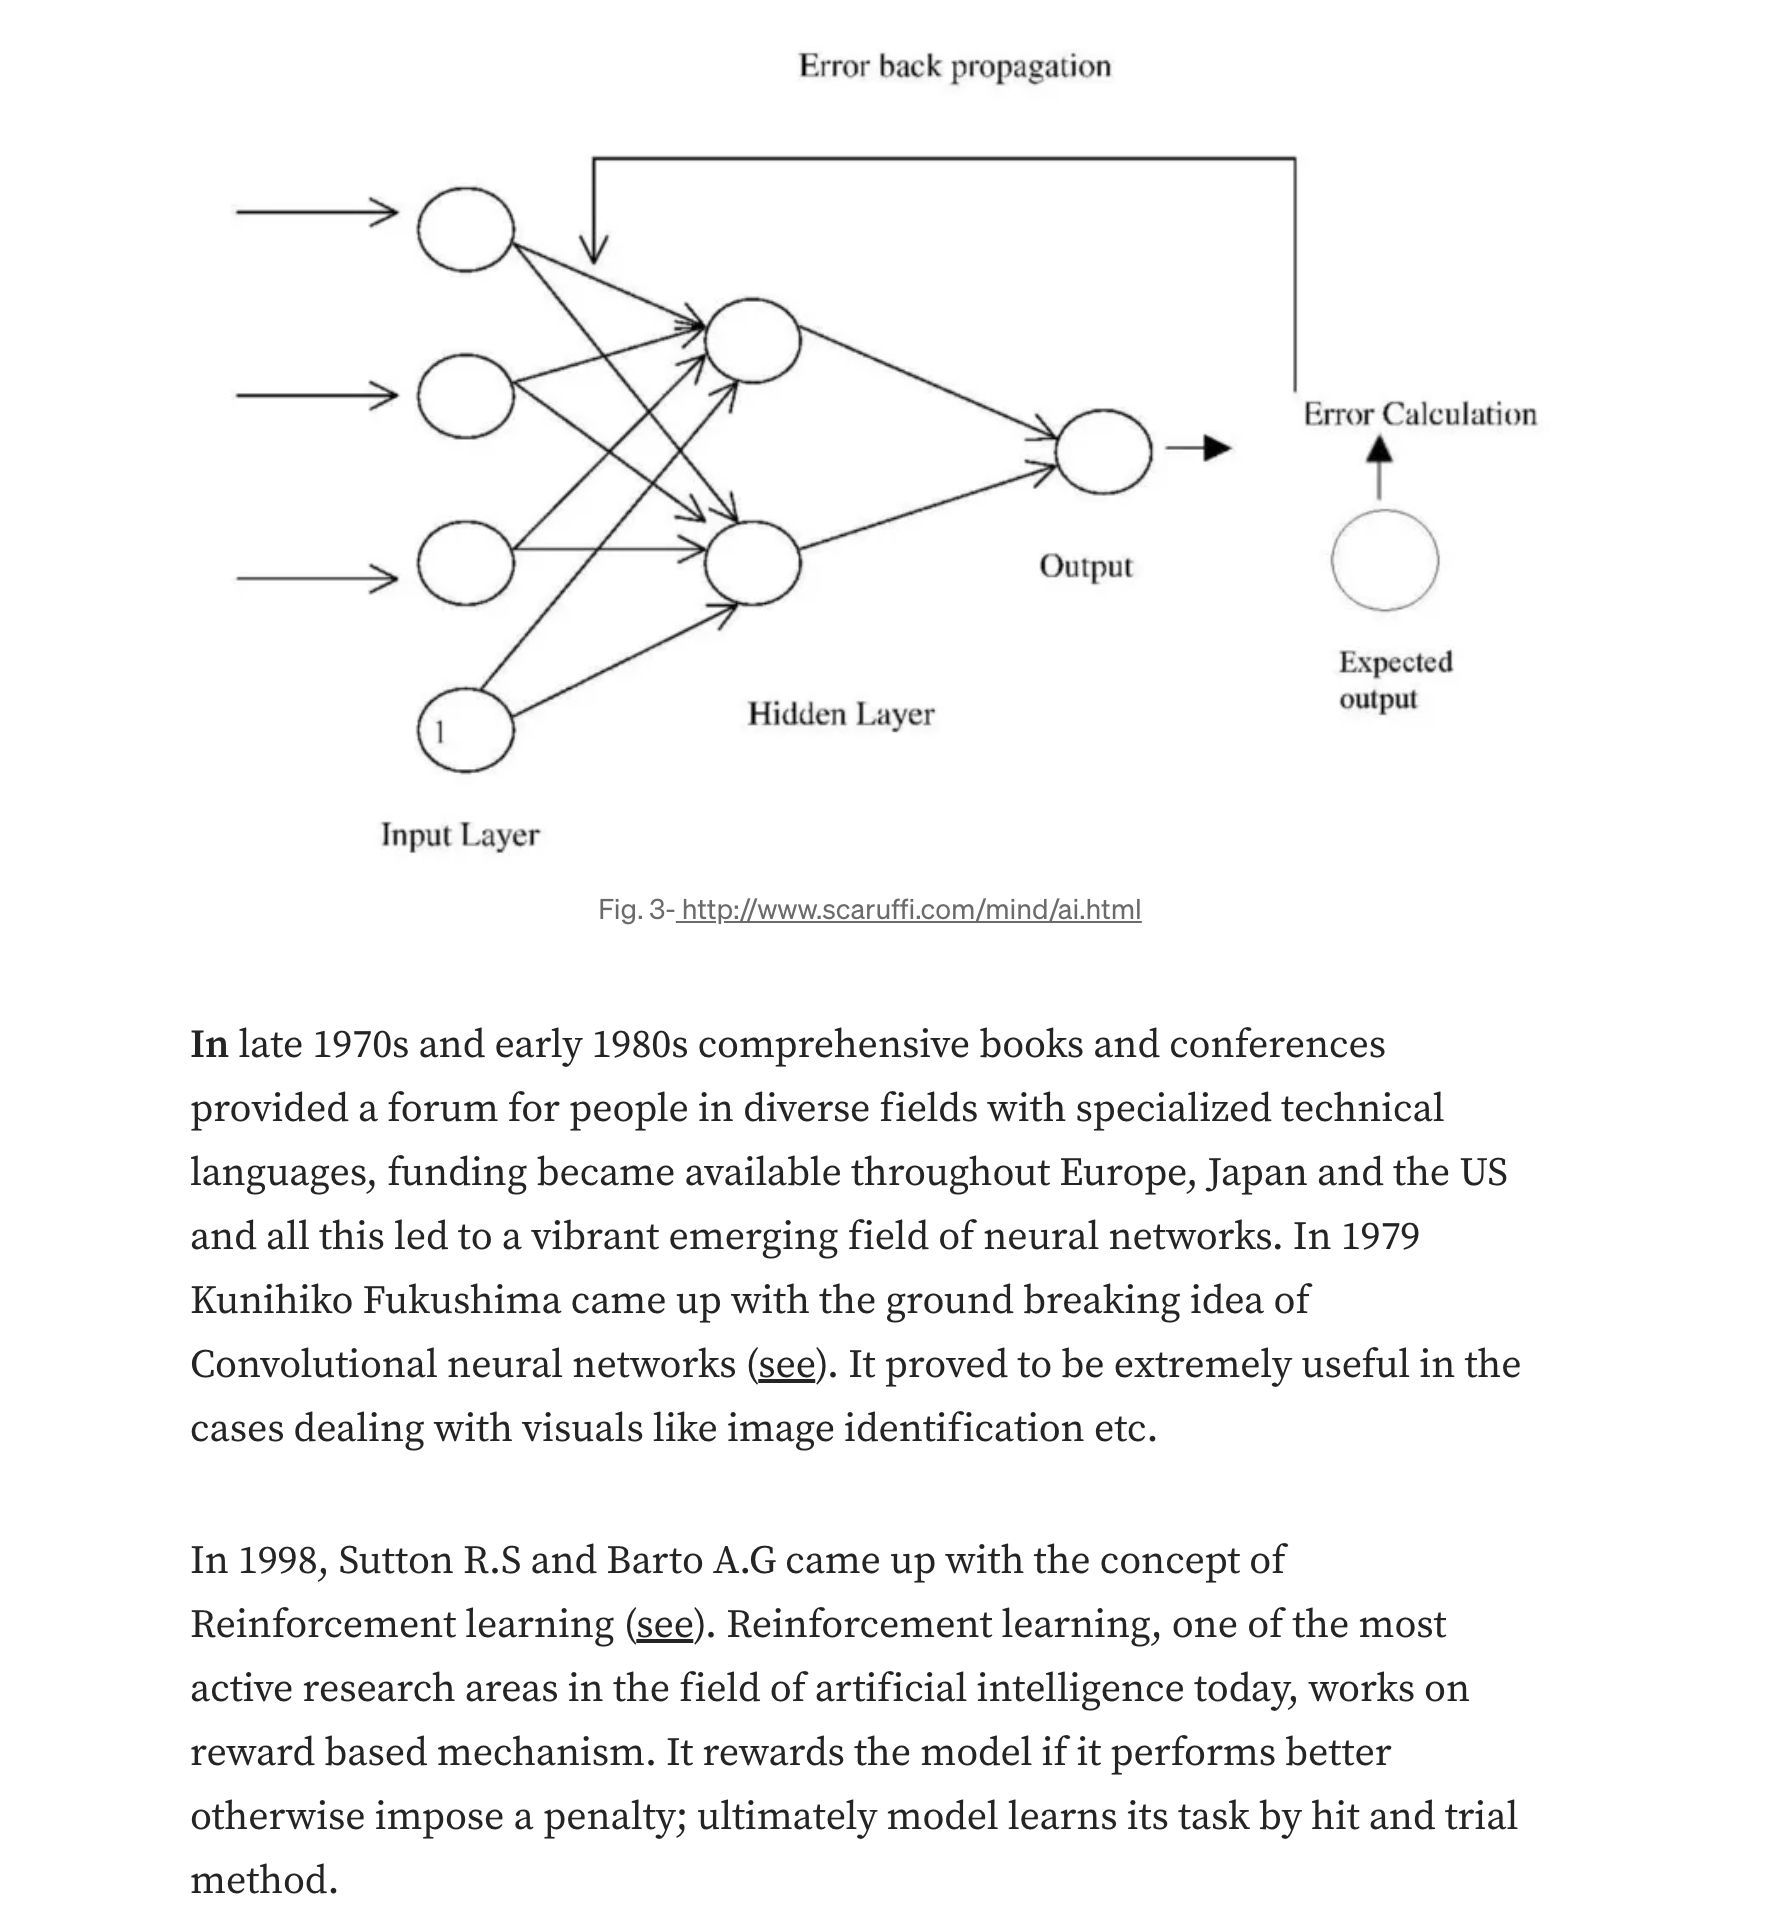
Introduction to Neural Networks: AI and Machine Learning Fundamentals
By
–
Intro to Neural Networks! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode https://
geni.us/Intro-Neural-N
ets
… -
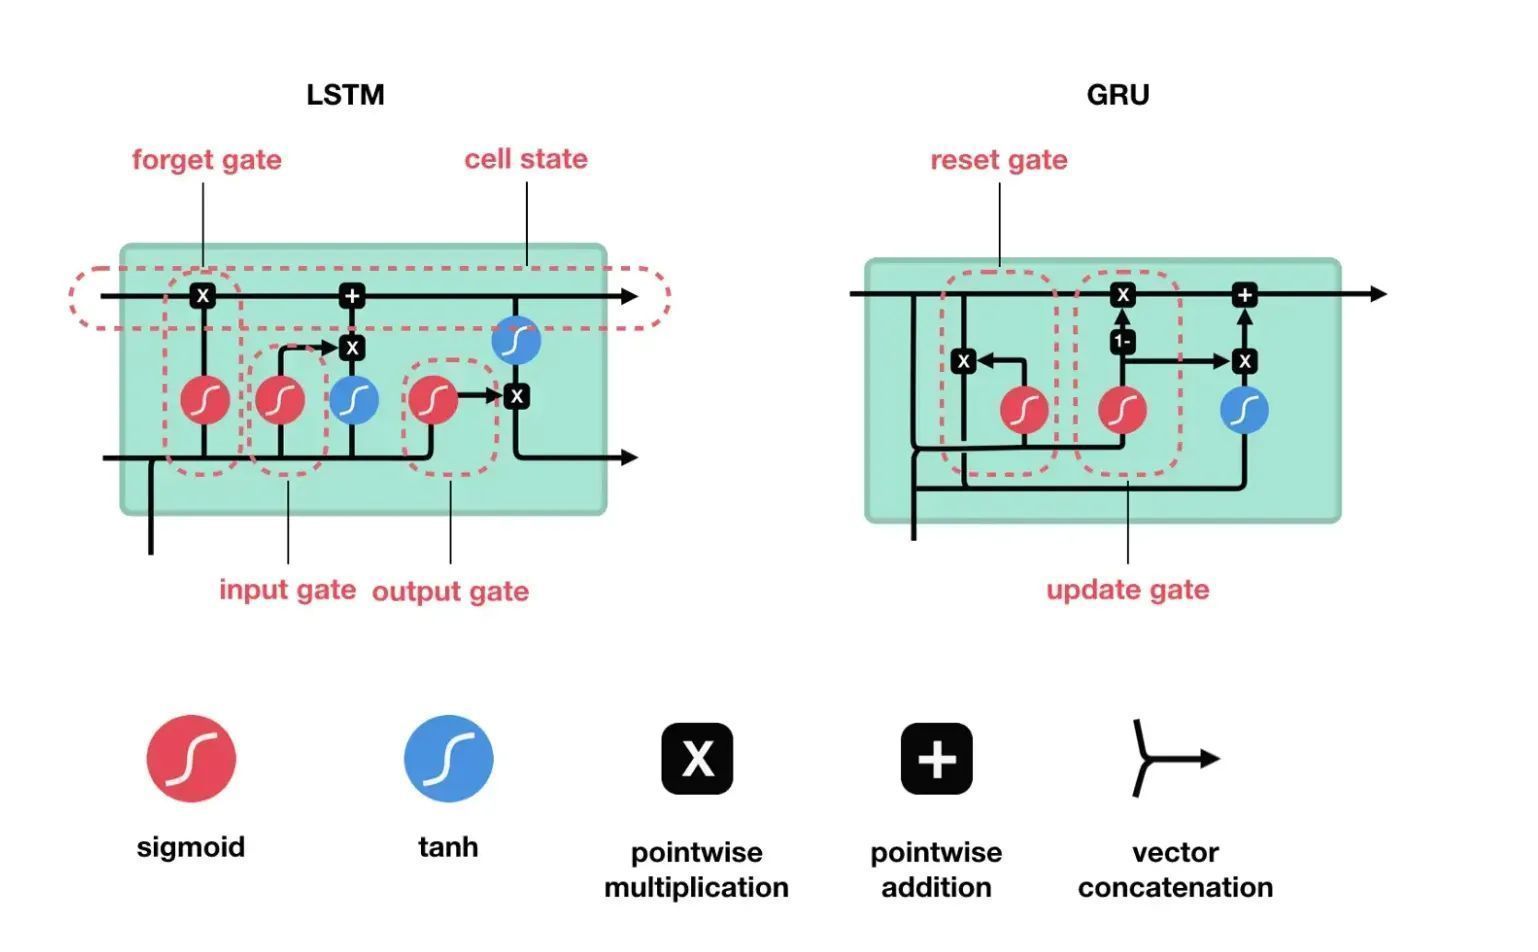
Illustrated Guide to LSTMs and GRUs for Deep Learning
By
–
Illustrated LSTMs and GRUs. #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode https://
geni.us/Illustrated-Gu
ide
… -
Linux Package Issues and GPU Memory Bugs Frustration
By
–
It’s been a long frustrating day of dealing with crappy Linux packages and out-of-memory GPU bugs. :/
-
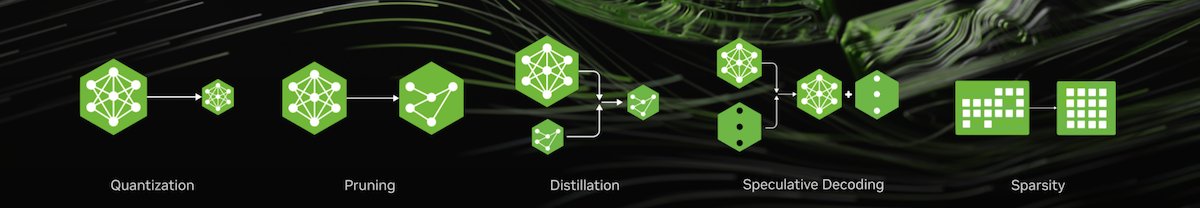
NVIDIA Releases Quantized Gemma 4 31B Model on Hugging Face
By
–
NVIDIA just released a quantized Gemma 4 31B on Hugging Face NVFP4 compression delivers 4x smaller weights with frontier-level accuracy. Runs on consumer GPUs with a 256K context window.
→ View original post on X — @huggingface, 2026-04-02 17:17 UTC
-
llama.cpp achieves 300 tokens/second on Mac Studio M2 Ultra
By
–
Let me demonstrate the true power of llama.cpp:
— Georgi Gerganov (@ggerganov) 2 avril 2026
– Running on Mac Studio M2 Ultra (3 years old)
– Gemma 4 26B A4B Q8_0 (full quality)
– Built-in WebUI (ships with llama.cpp)
– MCP support out of the box (web-search, HF, github, etc.)
– Prompt speculative decoding
The result:… pic.twitter.com/B3EnpbWJdeLet me demonstrate the true power of llama.cpp: – Running on Mac Studio M2 Ultra (3 years old) – Gemma 4 26B A4B Q8_0 (full quality) – Built-in WebUI (ships with llama.cpp) – MCP support out of the box (web-search, HF, github, etc.) – Prompt speculative decoding The result: 300t/s (realtime video)
-
Llama-server powers new AI tool integration
By
–
very cool! uses llama-server from @ggerganov @huggingface under the hood? cc @julien_c @XciD_
-
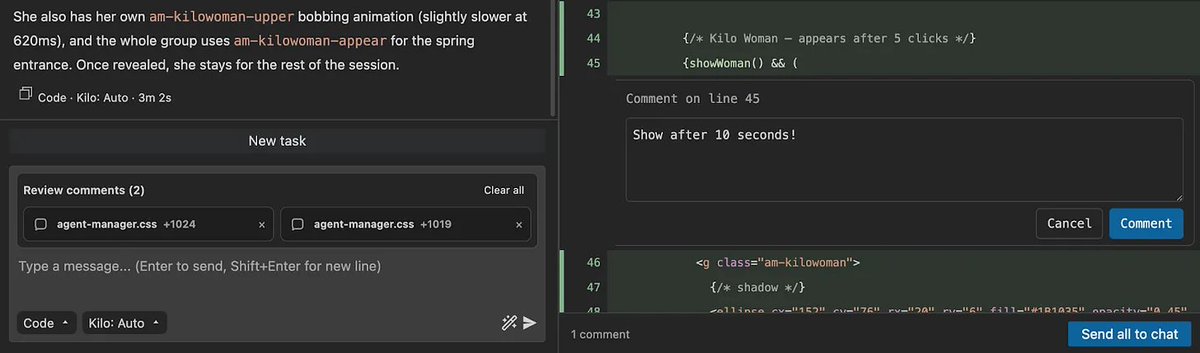
Observability Over Autonomy: The Real Challenge in Coding Agents
By
–
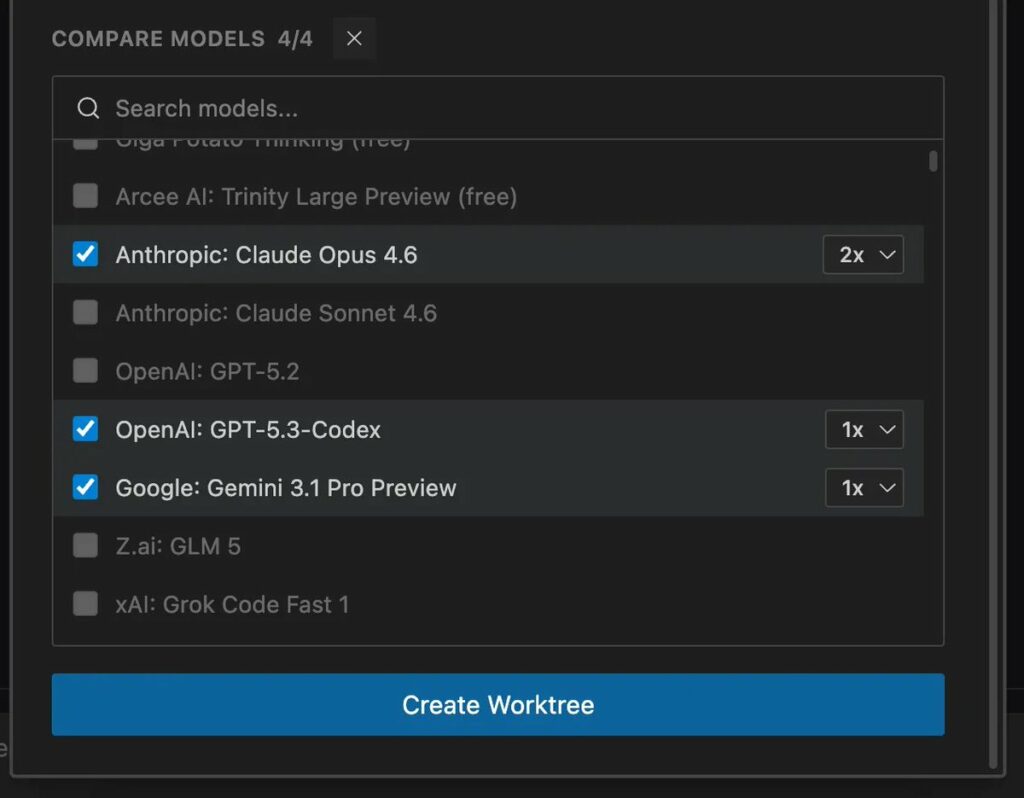
Most coding agents do not fail because they are weak. They fail because they are hard to inspect. The real problem with coding agents is not autonomy. It’s easy to make them “autonomous”. The problem is observability. A lot of tools still look impressive right until the moment they say “done”, move on, and when you check, the thing is half-built, wrong, or never happened. It happens to me almost every day, and if you don’t check for it, you might as well skip half your to-do tasks… That is why I care so much about observability and control in agentic coding. Not just more tool calls. Not just more agents. Not just more autonomy. I want to see the diff. I want to review the exact line and ensure it was done, and understand how. I want to send (only relevant) feedback back into the context. I want to compare models on a real task in my repo instead of guessing. That is what I found interesting in the rebuilt Kilo Code extension on VS Code. Yes, the parallel subagents and tons of features are cool. But the part I care about more is the (human) review loop around them. You can inspect what each agent changed, comment directly on the diff, and send those comments back as structured context. That matters. Because the value of these tools is not just in generation. It is correction. It is debugging weird hallucinations (and other LLM weaknesses). It is catching the moments where the model says “I made it” and absolutely did not. And honestly, model comparison on real tasks is underrated too. Benchmarks are nice. Your repo and actual use case are way nicer. If a tool helps you compare quality, behaviour, and likely cost on your own codebase, that is real value. A 2026 tool NEEDS to be focusing around models’ weaknesses, which starts with observability and monitoring. And, unfortunately, observability, control, and evaluation are still missing layers in many agent products. I highly recommend trying it out and taking the time to review agents’ code in general! I put the link in the comments if you want to try it. What do you care about more in coding agents today: more autonomy, or more observability?
-
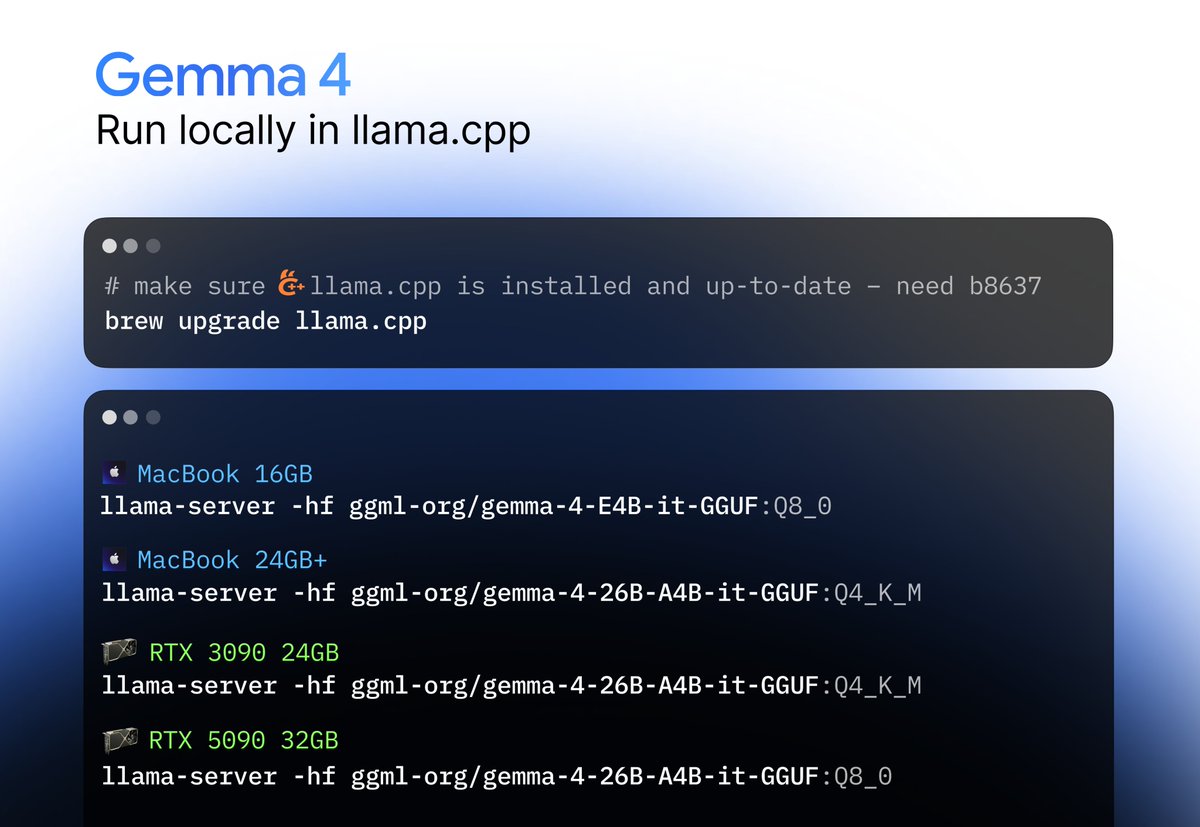
Installing and Running Llama.cpp with Gemma Model
By
–
Just do this: brew install llama.cpp –HEAD Then; llama-server -hf ggml-org/gemma-4-26B-A4B-it-GGUF:Q4_K_M
-
TierZero: AI Platform Automating Incident Response for Engineering Teams
By
–
LangSmith for Startups Spotlight: TierZero
— LangChain (@LangChain) 2 avril 2026
Engineering teams are shipping code faster than ever, but production operations remain heavily manual and concentrated in the hands of a few experienced engineers. The result: slower incident resolution, constant interruptions, and… pic.twitter.com/DKWXhzK4POLangSmith for Startups Spotlight: TierZero Engineering teams are shipping code faster than ever, but production operations remain heavily manual and concentrated in the hands of a few experienced engineers. The result: slower incident resolution, constant interruptions, and growing operational toil as systems scale. TierZero is the AI platform that helps engineering teams run production systems reliably at scale. Their agents automate incident response, surface reliability risks, and give engineers instant answers to production questions. High-scale teams like Discord, Drata, Framer, and WeightWatchers trust TierZero to accelerate incident resolution and reclaim engineering capacity. At Drata, TierZero reduced issue time-to-resolution by 42% and saved 7000+ engineering hours annually. LangSmith plays a central role in how the team builds agents. Learn more 👉 tierzero.ai Reach out to the team for a free 30-day trial 👉 cal.com/tierzero-az/45min
→ View original post on X — @langchain, 2026-04-02 16:38 UTC