Prediction: This is gonna kill some oss projects. "On the kernel security list we've seen a huge bump of reports. We were between 2 and 3 per week maybe two years ago, then reached probably 10 a week over the last year with the only difference being only AI slop, and now since
CODE
-
Coding Agents Demand Deep Software Engineering Experience
By
–
"Using coding agents well is taking every inch of my 25 years of experience as a software engineer." Simon Willison (
@simonw
) is one of the most prolific independent software engineers and most trusted voices on how AI is changing the craft of building software. He co-created -
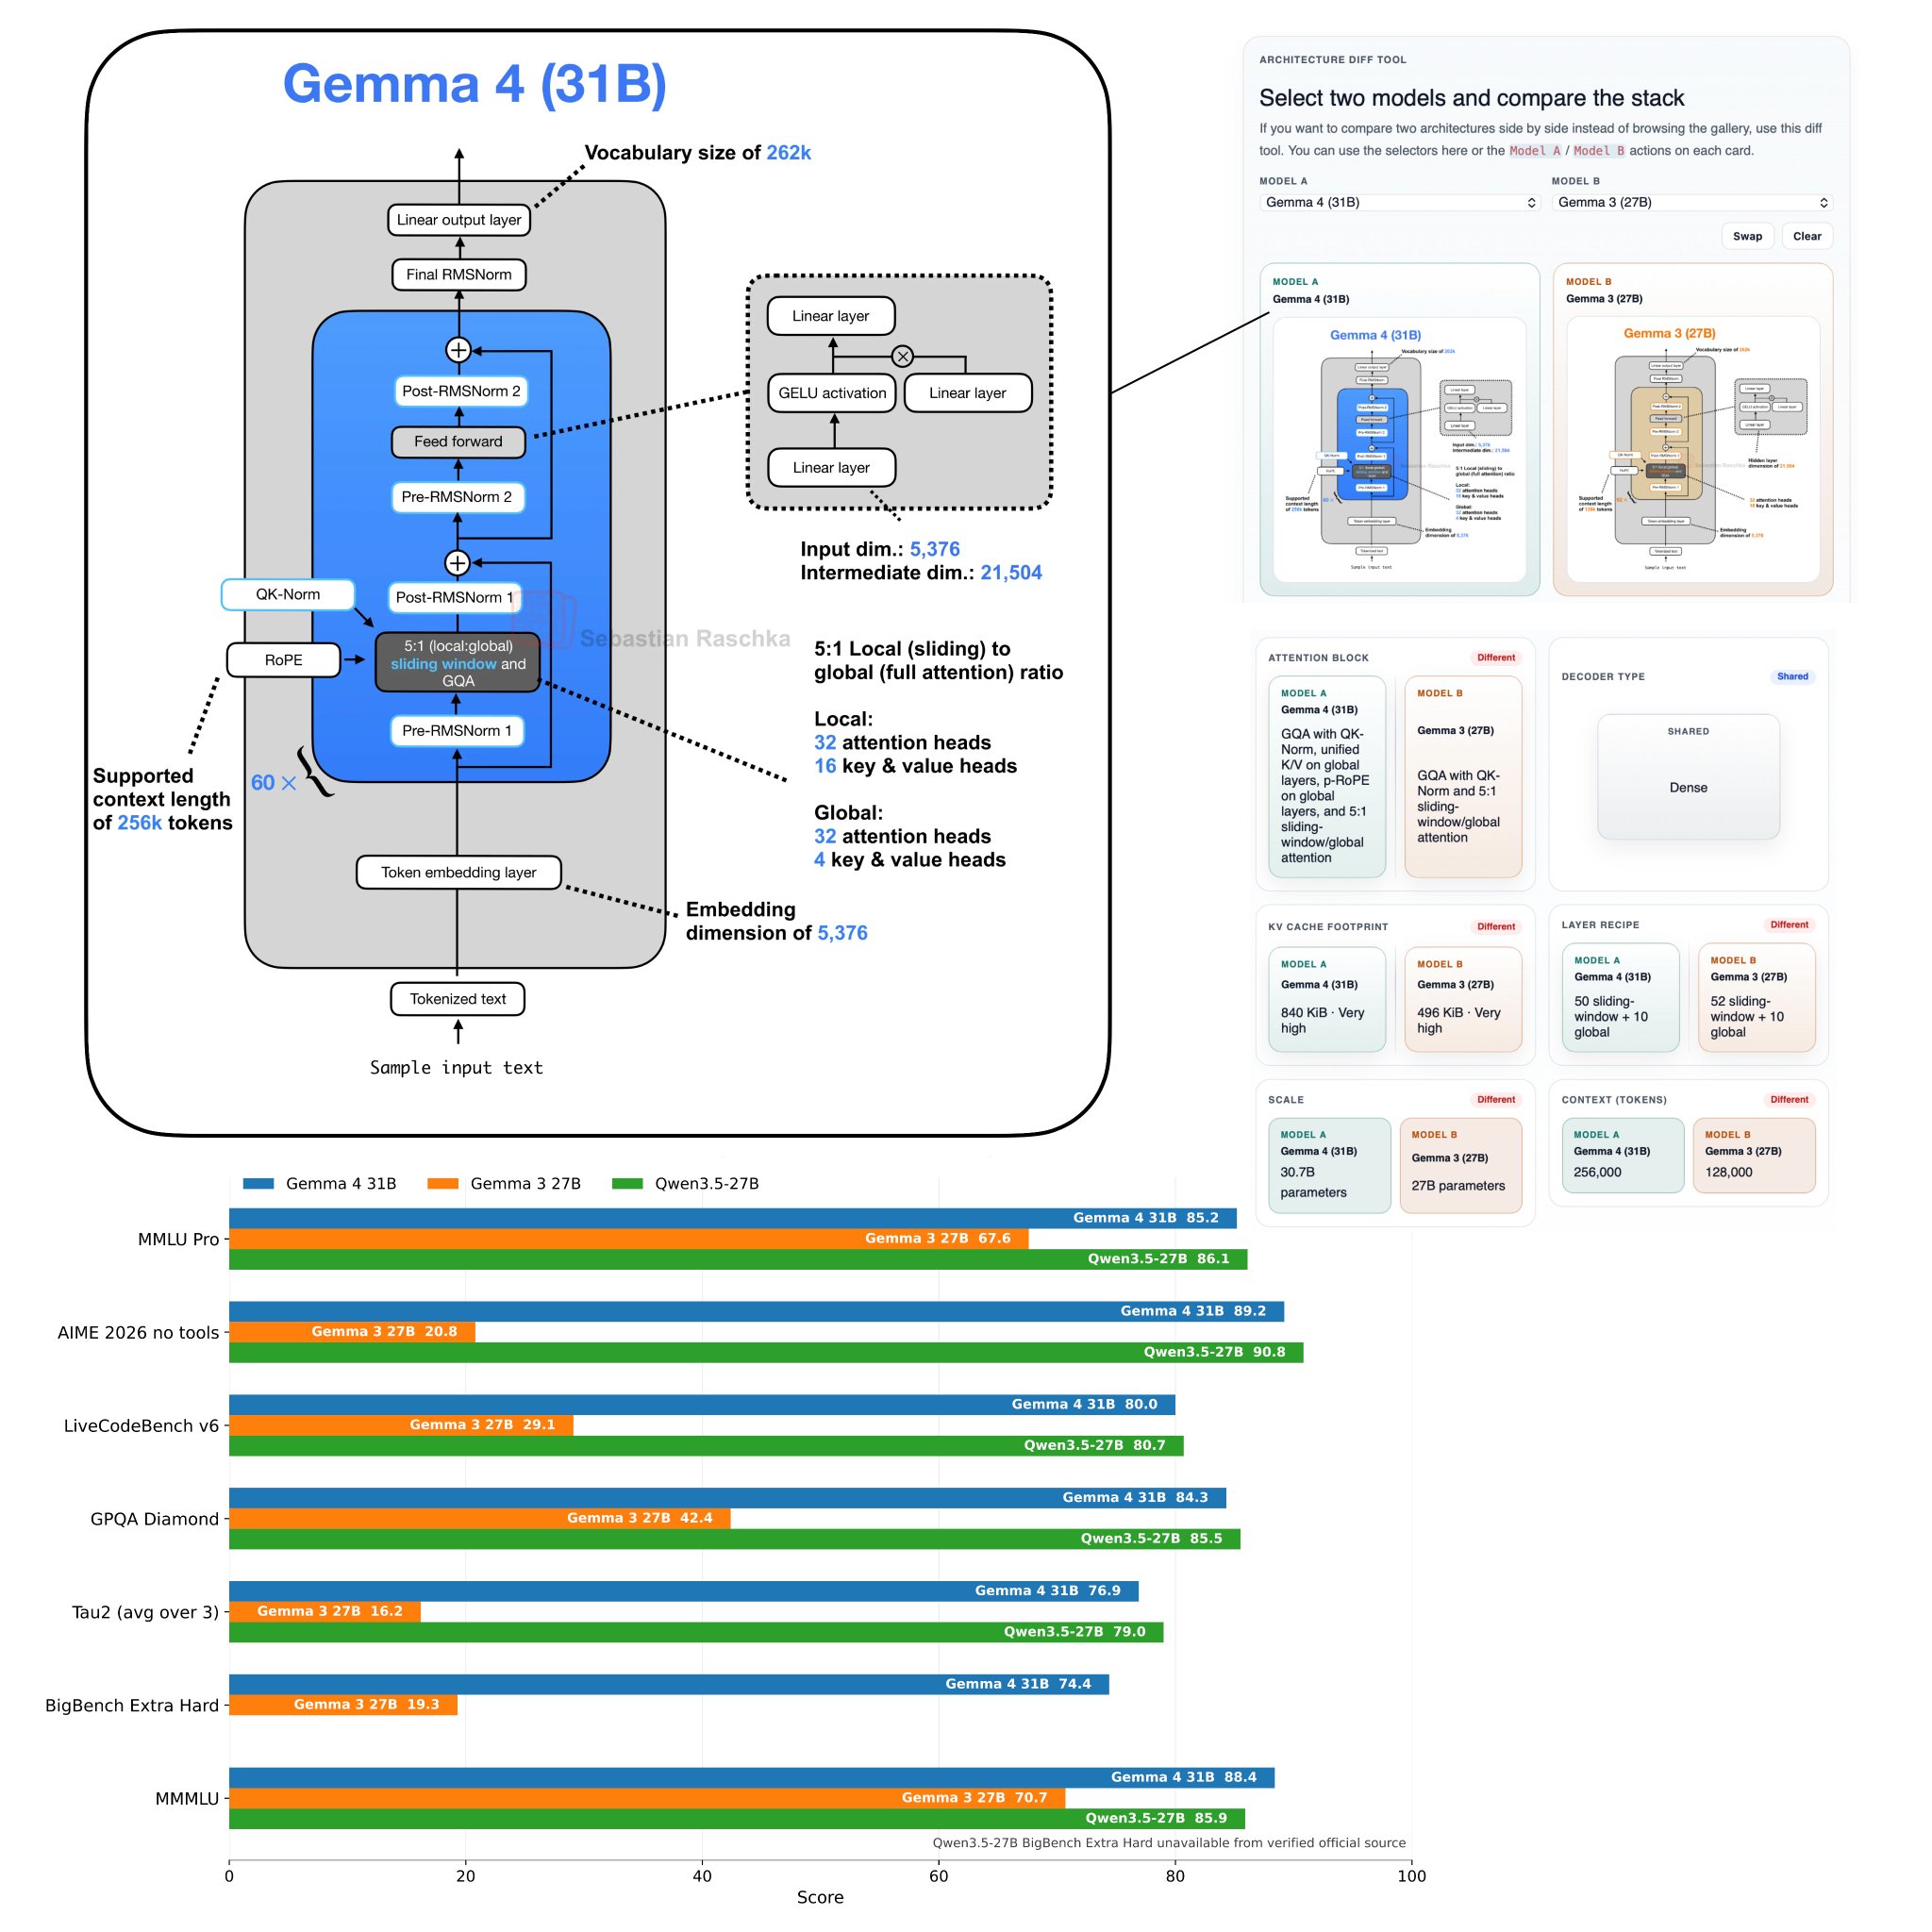
Overall Architecture Overview and Implementation Guide
By
–
Here you go (for the overall architecture):
-
Gemma 4 26B model architecture gallery entry and details
By
–
And the link to the gallery entry for more details, links, comparisons, etc: sebastianraschka.com/llm-arc…
-
Gemma 4 Release: Architecture Stability, Training Innovation, Strong Performance
By
–
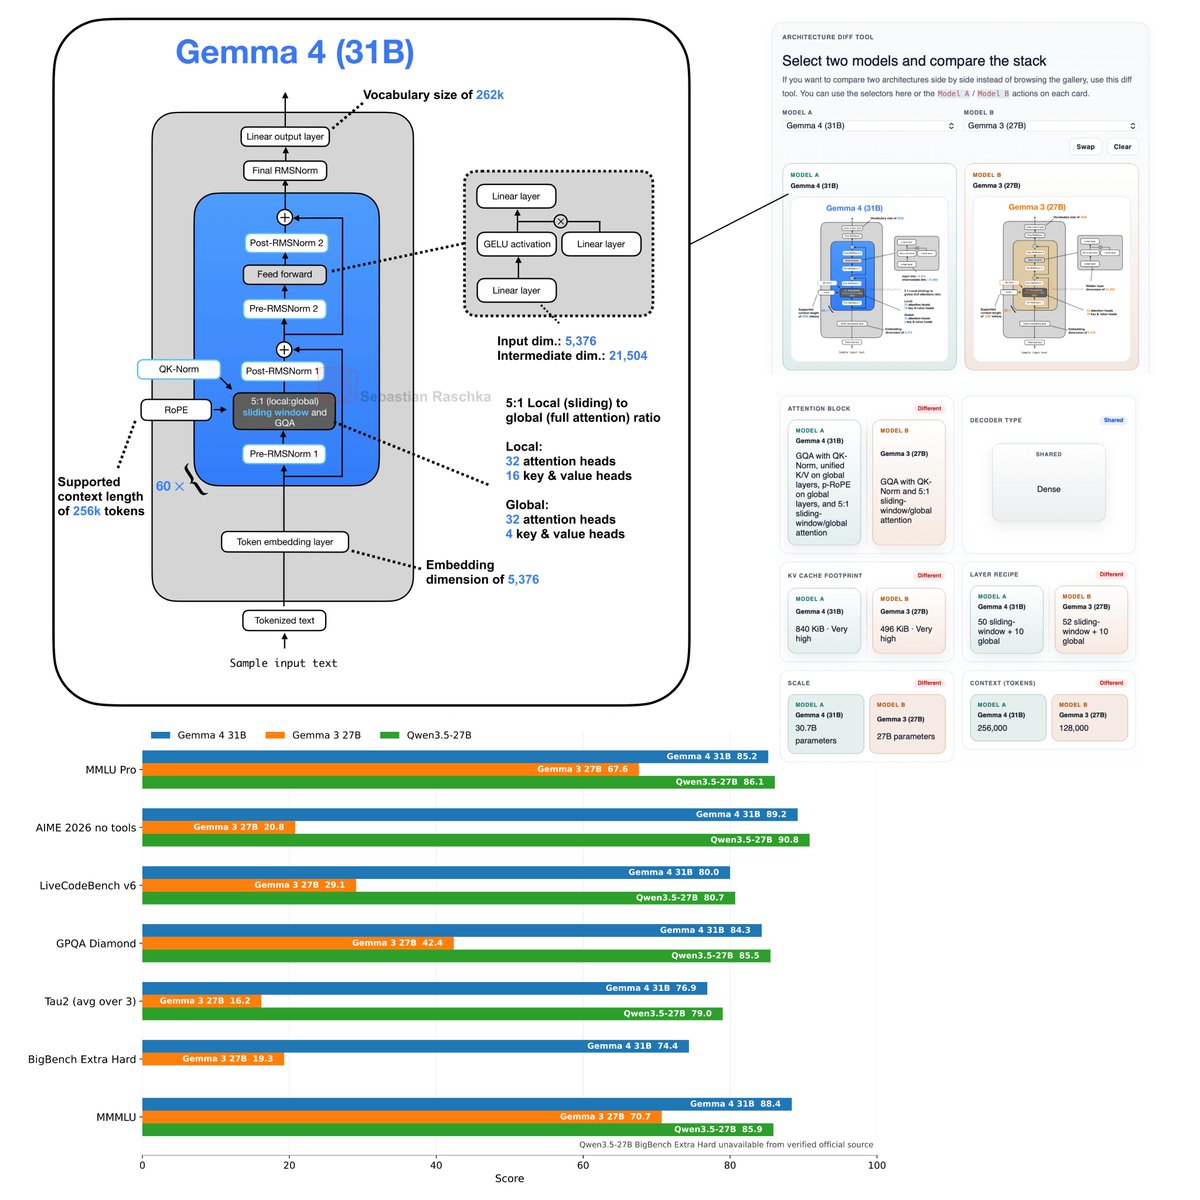
Flagship open-weight release days are always exciting. Was just reading through the Gemma 4 reports, configs, and code, and here are my takeaways: Architecture-wise, besides multi-model support, Gemma 4 (31B) looks pretty much unchanged compared to Gemma 3 (27B). Gemma 4 maintains a relatively unique Pre- and Post-norm setup and remains relatively classic, with a 5:1 hybrid attention mechanism combining a sliding-window (local) layer and a full-attention (global) layer. The attention mechanism itself is also classic Grouped Query Attention (GQA). But let’s not be fooled by the lack of architectural changes. Looking at the benchmarks, Gemma 4 is a huge leap from Gemma 3. This is likely due to the training set and recipe. Interestingly, on the AI Arena Leaderboard, Gemma 4 (31B) ranks similarly to the much larger Qwen3.5-397B-A17B model. But as I discussed in my model evaluation article, arena scores are a bit problematic as they can be gamed and are biased towards human (style) preference. If we look at some other common benchmarks, which I plotted below, we can see that it’s indeed a very clear leap over Gemma 3 and ranks on par with Qwen3.5 27B. Note that there is also a Mixture-of-Experts (MoE) Gemma 4 variant that is slightly smaller (27B with 4 billion parameters active. The benchmarks are only slightly worse compared to Gemma 4 (31B). I omitted the MoE architecture in the figure below because the figure is already very crowded, but you can find it in my LLM Architecture Gallery. Anyways, overall, it's a nice and strong model release and a strong contender for local usage. Also, one aspect that should not be underrated is that (it seems) the model is now released with a standard Apache 2.0 open-source license, which has much friendlier usage terms than the custom Gemma 3 license.
-

Jeremy Howard’s 2016 Paper on Steering Vectors from Synthetic Data
By
–
if it makes you feel better: i also introduced the idea of generating useful steering vectors from contrastive synthetic data in my 2016 paper – a whole section on augmenting inputs with low pass gaussian filter to derive a steering vector that produces less blurry samples. arxiv.org/abs/1609.04468
→ View original post on X — @jeremyphoward, 2026-04-02 18:44 UTC
-
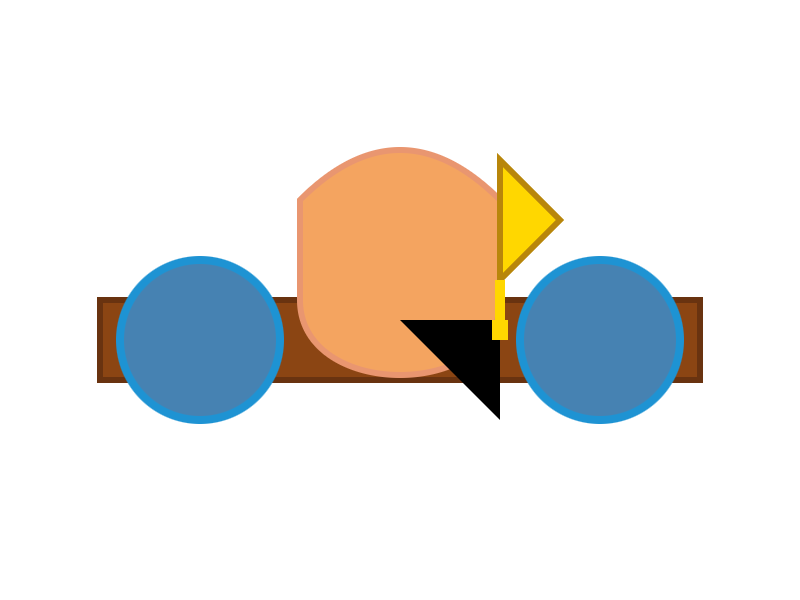
Gemma 4 Models Tested: Pelicans Generated via LM Studio and Gemini API
By
–
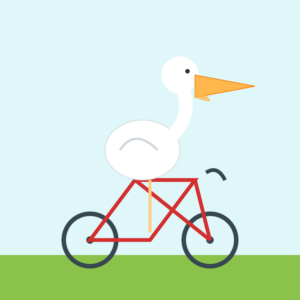
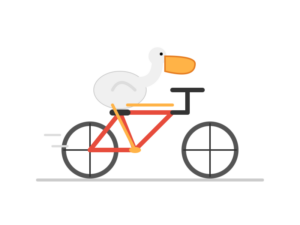
Pelicans for Gemma 4 E2B, E4B, 26B-A4B and 31B – the first three generated on my laptop via LM Studio, the 31B was broken on my laptop so I ran it via the Gemini API instead simonwillison.net/2026/Apr/2…
-
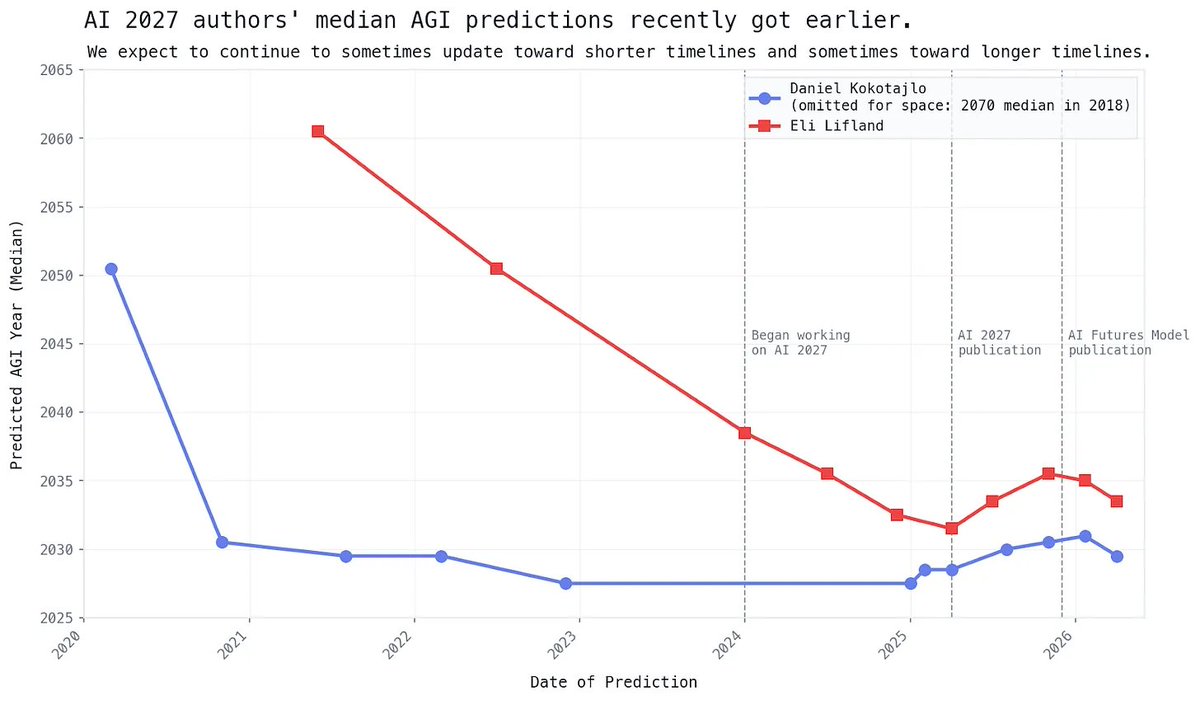
AI Timeline Predictions Shortened by 1.5 Years Due to Agent Progress
By
–
AI timelines update: @DKokotajlo and I have updated our timelines earlier by ~1.5 years over the last 3 months, primarily due to (a) expecting faster time horizon growth, and (b) coding agents impressing in the real world. During 2025, we had updated toward longer timelines.
→ View original post on X — @paulroetzer, 2026-04-02 18:34 UTC
-

Staying in Control During EDA with Coding Agents
By
–
How to stay in control when doing EDA with coding agents buff.ly/aZsp0Or #AI #MachineLearning #DeepLearning #LLMs #DataScience
→ View original post on X — @miketamir, 2026-04-02 18:33 UTC
-
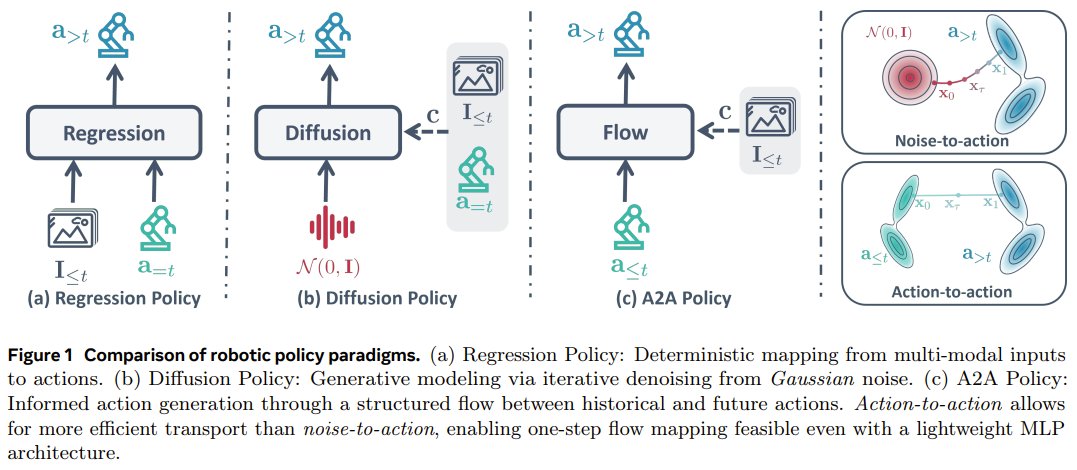
Action-to-Action Flow Matching: Ultra-Fast Robot Control Method
By
–
What if real-time robot control didn't have to wait for slow, iterative action generation? MARS Lab at Nanyang Technological University (Jindou Jia et al.) introduces Action-to-Action Flow Matching (A2A). This novel method uses a robot's own historical actions to directly predict the next move, skipping the slow, random noise sampling of traditional diffusion models. A2A enables lightning-fast, single-step action generation (0.56 ms!), vastly outperforming existing methods in speed, training efficiency, robustness to visual noise, and generalization to unseen configurations. It even shows versatility in video generation! Action-to-Action Flow Matching Website: lorenzo-0-0.github.io/A2A_Fl… arXiv: arxiv.org/pdf/2602.07322 Code: github.com/JIAjindou/A2A_Flo… Our report: mp.weixin.qq.com/s/mrSUcVLUA… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-02 18:30 UTC