Every enterprise will have its own model-harness-sandbox-eval flywheel with token value per watt optimization. This is the future. Simple reason: tacit knowledge about the domain and customers and their workflows that the company uniquely understands and has built trust around.
SOFTWARE
-
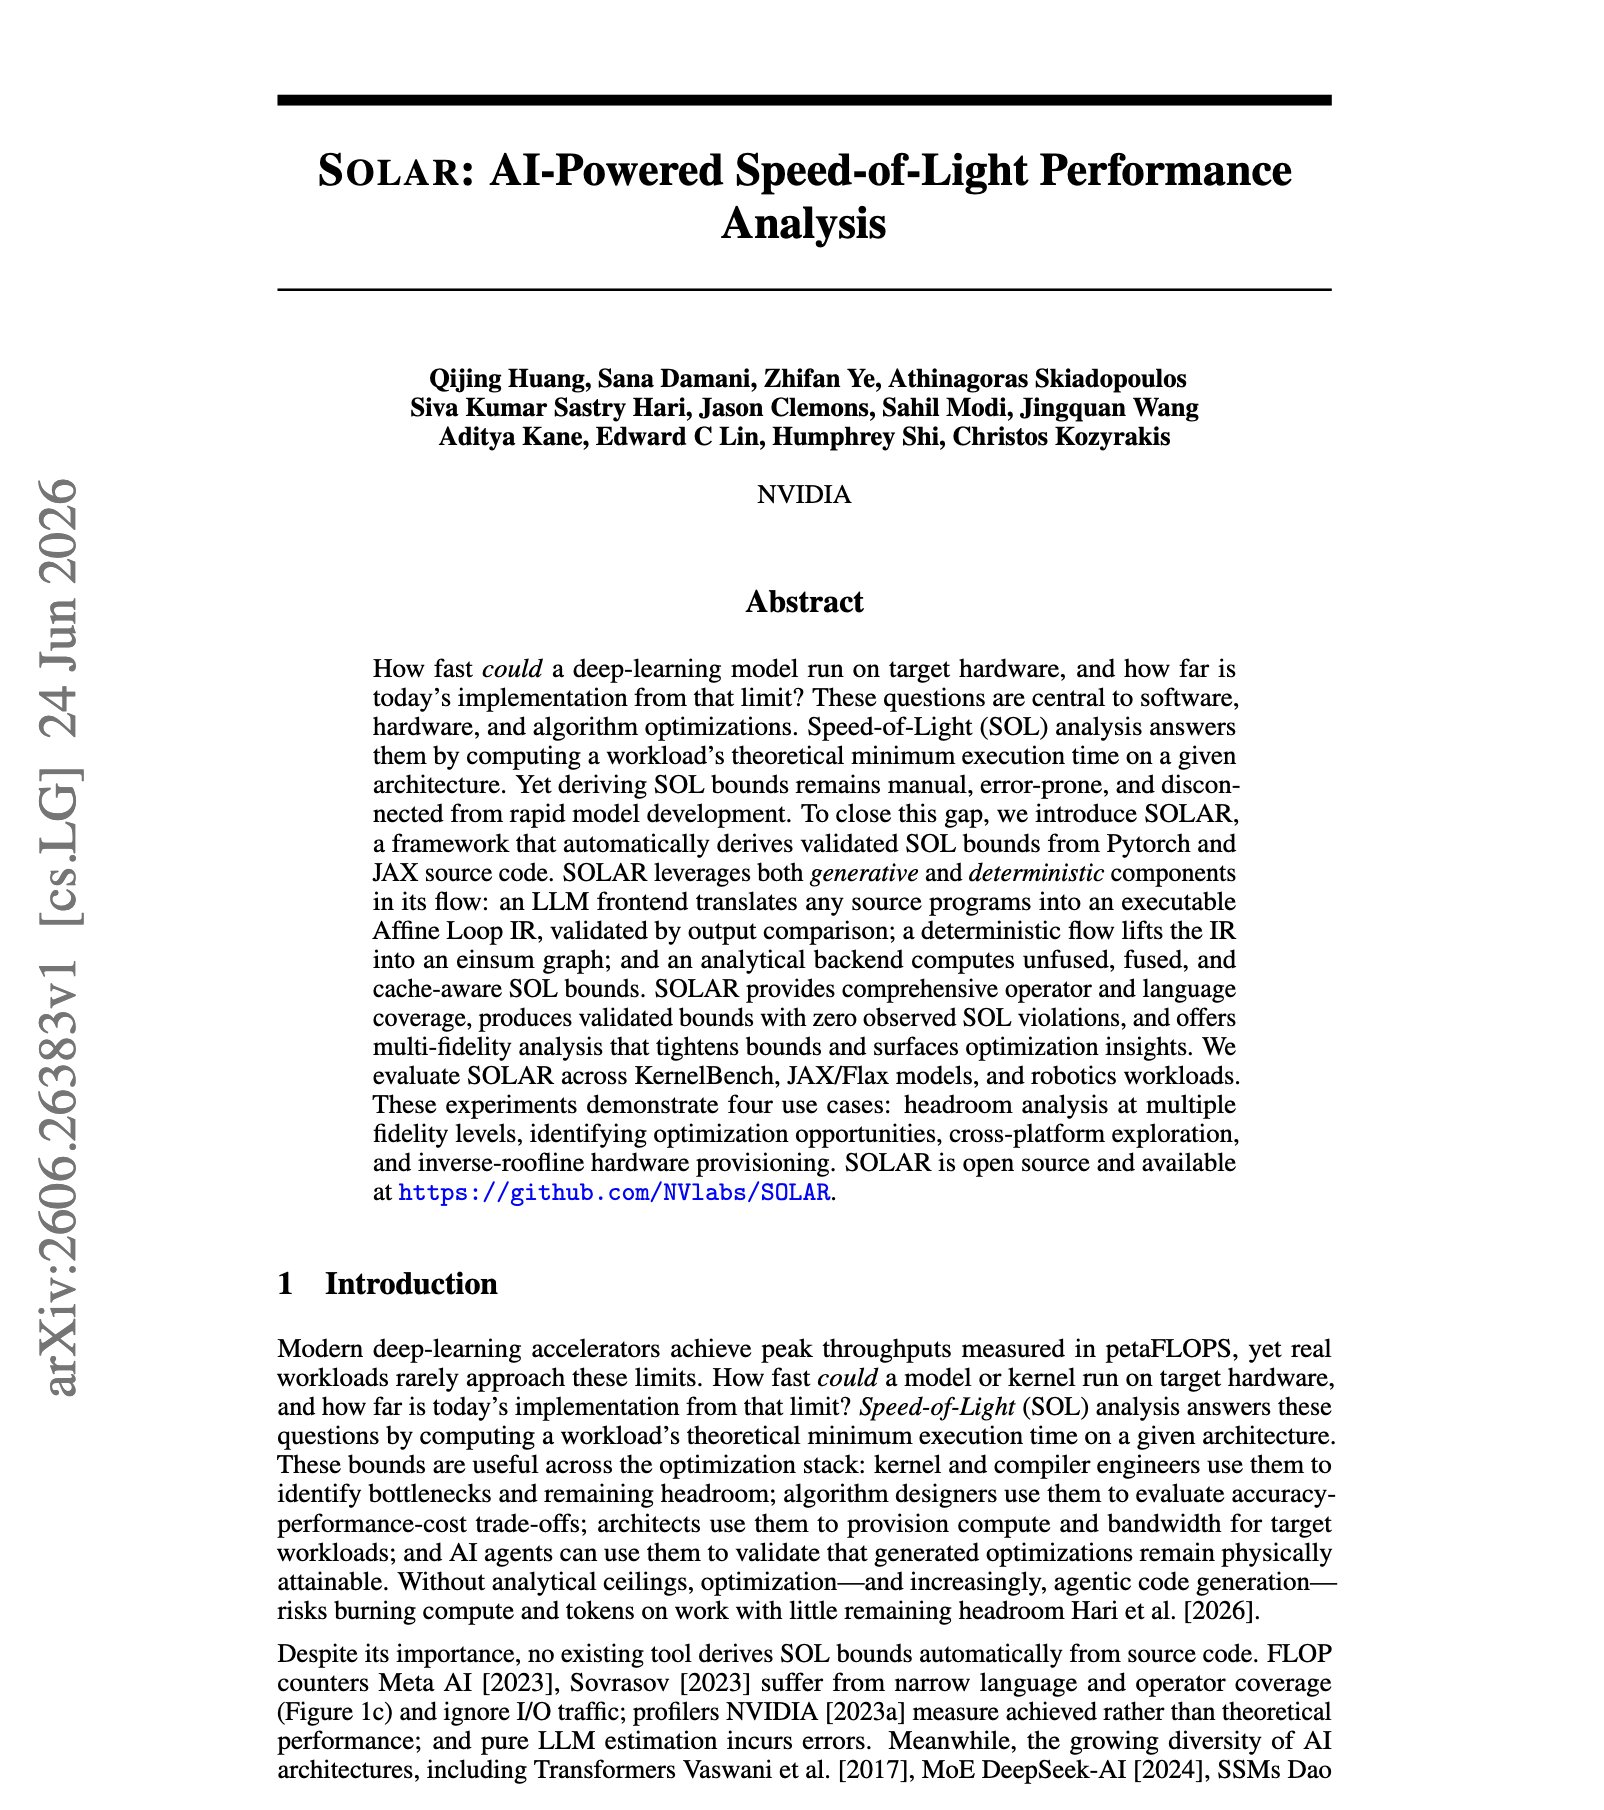
NVIDIA SOLAR automates speed-of-light performance analysis from PyTorch/JAX
By
–
NEW paper from NVIDIA. (bookmark it) Speed-of-light performance analysis tells you the theoretical floor of a workload, but teams still derive it by hand and freeze it. SOLAR automates the whole thing straight from PyTorch or JAX source. An LLM frontend translates arbitrary
-
Open source harness advances depend on model intelligence from few firms
By
–
Lots of advances coming from the open source harness movement (including Moltbook, RAG approaches back in the day, etc.) but they depend on the intelligence of the models created by a small handful of companies & the more intelligent those models, the more others can do with them
-
Voice-controlled transforms and blocking out with Unreal MCP
By
–
What if you used the new unreal MCP so a lot of the transforms and blocking out even is doing via voice and you can just tweak it
-
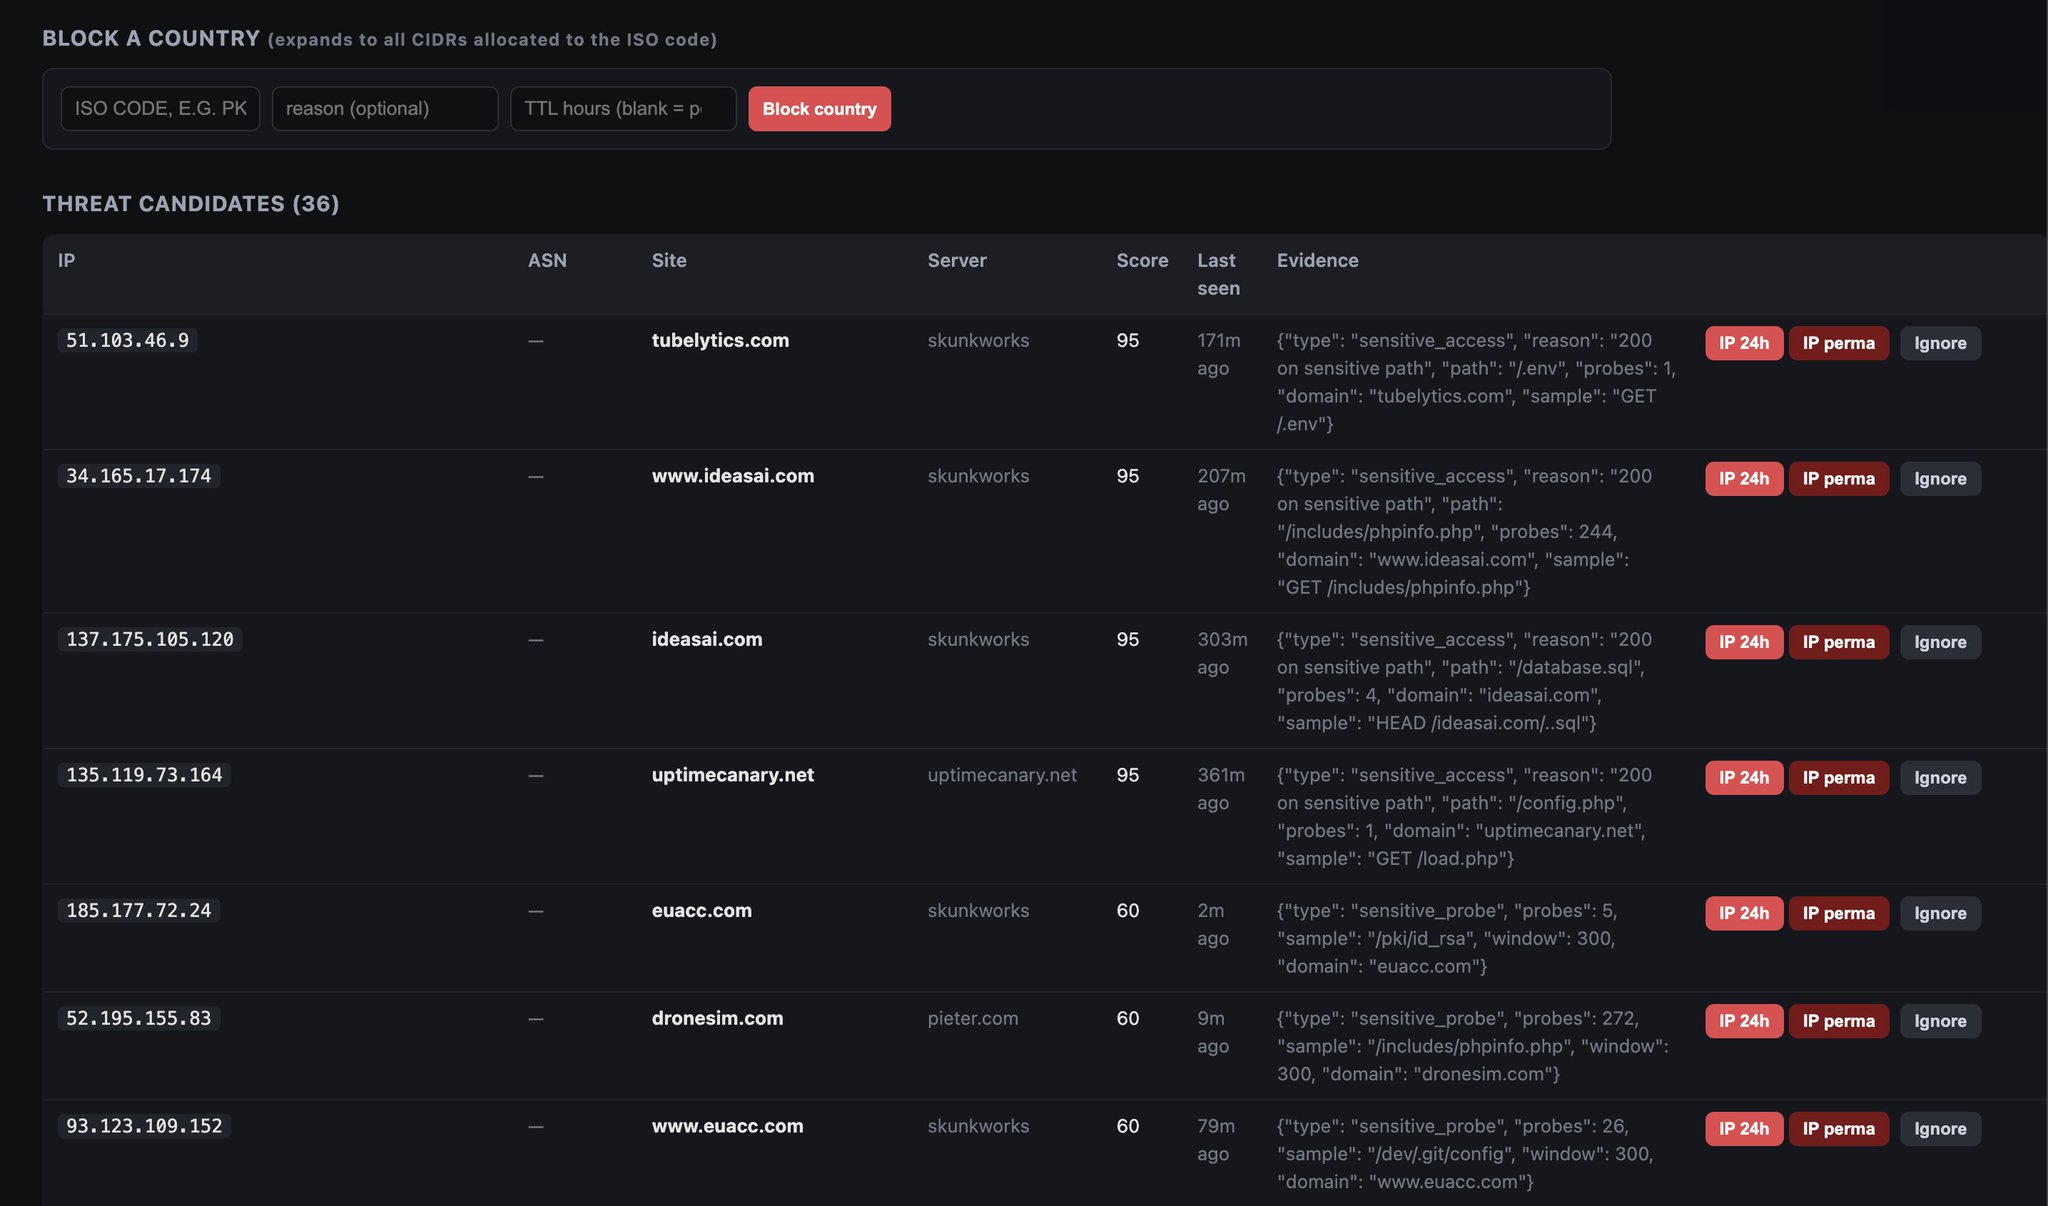
Pietflare: A DDOS and probe detector with AI central block list
By
–
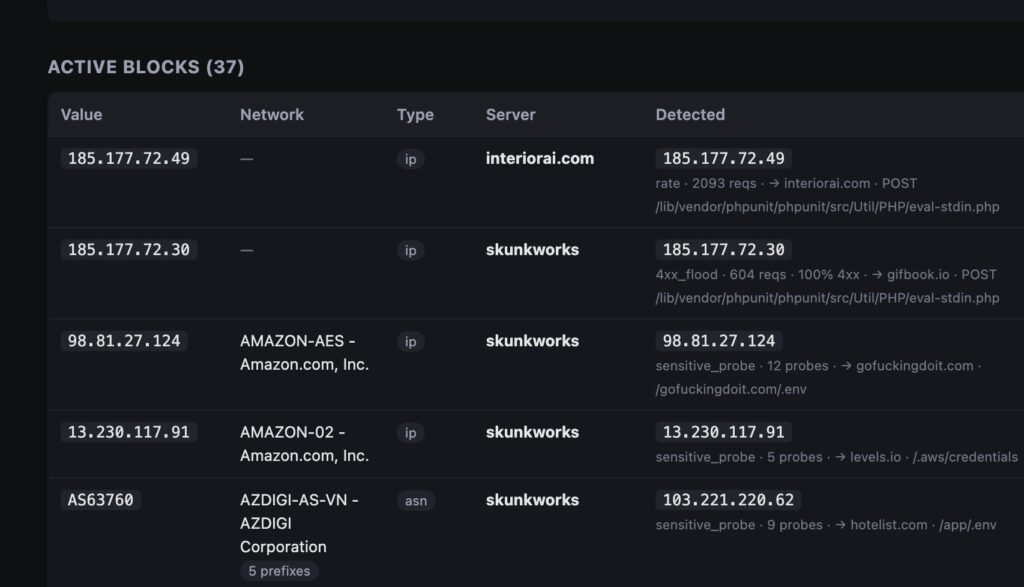
I made my own little Cloudflare called Pietflare, it's a DDOS and probe detector with AI and with a central IP / ASN / country block list Each server (VPS) sends suspicious probes, or DDOS attempts etc, from the access logs to the central admin and each server pulls a central
-
LMCache offloads KV cache to CPU, disk, or S3 instead of evicting
By
–
Compression is one way to fight the KV cache wall. The other is to not throw the KV away. LMCache reuses and offloads it to CPU, disk, or S3 instead of evicting. Already plugs into vLLM, SGLang, and NVIDIA Dynamo. Worth a star if you serve LLMs.
-
Change the base model of an LLM in one line
By
–
With any serious LLM library, it takes one line to change the core model.
-
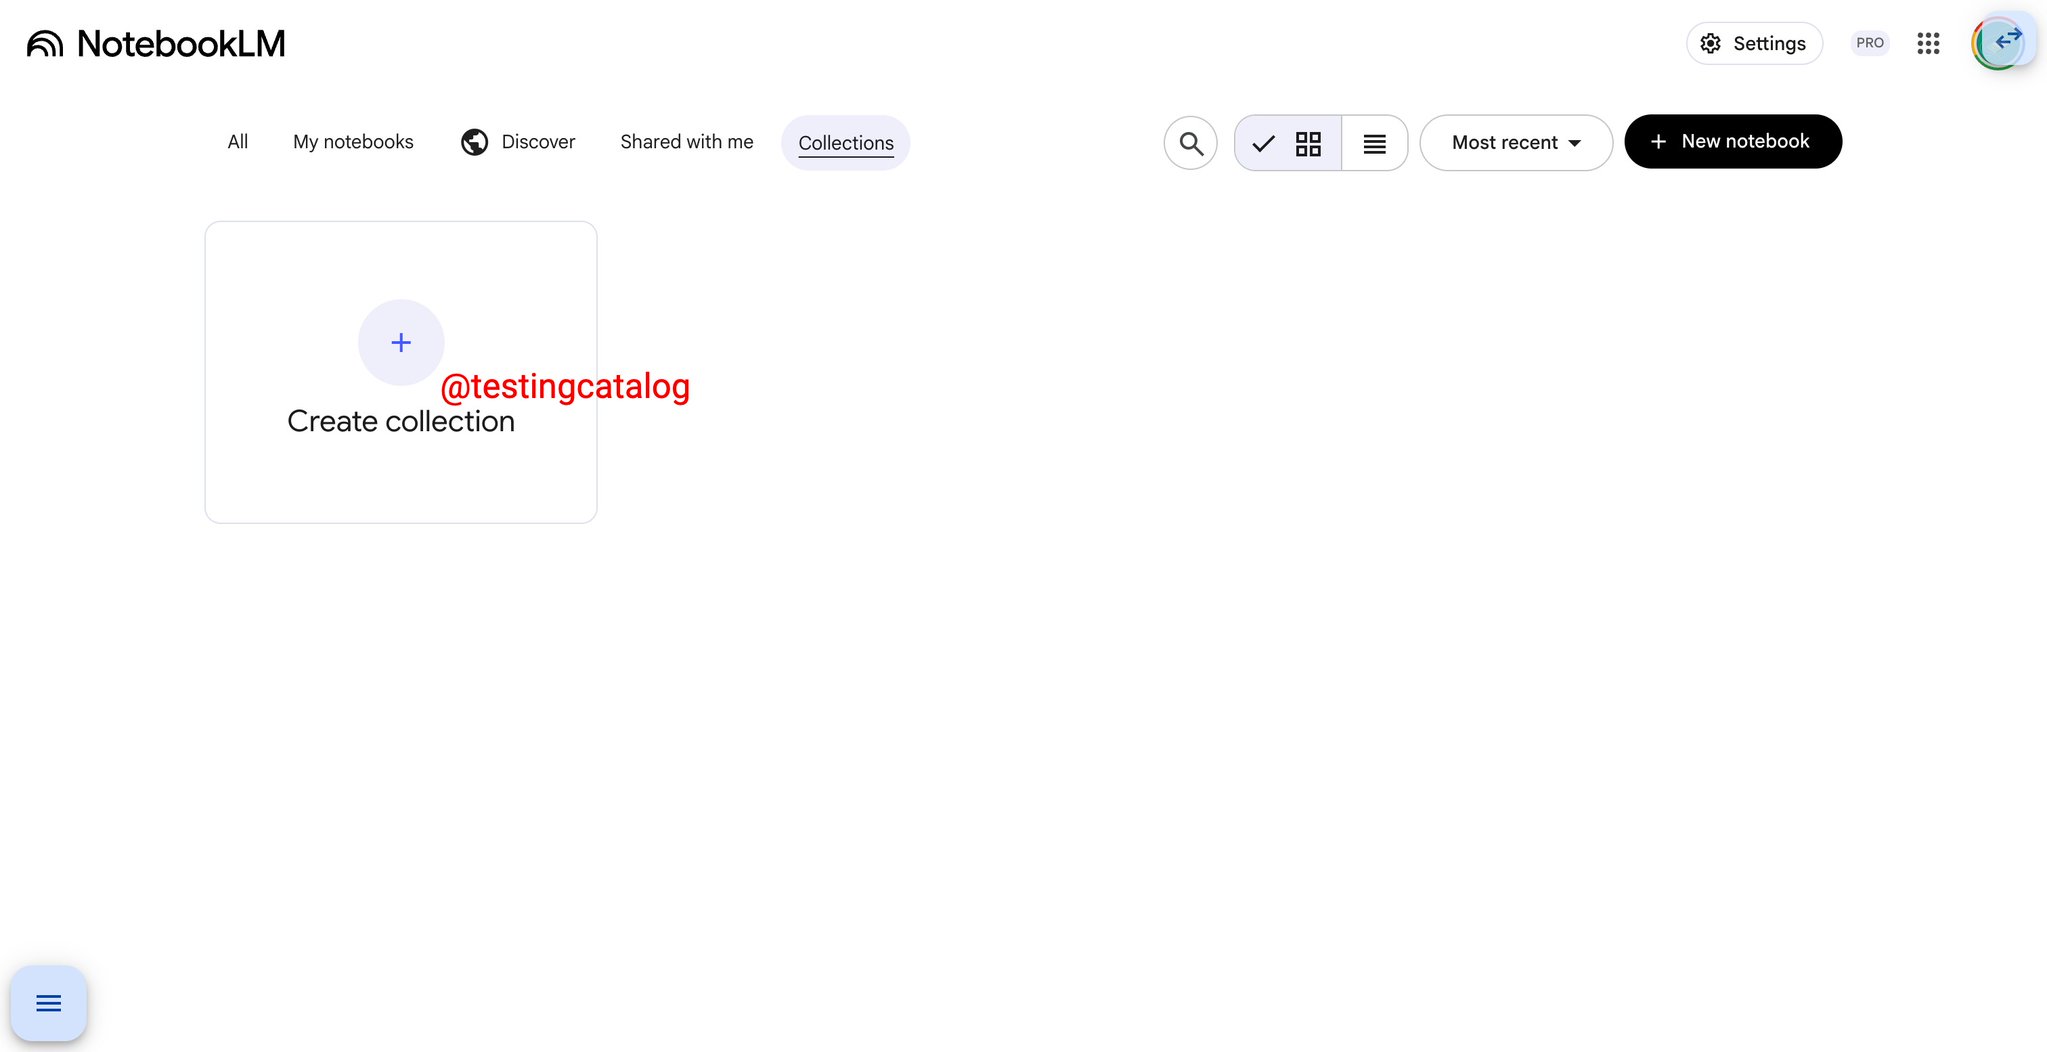
Google adds Collections support to NotebookLM for grouping notebooks
By
–
Google is working on Collections support for NotebookLM. > Users will be able to group multiple notebooks into a single collection.
> Collections will appear in a separate tab in the NotebookLM main menu. Since Notebooks now also function as "projects" in Gemini, this may -
@reach_vb — 2026-06-27
By
–
True story: I stopped thinking about context since GPT 5.3 Codex Single project focused threads with the recent capability of codex to spinoff new threads is goated! Codex continues and goes through compaction but remembers all the important stuff and if not, it’ll look up