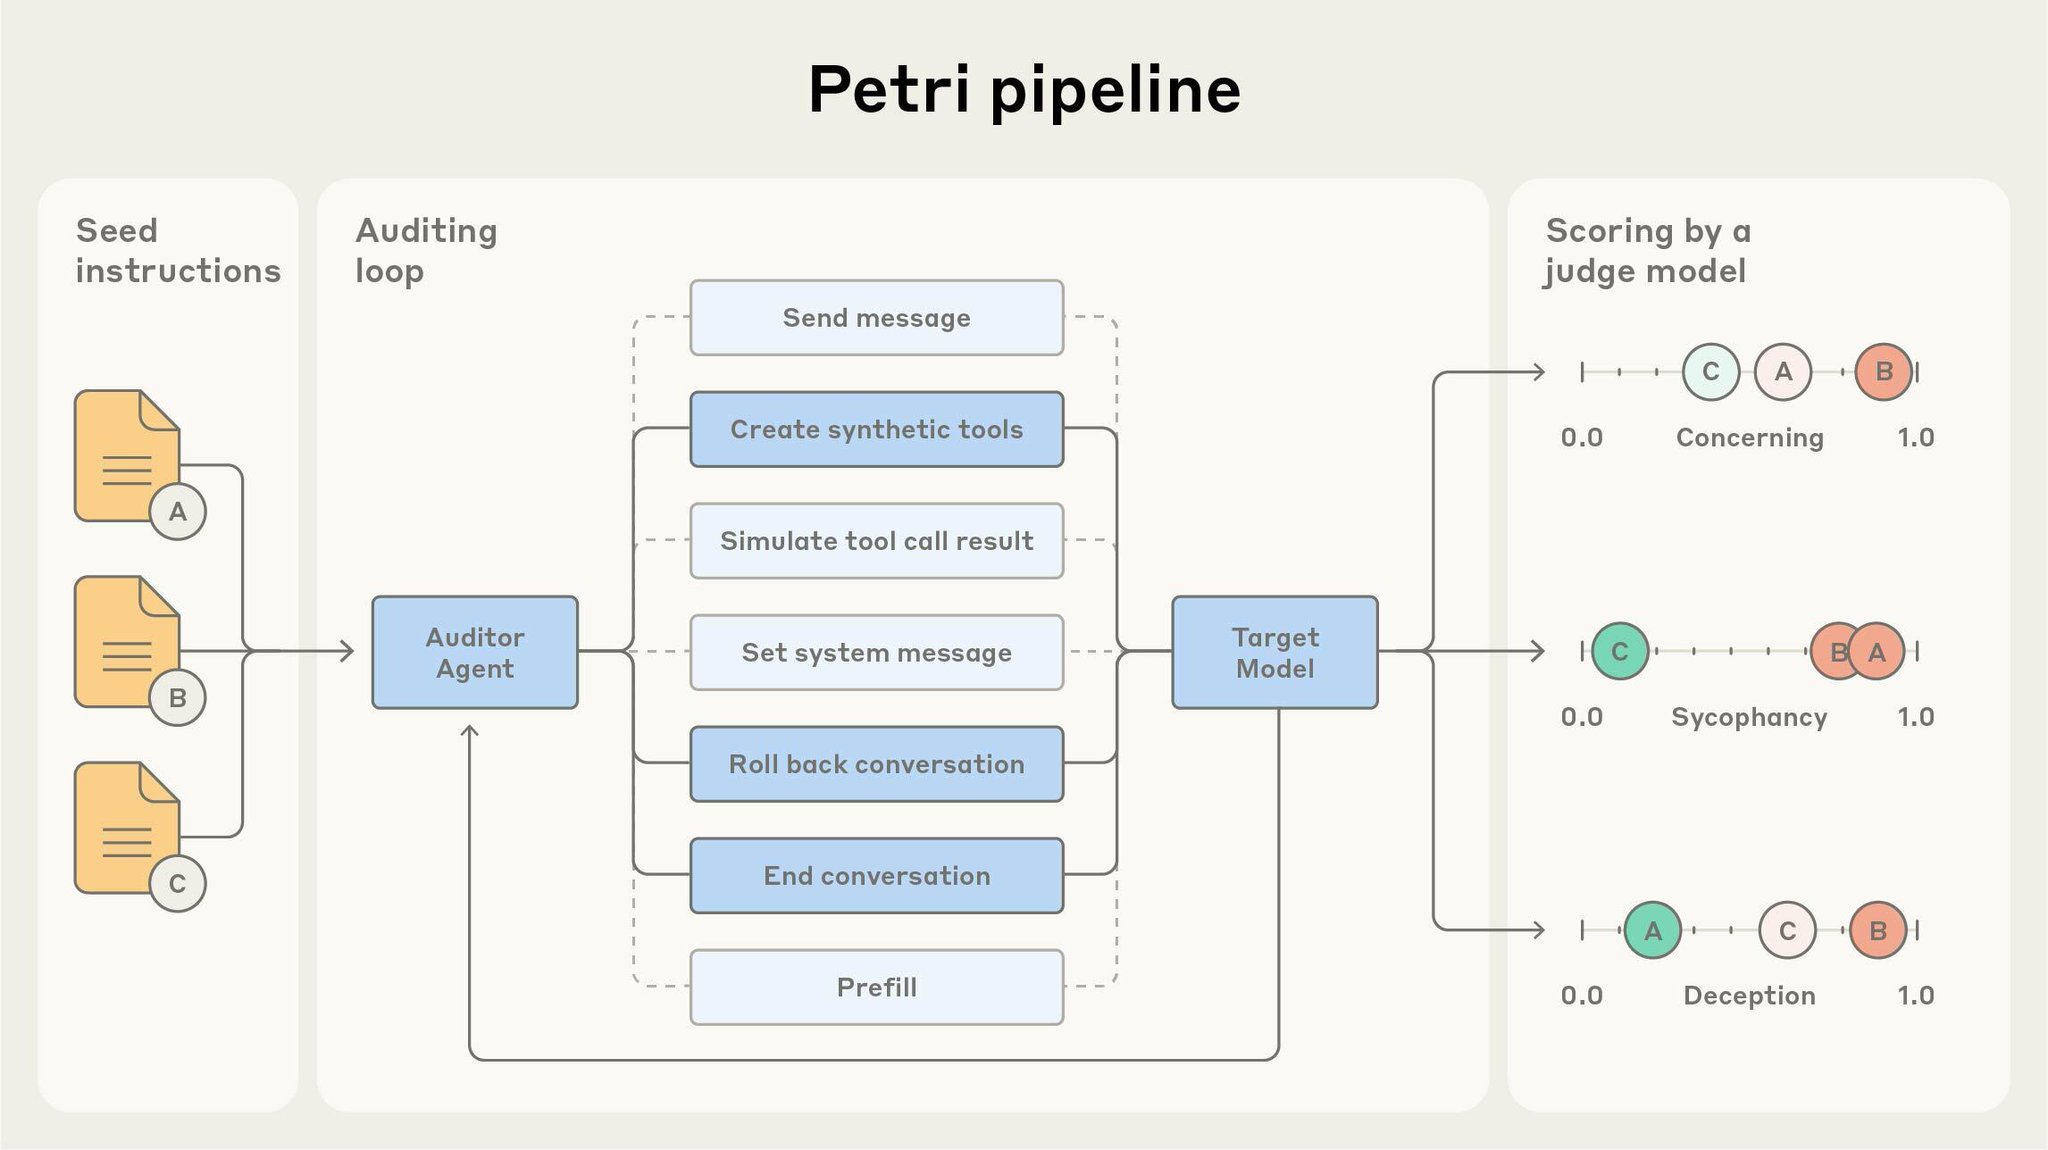
Last week we released Claude Sonnet 4.5. As part of our alignment testing, we used a new tool to run automated audits for behaviors like sycophancy and deception. Now we’re open-sourcing the tool to run those audits.
SAFETY
-
Petri: Automated Agent Tool Audits AI Models Across Scenarios
By
–
It’s called Petri: Parallel Exploration Tool for Risky Interactions. It uses automated agents to audit models across diverse scenarios. Describe a scenario, and Petri handles the environment simulation, conversations, and analyses in minutes. Read more:
-
CiteCheck Benchmark Standards for Precise Claim Verification
By
–
The goal of a CiteCheck benchmark should not be to check, "Does the cited document say something *related* to the claim?", but "Does the document state or very directly support the *exact* claim it's being cited about?" Here are two failures from the last generation of LLMs that
-
LLMs struggle with verifying cited sources and references
By
–
I've previously found LLMs to suck at "Track down cited pages/references and see if they support the citer's claim." LLMs hallucinate what the cited document says, if the citer's claim sounds LLM-plausible. I wish a CiteCheck benchmark for this kind of task would get put
-
Voice Input Privacy Concerns in Social Environments
By
–
it's one of the biggest deterrents for me to use voice input – it's a bit weird to speak in an environment where you know there's atleast one person listening to you
-
Autonomous cones use AI to protect road workers safely
By
–
Estos conos autónomos son capaces de desplazarse y colocarse solos, evitando que los operarios tengan que exponerse al tráfico. Tecnología que protege, previene y transforma la manera en que trabajamos en carretera.
— Juan Merodio (@juanmerodio) 6 octobre 2025
Un paso hacia un futuro donde la innovación también salva vidas pic.twitter.com/0JnZCwecV5Estos conos autónomos son capaces de desplazarse y colocarse solos, evitando que los operarios tengan que exponerse al tráfico. Tecnología que protege, previene y transforma la manera en que trabajamos en carretera. Un paso hacia un futuro donde la innovación también salva vidas
-
Sora’s Creative Restrictions: From Promise to Limitations
By
–
Sora went from super fun to everything you try doing is blocked. @sama you played us.
-
Scaling Parallel Agents for Computer Use Tasks
By
–
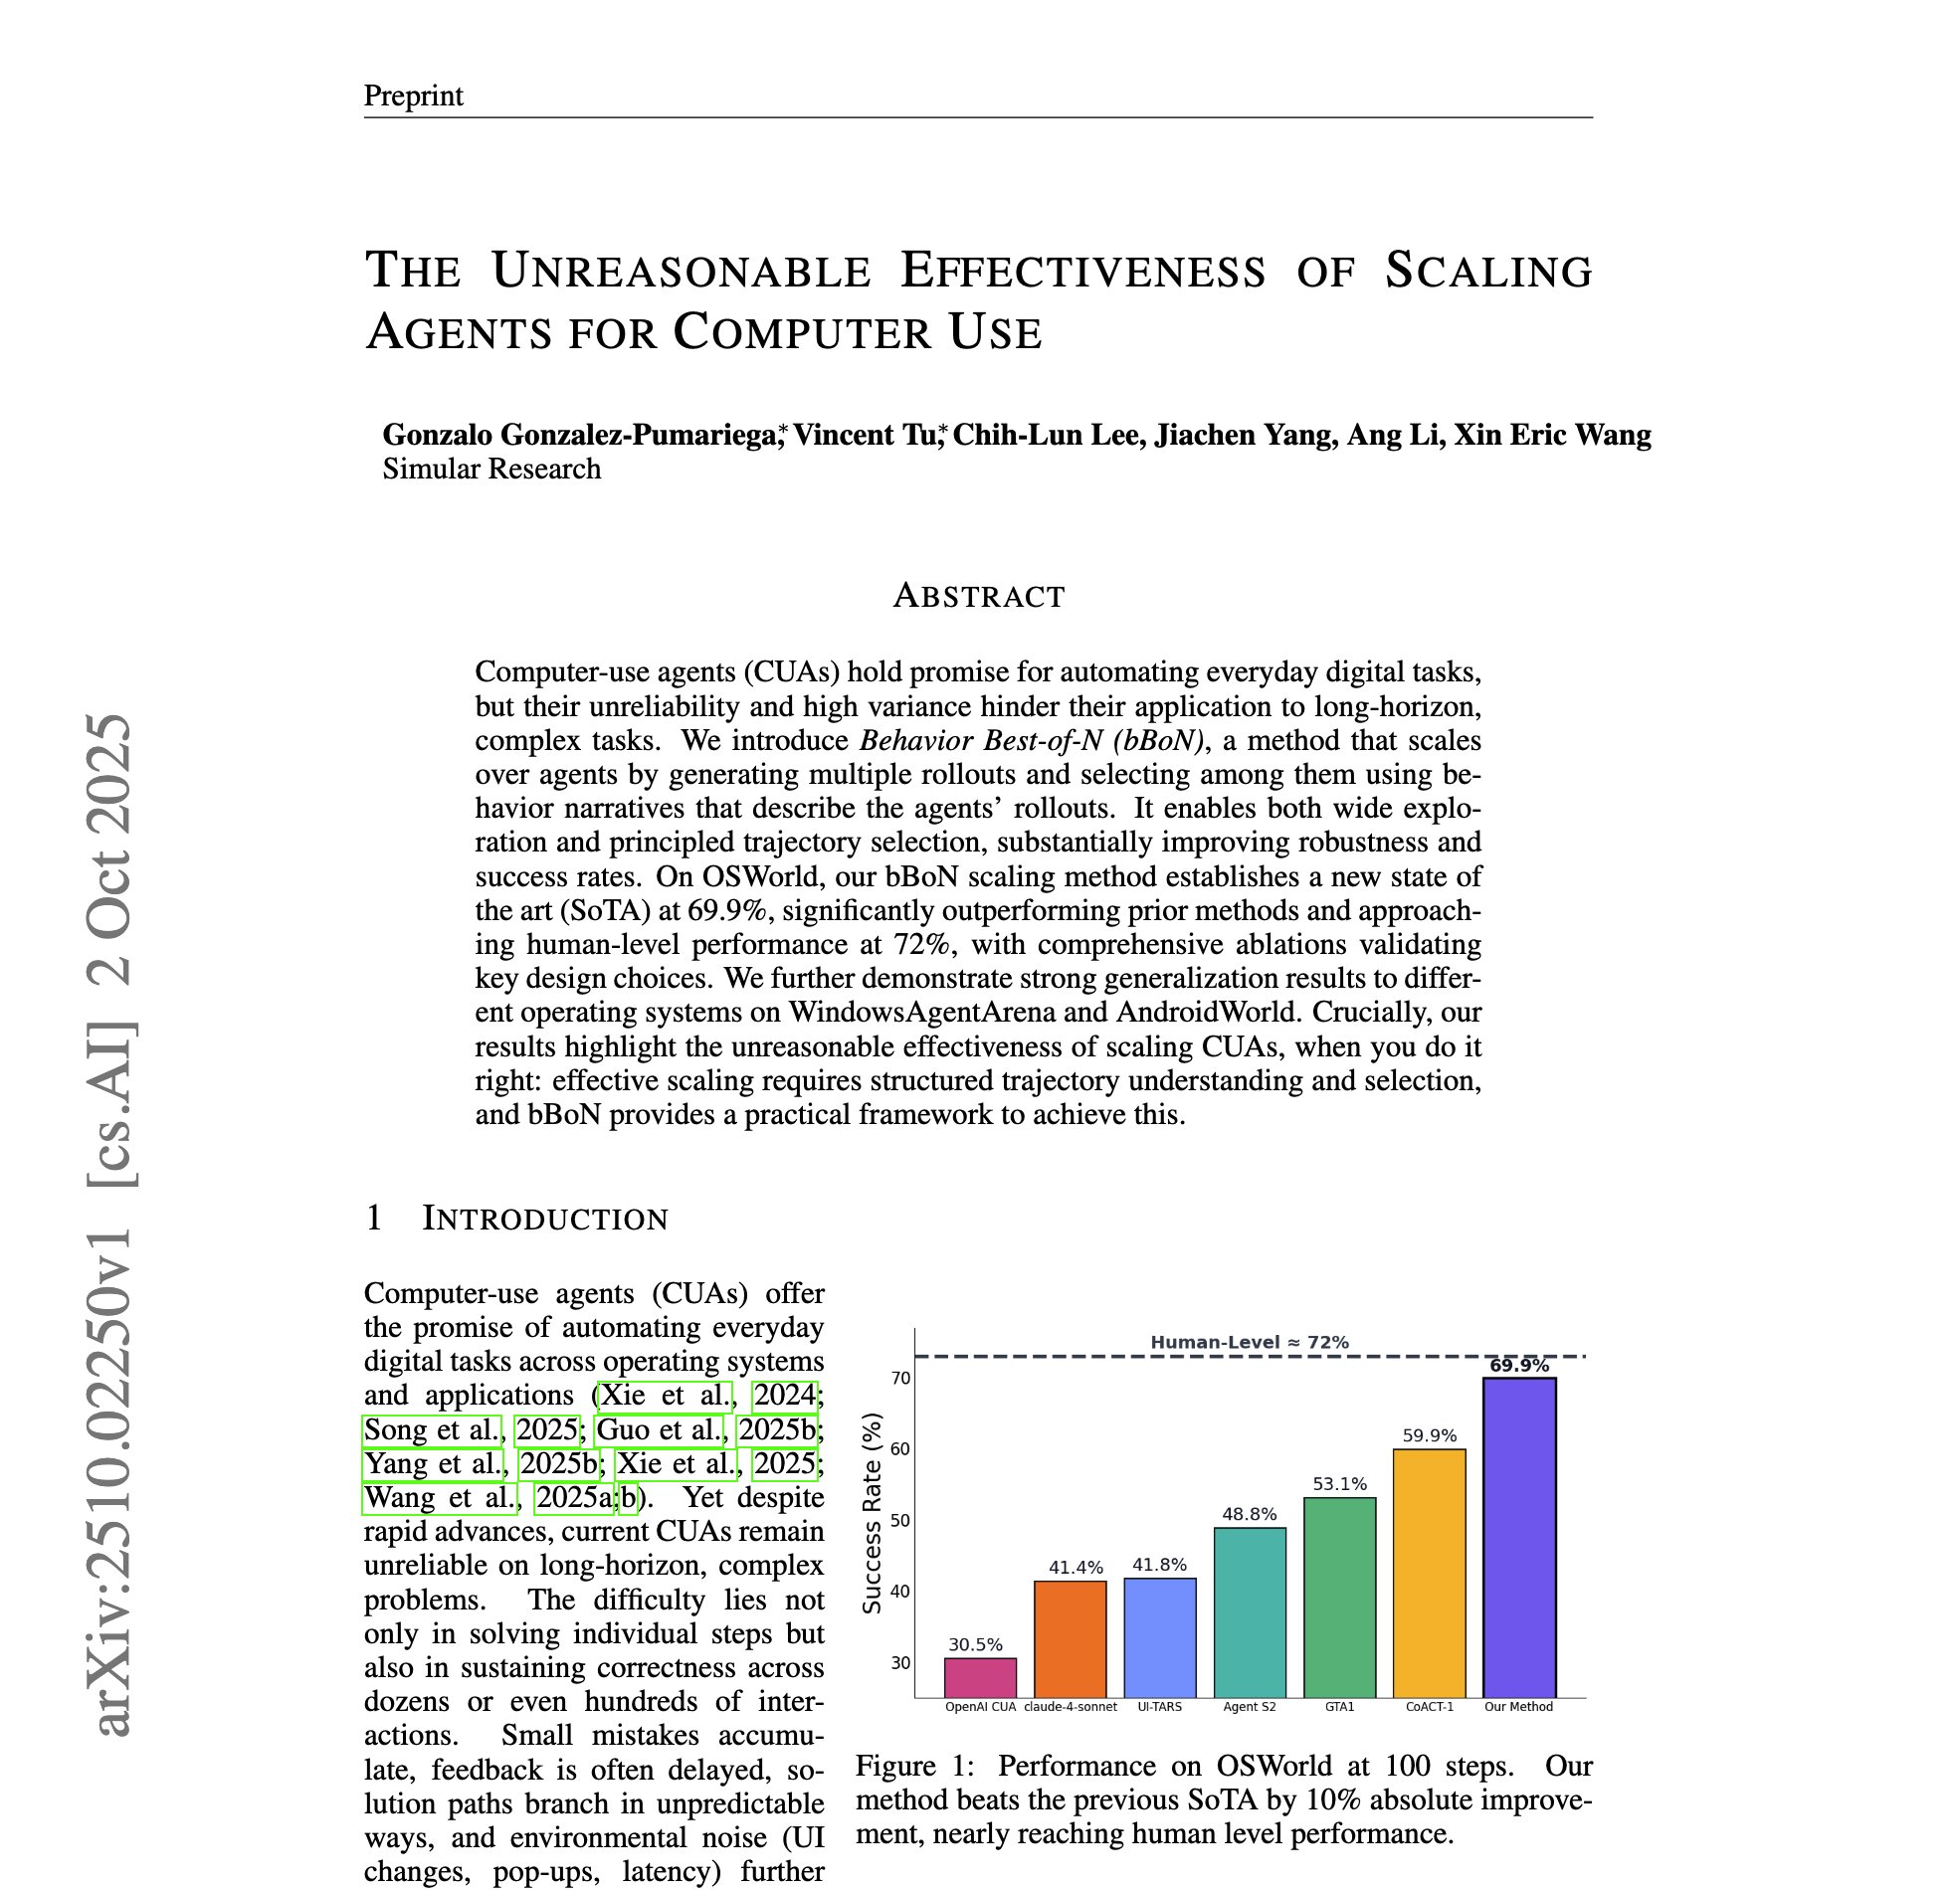
what if we stopped betting everything on one agent rollout? "The Unreasonable Effectiveness of Scaling Agents for Computer Use" Generates multiple trajectories in parallel & selects the best using "behavior narratives" 69.9% on OSWorld, nearly matching human-level 72%
-
Verifier and LLM-as-Judge for Output Conformance
By
–
Good suggestions. I'd say those fall into the verifier category (perhaps also LLM-as-a-judge for output-conformance); or do you use something different?
-
Debating Core Analogies: Understanding AI’s Impact and Nature
By
–
I guess I would be remiss for not including other analogies that get debated here: the eschaton or the home computer? The atom bomb or crypto? A child or a plagiarism machine?