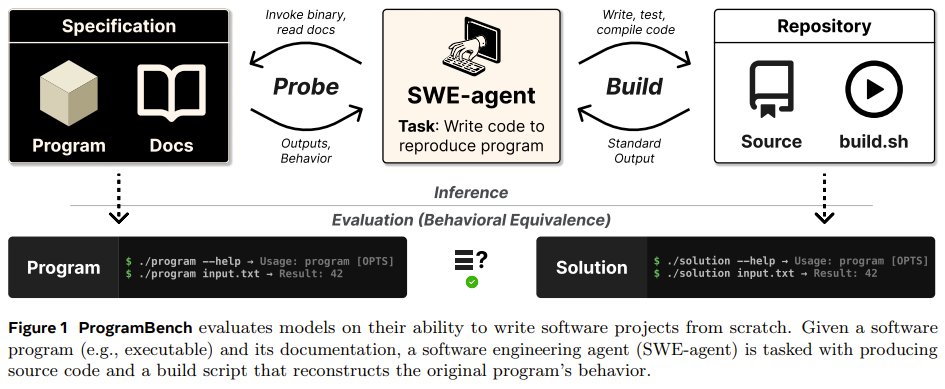
Can AI build an entire software project from scratch, not just fix one bug? Researchers at Meta FAIR, Stanford, and Harvard introduce ProgramBench. This benchmark tests if language-model agents can take a program’s documentation and build a full codebase that behaves
RESEARCH
-

Long-Horizon Reasoning in LLMs: An alphaXiv AI4Science Talk
By
–
If models can think for 100,000 tokens, why do they still lose the plot? Come join us for this AI4Science on alphaXiv talk: Long-Horizon Reasoning in LLMs. In this session, Sumeet Motwani (
@sumeetrm
) and Charles London (
@CharlieLondon02
) will share recent work on both training -

How Agentic LLMs Are Transforming Scientific Research and Mentorship
By
–
Why LLMs Aren't Scientists Yet? In our latest AI4Science talk, Prof. Dhruv Kumar (
@gargdhruv36
) and Dhruv Trehan (
@dhruvtrehan9
) from @lossfunk discussed how agentic LLM systems can support science in a whole new way, from generating research ideas to mentoring young researchers -
OpenAI GPT-5.6 close, question about Anthropic Sonnet 4.8
By
–
Seriously, OpenAI is on a run. GPT-5.6 very close. Where is even sonnet 4.8 @AnthropicAI ?
-
Debating the definition of world models in AI systems
By
–
I do not think there is a useful defensible definition of “no world model” which survives a model being able to position a character in three space then depict that character in a mirror in the same three space. Many people, who unquestionably have world models, would struggle.
-

CausalCine: Real-Time Autoregressive Generation for Multi-Shot Video Narratives
By
–
CausalCine Real-Time Autoregressive Generation for Multi-Shot Narratives
-

AI for Organizations Grand Challenge Explores Future of Work
By
–
200+ academic teams from 156 universities just competed to answer one question: How will AI actually change the way we work together? @StanfordHAI and @GoogleDeepMind announce winners of the AI for Organizations Grand Challenge: https://
hai.stanford.edu/news/researche
rs-worldwide-compete-to-shape-the-future-of-ai-in-organizations
… -

Agentic Discovery for Test-Time Scaling of LLMs
By
–
LLMs Improving LLMs: Agentic Discovery for Test-Time Scaling Zheng et al.: https://
arxiv.org/abs/2605.08083 #ArtificialIntelligence #DeepLearning #AIAgents -

LLMs Improving LLMs: New Research on Agentic Discovery and Scaling
By
–
LLMs Improving LLMs: Agentic Discovery for Test-Time Scaling Zheng et al.: https://
arxiv.org/abs/2605.08083 #ArtificialIntelligence #DeepLearning #AIAgents -
Mythos AI model solves UK AISI cyber range benchmarks
By
–
The UK AISI found Mythos Preview is the first model to solve both their cyber ranges end-to-end. No model had ever solved the AISI’s “Cooling Tower” cyber range before. We're getting it to defenders as fast as we responsibly can. More to come on our Glasswing work soon.