Monthly model releases means we're going to need monthly evals haha
RESEARCH
-
Junior vs Senior: Different Perspectives on AI Technology Adoption
By
–
The discrepency is always junior reaction "wow it's perfect", while more senior is "why is it doing it like this", and hopefully its a senior's reaction with openness rather than just thinking its useless.
-
AutoReason: Advancing AI Reasoning Research and Model Discovery
By
–
Paper: https://
github.com/NousResearch/a
utoreason/blob/main/paper/autoreason.pdf
… Check out http://
AlphaSignal.ai to get a daily summary of top models, repos, and papers in AI. Read by 280,000+ devs. -

Self-refinement loops in AI: Problems and solutions
By
–
Karpathy-inspired paper proves self-refinement destroys your AI's own output. Most AI self-refinement loops make outputs worse. Models hallucinate flaws to satisfy critique prompts. They expand scope every pass. They never stop editing. Autoreason is a new paper that fixes
-
Embedding Leaderboard Performance Fails on Real Data
By
–
Embedding leaderboard wins evaporate the second you swap to your actual corpus haha
-
AI Model Evaluation Benchmarks Limited Testing Scope Critique
By
–
Same energy as "we only tested on MMLU" a year ago haha
-
Beyond Model Size: Smart Scaffolding for LLM Agents
By
–
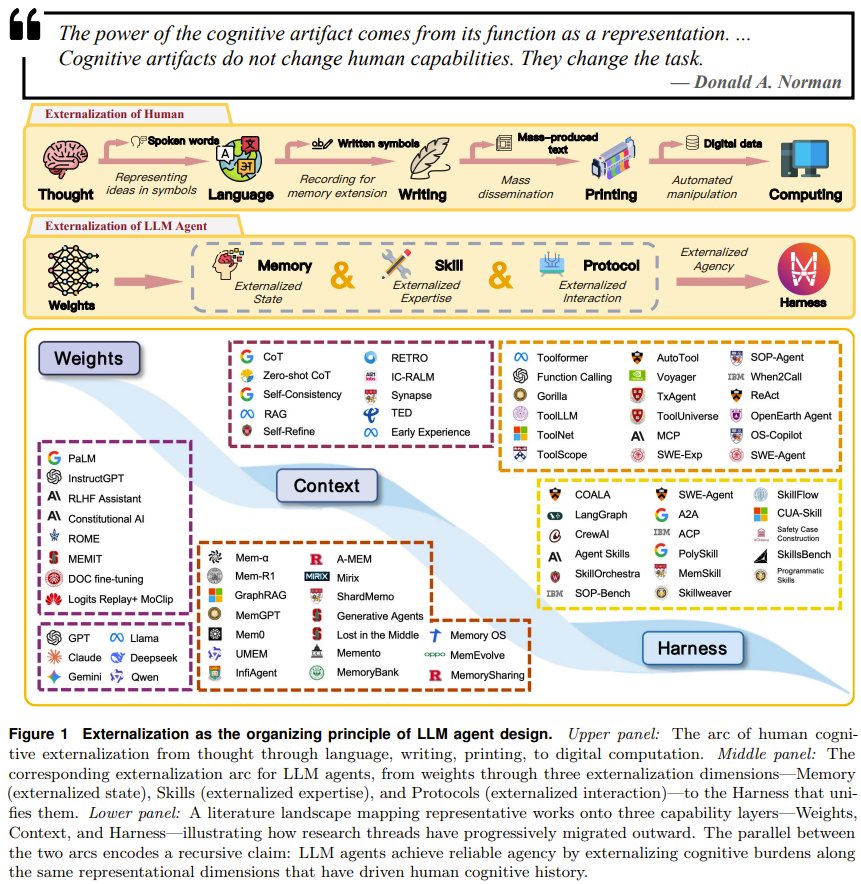
Think building an AI agent is just a better brain? What if the real secret is what you add outside the model? A team from Shanghai Jiao Tong University, OPPO, and others argues that the future of LLM agents isn't about bigger weights, but smarter scaffolding. They introduce a
-

April LLM Releases: Gemma 4, GLM-5.1, Qwen3.6, Kimi K2.6, DeepSeek V4
By
–
April was a pretty strong month for LLM releases:
– Gemma 4
– GLM-5.1
– Qwen3.6
– Kimi K2.6
– DeepSeek V4 All are now added to the LLM Architecture Gallery. More details once I am fully back in May! -

LLM Serving Engines: vLLM, SGLang, TensorRT Optimization
By
–
How to go about learning all of this? 1st: Start with the serving engine view – vLLM: PagedAttention, continuous batching, prefix caching, CUDA graphs – SGLang: RadixAttention/prefix reuse, speculative decoding, MoE, structured/agent workloads – TensorRT-LLM: NVIDIA peak
-
Decade-Long AI Predictions Finally Become Breaking News
By
–
Uncanny how what I have been telling the field for a decade is suddenly breaking news.