The irony: “Open”AI has closed down the AI ecosystem. But we should have no illusions that industry just automatically aligns with academic values, certainly not in the middle of an AI arms race.
RESEARCH
-
LeCun and Musk perspectives on AI challenge debate
By
–
Also to be fair, adding @ylecun as well to share his views in case @elonmusk takes up this challenge.
-
LLMs Discover Better Algorithms for AI Alignment Training
By
–
New Paper and Blog!https://t.co/zzAGMC2tRO
— hardmaru (@hardmaru) 13 juin 2024
As LLMs become better at generating hypotheses and code, a fascinating possibility emerges: using AI to advance AI itself! As a first step, we got LLMs to discover better algorithms for training LLMs that align with human preferences. https://t.co/80Ldqgxy3TNew Paper and Blog! https://
sakana.ai/llm-squared/ As LLMs become better at generating hypotheses and code, a fascinating possibility emerges: using AI to advance AI itself! As a first step, we got LLMs to discover better algorithms for training LLMs that align with human preferences. -
LLM Discovers Better LLM Training Algorithm DiscoPOP
By
–
Can LLMs invent better ways to train LLMs?
— Sakana AI (@SakanaAILabs) 13 juin 2024
At Sakana AI, we’re pioneering AI-driven methods to automate AI research and discovery. We’re excited to release DiscoPOP: a new SOTA preference optimization algorithm that was discovered and written by an LLM!https://t.co/yPOyJUbPHz… pic.twitter.com/73zEfWCFQnCan LLMs invent better ways to train LLMs? At Sakana AI, we’re pioneering AI-driven methods to automate AI research and discovery. We’re excited to release DiscoPOP: a new SOTA preference optimization algorithm that was discovered and written by an LLM! https://
sakana.ai/llm-squared/ -

Cerebras WSE-2 Outperforms Frontier Supercomputer 179x Faster
By
–
IEEE just published a new article by Dina Genkina highlighting the groundbreaking AI and HPC work that has been achieved on Cerebras. Our WSE-2 outperformed the world’s fastest supercomputer, Frontier, in molecular dynamics calculations, achieving speeds 179x faster. Tomas
-
Breaking Through AI Data Wall: Methods and Innovation
By
–
as confront the data wall in AI, consensus is that we need to innovate to push beyond it
— Alexandr Wang (@alexandr_wang) 12 juin 2024
scaling the data wall means developing methods for data abundance:
– frontier data & exquisite post training datasets
– verifiers and RL
– synthetic data
see more on my @twentyminutevc pod https://t.co/0pTzYgiuKUas confront the data wall in AI, consensus is that we need to innovate to push beyond it scaling the data wall means developing methods for data abundance:
– frontier data & exquisite post training datasets
– verifiers and RL
– synthetic data see more on my @twentyminutevc pod -

9B Parameter State Space Model Rivals Attention Transformers
By
–
9 billion parameters State Space Model (SSM) alternative to attention is out. Recurrent transformers are now on par with attention transformers, like Gemma and Mistral, but by maintaining a state vector they can be capable of faster inference.
-
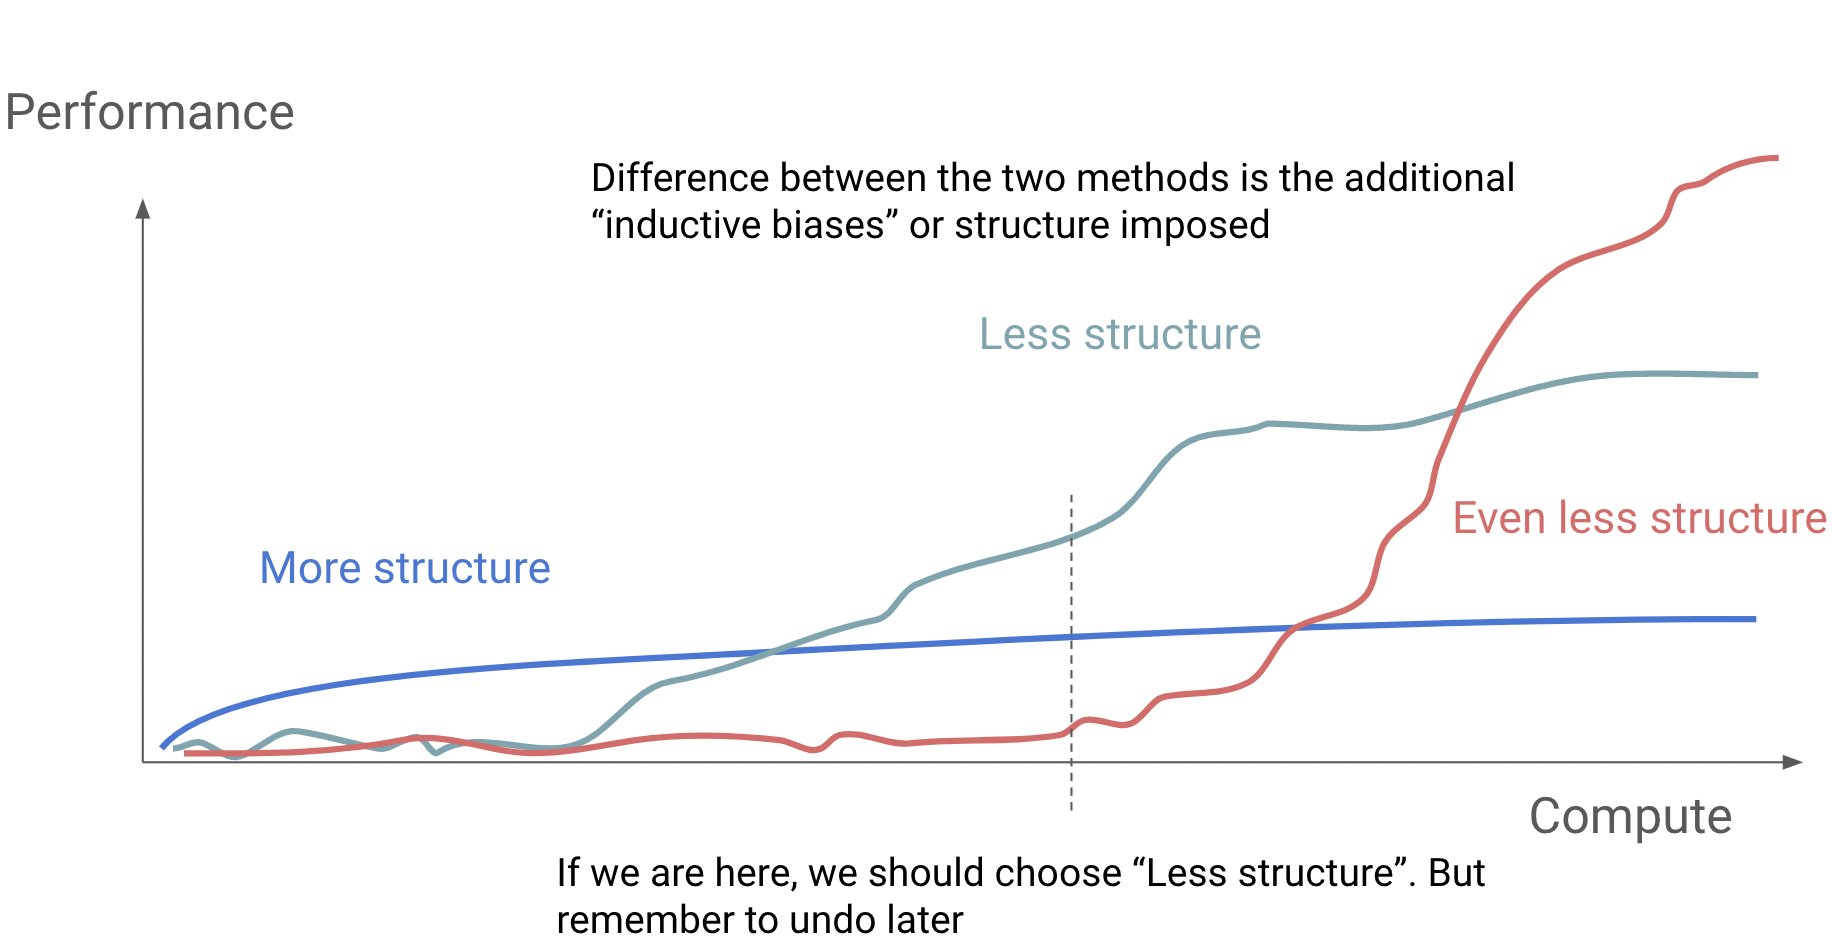
Optimal Structure in End-to-End Learning: When to Remove Inductive Bias
By
–
Although the bitter lesson suggests that end-to-end eventually wins, this talk observes that at a given level of (compute, data, algorithm, architecture), there exists an optimal structure to add to make things work at all. But we often forget to remove these when more end-to-end
-

Mirror Descent Algorithm Explained by Kevin Tian
By
–
Mirror descent in a nutshell, courtesy Kevin Tian (
@kevinjtian
) -

RISC-V Conference Panel on Open Source AI Advancements
By
–
Great panel at Andes RISC-V CON 2024! CEO Chris Walker joined Raja Koduri @Mihira_AI
, @jimkxa @tenstorrent
, & Charlie Cheng #Cucina to discuss #opensource #AI advancements. Thanks to Doug O'Laughlin @fabknowledge for moderating & @Andes_Tech
, @risc_v
, & @RISE_RISCV for hosting!