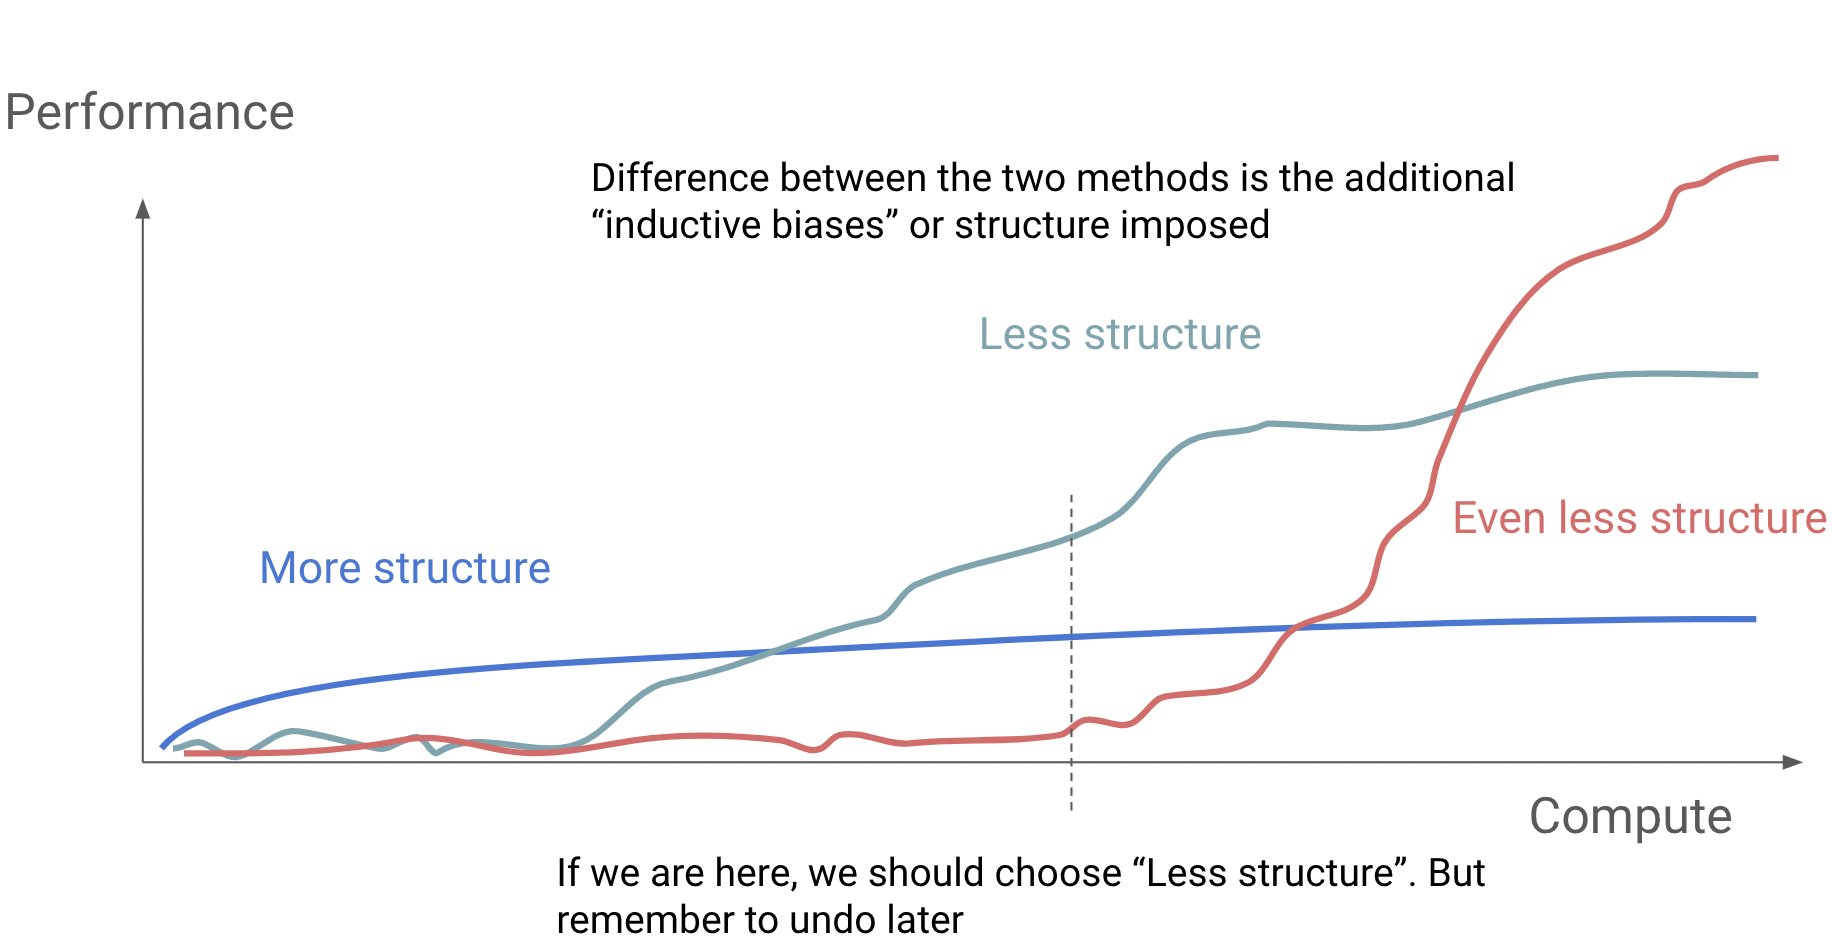
Although the bitter lesson suggests that end-to-end eventually wins, this talk observes that at a given level of (compute, data, algorithm, architecture), there exists an optimal structure to add to make things work at all. But we often forget to remove these when more end-to-end
RESEARCH
-

Mirror Descent Algorithm Explained by Kevin Tian
By
–
Mirror descent in a nutshell, courtesy Kevin Tian (
@kevinjtian
) -

RISC-V Conference Panel on Open Source AI Advancements
By
–
Great panel at Andes RISC-V CON 2024! CEO Chris Walker joined Raja Koduri @Mihira_AI
, @jimkxa @tenstorrent
, & Charlie Cheng #Cucina to discuss #opensource #AI advancements. Thanks to Doug O'Laughlin @fabknowledge for moderating & @Andes_Tech
, @risc_v
, & @RISE_RISCV for hosting! -

Plot Scaling Laws to Predict Long-Term Performance Improvement
By
–
I end with general advice to plot scaling laws for your work. Scaling laws will tell you whether doing more of your thing (on some axis) will continue improving performance or whether it will saturate (i.e., whether it will stand the test of time).
-
Lecture appreciation and recommendation for Hyung Won’s segment
By
–
Hope the lecture is helpful, and thanks @stevenyfeng @SeongHee17633 @DivGarg9 @EmilyBunna for having me! Also check out Hyung Won's second half of the lecture, which is about inductive biases and how AI has become more end to end
-
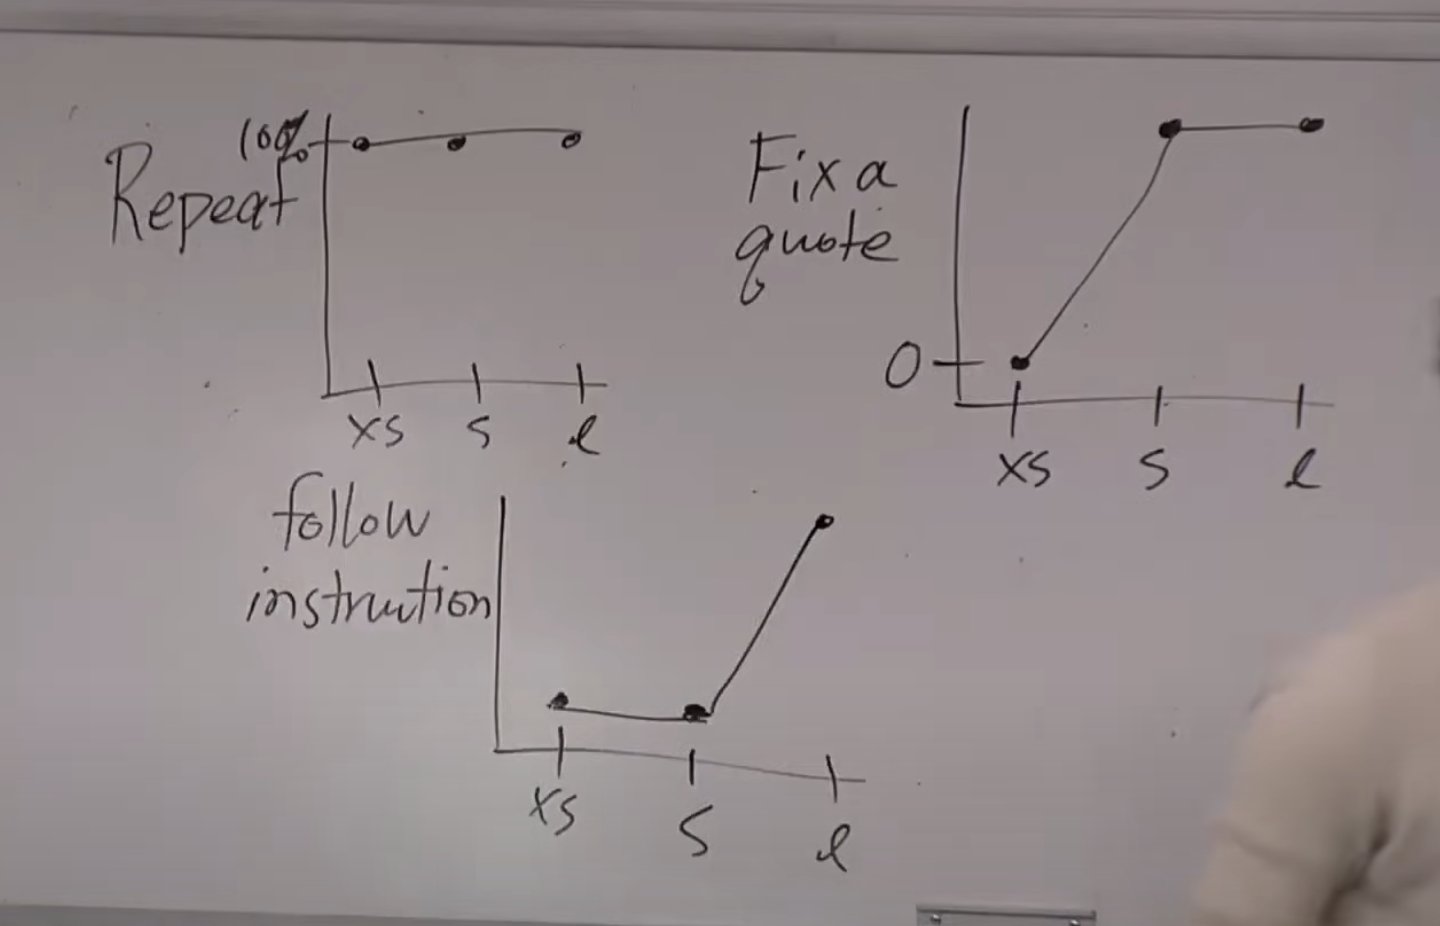
Task Decomposition and Emerging Model Capabilities Through Subtasks
By
–
Often these tasks are a decomposition of multiple sub-tasks, and changes in behavior can be explained by the ability for models to do new subtasks.
-
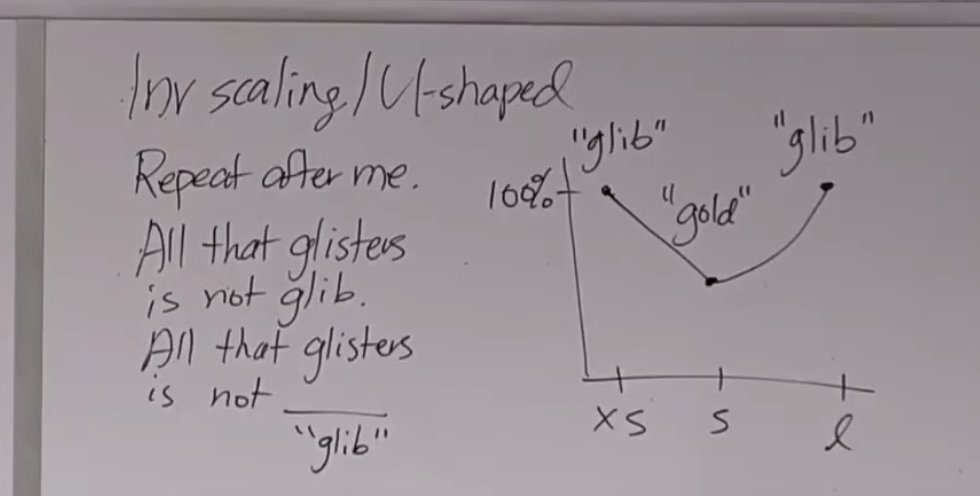
Inverse Scaling and U-Shaped Performance in Language Models
By
–
One interesting phenomena is that performance for some tasks can get worse with scale (“inverse scaling”), then potentially get better ("U-shaped scaling"). This is a nice case study to help understand language model behavior.
-
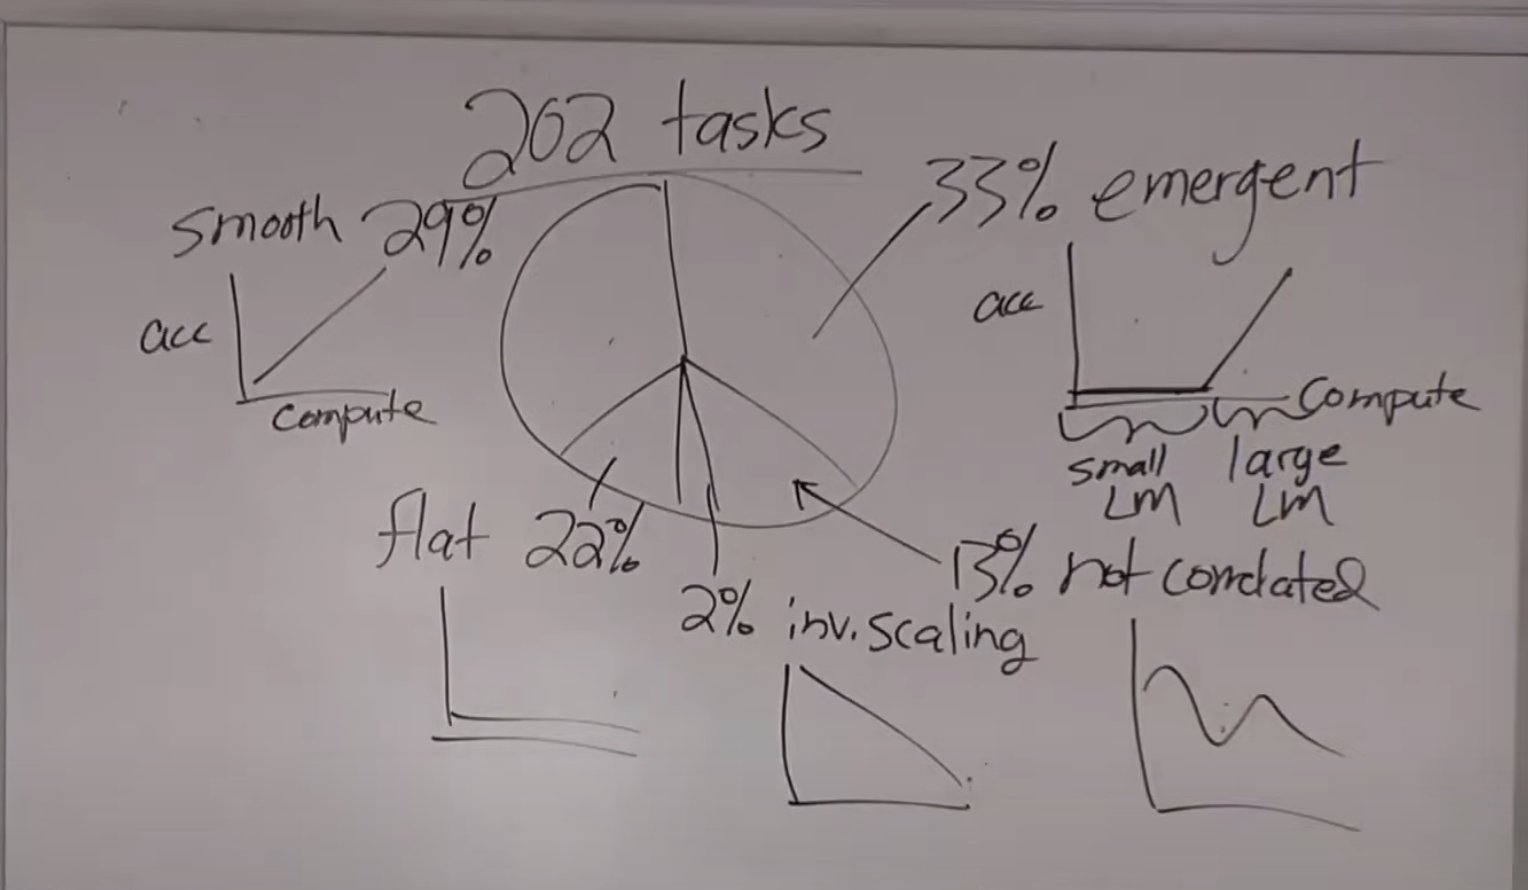
Task Performance Decomposition: Smooth and Sudden Scaling Patterns
By
–
And it turns out that you can take a corpus of tasks, for which the average performance scales smoothly, and decompose them into tasks that increase smoothly or suddenly. There are many tasks in both categories.
-
Model Size and Emergence of Specialized Capabilities in AI
By
–
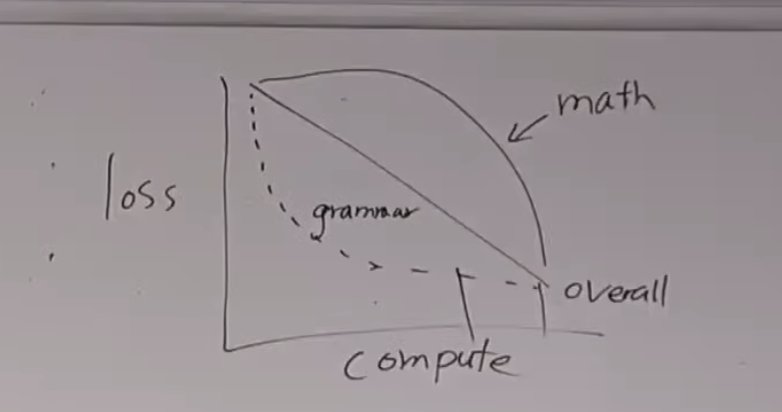
For harder tasks OTOH, only a large enough model will be incentivized to improve their loss (because by definition, they are harder). For example, GPT-4 is way better at math or physics than GPT 3.5. These abilities might appear only when you reach a certain model size.
-
Different Tasks Improve at Different Rates with AI Models
By
–
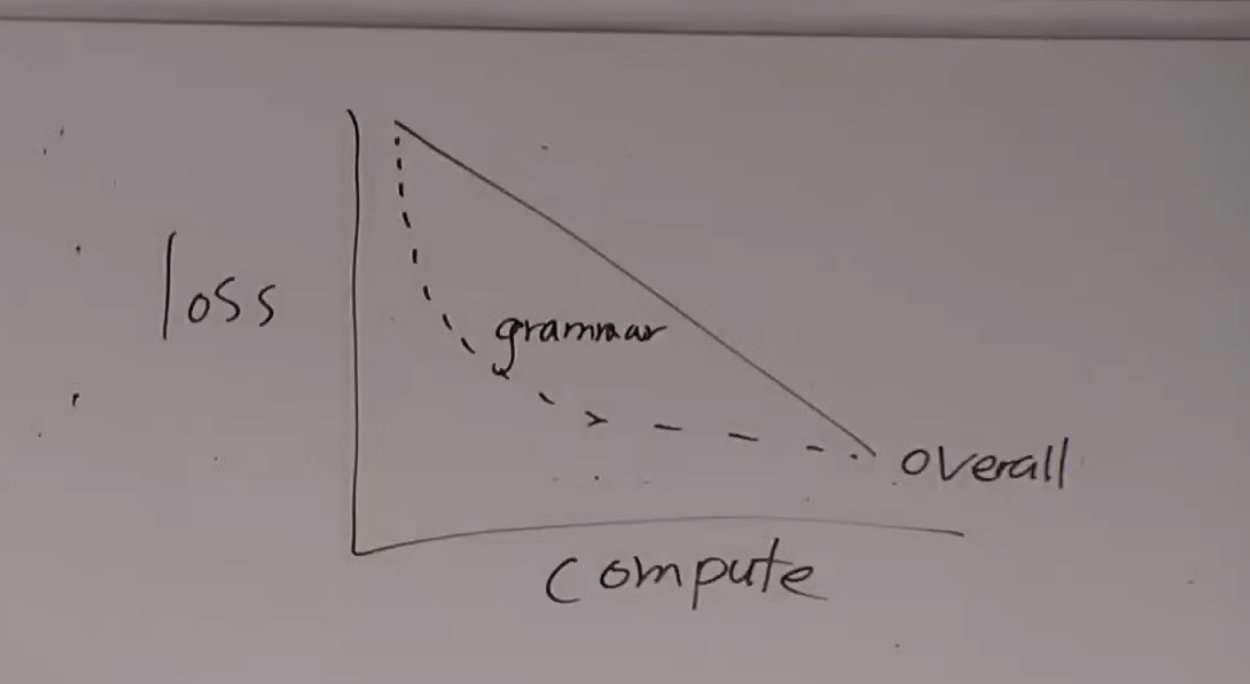
It seems obvious that different tasks should improve at different rates. For easy tasks, it is likely that they don’t improve much after we saturate them. For example, GPT-3.5 is basically as good as GPT-4 at writing grammatical sentences or classifying sentiment analysis.