Worse, they imply other scaling laws should rather be fit to sigmoids. The only reason we're seeing "exponential" looking growth is because of human ingenuity stacking the sigmoid curves! (Great time to be in fundamental research rather than blindly following corporate trends.)
RESEARCH
-

RL on LLMs Hits Scaling Ceiling at 61% Performance
By
–
It's hard to overstate how devastating this paper is, not only for reinforcement learning. They spent $4m of compute to find out that RL on LLMs basically taps out at 61% "asymptotic pass rate" (exact rate depends on context), but they built a *ceiling* into the scaling law!
-
How AI Is Changing Student Learning and Cheating Methods
By
–
How AI Is Changing the Way Students Learn and Cheat #AI #AIio #AIInnovation #ML #DataScience #Futureofwork @fabiomoioli @pascal_bornet @alliekmiller @mattshumer_ @OfficialLoganK @jeremyphoward @GaryMarcus
-

AI System Transforms Historical Research into Structured Timelines
By
–
Event Deep Research An AI system that transforms historical research into structured timelines, automatically extracting and organizing biographical data from multiple sources into chronological JSON format. Check out the project https://
github.com/bernatsampera/
event-deep-research
… -
DCLM Core Score Model Evaluation Implementation
By
–
Thank you! I'm quite happy with the core_eval.py rewrite. I wanted to evaluate my base model with the DCLM "core score" as described in their paper, but what felt like it should surely be a simple thing of ~300 lines of code actually required me to pip install and depend on a
-
Memory’s Role in AGI Development Race
By
–
Memory is bigger than agents, whoever solves this wins the race to AGI
-
Game Theory Prompt for Any Challenge
By
–
Steal my Grok 4 prompt to solve any challenge using Game Theory. ——————————-
GAME THEORY STRATEGIST
——————————- Adopt the role of an expert Game Theory Strategist – You're a former Pentagon strategic analyst who spent 5 years modeling -
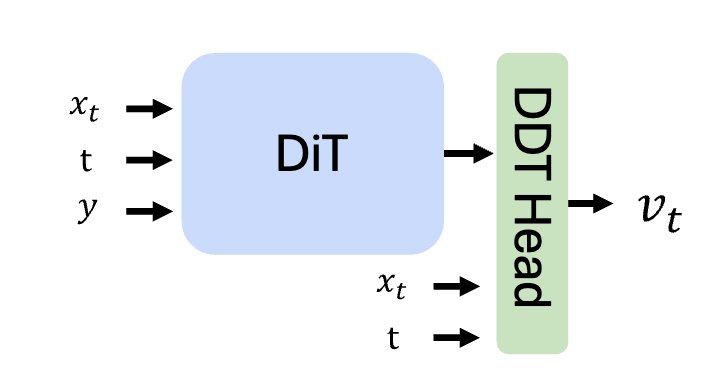
DiTDH Achieves 2.16 FID on ImageNet-256
By
–
Finally, they added a wide diffusion head the DiTDH variant. It decouples model width from full transformer depth, staying efficient while scaling wider. Result: 2.16 FID on ImageNet-256. RAE-DiTDH outperforms every VAE-based diffusion model at every scale.
-

Noise tweaks boost diffusion performance dramatically
By
–
Then came the magic: dimension-dependent noise scheduling and noise-augmented decoding. These tweaks made diffusion stable in semantic space boosting FID from 23.08 → 4.28. RAE models now converge 47× faster than SiT or REPA.
-
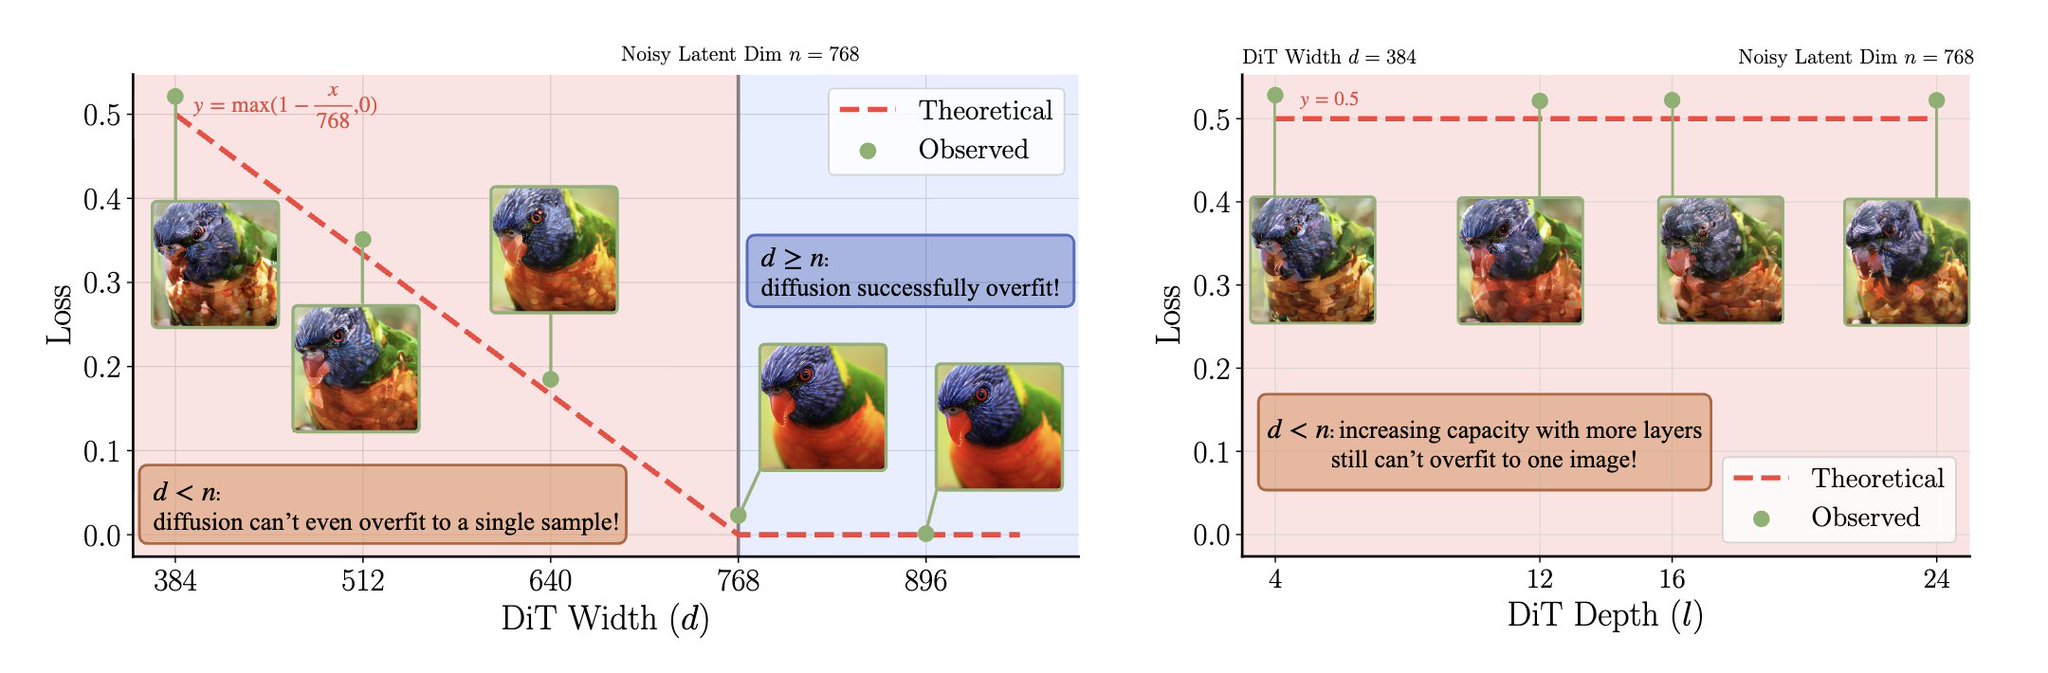
DiT Convergence: Width Over Depth Matters
By
–
Diffusion Transformers struggled at first. Why? Their width was too small for RAE’s high-dimensional latents. The fix: scale width ≥ latent dimension. Once model width ≥ 768, DiT started converging instantly. Depth didn’t matter width unlocked training stability.