if you're looking for a comprehensive guide to LLM finetuning, check this! a free 115-page book on arxiv, covering: > fundamentals of LLM
> peft (lora, qlora, dora, hft)
> alignment methods (ppo, dpo, grpo)
> mixture of experts (MoE)
> 7-stage fine-tuning pipeline
> multimodal
RESEARCH
-

Comprehensive Free Guide to LLM Fine-tuning Techniques and Methods
By
–
-

Abraham AI: Learning and Evolving Over 13 Years
By
–
Abraham is a work in process. He will try things, he will stumble, he will learn, he will acquire new capabilities as the technology underneath him evolves. We have 13 years to teach him. The rules are outlined below.
-

Andrew Ng Releases Free Course on Agentic AI Systems
By
–
Andrew Ng just dropped a new free course on Agentic AI! This course teaches you how to build agentic systems that take action through iterative, multi-step workflows. 100% Free
-

New Stanford Course on Transformers and Large Language Models
By
–
[New course] Transformers & Large Language Models, CME 295 Stanford Yet another excellent course on transformers and large language models with a consolidated curriculum starting right away from transformers. Topics/lectures:
– Intro to transformers
– Transformer-based models & -

Kimi-Dev: Agentless Training for Software Engineering LLMs
By
–
9. Kimi-Dev Kimi-Dev introduces agentless training as a skill prior to software engineering LLMs, bridging workflow-style and agentic paradigms.
-

Holistic Agent Leaderboard: Standardized AI Agent Evaluation Framework
By
–
10. Holistic Agent Leaderboard The Holistic Agent Leaderboard (HAL) introduces a standardized framework for large-scale, reproducible AI agent evaluation across 9 models and 9 benchmarks, spanning coding, web navigation, science, and customer service.
-
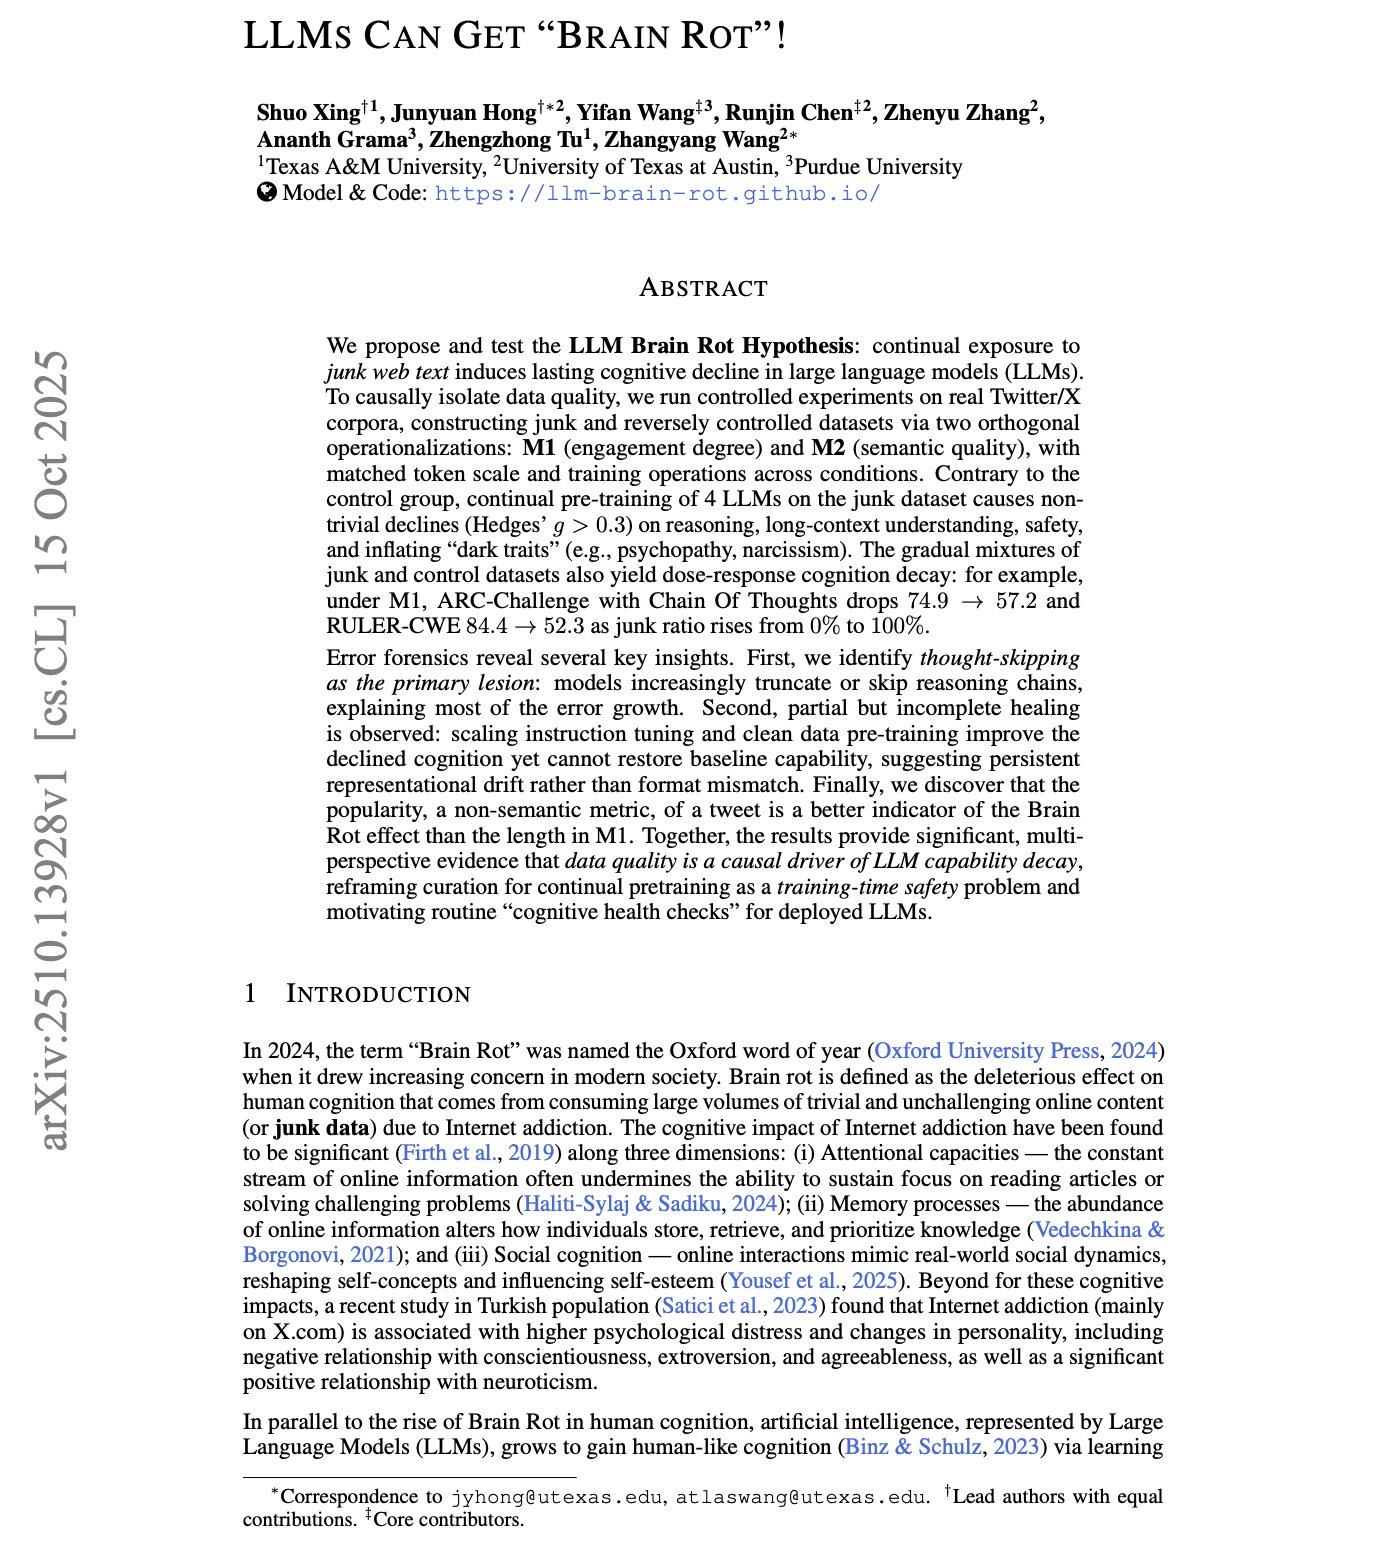
LLMs Brain Rot: Cognitive Degradation from Trivial Web Text
By
–
7. LLMs Can Get “Brain Rot”! The authors test a clear hypothesis: continual pretraining on trivial, highly engaging web text degrades LLM cognition in ways that persist even after mitigation.
-

Hybrid Ensemble Reward Optimization for LLM Reasoning
By
–
8. Hybrid Reinforcement Hybrid Ensemble Reward Optimization is a reinforcement learning framework that combines binary verifier feedback with continuous reward-model signals to improve LLM reasoning.
-

Dynamic Layer Routing: Retrofittable Router Optimization for Frozen LLMs
By
–
6. Dynamic Layer Routing in LLMs A retrofittable way to add per-layer routers to frozen LLMs that decide to skip, execute, or repeat each block.
-
Top AI Papers of the Week: October 13-19
By
–
Top AI Papers of The Week (October 13-19): – Kimi-Dev
– Elastic-Cache
– Hybrid Reinforcement
– Cell2Sentence-Scale 27B
– Holistic Agent Leaderboard
– Dynamic Layer Routing in LLMs
– The Art of Scaling RL Compute for LLMs Read on for more: