
Every child learns differently. Our ORF tool is: Shaped by classrooms Guided by teachers Built to help young learners progress with confidence #WadhwaniAI #AIforGood #EdTech #EducationEquity #MachineLearning #DataForGood #SocialImpact #EducationInIndia
RESEARCH
-
Homo Technologicus: AI Humanism Interview with Juan Merodio
By
–
He publicado un episodio en @ivoox
: "Somos Homo Technologicus: IAhumanismo (entrevista a Juan Merodio por David Sobrino) #podcast -

Jais-2: Arabic LLM 20x Faster Than Leading Models
By
–
Introducing Jais-2 – a major leap for Arabic AI. Co-developed with @G42ai , Inception, and @mbzuai
, Jais-2 is a family of Arabic models built end-to-end on Cerebras from pretraining to inference. Jais-2 70B runs at 2,000 tokens/sec – 20x faster than leading LLMs. It brings deep -
Meta’s Avocado AI Model Delayed to 2026
By
–
Meta is working on a new proprietary frontier AI model called “Avocado” according to CNBC. “We were expecting the model to be released before the end of this year, but that the plan now is for that to happen in the first quarter of 2026.” Meta will be back
-
Waymo’s Use of Large Models and GOFE in Autonomous Driving
By
–
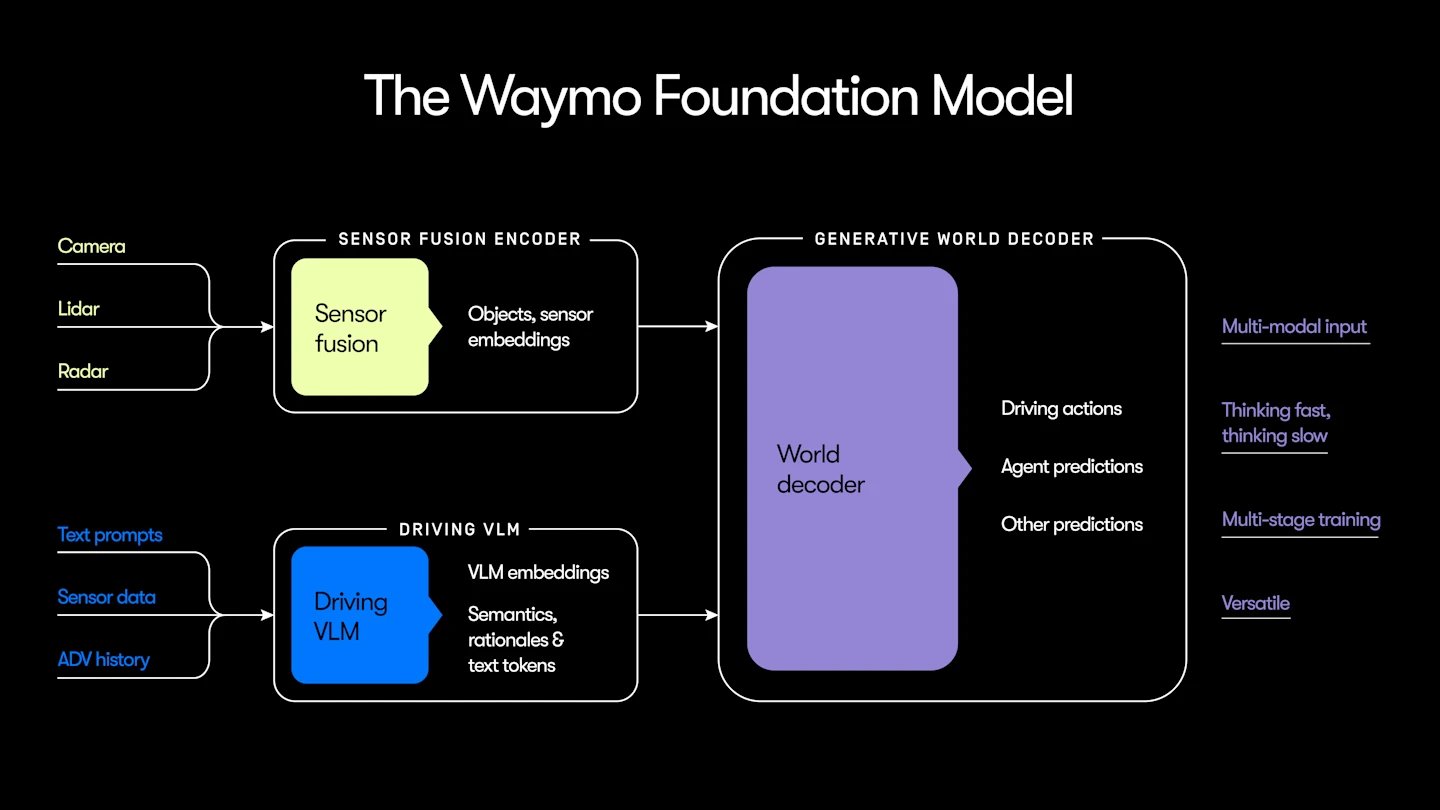
My sense is that @Waymo has been using large models for awhile (plus lots of GOFE for sensor pre-processing, system bootstrapping, data avalanching, and ongoing safety). One clue is the “thinking fast and slow” note on the image.
-
RL Impact on Base Model Performance: Pre-training and Mid-training Interplay
By
–
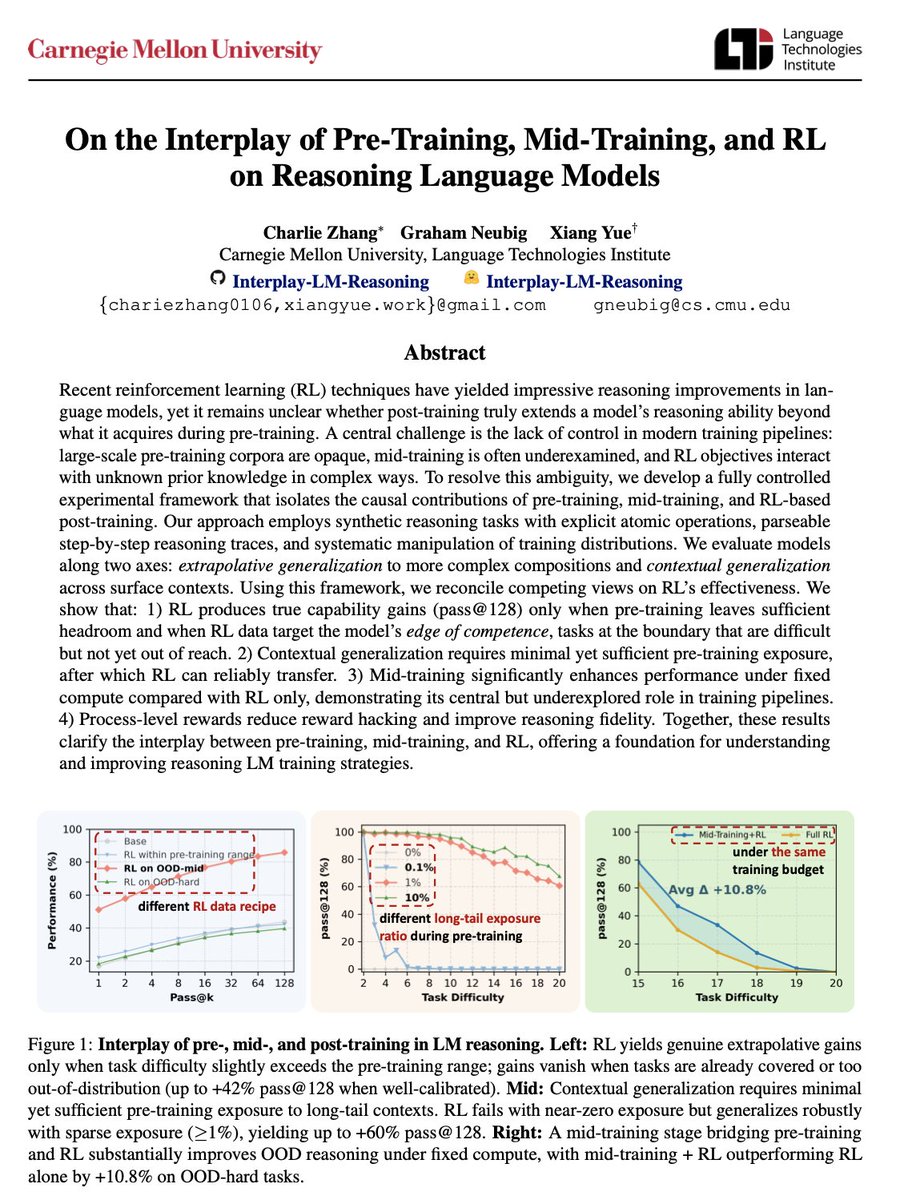
There are competing views on whether RL can genuinely improve base model's performance (e.g., pass@128). The answer is both yes and no, largely depending on the interplay between pre-training, mid-training, and RL. We trained a few hundreds of GPT-2 scale LMs on synthetic GSM-like reasoning data from scratch. Here are what we found: 🧵
-

Notion Testing GPT-5.2 Internally
By
–
BREAKING : Notion might be testing GPT-5.2 internally under the "olive-oil-cake" codename. The codename is abstracted by Notion. Soon or not soon?
-

Terminal-Bench 2.0: Harder Tasks and Deeper Agent Verification
By
–
ICYMI — the Terminal-Bench creators just laid out what actually matters for agent evaluation.
— Snorkel AI (@SnorkelAI) 9 décembre 2025
Terminals > GUIs
Containers for real rollouts
TB 2.0 = harder tasks + deeper verification pic.twitter.com/zSazGyZYS2ICYMI — the Terminal-Bench creators just laid out what actually matters for agent evaluation.
Terminals > GUIs
Containers for real rollouts
TB 2.0 = harder tasks + deeper verification -
AI Agents Reshape Learning Work Problem Solving
By
–
AI agents are reshaping how we learn, work, and solve problems. Read the full research paper:
-

Agent Activity Dominated by Productivity and Learning Work
By
–
More than half of all agent activity focuses on cognitive work. Agent use is dominated by Productivity & Workflow (36% of queries) and Learning & Research (21%). Users rely on the assistant to think through something, synthesize findings, and take action on those learnings.