The core idea is that this lets you skip writing but it doesn’t let you skip reading and thinking. And the surprising result is that this works. Personally I process most of what I file by reading it, reading its summary, reading the LLM’s opinion on how it fits into the wiki and
RESEARCH
-
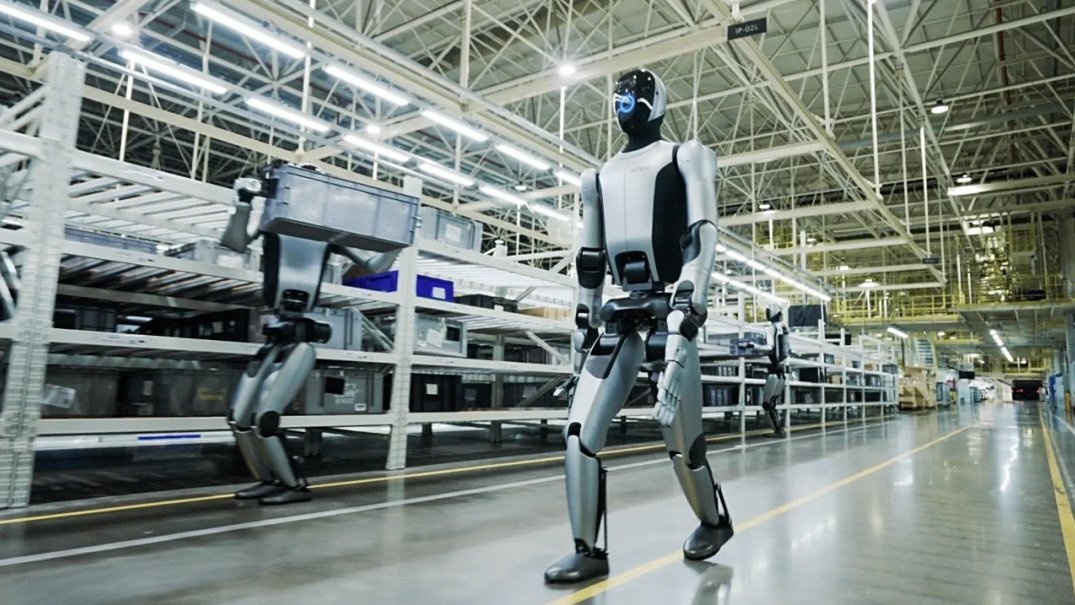
Top Robotics Stories: AI Talent, Humanoids, and Japan’s Robot Workforce
By
–
Top stories in robotics today: – UBTech offers $18M a year for one AI scientist
– This tiny bot grows its own nervous system
– Japan’s new workforce: robots wanted
– New gig economy teaches humanoids how to work – Quick hits on other robotics news -
OpenSeeker: AI-Native Search Beyond Keyword Matching
By
–
OpenSeeker: Rethinking Search With AI-Native Reasoning
— Satya Mallick (@LearnOpenCV) 6 avril 2026
In this episode of Artificial Intelligence: Papers and Concepts, we explore OpenSeeker, an emerging approach to building AI-native search systems that go beyond traditional keyword matching. Instead of retrieving links based… pic.twitter.com/EOmZhq5QZTOpenSeeker: Rethinking Search With AI-Native Reasoning In this episode of Artificial Intelligence: Papers and Concepts, we explore OpenSeeker, an emerging approach to building AI-native search systems that go beyond traditional keyword matching. Instead of retrieving links based purely on queries, OpenSeeker focuses on reasoning over information helping users get structured, context-aware answers rather than a list of results. We break down how modern search is evolving with large language models, why retrieval alone is no longer enough, and how systems like OpenSeeker combine retrieval with reasoning to deliver more accurate and useful outputs. If you’re interested in AI-powered search, retrieval-augmented generation, or the future of information discovery, this episode explains why OpenSeeker represents a shift toward more intelligent and answer-driven search experiences. Resources: Paper Link: arxiv.org/abs/2603.15594v1 Interested in Computer Vision and AI consulting and product development services? Email us at contact@bigvision.ai or visit us at bigvision.ai
→ View original post on X — @learnopencv, 2026-04-06 14:30 UTC
-
Google Cloud Cookbook: Big Data Analytics and Machine Learning Guide
By
–
Google Cloud Cookbook! #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #PyTorch #Python #RStats #TensorFlow #Java #JavaScript #ReactJS #GoLang #CloudComputing #Serverless #DataScientist #Linux #Books #Programming #Coding #100DaysofCode geni.us/Google-Cloud-Cookboo…
→ View original post on X — @gp_pulipaka, 2026-04-06 14:26 UTC
-
One-Step AI Image Generation Framework Achieves State-of-the-Art Results
By
–
What if you could generate stunning AI images in a single step, without compromising quality? Researchers from Westlake University, Chinese Academy of Sciences, and DP Technology present a breakthrough. They've introduced a new framework that simplifies the design of 'shortcut' diffusion models. This framework clarifies how to build more efficient one-step image generators by disentangling their core components. Their model achieves a new state-of-the-art FID50k of 2.85 on ImageNet-256×256 with one-step generation, and 2.53 with two steps. Remarkably, it requires NO pre-training, distillation, or curriculum learning! On the Design of One-step Diffusion via Shortcutting Flow Paths Paper: openreview.net/forum?id=k6q8… Code: github.com/EDAPINENUT/Explic… Project: edapinenut.github.io/explici… Our report: mp.weixin.qq.com/s/BptmtBa_O… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-06 14:23 UTC
-
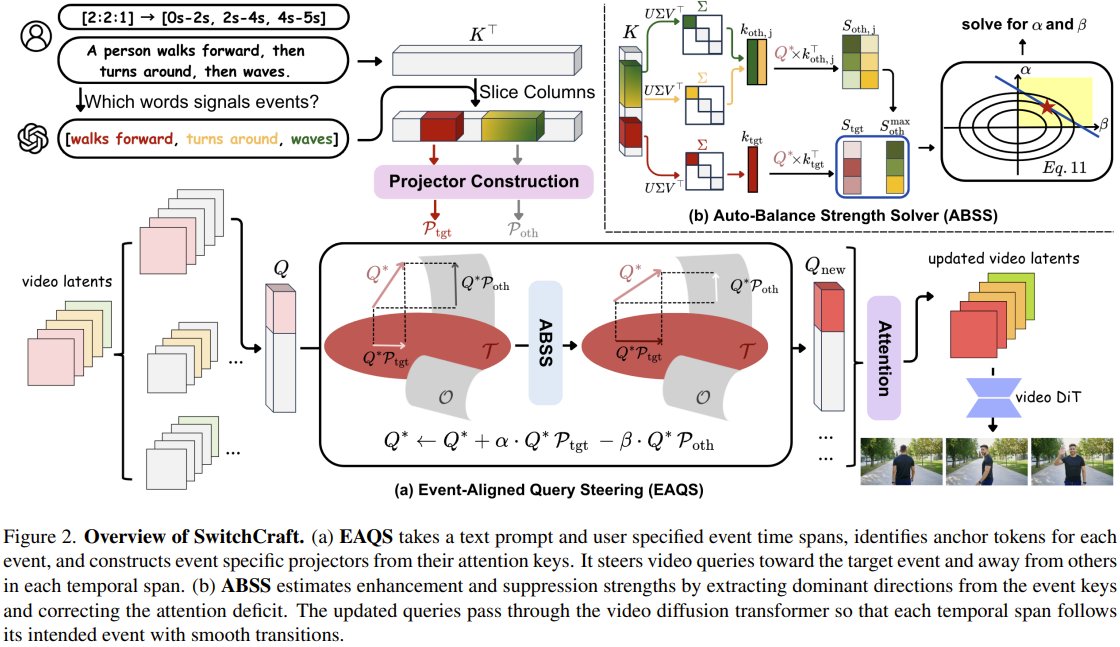
SwitchCraft: Training-Free Multi-Event Video Generation Framework
By
–
What if AI could generate multi-event videos with perfectly distinct scenes and smooth transitions? Researchers from Westlake University, Duke Kunshan University, and The University of Queensland present SwitchCraft! This training-free framework smartly aligns each video frame's attention to individual events in your prompt. t directs focus precisely and adaptively balances this control to ensure both smooth transitions and visual quality. It dramatically improves prompt alignment, event clarity, and scene consistency, outperforming current baselines and making complex video narratives easy. SwitchCraft: Training-Free Multi-Event Generation with Attention Controls Paper: arxiv.org/abs/2602.23956 Project: switchcraft-project.github.i… Github: github.com/Westlake-AGI-Lab/… Our report: mp.weixin.qq.com/s/Z7D5imbgZ… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-06 14:20 UTC
-
Eric Topol reviews Sebastian Mallaby’s AI history book
By
–
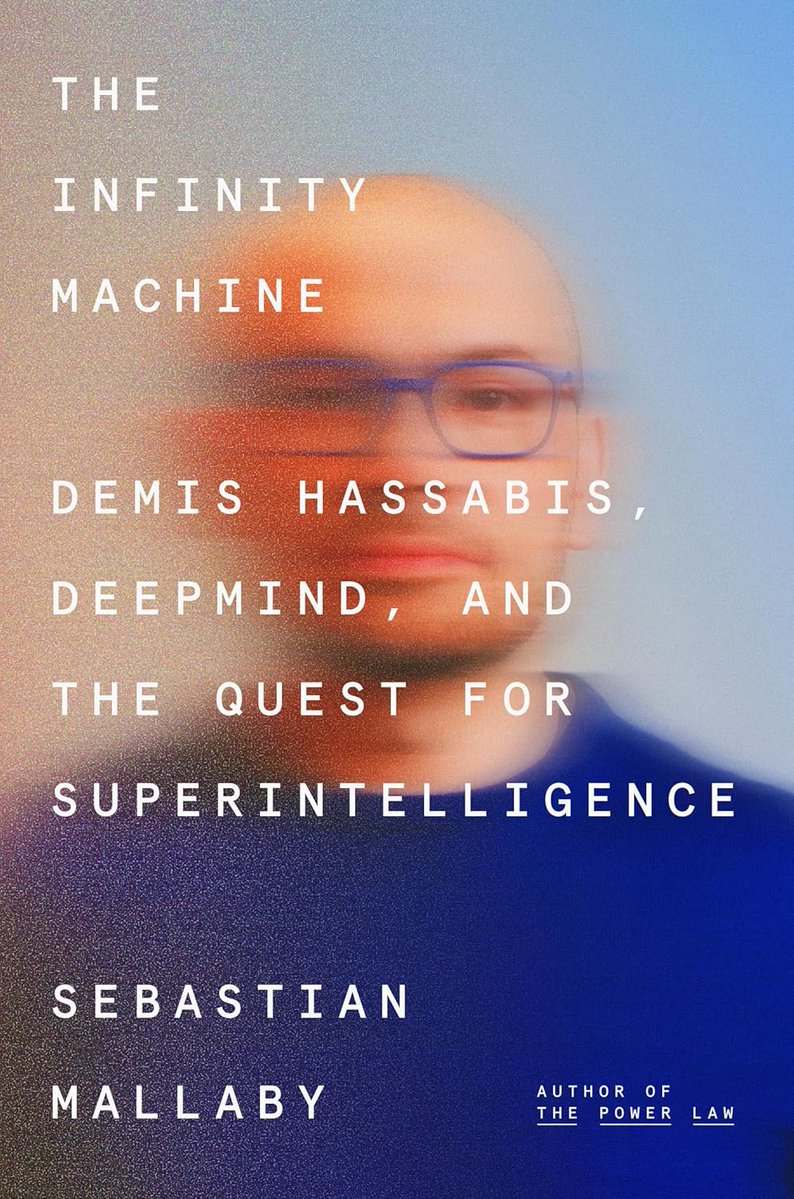
Just finished this riveting, fact-based, storytelling book on how AI rose in the past 15+ years to where it is today, by @scmallaby, featuring @demishassabis and @GoogleDeepMind. Join Sebastian and me for a Ground Truths live podcast tomorrow 12N PT erictopol.substack.com
→ View original post on X — @erictopol, 2026-04-06 14:17 UTC
-
Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Processing
By
–
If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/204… Sumanth (@Sumanth_077) Microsoft just fixed a major speech recognition problem! They open sourced VibeVoice-ASR, a speech-to-text model that processes 60 minutes of audio in a single pass. Here's the problem with most ASR models. They slice audio into short chunks, usually 30 seconds or less. Process each chunk separately. Lose speaker context between segments. You get disconnected transcripts that can't track who said what across a full meeting. VibeVoice-ASR handles 60 minutes of continuous audio without chunking. The model maintains global context across the entire hour. The output is structured. Who spoke, when they spoke, what they said. Speaker diarization, timestamps, and transcription all in one pass. Key features: • 60-minute single-pass processing without chunking audio • Structured output: speaker labels, timestamps, and content combined • Customized hotwords: provide specific names or technical terms to improve accuracy • Multilingual support: 50+ languages • Joint ASR, diarization, and timestamping in one model The model is 7B parameters. Available on Hugging Face with finetuning code included. I've shared the repo link in the comments! — https://nitter.net/Sumanth_077/status/2041157100840051111#m
→ View original post on X — @sumanth_077, 2026-04-06 14:14 UTC
-
Microsoft Shares VibeVoice GitHub Repository
By
–
Github Repo: github.com/microsoft/VibeVoi… [Translated from EN to English]
→ View original post on X — @sumanth_077, 2026-04-06 14:12 UTC
-
Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Recognition
By
–
Microsoft just fixed a major speech recognition problem! They open sourced VibeVoice-ASR, a speech-to-text model that processes 60 minutes of audio in a single pass. Here's the problem with most ASR models. They slice audio into short chunks, usually 30 seconds or less. Process each chunk separately. Lose speaker context between segments. You get disconnected transcripts that can't track who said what across a full meeting. VibeVoice-ASR handles 60 minutes of continuous audio without chunking. The model maintains global context across the entire hour. The output is structured. Who spoke, when they spoke, what they said. Speaker diarization, timestamps, and transcription all in one pass. Key features: • 60-minute single-pass processing without chunking audio • Structured output: speaker labels, timestamps, and content combined • Customized hotwords: provide specific names or technical terms to improve accuracy • Multilingual support: 50+ languages • Joint ASR, diarization, and timestamping in one model The model is 7B parameters. Available on Hugging Face with finetuning code included. I've shared the repo link in the comments!
→ View original post on X — @sumanth_077, 2026-04-06 14:12 UTC