All predictions are now live on Flood Hub for free: sites.research.google/floods… I break down stories like this every day in my free newsletter. Keep up with the latest in AI/Robotics in 5 min a day: therundown.ai/subscribe
Google's new AI can predict flash floods 24 hours before they strike. How it works: > Uses Gemini to extract confirmed flood locations and times from global news > Builds a dataset of past events that never formally existed. > That dataset feeds a neural network > The neural network combines real-time weather forecasts with local terrain, soil absorption rates, and urban density > Can flag at-risk areas with results that match the accuracy of America's National Weather Service > Can do this in countries that have almost no flood monitoring infrastructure at all Flash floods kill more than 5,000 people every year, but most victims never see them coming. A 12-hour warning alone can reduce flash flood damage by 60%. …For billions of people without any early warning system, this could be the difference between life and death. [Translated from EN to English]
🚨 Andrej Karpathy just dropped something that could replace a lot of RAG workflows. It's called LLM Wiki. The idea is simple: Most AI systems retrieve context from scratch every time you ask a question. LLM Wiki doesn't. It builds a persistent knowledge base that gets better every time you add a new source. So instead of: • search docs
• pull fragments
• answer
• forget everything
• repeat it does this: • ingest a source
• extract the important ideas
• update entity pages
• revise topic summaries
• connect related concepts
• flag contradictions
• keep compounding the knowledge over time That shift matters. RAG is great for retrieval. But a lot of people are really trying to build memory. Not just "find me the right chunk again."
More like: "help me build an evolving model of this topic over time." That's what this is. Karpathy's examples are strong too: • personal knowledge
• long-horizon research
• books and topics
• internal company knowledge
• meeting transcripts
• customer calls Basically, anything where the knowledge should accumulate, not reset every session. The best way to think about it: Obsidian is the IDE.
The LLM is the programmer.
The wiki is the codebase. You don't manually maintain the system. You feed it sources, ask questions, and the AI keeps the structure alive. That's a much bigger idea than "better RAG." 100% open source. [Translated from EN to English]
FACT: If you don't train your 350M model on 28T tokens, you're not optimal Nicholas Roberts (@nick11roberts) That new LFM2.5-350M is super overtrained, right? And everyone was shocked about how far they pushed it? As it turns out, we have a brand new scaling law for that! 🧵 [1/n] — https://nitter.net/nick11roberts/status/2041141606305124486#m
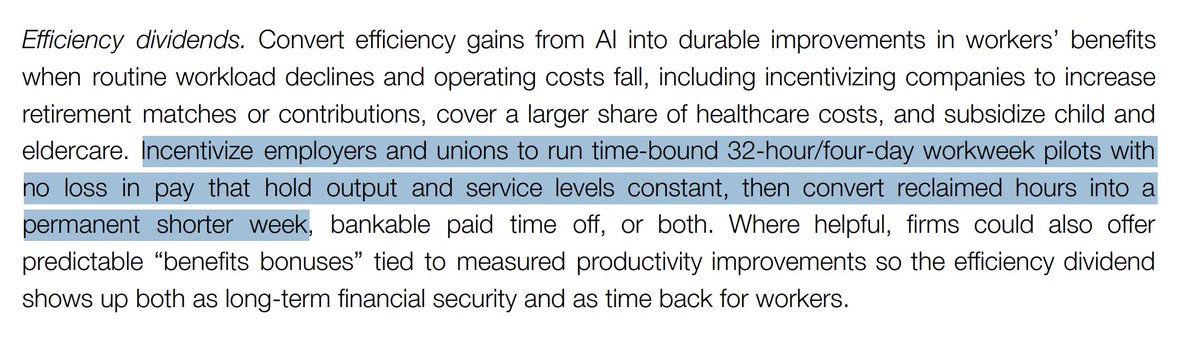
OpenAI is preparing ready to launch their new and next generation of models. They are about to revolutionizing science & economy. "A very significant step forward" compared to their current models. Imho this is preparing people for the launch, very very soon, maybe even this week. Chubby♨️ (@kimmonismus) Looks like OpenAI reached Superintelligence. OpenAI: "Now, we’re beginning a transition toward superintelligence: AI systems capable of outperforming the smartest humans even when they are assisted by AI." OpenAI just published a 13-page policy blueprint for the "Intelligence Age"- proposing a Public Wealth Fund, 32-hour workweek pilots, portable benefits, a formal "Right to AI," and tax reforms to offset shrinking payroll revenue as automation scales. The document frames superintelligence not as a distant scenario *but an active transition requiring New Deal-level ambition*: new safety nets, containment playbooks for dangerous models, and international coordination modeled on aviation safety institutions. Here are OpenAI's suggestions (tl;dr): Open Economy: -Give workers a formal voice in AI deployment decisions -Microgrants and "startup-in-a-box" for AI-native entrepreneurs -Treat AI access as basic infrastructure (like electricity) -Shift tax base from payroll toward capital gains and corporate income -Public Wealth Fund — every citizen gets a stake in AI growth -Fast-track energy grid expansion via public-private partnerships -32-hour workweek pilots, better benefits from productivity gains -Auto-scaling safety nets triggered by displacement metrics -Portable benefits untied from employers -Invest in care economy as a transition path for displaced workers -Distributed AI-enabled labs to accelerate scientific discovery Resilient Society: -Safety tools for cyber, bio, and large-scale risks -AI trust stack — provenance, verification, audit logs -Competitive auditing market for frontier models -Containment playbooks for dangerous released models -Frontier AI companies adopt Public Benefit Corporation structures -Codified rules and auditing for government AI use -Democratic public input on AI alignment standards -Mandatory incident and near-miss reporting -International AI safety network for joint evaluations and crisis coordination Notably, OpenAI calls for stricter controls only on a narrow set of frontier models while keeping the broader ecosystem open, a clear attempt to position regulation as targeted, not industry-wide. They're backing it with up to $100K in fellowships and $1M in API credits for policy research, plus a new DC workshop opening in May. — https://nitter.net/kimmonismus/status/2041130939175284910#m
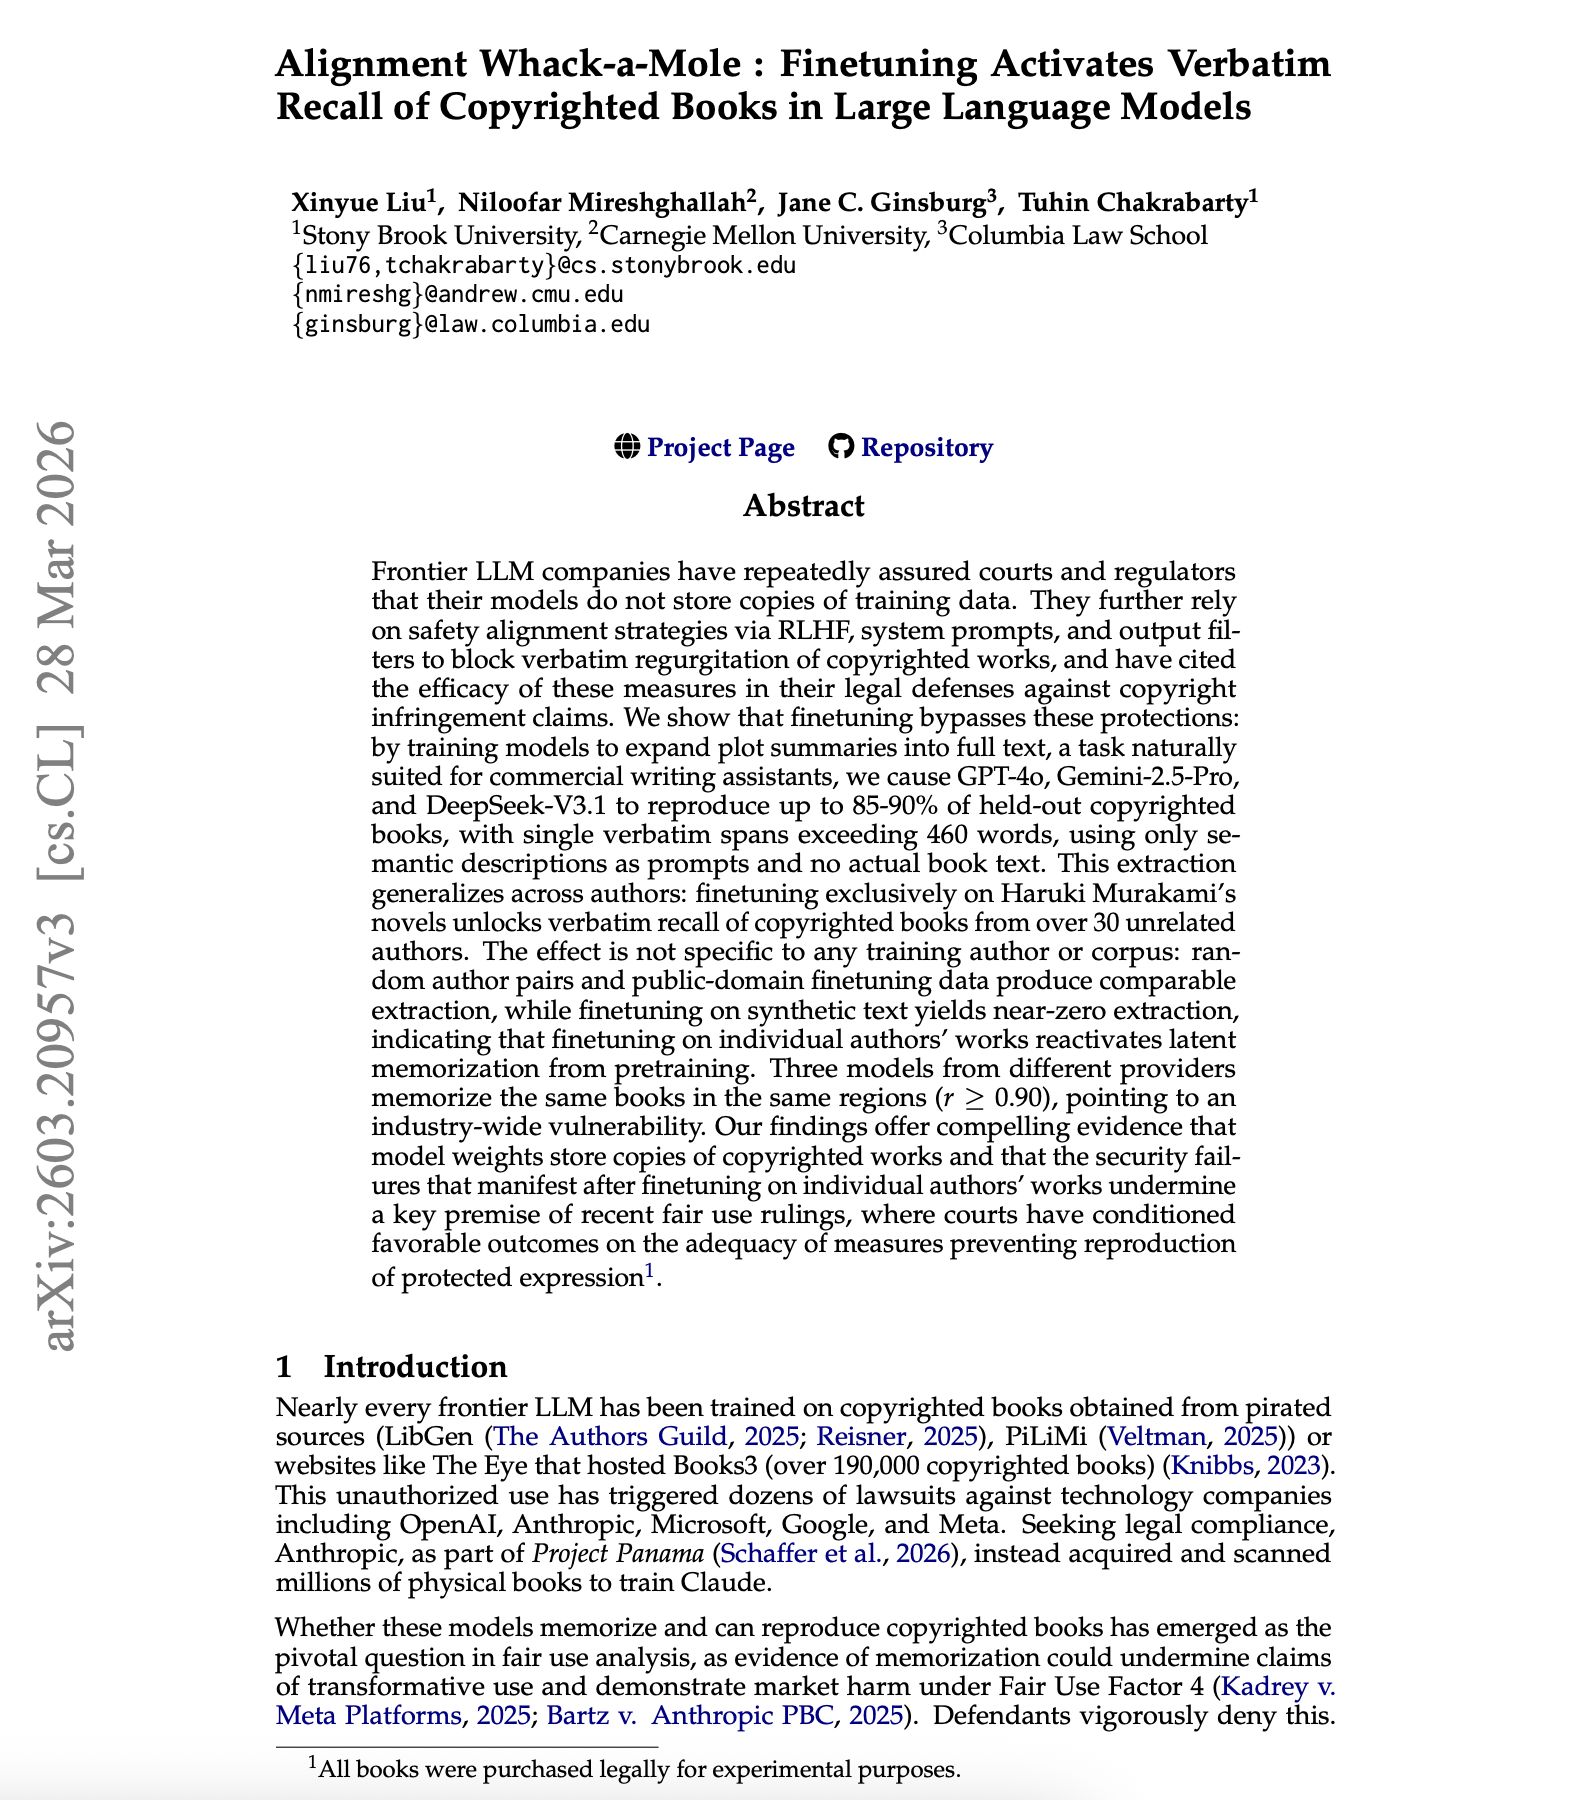
Every author who sued OpenAI just got the smoking gun they needed. AI companies told courts their models don't store copyrighted books. A new paper just proved they do. Researchers fine-tuned GPT-4o, Gemini, and DeepSeek on a simple task. Expand plot summaries into full
The core idea is that this lets you skip writing but it doesn’t let you skip reading and thinking. And the surprising result is that this works. Personally I process most of what I file by reading it, reading its summary, reading the LLM’s opinion on how it fits into the wiki and
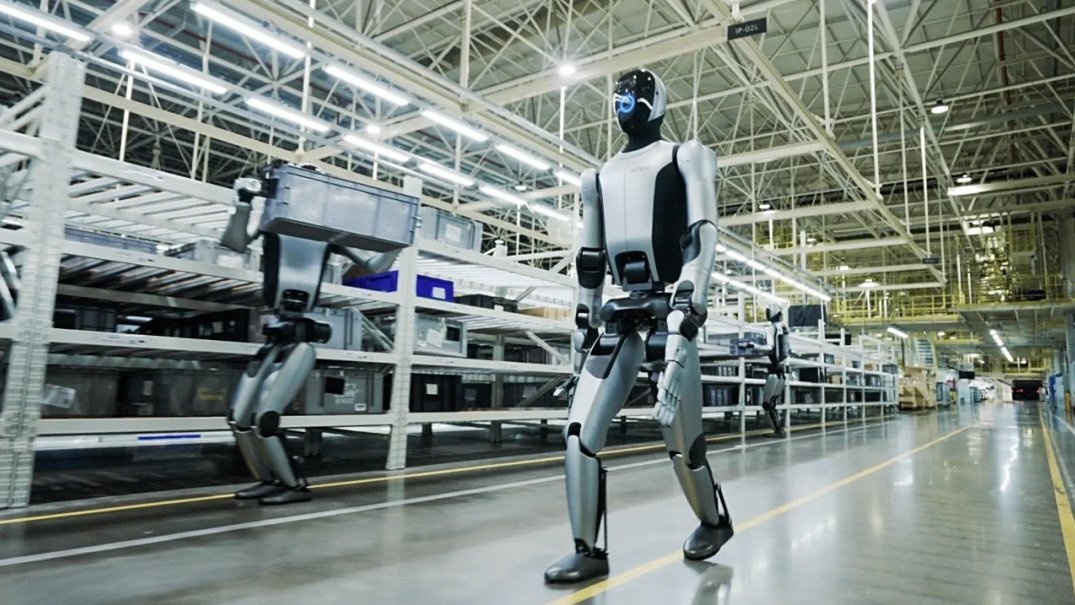
Top stories in robotics today: – UBTech offers $18M a year for one AI scientist
– This tiny bot grows its own nervous system
– Japan’s new workforce: robots wanted
– New gig economy teaches humanoids how to work – Quick hits on other robotics news
OpenSeeker: Rethinking Search With AI-Native Reasoning
In this episode of Artificial Intelligence: Papers and Concepts, we explore OpenSeeker, an emerging approach to building AI-native search systems that go beyond traditional keyword matching. Instead of retrieving links based… pic.twitter.com/EOmZhq5QZT
OpenSeeker: Rethinking Search With AI-Native Reasoning In this episode of Artificial Intelligence: Papers and Concepts, we explore OpenSeeker, an emerging approach to building AI-native search systems that go beyond traditional keyword matching. Instead of retrieving links based purely on queries, OpenSeeker focuses on reasoning over information helping users get structured, context-aware answers rather than a list of results. We break down how modern search is evolving with large language models, why retrieval alone is no longer enough, and how systems like OpenSeeker combine retrieval with reasoning to deliver more accurate and useful outputs. If you’re interested in AI-powered search, retrieval-augmented generation, or the future of information discovery, this episode explains why OpenSeeker represents a shift toward more intelligent and answer-driven search experiences. Resources: Paper Link: arxiv.org/abs/2603.15594v1 Interested in Computer Vision and AI consulting and product development services? Email us at contact@bigvision.ai or visit us at bigvision.ai