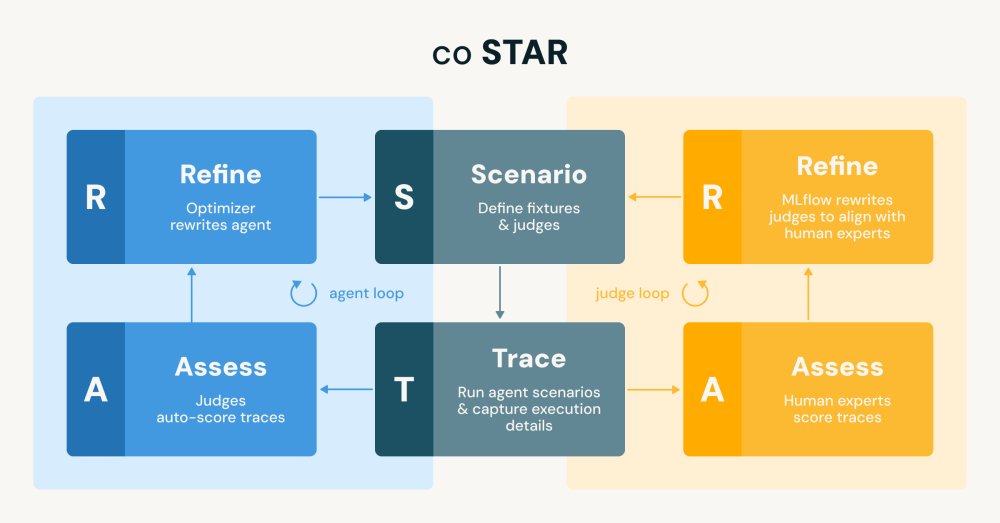
With coSTAR, we replaced manual agent iteration with an automated test and refine loop. Agents run against defined scenarios. MLflow captures execution traces, and LLM judges score the results. A coding assistant then updates the agent until it passes the tests. This cuts
RESEARCH
-
Improving Judgments Through Pairwise Comparisons and ELO Ranking
By
–
So many judging tasks could be improved by aggregating partial orderings, and in the limit, just ordering pairs. The annual Libertarian Futurist Society novel awards discussion is starting, and while I would like to participate on some level, there is no way I have time to read an entire slate of novels. However, I will likely read at least two from the list, and I could give a relative assessment. This cries out for the use of something like ELO ranking, as in chess competition, perhaps with some suggestions to get sufficient coverage. Peer and out-of-chain employee performance calibrations could probably also benefit from a greater quantity of sparse pairwise comparisons
→ View original post on X — @id_aa_carmack, 2026-04-06 19:36 UTC
-
Can LLMs Model Human Emotions Effectively?
By
–
I don't see why an LLM should not be able to model emotion in this way!
-
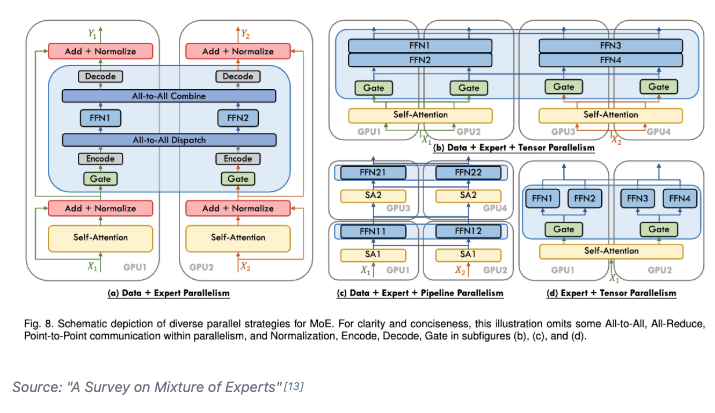
The Ultra-Scale Playbook: GPU Parallelism Strategies for LLM Training
By
–


Day 93/365 of GPU Programming Studying parallelism today and stumbled upon this incredible blog post/book The Ultra-Scale Playbook: Training LLMs on GPU Clusters by Hugging Face that dives deep into data parallelism, expert parallelism, tensor parallelism, pipeline parallelism and context parallelism. I've read a bit about each of these methodologies before but this is the best resource I've found that really pieces them all together into a unified coherent picture. Kinda like its name implies, the team goes into actual empirical examples based on the 4000 scaling experiments (across up to 512 GPUs!) they conducted. E.g. how does tensor parallelism reduce activation memory for matmuls but still require gathering full activations for LayerNorm? When does pipeline parallelism's bubble overhead outweigh its memory savings? When and why would you combine TP/PP/DP on a specific cluster topology? What's the real memory breakdown between params, gradients, optimizer states and activations and which parallelism strategy targets which? et cetera Also loved all the beautiful and sometimes interactive diagrams that reminded me of distill.pub (which makes sense given they used distill's template to create the post). I wish more blog posts in ML would use a similar approach to help visual learners understand the content at an intuitive level. Especially now that rich visualizations/animations are so easy to spin up with LLMs. Really wonderful work by @Nouamanetazi @FerdinandMom @xariusrke @mekkcyber @lvwerra @Thom_Wolf. In times when things are going more and more closed source in, this is such a good example of what great open source AI education and research can look like. levi (@levidiamode) Day 92/365 of GPU Programming Taking a closer look at disaggregated LLM inference today, which I've been wanting to survey more after listening to the Dean <> Daly discussion at GTC. The best resource I found on the topic was this great talk by @Junda_Chen_ on the past, present and future of prefill decode disaggregation. In the lecture, Junda goes through Nvidia's dynamo, the intrinsic tradeoff spectrum between throughput & latency, TTFT, TPOT, the "goodput" metric, distinct characteristics between prefill vs decode, chunking P&D, the problem of interference, pipeline parallelism, resource & parallelism coupling, disaggregation and DistServe. — https://nitter.net/levidiamode/status/2040938107604742640#m
→ View original post on X — @thom_wolf, 2026-04-06 18:58 UTC
-
Gary Marcus Criticizes Gullibility Over AGI Claims
By
–
the gullibility 🙄 https://t.co/WCWPBzMsM5
— Gary Marcus (@GaryMarcus) 6 avril 2026the gullibility 🙄 Chubby♨️ (@kimmonismus) I don't know what Sam Altman saw internally at OpenAI, but it seems that, according to their definition, AGI is here, and superintelligence is incredibly close. AI models that independently conduct scientific research and find novel solutions are already here, and their internal model appears to surpass everything seen before. — https://nitter.net/kimmonismus/status/2041151011289735573#m
→ View original post on X — @garymarcus, 2026-04-06 18:29 UTC
-

Comprehensive Survey on World Models in Artificial Intelligence
By
–
Nice survey! This comprehensive survey tackles the fragmented field of World Models, systems that help AI predict how environments change. It unifies them into four key paradigms, from learning directly from observations to understanding objects and actions. This survey provides a unified map for understanding, comparing, and advancing World Models. It clarifies their performance across robotics, autonomous driving, game simulation, and identifies critical challenges like long-term consistency, charting the course for future AI breakthroughs. Learning to Model the World: A Survey of World Models in Artificial Intelligence Project: github.com/JiahuaDong/Awesom… Paper: techrxiv.org/doi/full/10.362… Our report: mp.weixin.qq.com/s/RYATYwUDg… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-06 18:27 UTC
-

American AI Development Lacks Metaphysical Reflection
By
–
Et ça pose aucune reflexion métaphysique aux américains…
-
Chollet and Altman Discuss AGI, Social Contracts at ARC-AGI-3
By
–
Francois Chollet + Sam Altman Fireside@fchollet and @sama fireside during ARC-AGI-3 Launch Party moderated by @deedydas
— ARC Prize (@arcprize) 6 avril 2026
They discuss:
– Social contracts evolving
– AGI views as a parent
– When will labs score >85% on ARC-AGI-3? pic.twitter.com/5r9ZCWNBToFrancois Chollet + Sam Altman Fireside @fchollet and @sama fireside during ARC-AGI-3 Launch Party moderated by @deedydas They discuss: – Social contracts evolving – AGI views as a parent – When will labs score >85% on ARC-AGI-3?
→ View original post on X — @ceobillionaire, 2026-04-06 18:21 UTC
-
alphaXiv and marimo Notebook Competition with Mac Mini Prize
By
–
We partnered with @askalphaxiv on a competition. Pick a paper, build a marimo notebook that brings the core idea to life, and become one of the few experts on your research topic. Oh, and did we mention you can win a Mac Mini + $1K in prizes? 👀 Full details found here: marimo.io/pages/events/noteb…
→ View original post on X — @askalphaxiv, 2026-04-06 18:17 UTC
-
Hugging Face and SAIR Foundation Deepen AI x Science Collaboration
By
–
We’re very excited to deepen our work with the @SAIRfoundation co-founded by Terence Tao. We’ve been very active pushing the communities in AI x science in chemistry, physics, biology (more on that very soon) and this aligns perfectly with what the SAIR foundation has been doing… https://t.co/EA1EroWJTk
— Thomas Wolf (@Thom_Wolf) 6 avril 2026We’re very excited to deepen our work with the @SAIRfoundation co-founded by Terence Tao. We’ve been very active pushing the communities in AI x science in chemistry, physics, biology (more on that very soon) and this aligns perfectly with what the SAIR foundation has been doing in math (and soon extending as well). Sharing datasets, building challenges and communities Exciting future for open-science SAIR (@SAIRfoundation) We’re excited to announce our collaboration with @huggingface. Through SAIR competitions, we aim to provide open data, benchmarks, tools, and models, and expand the frontier of AI x Science through collective contributions from the community. SAIR on Hugging Face: huggingface.co/SAIRfoundatio… — https://nitter.net/SAIRfoundation/status/2041183272445559179#m
→ View original post on X — @thom_wolf, 2026-04-06 18:13 UTC