
Voyager SDK v1.5.3 adds YOLO26 support End-to-end NMS-free inference, faster CPU performance, better small object detection through ProgLoss + STAL. Removes DFL module for simpler export and broader hardware compatibility. Available across all YOLO26 sizes (n/s/m/l) for
MACHINE LEARNING
-
FourcastNet: NVIDIA’s AI Weather Forecasting Innovation Advances
By
–
In 2021 at @nvidia I led the release of FourcastNet the first fully AI based high resolution weather model. More than a year later @GoogleDeepMind released graphcast following our work. Proud to see further progress including FourCastNet 3 https://t.co/CC5YTXO6Ps
— Prof. Anima Anandkumar (@AnimaAnandkumar) 26 janvier 2026In 2021 at @nvidia I led the release of FourcastNet the first fully AI based high resolution weather model. More than a year later @GoogleDeepMind released graphcast following our work. Proud to see further progress including FourCastNet 3
-
NVIDIA Earth-2 Open Models Released for Climate AI
By
–
https://
huggingface.co/blog/nvidia/ea
rth-2-open-models
… -
Is Yann LeCun wrong about LLMs and AGI?
By
–
Is Yann LeCun wrong? And what is the path to AGI? Everyone is talking about Yann LeCun, his return to France, and the fact that he criticizes LLMs. But do you really know what he advocates technically? And above all: is he wrong or right?
-
12 prompts from Perplexity Pro replaced $500 research subscriptions
By
–
Perplexity Pro just became the best $20/month I spend. I use it for market research, trend analysis, and competitive intelligence. Here are 12 prompts that replaced my $500/month research subscriptions:
-
The challenge of model transparency and black box neural networks
By
–
Yeah, they open sourced it, but most of the work is done by a neural network and they didn't share the weights of that. So it's still 2/3rds a black box. And that black box is changing every month (I think it actually is changing faster than that).
-
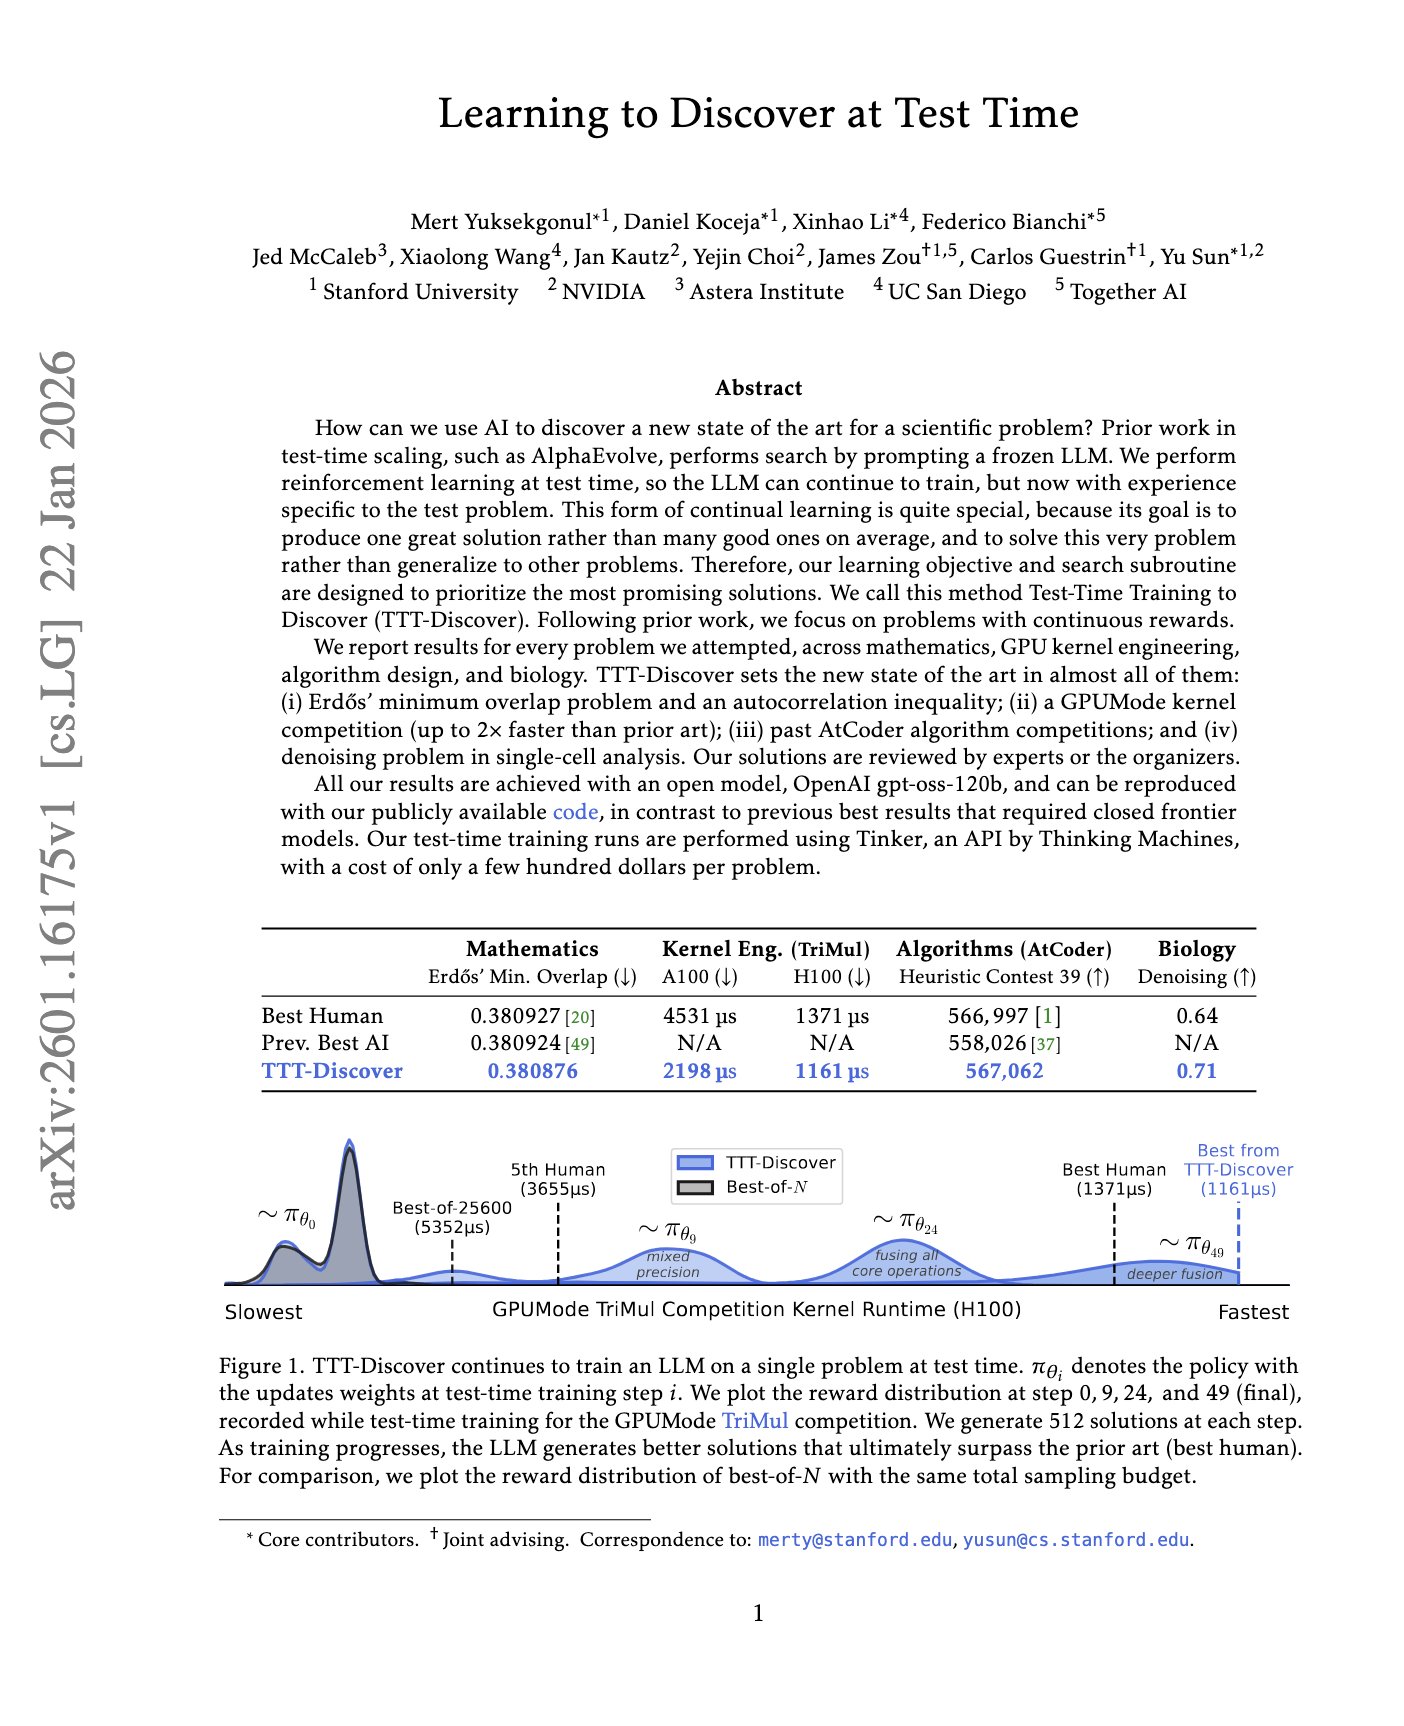
Test-Time Learning: RL Discovers Solutions During Inference
By
–
Learning to Discover at Test Time This paper TTT-Discover shows that by replacing best-of-N prompting with RL at test time on a continuous verifiable reward (via LoRA), it can learn from its own attempts and reliably push past the prior performance. The “learn-while-solving”
-
Humans and Machines Optimizing Reality Together
By
–
Humachineology aims to inspire creativity and innovation in shaping reality by optimizing the role of humans and machines.
-
Limitations of Intelligence: Laplace’s Gremlin and Irreducibility
By
–
New blog post on some of the intuitions I have on ways of describing limitations on intelligence. https://
inverseprobability.com/2026/01/25/lap
laces-gremlin-and-irreducibility
… It also links to a new arXiv paper that continues to look at the inaccessible game … a sandbox for idea formalisation. -
Programmer’s passion for the new AI-powered world
By
–
i always loved programming but am loving the new world even more