The complexity story is WILD: Standard attention: O(L²d) – quadratic scaling with sequence length
Grassmann mixing: O(Ld²) – LINEAR scaling (for fixed rank r) This isn't just theoretical. As sequences get longer, the gap becomes exponential.
MACHINE LEARNING
-

Attention quadratic vs Grassmann linear scaling complexity gap
By
–
-
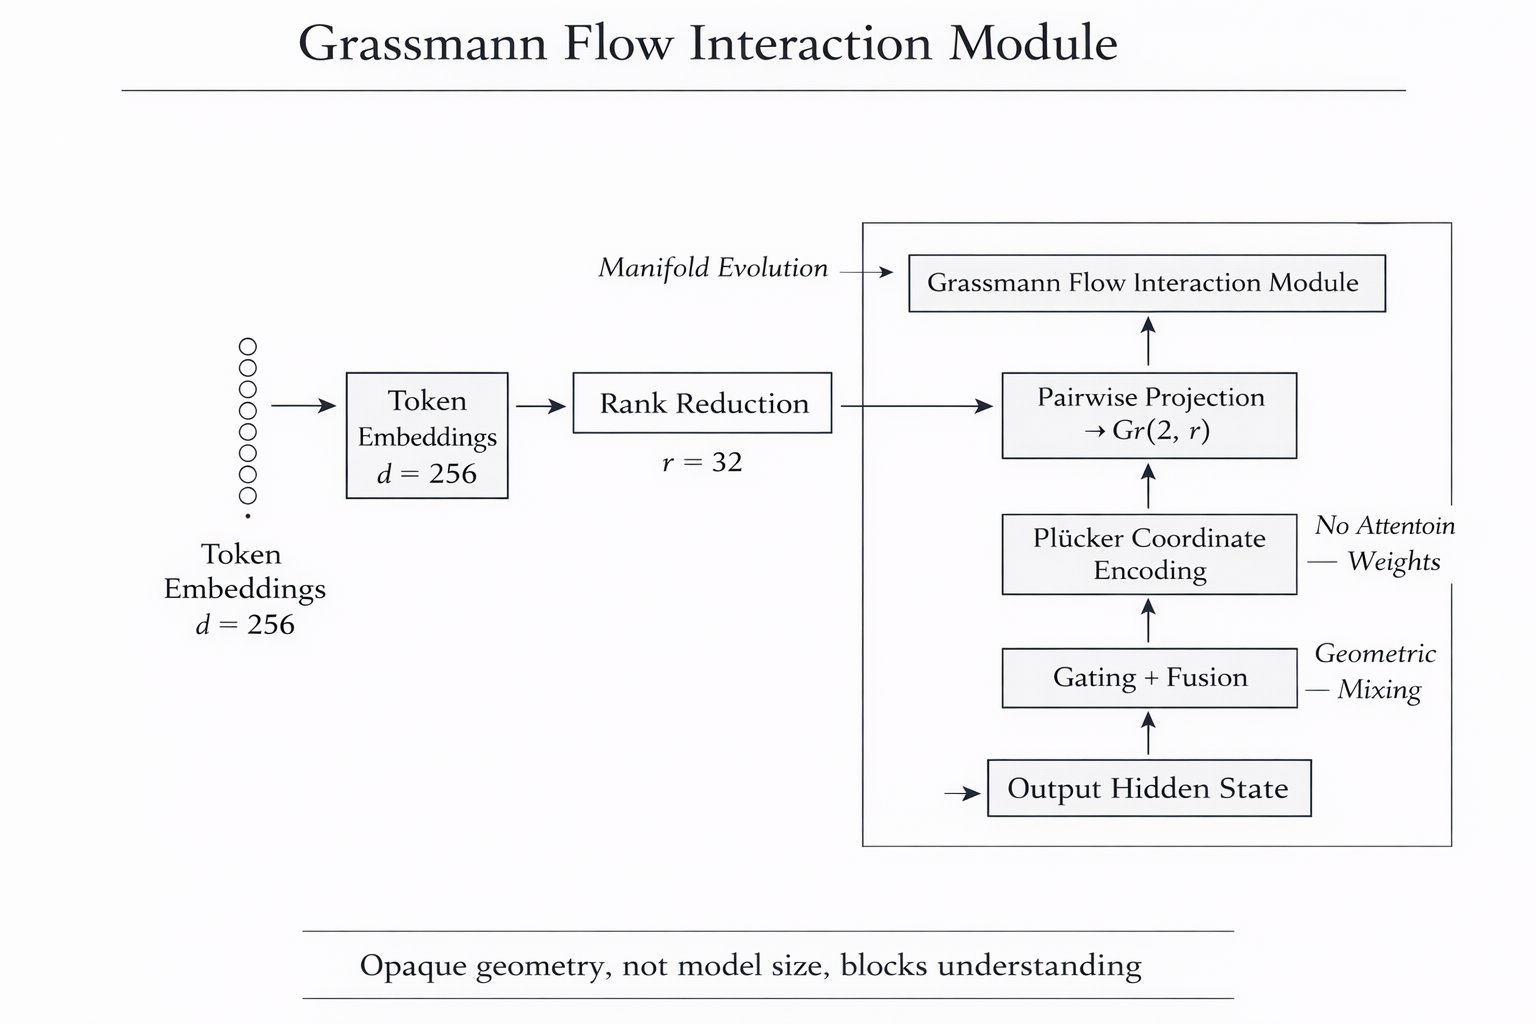
Grassmann flows replace attention with geometric evolution
By
–
The alternative is mathematically beautiful: Grassmann flows replace attention with controlled geometric evolution on a manifold. – Reduce hidden states to r=32 dimensions (from d=256)
– Encode token pairs as 2D subspaces on Gr(2,r)
– Use Plücker coordinates to create geometric -
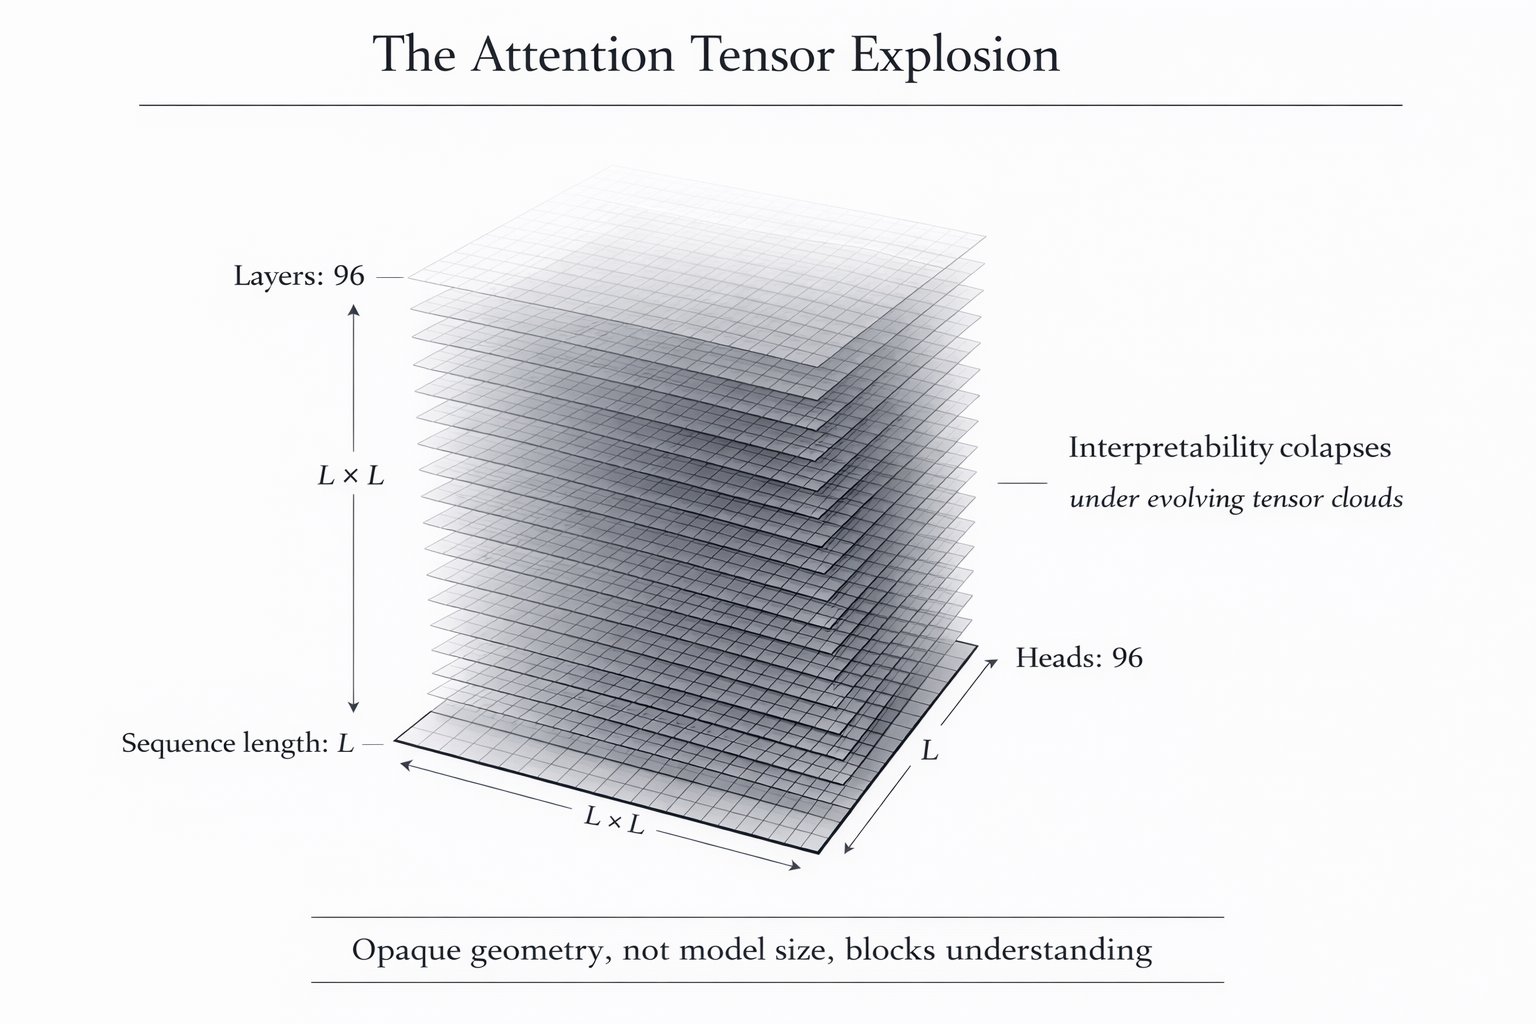
Massive attention matrices cause Transformer interpretability crisis
By
–
Here's the interpretability crisis no one talks about: Every Transformer layer creates an L×L attention matrix. Across 96 layers and 96 heads in GPT-4, that's a MASSIVE evolving tensor cloud. The paper proves this is why we can't interpret these models not their size, but their
-
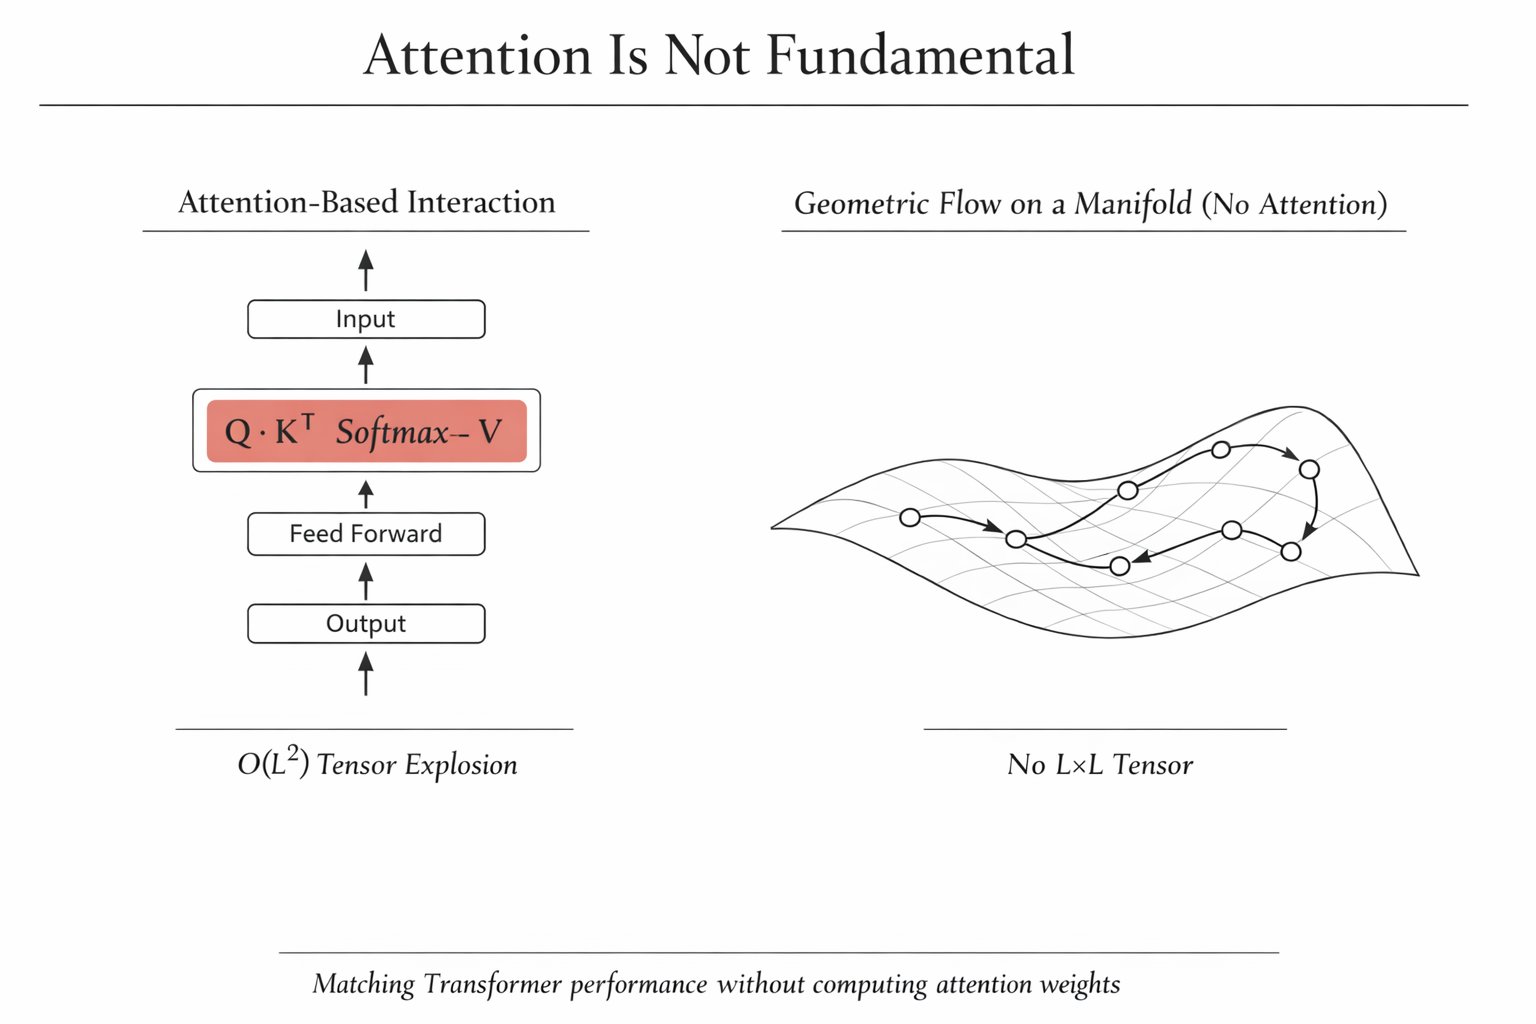
Transformer performance matched without computing attention weights
By
–
This paper just murdered the foundation of every AI model you've ever used. A researcher proved you can match Transformer performance WITHOUT computing a single attention weight. Here's what changed (and why this matters now):
-
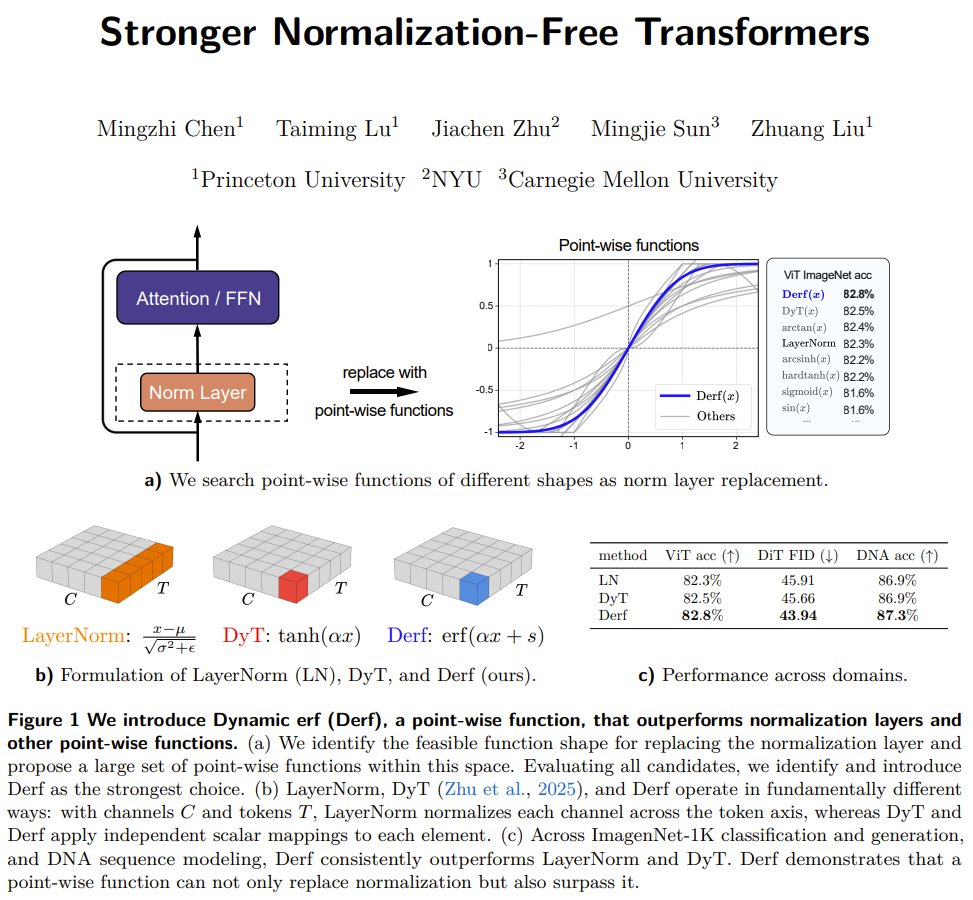
Derf: Replacing Transformer Normalization with Simpler Function
By
–
What if you could replace a core part of a Transformer with something simpler and stronger? Researchers from Princeton, NYU, and CMU present Derf. They swapped the standard "normalization" layer with a simple, element-by-element function called Derf (based on a Gaussian error
-
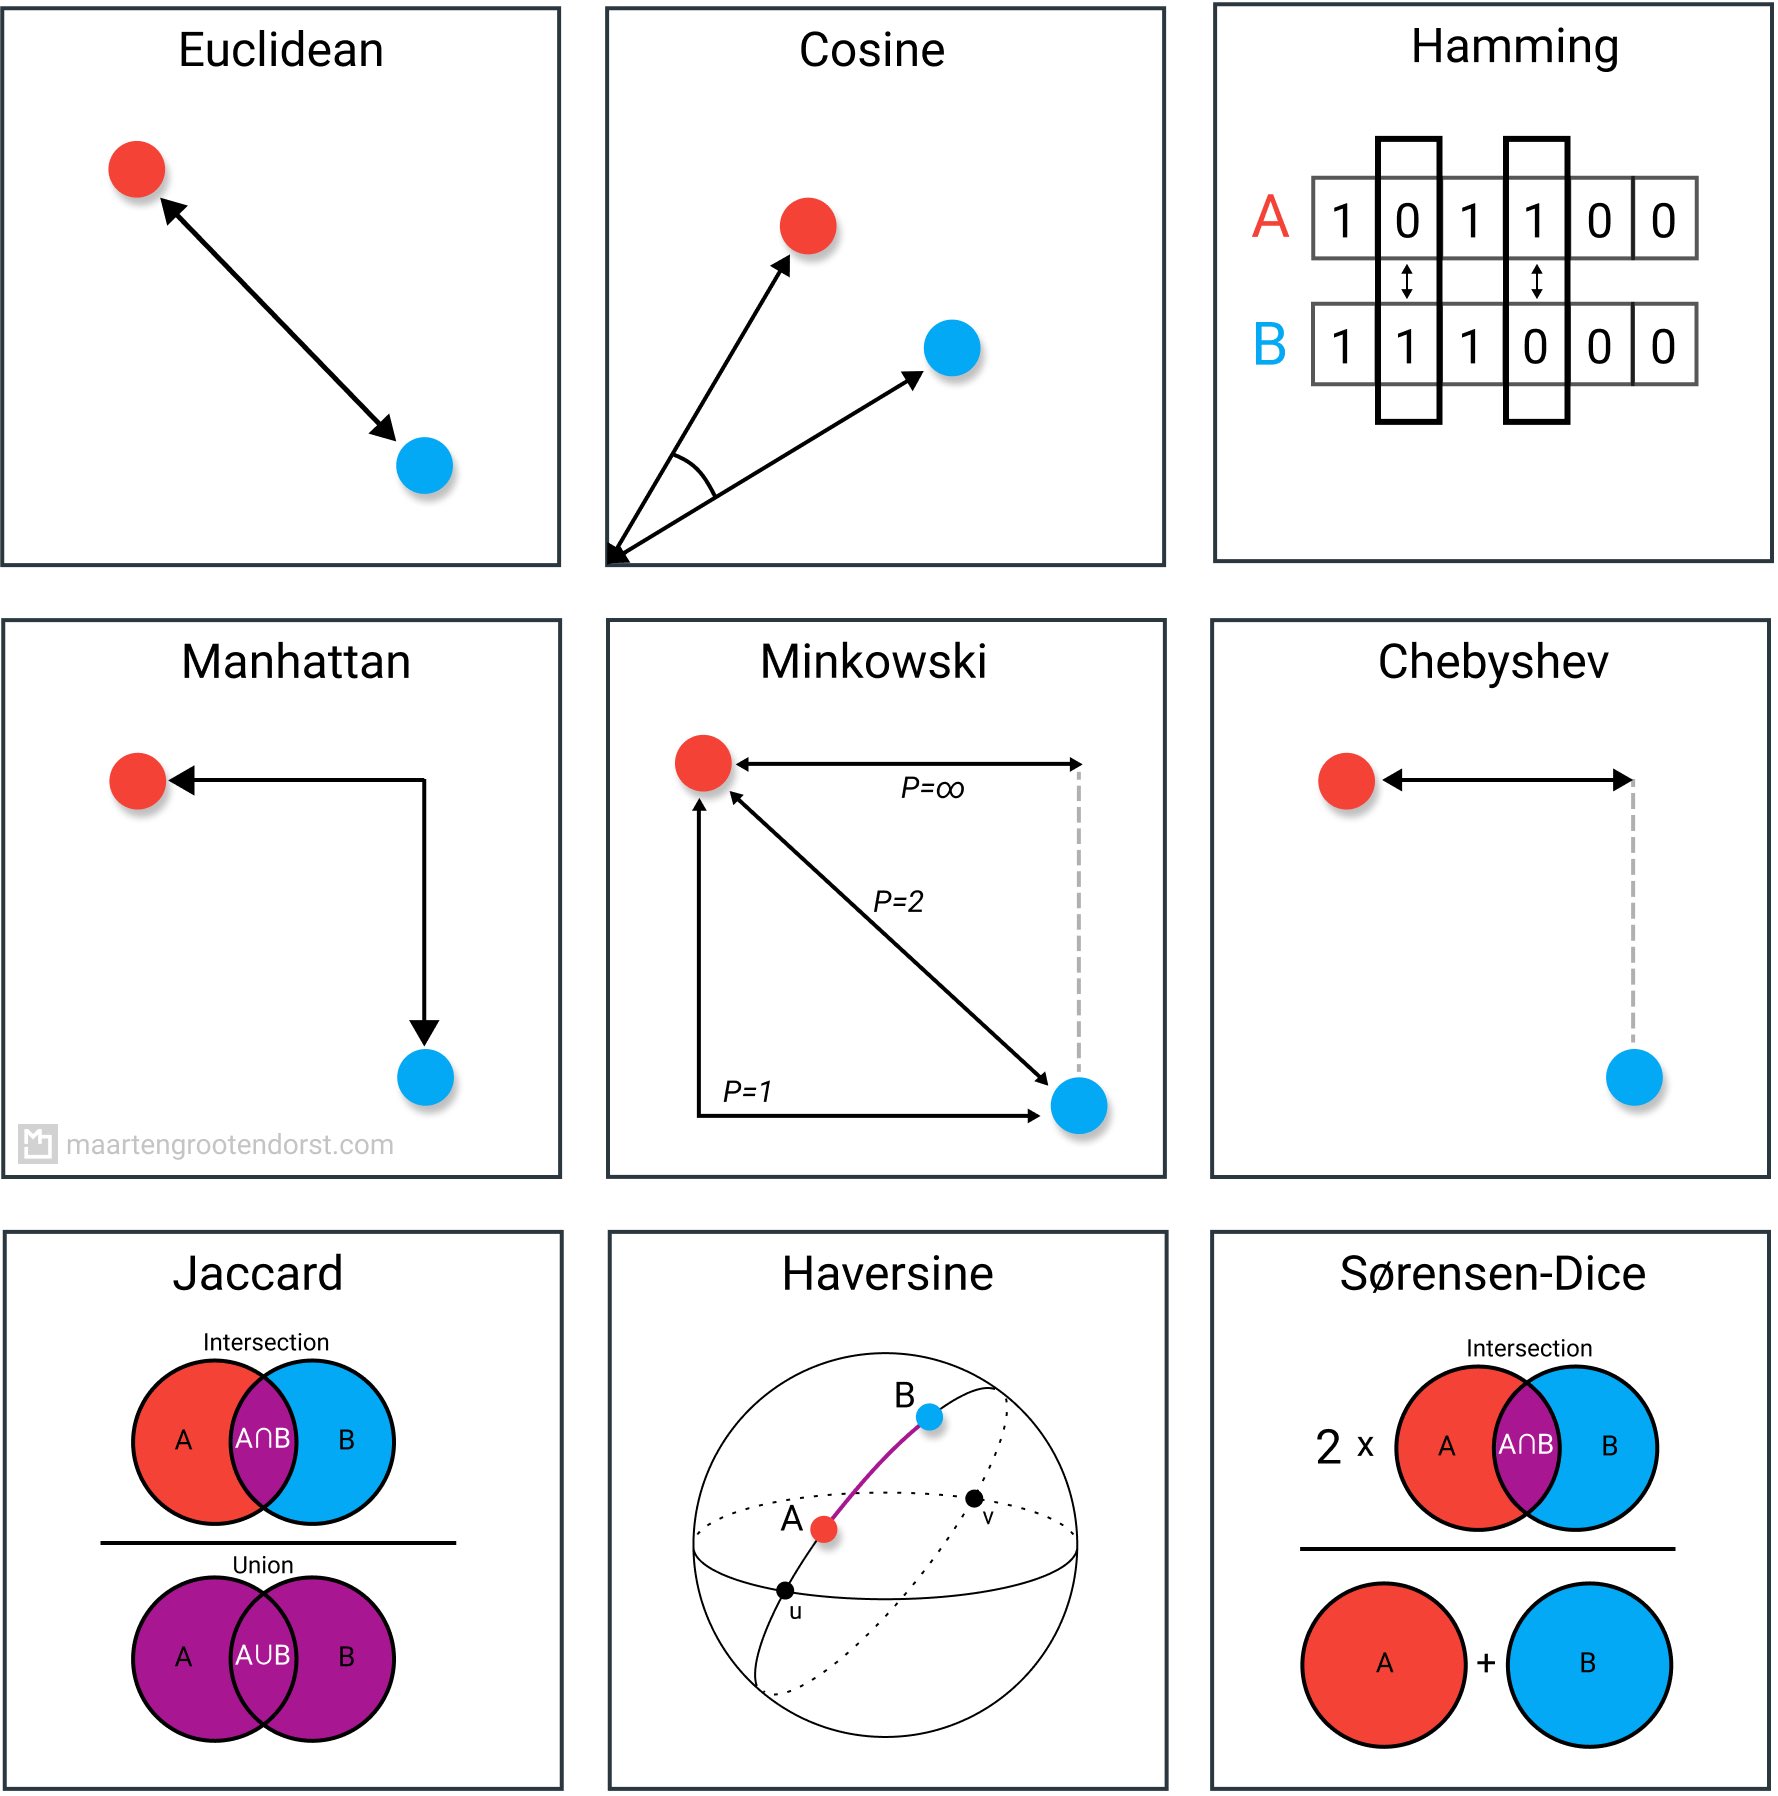
9 Distance Metrics for Machine Learning and Data Science
By
–
9 Distance Metrics used in #DataScience and #MachineLearning (advantages & pitfalls): https://
maartengrootendorst.com/blog/distances/
———
#AI #ML #Statistics #Mathematics #DataScientist #Algorithms
———
See 730+ page book "Encyclopedia of Distances" (3rd edition): http://
amzn.to/3skDOWm -
New Edition of Transformers and Generative AI Technical Guide
By
–
Very impressive! >> "Transformers for #NLProc and #ComputerVision: Explore #GenerativeAI and Large Language Models #LLMs with Hugging Face, GPT-4V, DALL-E 3,…" [3rd Edition] http://
amzn.to/3TkBknI
————
Huge, 728 pages of #AI #DeepLearning #MachineLearning #DataScience joy! -
State-of-the-art reinforcement learning algorithms replacing traditional methods
By
–
#PaperADay 11
Discovering state-of-the-art reinforcement learning algorithms https://nature.com/articles/s41586-025-09761-x
… The paper is about replacing the traditional RL target generation algorithms (policy gradient, GAE, TD-lambda, etc) that look at a sequential block of agent frame predictions -
Iterative Improvements and Error Correction in Neural Networks
By
–
It's a neural network. Every minor update fixed errors and got smoother. Do you want to admit to what errors they fixed? I wouldn't. "We retrained the system so it doesn't run red lights in a small community in Idaho."
-
Running R1 model locally requires significant memory
By
–
I’m waiting for them to release a 768 GB version so I can run full R1 model locally.