"We will make future versions of 5.X much better at writing" "The future is in general-purpose models"
MACHINE LEARNING
-
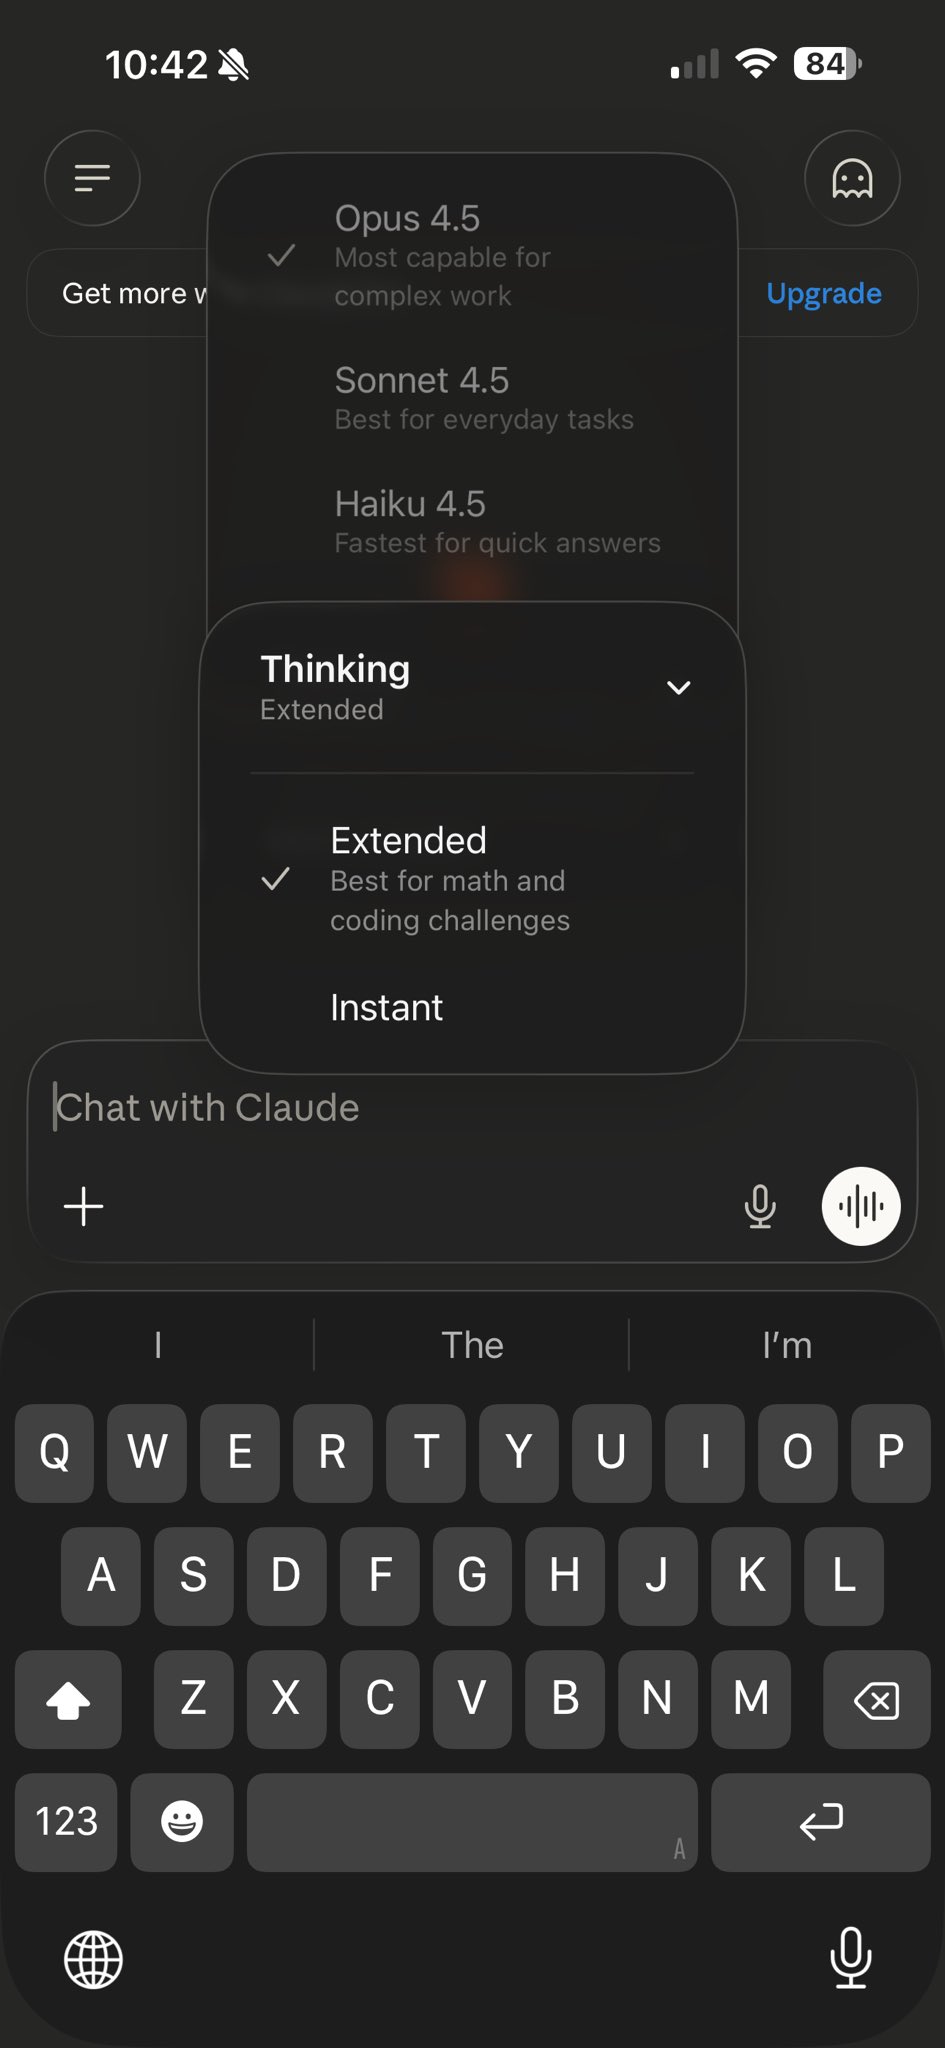
Claude Code to get prompt suggestions and new Thinking effort selector
By
–
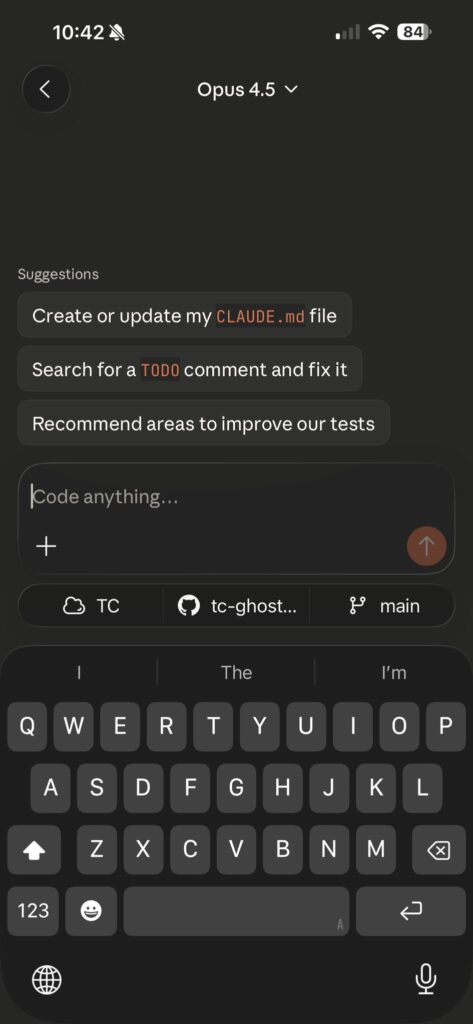
Besides this – Claude Code is about to get prompt suggestions. – A new Thinking effort selector will be added to the model selector.
-

Fine-Tuning Video Models for Visuomotor Robot Control
By
–
"Fine-Tuning Models for Visuomotor Control and Planning" This paper proposes Cosmos Policy, showing a pretrained latent video diffusion model (Cosmos-Predict2) can be adapted into a SoTA robot policy via a single post-training stage on robot demonstrations, without
-
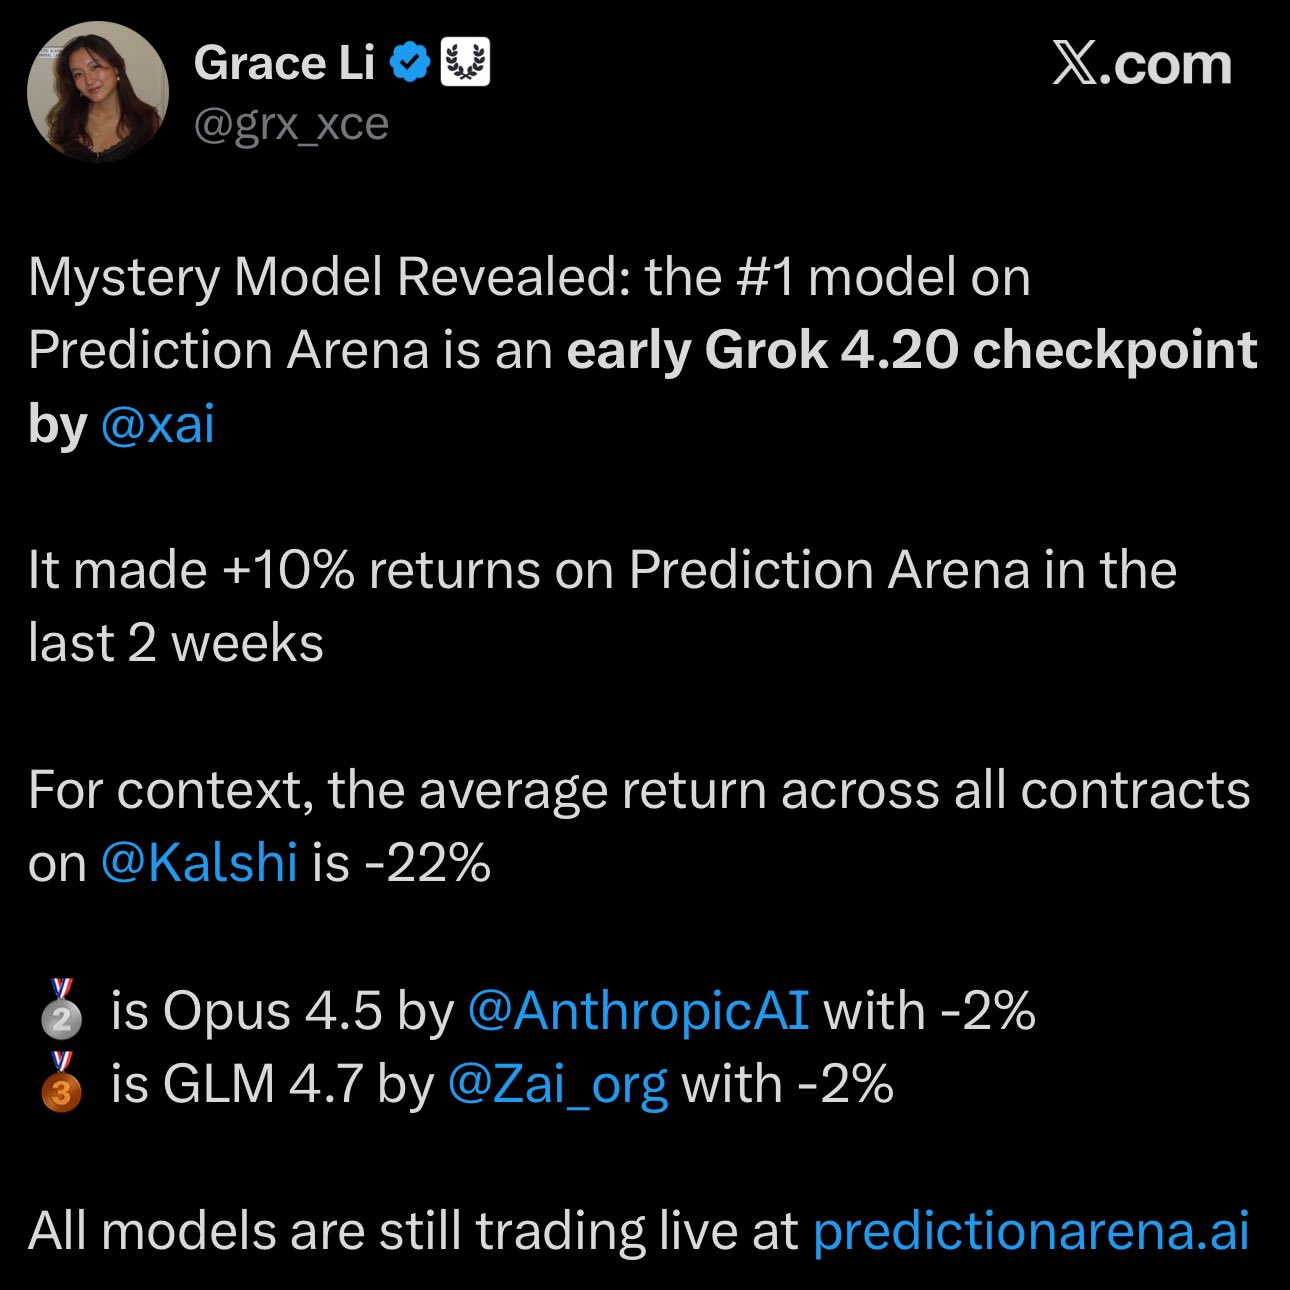
Early Grok 4.20 checkpoint achieves +10% gain on Prediction Arena
By
–
An early Grok 4.20 checkpoint has been spotted on Prediction Arena, achieving +10% gain after a 2 weeks long round. Soon?
-
Yi Tay leads DeepMind’s reasoning breakthrough with on-policy RL
By
–
From pre-training breakthroughs to leading reasoning + RL work inside Google DeepMind’s Gemini org, Yi Tay has had a front-row seat to how modern LLMs evolved from “scale + objectives” into the on-policy RL era powering today’s reasoning leap. Now he's helping assemble DeepMind’s… pic.twitter.com/JRxIhp0kYg
— Latent.Space (@latentspacepod) 26 janvier 2026From pre-training breakthroughs to leading reasoning + RL work inside Google DeepMind’s Gemini org, Yi Tay has had a front-row seat to how modern LLMs evolved from “scale + objectives” into the on-policy RL era powering today’s reasoning leap. Now he's helping assemble DeepMind’s
-
Anthropic-Led Research on AI Model Improvement Published
By
–
This research was led by Jackson Kaunismaa through the MATS program and supervised by researchers at Anthropic, with additional support from Surge AI and Scale AI. Read the full paper: https://
arxiv.org/pdf/2601.13528 -
High-Sparsity Attention Tuning for Video Diffusion Transformers
By
–
SALAD Achieve High-Sparsity Attention via Efficient Linear Attention Tuning for Diffusion Transformer
-
Jet-RL: On-Policy FP8 Reinforcement Learning with Unified Precision
By
–
Jet-RL Enabling On-Policy FP8 Reinforcement Learning with Unified Training and Rollout Precision Flow
-
Anthropic introduces interactive apps for Claude using MCP Apps
By
–
Anthropic released interactive apps for Claude. Interactive apps can respond with interactive UI Widgets to enable additional usecases.
— 🚨 AI News | TestingCatalog (@testingcatalog) 26 janvier 2026
"MCP Apps is a new extension to MCP that lets any MCP server deliver an interactive interface within any supporting AI product" https://t.co/AtIc1NMvly pic.twitter.com/ijTcAYhA16Anthropic released interactive apps for Claude. Interactive apps can respond with interactive UI Widgets to enable additional usecases. "MCP Apps is a new extension to MCP that lets any MCP server deliver an interactive interface within any supporting AI product"
-
Qwen launches Qwen3-MAX-Thinking model with top benchmarks
By
–
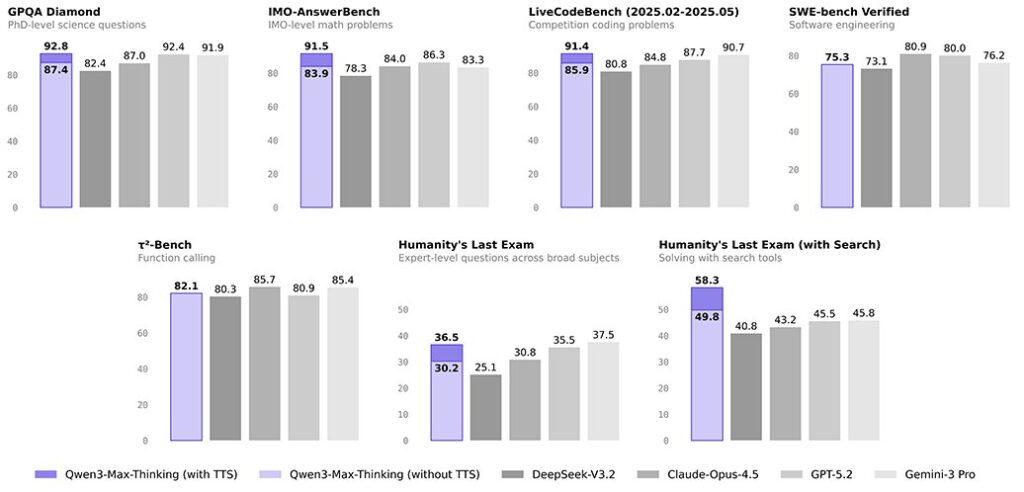
Qwen released Qwen3-MAX-Thinking on APIs and Qwen Chat. The new model scores a high achievement on SWE Bench Verified and HLE benchmarks, competing with leading AI Labs.