
If you found it insightful, reshare with your network. Find me → @akshay_pachaar For more insights and tutorials on LLMs, AI Agents, and Machine Learning!
MACHINE LEARNING
-
Custom AI Models for Domain Specific Applications Challenge
By
–
Designing the custom AI model for domain specific application is the hardest thing you will do.
-
Thumbtack Uses Fine-Tuned LLMs for Policy Violation Detection
By
–
.@thumbtack reviews tens of millions of messages each year to maintain marketplace trust while meeting strict privacy requirements.
— Databricks (@databricks) 20 février 2026
By unifying its GenAI workflows, the team fine-tuned LLMs to detect nuanced policy violations that rules alone couldn’t catch. Precision improved… pic.twitter.com/b9usmLCFfE.
@thumbtack reviews tens of millions of messages each year to maintain marketplace trust while meeting strict privacy requirements. By unifying its GenAI workflows, the team fine-tuned LLMs to detect nuanced policy violations that rules alone couldn’t catch. Precision improved -
AI Progress From Autocomplete to Compilers: Software Abundance Vision
By
–
I think this group of reactions are still fundamentally rooted in a scarcity mindset of software. 2 years ago AI was botching autocomplete, today it is almost one shotting browsers and C compilers. Where is it in 2 more? 10? 20? Software so insanely cheap and abundant that
-
Large MCED AI Trial Misses Primary Endpoint Despite Promise
By
–
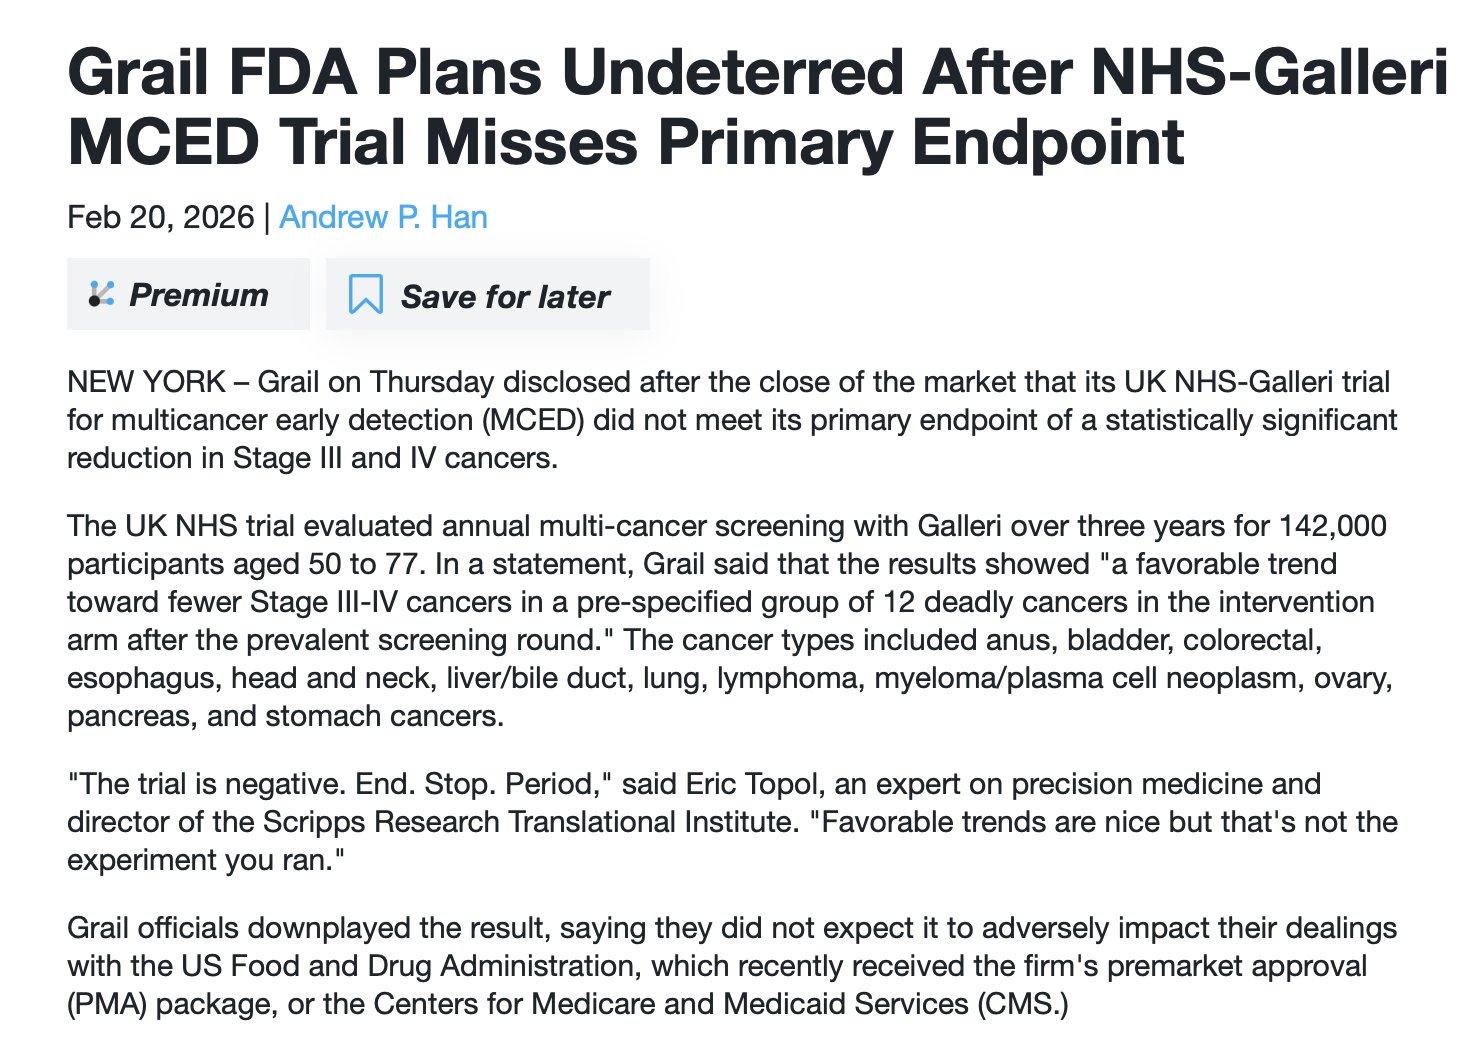
142,000 participants!
The largest randomized trial of a multi-cancer early detection (MCED) test failed its primary endpoint https://
genomeweb.com/cancer/grail-f
da-plans-undeterred-after-nhs-galleri-mced-trial-misses-primary-endpoint
…
Had the enrollment been risk-based instead of age 50, it would likely have been very positive. -
Joy Of Benchmarks Q1’26: AI Problem-Solving Creativity Focus
By
–
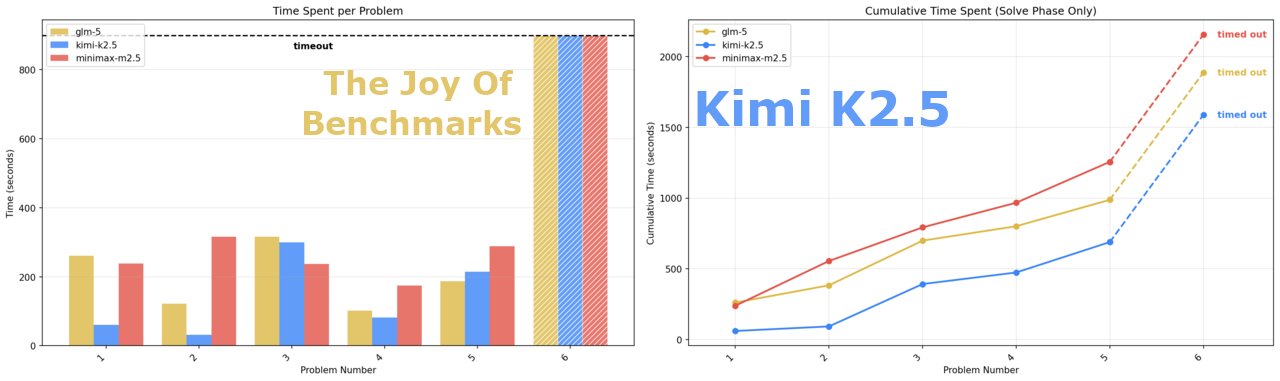
You know how AI benchmarks seem to measure intelligence on abstract problems, but then it turns out the models can't even think logically? This one instead focuses on problem solving creativity, not nerdy math… NEW: The Joy Of Benchmarks Q1'26 is out!
-
Abacus AI Wins ICLR 2025 Spotlight for LiveBench LLM Benchmark
By
–
Abacus AI just earned an ICLR 2025 Spotlight for LiveBench – the contamination-proof LLM benchmark that's becoming the gold standard for evaluating AI models. Real benchmarks for real progress. #AI #MachineLearning #OpenSource
-
TI-DPO: Gradient Attribution for Improved AI Model Training
By
–
What if your AI could ignore the noise and focus only on the words that actually matter for human preferences? Researchers from CASIA, ByteDance, and Microsoft Research introduce TI-DPO. This method moves beyond basic training by using gradient attribution to prioritize key
-
Data Scientists No Longer Needed as AI Model Intermediaries
By
–
The requirement for data scientists to act as intermediaries between businesses and AI models has disappeared. Two factors are driving this change. First, models have improved in precision and pattern recognition. Second, generative AI allows for natural language interaction.… pic.twitter.com/dn4hbQN3D4
— Lucian Fogoros (@fogoros) 20 février 2026The requirement for data scientists to act as intermediaries between businesses and AI models has disappeared. Two factors are driving this change. First, models have improved in precision and pattern recognition. Second, generative AI allows for natural language interaction.
-
AI Agent Index: 1350 Data Fields on 30 State-of-the-Art Systems
By
–
The AI Agent Index collected 1350 fields of information on 30 state-of-the-art systems. Check out the website for more findings & data: https://
bit.ly/4cDR0wl For questions or other inquiries, contact @StephenLCasper (scasper@mit.edu) & @LeonStaufer (lets2@cam.ac.uk).