The Molecular Structure of Thought: Mapping the Topology of Long Chain-of-Thought Reasoning Chen et al.: https://
arxiv.org/abs/2601.06002 #ArtificialIntelligence #DeepLearning #MachineLearning
MACHINE LEARNING
-
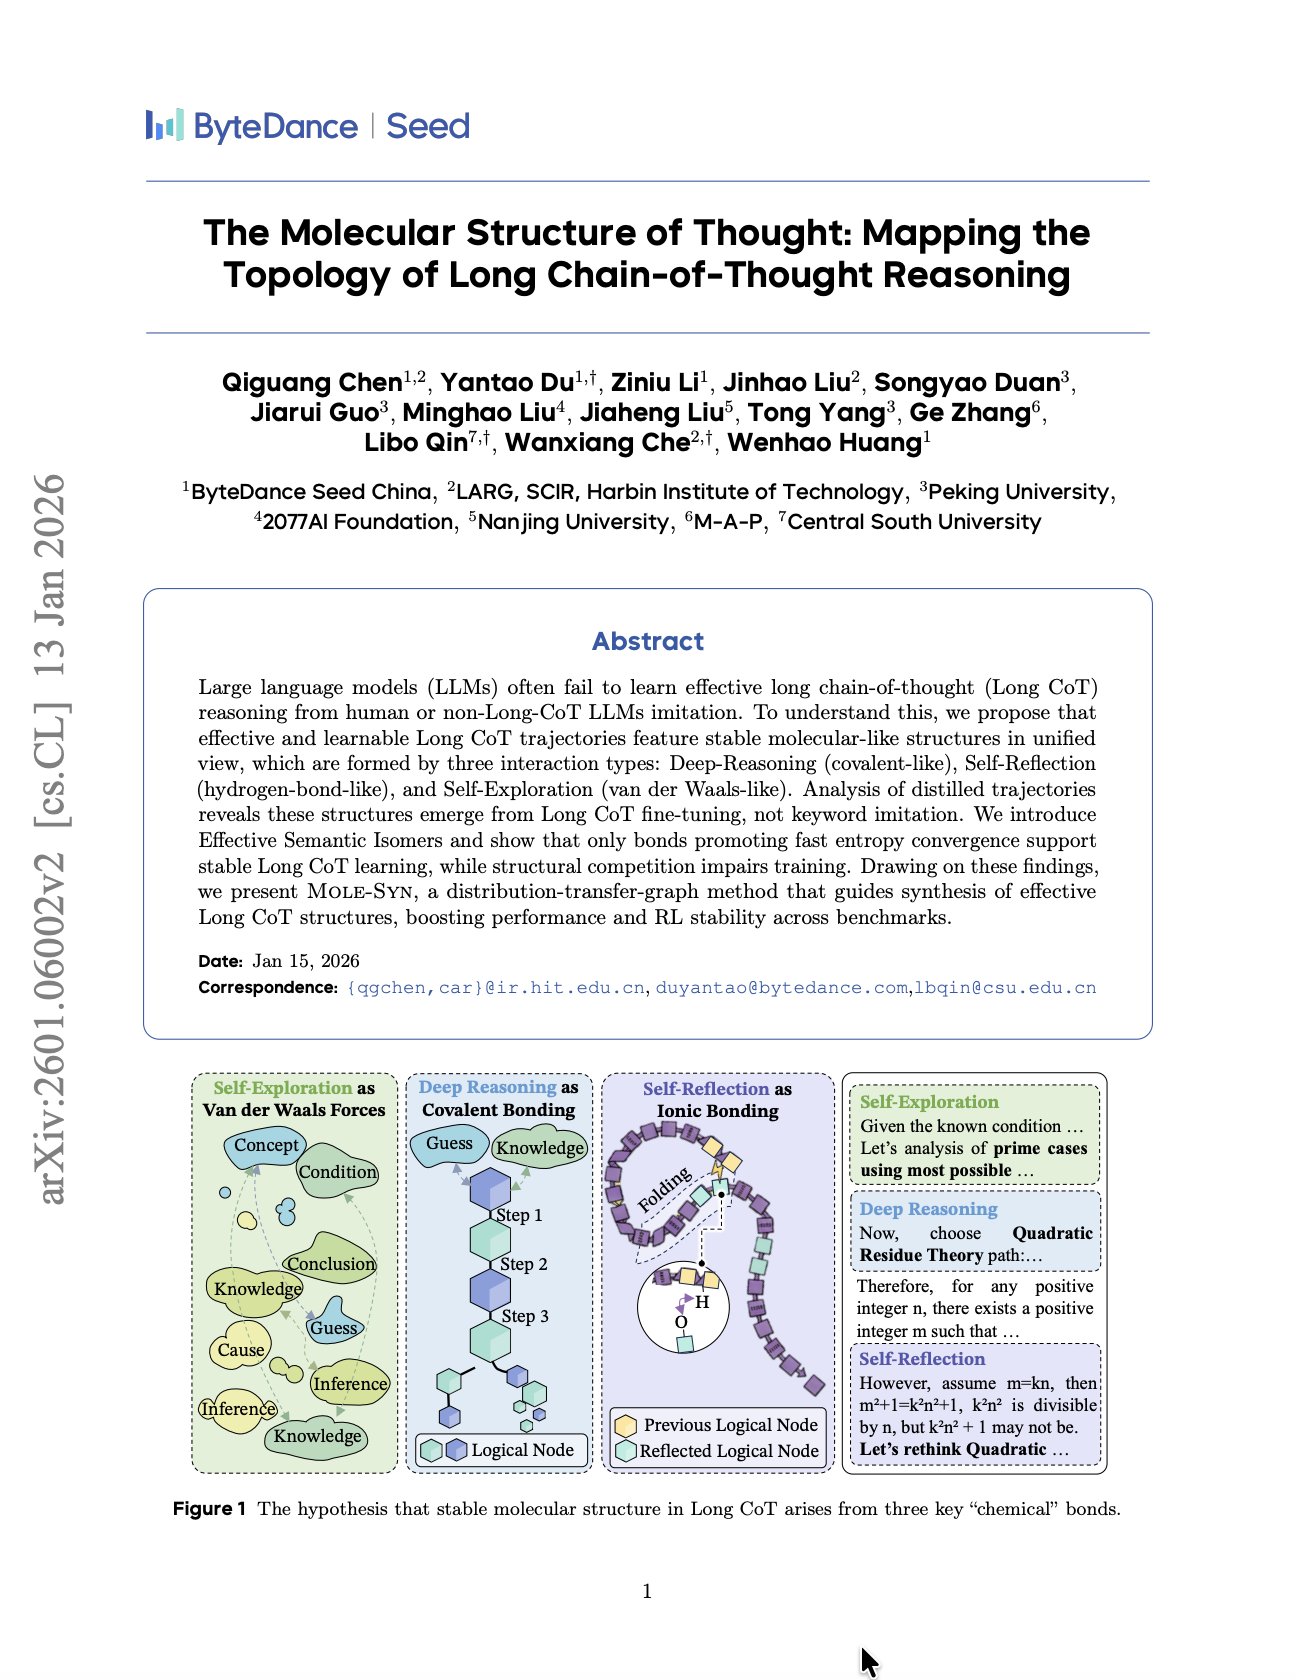
Molecular Structure of Thought: Mapping Long Chain-of-Thought Reasoning
By
–
-
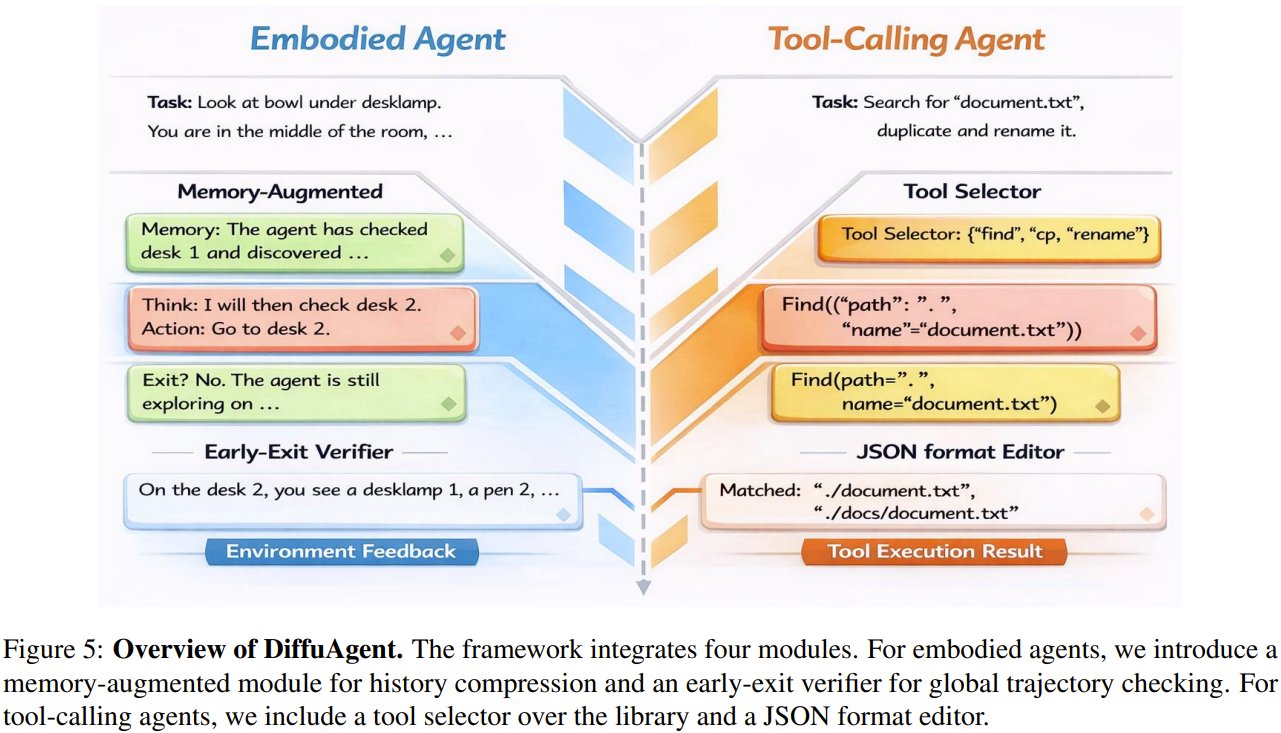
Can Diffusion Models Replace Traditional LLMs for Fast AI Agents?
By
–
Can diffusion models replace traditional LLMs to build lightning-fast AI agents? Researchers from Southeast University, Alibaba, and NTU Singapore just released a reality check on diffusion-based language models like LLaDA and Dream. They tested whether the speed of
-
Book Impact on Graph Databases and Linked Data Thinking
By
–
This book had a big impact on my thinking (graph databases, linked data, semantic knowledgebases, contextual metadata, connected IoT, context engineering, etc.): http://
amzn.to/4cBYJIi "Linked: How Everything is Connected to Everything Else — What It Means for Business, -
AI rendering replaces traditional clay dressing and set creation
By
–
No need to waste time on dressing your clay anymore, actually no need to even create the sets, just your primary model and some reference stills.
— Linus ✦ Ekenstam (@LinusEkenstam) 21 février 2026
This equates to when Portrait Painters got replaced by Photographers.
Hard earned skills rendered obsolete with one AI model drop https://t.co/2K8kzHLKxlNo need to waste time on dressing your clay anymore, actually no need to even create the sets, just your primary model and some reference stills. This equates to when Portrait Painters got replaced by Photographers. Hard earned skills rendered obsolete with one AI model drop
-
DeepSeek: fine-tuning, distillation, agents and prompt engineering
By
–
"DeepSeek in Practice: From basics to fine-tuning, distillation, agent design, and prompt engineering of open source LLM" via @PacktDataML at http://
amzn.to/4imbryH Discover DeepSeek's unique traits in the LLM landscape
Compare DeepSeek's multimodal features with leading -
Pretraining Vision and LLMs: Building Foundation Models on AWS
By
–
Pretrain Vision and #LLMs (Large Language Models) in #Python — Techniques for Building & Deploying Foundation Models on #AWS: http://
amzn.to/3pT9seD v/ @PacktDataML ————
#AI #MachineLearning #DeepLearning #MLOps #DataScience #ComputerVision #DataScientist #GenAI #GenerativeAI -
LangChain crash course for building OpenAI LLM-powered apps
By
–
#LangChain Crash Course — Fast track to building OpenAI LLM-powered Apps using #Python: http://
amzn.to/3TFlQJT
—————
#LLMs #AI #DeepLearning #GenerativeAI #ML #MachineLearning #LLMOps #DataScience #DataScientist -
Meta-Learning Approaches in Deep Learning: MAML Framework Discussion
By
–
Cool! I only had a quick sim earlier today but really enjoyed a number of ideas even unrelated to the claw part, esp around the skills system. In deep learning there were a number of meta learning approaches (Eg MAML paper in 2017) where the goal is to optimize for the model
-
Operating Systems Will Be Rebuilt Using Differentiable Programming
By
–
Prediction: we will end up rebuilding Operating Systems using automatically differentiable programming primitives. It won’t be a monumental task with LLMs, and it will lead to gradients back-propagating into the OS kernel. < 7 years.
→ View original post on X — @reza_zadeh, 2026-02-21 03:39 UTC
-

WAMs Replace VLAs: Video Models for Advanced Robot Manipulation
By
–
An elegant and simple pipeline Seonghyeon Ye (@SeonghyeonYe) VLAs (from VLMs) ❌ => WAMs (from Models) ✅ Why WAMs? 1️⃣ World Physics: VLMs know the internet, but Models implicitly model the physical laws essential for manipulation. 2️⃣ The "GPT Direction": VLAs are like BERT (rely heavily on task-specific post-training). WAMs are like GPT (pre-train & prompt), unlocking incredible zero-shot transfer! What I want to see in 2026: 📈 Scaling Laws: We will see much clearer scaling laws for robotics compared to VLAs. 🤝 Human-to-Robot Transfer: Unlocking massive transfer capabilities using video as a shared representation space. 🤖 Zero-Shot Mastery: Moving from short-horizon tasks to long-horizon, dexterous manipulation without task-specific demonstrations. We recently open-sourced the checkpoints, training and inference code. Dive into the research! 👇 📄 Paper: arxiv.org/abs/2602.15922 💻 Code: github.com/dreamzero0/dreamz… 🤗 HF: huggingface.co/GEAR-Dreams/D… — https://nitter.net/SeonghyeonYe/status/2024501978106061056#m
→ View original post on X — @shiqi_yang_147, 2026-02-21 03:30 UTC