Damn! Codex finished the task in 2 minutes. Claude Code took 30 minutes and failed.
→ View original post on X — @romainhuet, 2026-03-30 17:22 UTC
By
–
Damn! Codex finished the task in 2 minutes. Claude Code took 30 minutes and failed.
→ View original post on X — @romainhuet, 2026-03-30 17:22 UTC
By
–
Which models would you recommend for longer context tool calling? Are there any benchmarks for that which you find credible? I've not found a local model with tool calling good enough for me to trust with Claude Code or Codex, but I may not have been looking at the right options
By
–
What would a "theory" of machine learning tell us? Turing winner and Harvard Professor Leslie Valiant invented the widely accepted definition of supervised machine learning. Perspective, advice for new researchers and more on today’s episode! 📼YouTube: piped.video/xjwgk7jY6T8
→ View original post on X — @stanfordhai, 2026-03-30 16:52 UTC
By
–
We built a model that predicts multiple correlated outcomes simultaneously: portfolio risk, grid balancing, supply chains. In 10ms with no calibration required and it's 14% better than the best alternative. Check out the research: https://
arxiv.org/pdf/2603.20266
By
–
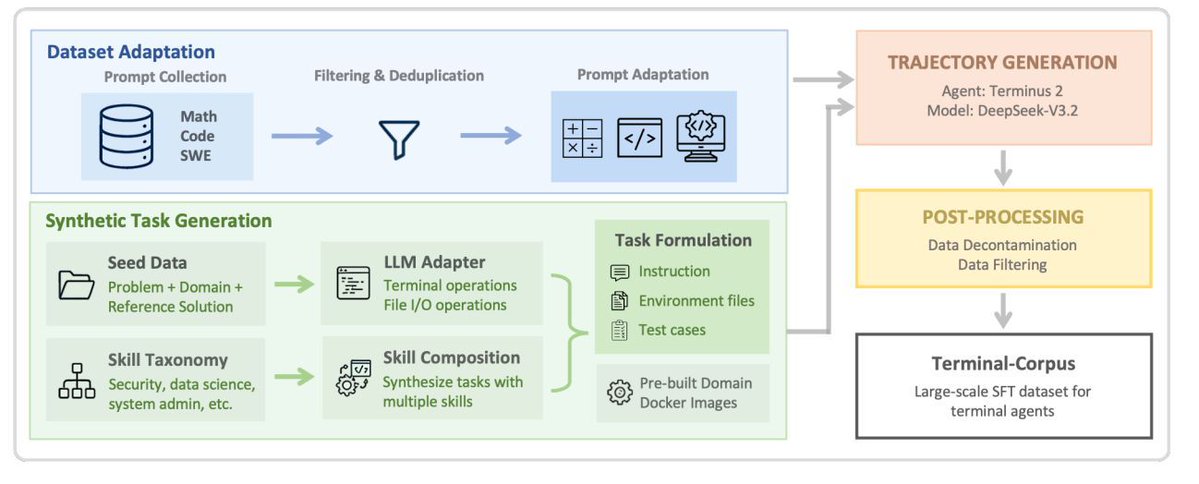
On Data Engineering for Scaling LLM Terminal Capabilities buff.ly/AKibXBi #AI #MachineLearning #DeepLearning #LLMs #DataScience
→ View original post on X — @miketamir, 2026-03-30 16:05 UTC
By
–
An introductory course about deep learning, courtesy of MIT: https://t.co/xlVPQUthXI pic.twitter.com/ry4auHQXd3
— MIT CSAIL (@MIT_CSAIL) 30 mars 2026
An introductory course about deep learning, courtesy of MIT: bit.ly/4in6rsJ
→ View original post on X — @mit_csail, 2026-03-30 16:00 UTC
By
–
That would only be true if the losses didn’t share any computation. I would think the far more common case of multiple losses would be regularizations on a shared set of layers, in which case splitting the loss backwards would still give the same result, but be early twice as
By
–
I'm not convinced LLMs can catch interesting deep patterns in their training data

By
–
// Coding Agents are Effective Long-Context Processors // We are just touching the surface of what's possible with coding agents. LLMs struggle with long contexts, even the ones that support massive context windows. It turns out coding agents already know how to solve this; you just need to reframe the problem. This work places massive text corpora into directory structures and lets off-the-shelf coding agents (Codex, Claude Code) navigate them with terminal commands and Python scripts. This is great, as you are not feeding massive text directly into a model’s context window or relying on semantic retrieval. Results: – On BrowseComp-Plus (750M tokens), this approach scores 88.5% vs 80% best published. – On Oolong-Real (385K tokens), 33.7% vs 24.1%, a 56% relative improvement. – GPT-5 full-context baseline only manages 20% on BrowseComp-Plus. Works up to 3 trillion tokens. Instead of scaling context windows or building retrieval pipelines, coding agents that already know how to navigate file systems can process virtually unlimited context. The agents autonomously develop task-specific strategies: writing scripts, iterative query refinement, and programmatic aggregation. Paper: arxiv.org/abs/2603.20432 Learn to build effective AI agents in our academy: academy.dair.ai/

By
–
Okay LLM + PyTorch people, trunc_normal_, what the fuck! Many LLM inits use it w/ default cutoffs. It's either not doing anything or it's quite broken due 2 issues. 1. The a/b cutoffs in PyTorch are not in std-devs, they are absolute. So w/ a std=0.02, and -2/2 (default arg) cutoffs that's 100σ!! That is a normal distribution, trun isn't doing anything. 2. There are numerical issues. Even in float32, the truncation produces a handful of -2 (lower cutoff) values, 100σ!! That's incomprehensibly improbable. I doubt a float32 or even float64 algo could even produce it, but clamping a bad float value does. Olmo (@allenai codebases) appear to be one of the few that uses trunc_normal_ and bothered to set the cutoffs properly. It'd be nice to see more train code opened up as a default. We so often only end up with a sanitized version of the inference/fine-tune friendly model these days and may lose details like original init. I've known about #1 for ages, I have an alternate trunc_normal_tf_ implementation in timm for that reason. But I saw those -2's last week when I was debugging something and was a little surprised.
→ View original post on X — @jeremyphoward, 2026-03-30 15:09 UTC