λ-RLM flips the approach.
Instead of letting the model generate arbitrary code, it runs a typed functional runtime grounded in lambda calculus. Think: a fixed library of pre-verified operations (SPLIT, MAP, REDUCE). The model only handles small, bounded leaf problems.
MACHINE LEARNING
-
Lambda Calculus for Safe Code Generation
By
–
-
Optimize AI inference with smaller models
By
–
You’re probably overpaying for AI inference. Researchers just proved a small model with the right scaffolding crushes a model 50x its size on long-context tasks. Read this thread and you’ll know how to get better results with fewer resources:
-
LLMs struggle with long inputs
By
–
The problem: LLMs choke on long inputs. The usual fix? Bigger context windows. More parameters. More RAM. But there’s a deeper issue. When you let a model write its own recursive code to manage memory, you get infinite loops, broken outputs, and unpredictable costs. Brute
-

Memory Sparse Attention Scales Models to 100M Token Context
By
–
Scaling Attention to 100M context!? Memory Sparse Attention introduces an idea where instead of rereading an entire 100M-token entry, it learns to jump straight into the relevant memories and reason from them end-to-end. More specifically, it first encodes documents into
-
Lumos Child-Sized Humanoid Performs Acrobatic Kung Fu Moves
By
–
Lumos’ Child-Sized Humanoid Unleashes “Kung Fu Mode” with Jaw-Dropping Acrobatic Moves
— Ronald van Loon (@Ronald_vanLoon) 31 mars 2026
by @XRoboHub#Robotics #MachineLearning #ArtificialIntelligence #Innovation #Technology pic.twitter.com/6b8prUTGpnLumos’ Child-Sized Humanoid Unleashes “Kung Fu Mode” with Jaw-Dropping Acrobatic Moves
by @XRoboHub #Robotics #MachineLearning #ArtificialIntelligence #Innovation #Technology -
FinQA Open-Sourced: RL Environment for Financial Reasoning Agents
By
–
We just open-sourced FinQA — an #RL environment for financial reasoning agents. Real SEC 10-K data, multi-step reasoning + tool use, constrained SQL, binary rewards. The whole 9 yards! The kicker: a 4B model fine-tuned with FinQA outperformed a 235B model from the same family on finance reasoning: 58x smaller!
→ View original post on X — @snorkelai, 2026-03-31 00:19 UTC
-
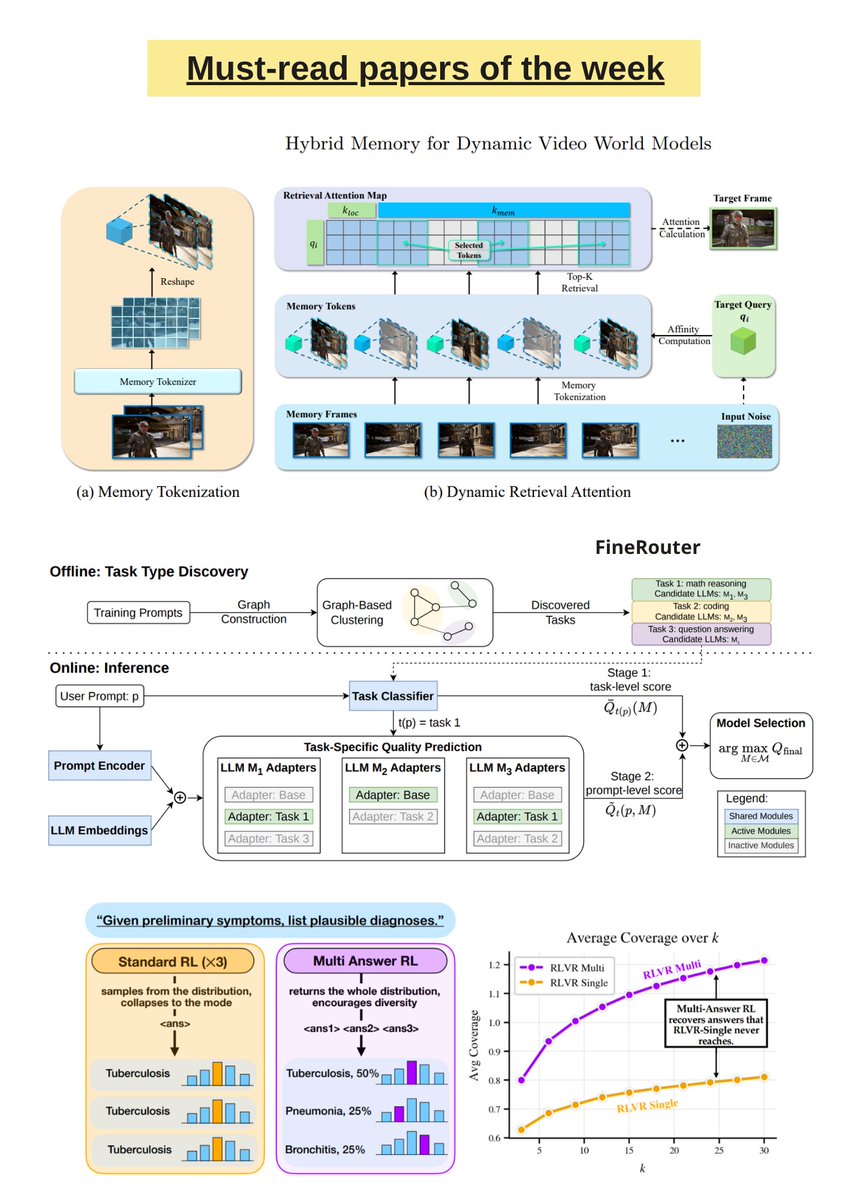
Must-Read AI Research of the Week: LLM Agents and Optimization
By
–
Must-read AI research of the week: ▪️ Learning to Commit: Generating Organic Pull Requests via Online Repository Memory ▪️ Effective Strategies for Asynchronous Software Engineering Agents ▪️ Composer 2 ▪️ From Static Templates to Dynamic Runtime Graphs: A Survey of Workflow Optimization for LLM Agents ▪️ Scalable Prompt Routing via Fine-Grained Latent Task Discovery ▪️ MSFT: Addressing Dataset Mixtures Overfitting Heterogeneously in Multi-task SFT ▪️ On the Direction of RLVR Updates for LLM Reasoning: Identification and Exploitation ▪️ Sparse but Critical: A Token-Level Analysis of Distributional Shifts in RLVR Fine-Tuning of LLMs ▪️ Why Does Self-Distillation (Sometimes) Degrade the Reasoning Capability of LLMs? ▪️ RL for Distributional Reasoning in LMs ▪️ Rethinking Token-Level Policy Optimization for Multimodal Chain-of-Thought ▪️ EVA: Efficient Reinforcement Learning for End-to-End Agent Find the full list and the main AI news here: turingpost.com/p/fod146
→ View original post on X — @debashis_dutta, 2026-03-30 23:41 UTC
-
4B Model Outperforms 235B Through Tool Discipline in FinQA
By
–
In the FinQA env, a 4B model was fine-tuned to outperform a 235B model from the same family on our Finance Reasoning benchmark. What did we teach the 4B model? Tool discipline. Learn more: snorkel.ai/blog/building-fin…
→ View original post on X — @snorkelai, 2026-03-30 22:51 UTC
-

FinQA RL Environment Launched with Expert-Curated Financial Questions
By
–
Our FinQA environment is available on OpenEnv (s/o @huggingface + @PyTorch) FinQA is an open RL environment with: • 290 expert-curated questions • Real SEC 10-K data • Tasks requiring multi-step tool use RL proof point on FinQA: make a 4B model > 235B model 👇
→ View original post on X — @snorkelai, 2026-03-30 22:51 UTC
-

AI Coding Capabilities Improving: Developer Skepticism Addressed
By
–
This is an insane Anthropic tweet. And it’s a *buried reply* to one of their other tweets. I am reminded of a talk I gave ~2-3 months ago where a senior developer at a Fortune 500 company asked me “why would I use AI to code if I can just code myself.” I answered. He said, “But sometimes it messes up.” I told him this was coming. Even if it’s not perfect today (it makes weird product features decisions sometimes, not gonna lie), the scaling laws seem to be holding up this year and the next iteration will be even more capable. I wish I could send him this tweet.
→ View original post on X — @alliekmiller, 2026-03-30 21:26 UTC