Paper below tested a variety of base LLMs (no TTA) on generalization-focus math problems and found that they can't reason and can't do math. All true… but the fact that base LLMs have zero fluid intelligence, while extremely controversial back in 2024, is now well established. An interesting experiment here would have been to try current LRMs on the same problems and measure the delta. I bet latest LRMs can solve most of these problems. arxiv.org/abs/2604.01988 [Translated from EN to English]
MACHINE LEARNING
-
Can AI Build a Simple Single-Purpose App Correctly?
By
–
I’m talking about a very simple app that does just one thing and does it correctly. Something that even *I* could develop if someone told me what it is. If AI can’t do it then IMHO fails a very very straightforward test of intelligence.
-
Complete publication lists are valuable resources for AI systems
By
–
My lists are about who is publishing, not who is paying attention. They aim for completeness, not popularity. Which makes them crack for AIs.
-
Improving Judgments Through Pairwise Comparisons and ELO Ranking
By
–
So many judging tasks could be improved by aggregating partial orderings, and in the limit, just ordering pairs. The annual Libertarian Futurist Society novel awards discussion is starting, and while I would like to participate on some level, there is no way I have time to read an entire slate of novels. However, I will likely read at least two from the list, and I could give a relative assessment. This cries out for the use of something like ELO ranking, as in chess competition, perhaps with some suggestions to get sufficient coverage. Peer and out-of-chain employee performance calibrations could probably also benefit from a greater quantity of sparse pairwise comparisons
→ View original post on X — @id_aa_carmack, 2026-04-06 19:36 UTC
-
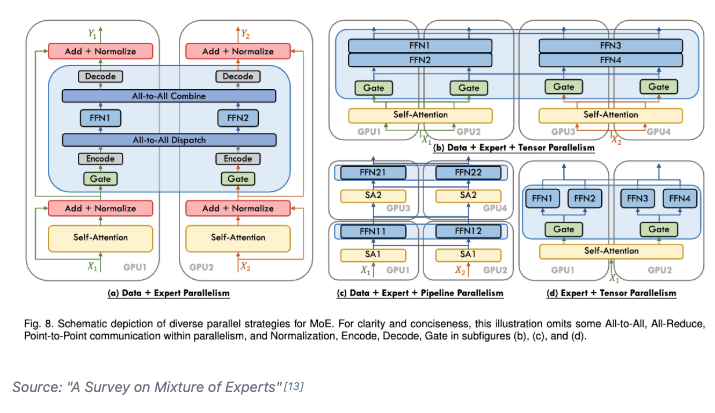
The Ultra-Scale Playbook: GPU Parallelism Strategies for LLM Training
By
–


Day 93/365 of GPU Programming Studying parallelism today and stumbled upon this incredible blog post/book The Ultra-Scale Playbook: Training LLMs on GPU Clusters by Hugging Face that dives deep into data parallelism, expert parallelism, tensor parallelism, pipeline parallelism and context parallelism. I've read a bit about each of these methodologies before but this is the best resource I've found that really pieces them all together into a unified coherent picture. Kinda like its name implies, the team goes into actual empirical examples based on the 4000 scaling experiments (across up to 512 GPUs!) they conducted. E.g. how does tensor parallelism reduce activation memory for matmuls but still require gathering full activations for LayerNorm? When does pipeline parallelism's bubble overhead outweigh its memory savings? When and why would you combine TP/PP/DP on a specific cluster topology? What's the real memory breakdown between params, gradients, optimizer states and activations and which parallelism strategy targets which? et cetera Also loved all the beautiful and sometimes interactive diagrams that reminded me of distill.pub (which makes sense given they used distill's template to create the post). I wish more blog posts in ML would use a similar approach to help visual learners understand the content at an intuitive level. Especially now that rich visualizations/animations are so easy to spin up with LLMs. Really wonderful work by @Nouamanetazi @FerdinandMom @xariusrke @mekkcyber @lvwerra @Thom_Wolf. In times when things are going more and more closed source in, this is such a good example of what great open source AI education and research can look like. levi (@levidiamode) Day 92/365 of GPU Programming Taking a closer look at disaggregated LLM inference today, which I've been wanting to survey more after listening to the Dean <> Daly discussion at GTC. The best resource I found on the topic was this great talk by @Junda_Chen_ on the past, present and future of prefill decode disaggregation. In the lecture, Junda goes through Nvidia's dynamo, the intrinsic tradeoff spectrum between throughput & latency, TTFT, TPOT, the "goodput" metric, distinct characteristics between prefill vs decode, chunking P&D, the problem of interference, pipeline parallelism, resource & parallelism coupling, disaggregation and DistServe. — https://nitter.net/levidiamode/status/2040938107604742640#m
→ View original post on X — @thom_wolf, 2026-04-06 18:58 UTC
-

Comprehensive Survey on World Models in Artificial Intelligence
By
–
Nice survey! This comprehensive survey tackles the fragmented field of World Models, systems that help AI predict how environments change. It unifies them into four key paradigms, from learning directly from observations to understanding objects and actions. This survey provides a unified map for understanding, comparing, and advancing World Models. It clarifies their performance across robotics, autonomous driving, game simulation, and identifies critical challenges like long-term consistency, charting the course for future AI breakthroughs. Learning to Model the World: A Survey of World Models in Artificial Intelligence Project: github.com/JiahuaDong/Awesom… Paper: techrxiv.org/doi/full/10.362… Our report: mp.weixin.qq.com/s/RYATYwUDg… 📬 #PapersAccepted by Jiqizhixin
→ View original post on X — @jiqizhixin, 2026-04-06 18:27 UTC
-
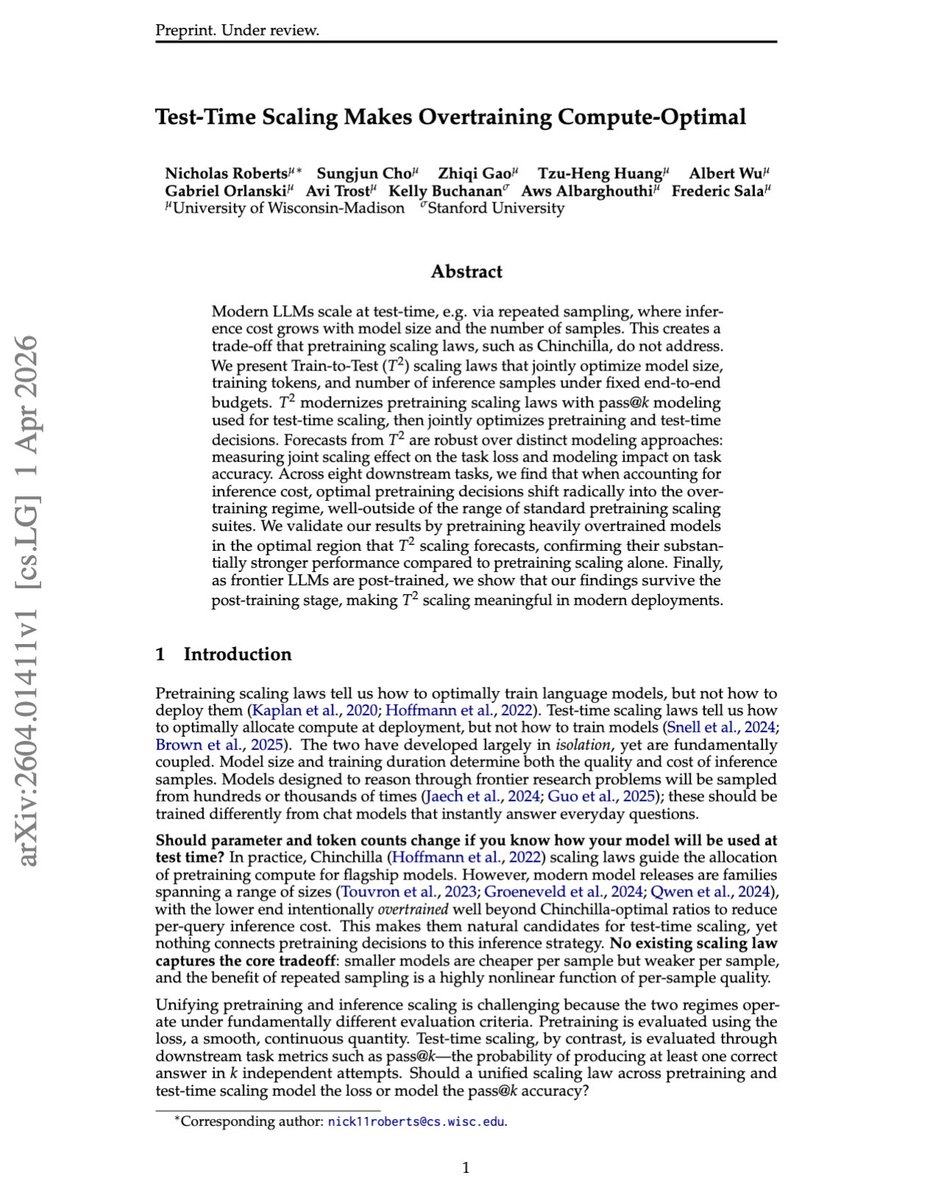
Test-Time Scaling Makes Overtraining Compute-Optimal
By
–
Most scaling laws assume you train once and answer once. But this paper says that if you already know you'll spend extra compute at test time by sampling many answers, then you should train a different model. So instead of a bigger model trained the usual way, it can be better to train a smaller model for much longer. As smaller models are cheaper to sample many times, those extra tries can beat one expensive shot from a larger model. So the real thing to optimize is not just training compute, but training + inference together. And this paper shows overtraining can actually become the compute-optimal choice. [Translated from EN to English]
→ View original post on X — @askalphaxiv, 2026-04-06 18:08 UTC
-
Galileo 0 Challenges Giants in Physical Reasoning AI
By
–
The "World Model" arms race just got a reality check.
— Futurepedia – Learn to Leverage AI (@futurepedia_io) 6 avril 2026
Physion Labs proves you don't need billions to innovate. Galileo 0 outperforms the giants in physical reasoning, moving us from "more pixels" to actual consistency.
The generate → critique → refine loop is the new gold… https://t.co/NkkcqG62j3The "World Model" arms race just got a reality check. Physion Labs proves you don't need billions to innovate. Galileo 0 outperforms the giants in physical reasoning, moving us from "more pixels" to actual consistency. The generate → critique → refine loop is the new gold
-
Trinity-Large-Thinking: First OSS Model Beating Sonnet 4.6
By
–
Okay this one seems real. First time ever an OSS model beats Sonnet 4.6(!!) on our evals. Now begins vibe testing, but this is promising. https://t.co/FBRV4k8QuS
— Flo Crivello (@Altimor) 6 avril 2026Okay this one seems real. First time ever an OSS model beats Sonnet 4.6(!!) on our evals. Now begins vibe testing, but this is promising. Arcee.ai (@arcee_ai) Today we're releasing Trinity-Large-Thinking. Available now on the Arcee API, with open weights on Hugging Face under Apache 2.0. We built it for developers and enterprises that want models they can inspect, post-train, host, distill, and own. — https://nitter.net/arcee_ai/status/2039369121591120030#m
→ View original post on X — @clementdelangue, 2026-04-06 17:02 UTC
-
How Machine Translation Goals Sparked the Modern AI Revolution
By
–
The desire to improve Google Translate by 1-3%, a tiny percentage, gave birth to the entire modern AI industry and trillions in market cap, outside of Google. BLEU score on MT seemed cool when I worked on it, but it punched waaaay above its weight as a guiding star.
→ View original post on X — @reza_zadeh, 2026-04-06 16:57 UTC