T-Rex introduces a new set of basis hand motions to learn tactile responses:
MACHINE LEARNING
-
Generative media break visual Turing test: hope for truce
By
–
Sigh. Unfortunately, it will only get worse as generative media shatter the visual Turing test. I hope that internal quarrels between traditional and neural computer graphics will cease.
-
ColBERT outperforms on CPU with low latency for embeddings
By
–
I'm talking about individual descriptions used for embeddings. It doesn't need to be particularly long for late interaction to perform better. The tradeoff really depends on the use case. In this case, even on a cheap CPU, the latency is so low that ColBERT just works better!
-

Comparison of LLM, RAG, AIAgent, and MCP
By
–
#LLM vs. RAG vs. #AIAgent vs. MCP
by @Python_Dv #GenerativeAI #ArtificialIntelligence #MachineLearning #ML -
PixelRAG skips OCR by embedding screenshots directly into vectors
By
–
True if you round-trip through OCR to markdown, that's where the token cost piles up. But PixelRAG skips that. The screenshot gets embedded straight into a vector for retrieval, no image to text step in the pipeline. The VLM only reads pixels at the end, on the few tiles it
-
RAG stacks still convert pages to text, but vision models are catching up
By
–
Same, you'd think it was the default by now. But most RAG stacks still parse pages to text first, mostly because vision models were too slow and pricey to run at scale until pretty recently. That window is closing fast now.
-
Small random recurrent net contains function, train only output layer
By
–
A small randomly connected recurrent net tends to bubble around chaotically and often contain the function you are looking for, and you can find it by training only an output layer. That's the basic idea
-
Google’s X, Brain, and Cerebra before DeepMind integration
By
–
google had x, brain and cerebra before it all got deepminded
-
Andrej Karpathy’s 2018 talk on Building the Software 2.0 Stack
By
–
The talk is "Building the Software 2 0 Stack (Andrej Karpathy)" 2018
-
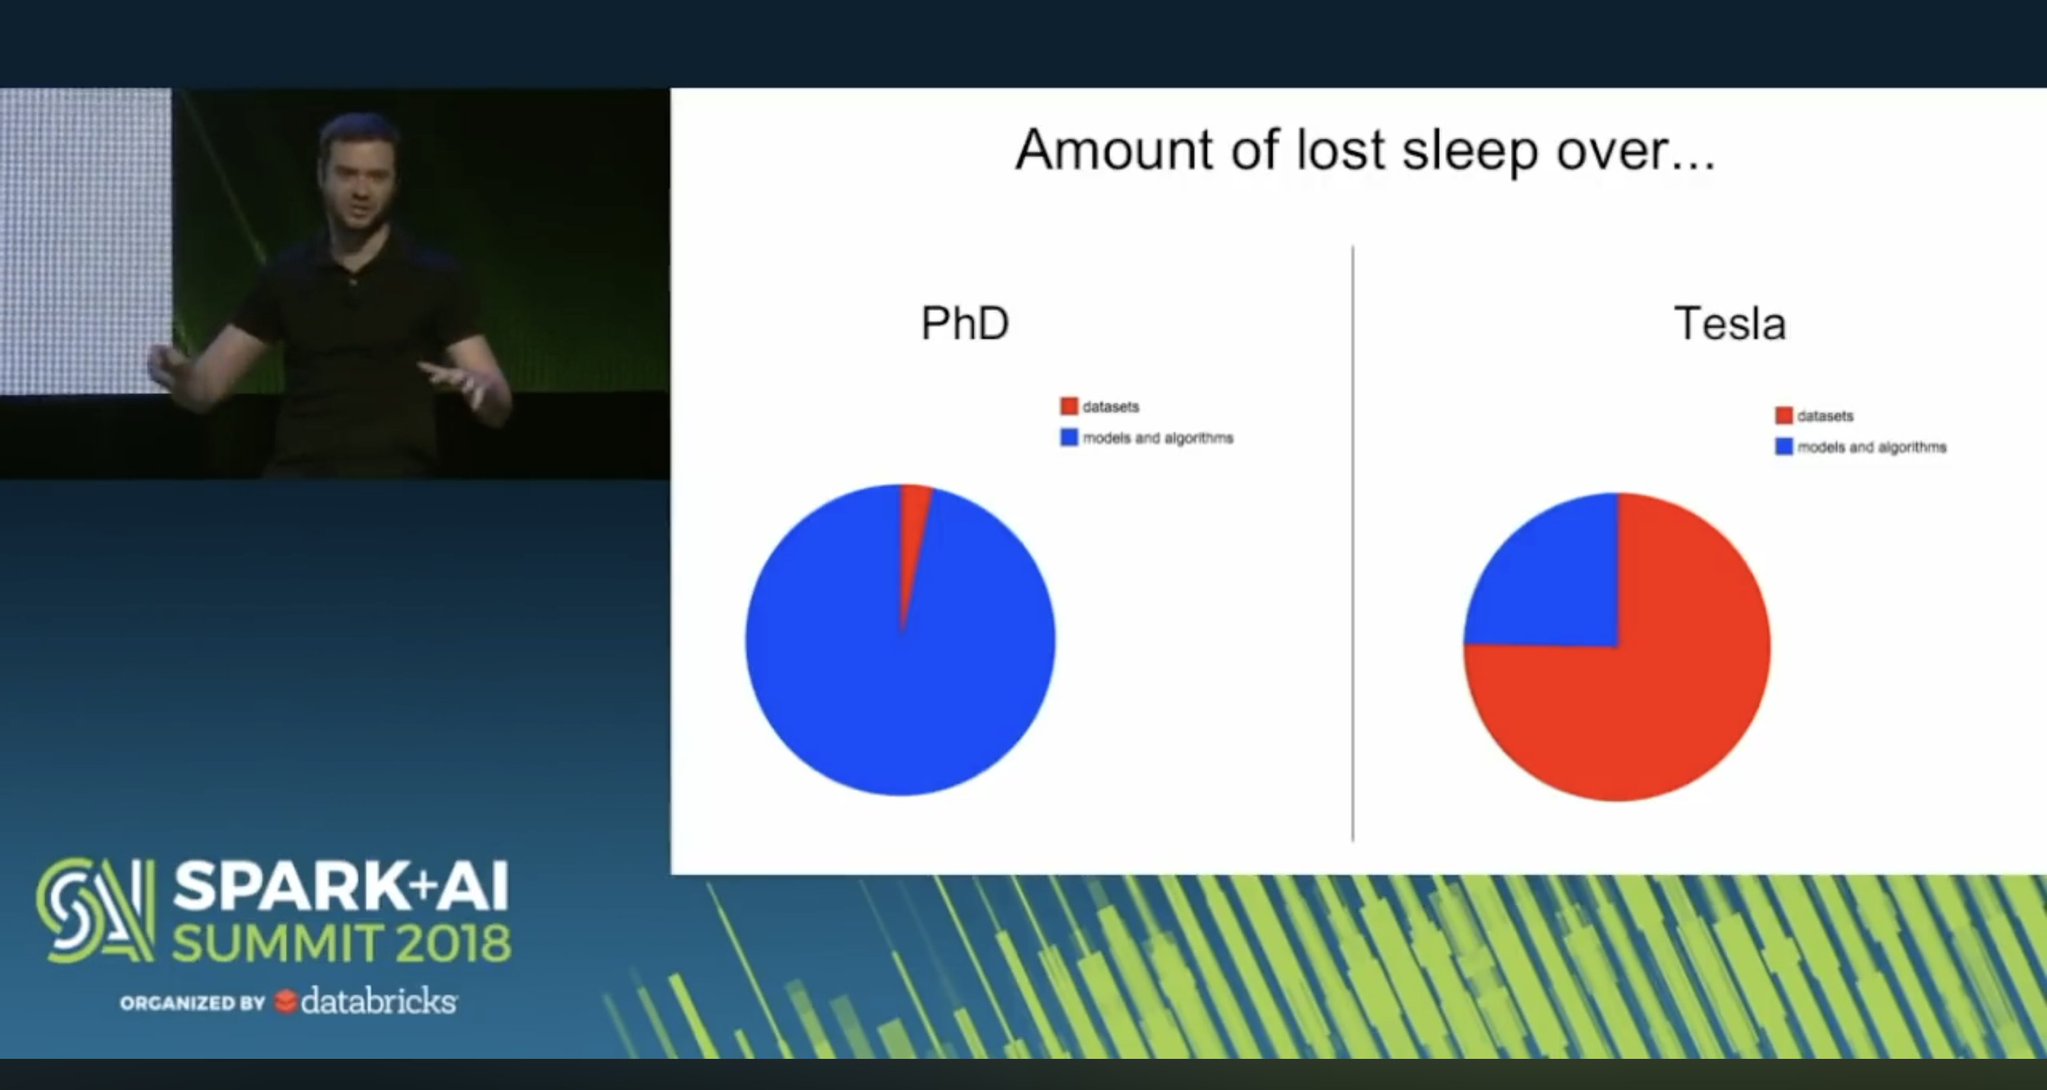
Karpathy: PhD sleep lost over models, industry over datasets
By
–
There is this 2018 talk of Andrej Karpathy comparing his PhD time spent vs Tesla old days. PhD: sleep lost over massaging models and algorithms
Tesla(industry): sleep lost over massaging datasets In reality it is always about data and evals/your mechanism of evaluating the