This sounds a bit more humble than the recent 1M or 1B context lengths claims. But this requires only minimal (1000 steps) finetuning. And it allows long document summarization using LLaMA 7B and 65B models, for example. Link to the paper here: https://
arxiv.org/abs/2306.15595 3/3
MACHINE LEARNING
-
Humble approach to long context lengths with minimal finetuning
By
–
-

Extending Transformer LLMs Context Window via Positional Interpolation
By
–
In the last couple of days, we talked a lot about extending the context window of transformer LLMs. Here's one more: "Extending Context Window of Large Language Models via Positional Interpolation" 1/3
-
AI Democratizes Healthcare by Providing Everyone Access to Best Doctors
By
–
How To Democratize Healthcare: AI Gives Everyone The Very Best Doctor
#AI #AIio #BigData #ML #NLU #Futureofwork @TunstallAsc @StrategyFintech @TamaraMcCleary @TerenceLeungSF @psb_dc @thomaspower @vinod1975 @ylecun http://
ow.ly/8VTC30sw8oT -

Impressive Open Source LLM Performance with Creative Poetry Generation
By
–
The results are very impressive. You can quickly see why it's the best performing open source LLM. "Write a poem about open source machine learning in the style of Byron."
-
Data Science Interview Questions and Answers
By
–
GitHub – youssefHosni/Data-Science-Interview-Questions-Answers: Curated list of data science interview questions and answers
https://bit.ly/42FHnF3 #AI #MachineLearning #DeepLearning #LLMs #DataScience -
Zero-Sum Performance Trade-offs in Attention Mechanisms
By
–
Yeah but my guess is it’s a zero sum issue. Like if you fixing the performance in the middle, you will probably have to sacrifice performance elsewhere. Otherwise if you pay attention to everything equally, you’ll lose the advantage of attention in a way.
-
Rebooting Tech Talent in the Race for Artificial Intelligence
By
–
Rebooting Tech Talent In The Race For AI
#AI #AIio #BigData #ML #NLU #Futureofwork @TopCyberNews @SpirosMargaris @MarshaCollier @MHiesboeck
@MHcommunicate @Fisher85M @MikeQuindazzi @NealSchaffer
http://
ow.ly/bmP630sw8oR -
Bookmarking Key Papers on Learning and Vision-Language Models
By
–
@chelseabfinn on learning to learn with gradients. I bookmarked it and hope to read it sometime: https://
ai.stanford.edu/~cbfinn/_files
/dissertation.pdf
… Also @karpathy on connecting images and texts, which was ahead of time given current progress in visual language learning: https://
cs.stanford.edu/people/karpath
y/main.pdf
… -
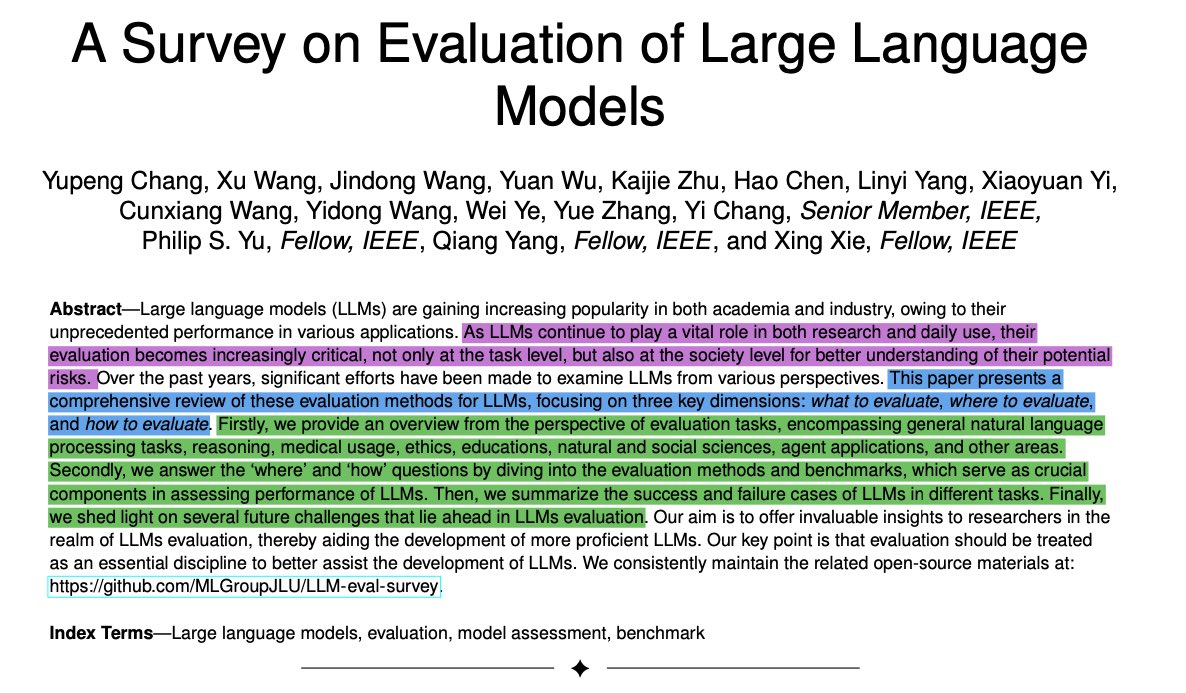
Comprehensive Survey on Large Language Models Evaluation Methods
By
–
A Survey on Evaluation of Large Language Models A comprehensive survey of evaluation methods for LLMs. Focus on “what, where and how to evaluate”. Also shed light on success and failure cases of LLMs in different tasks, and future challenges. Paper: https://
arxiv.org/abs/2307.03109 -
Hyena Convolutional LLMs: Efficient Alternative to Transformers
By
–
Hyena convolutional LLMs look interesting. Not necessarily better but matches the performance more or less. It’s different but more efficient. We will see if this will get more interest vs continuing the transformer route.