This year Toronto, ON hosts the @aclmeeting
. Google Research has a strong presence at #ACL2023 with over 50 accepted papers and participation in a number of workshops and tutorials. Find the full list at https://
goo.gle/3JPAx9p
MACHINE LEARNING
-
Google Research Showcases 50+ Papers at ACL 2026 Toronto
By
–
-
LLM learns patterns from training data representation
By
–
Yeah exactly, I think that’s where the LLM gets this from (ie this pattern being represented in the training data)
-
India’s AI University Initiative Launches Machine Learning Programs
By
–
@universalaiuniv @FinancialXpress @_DigitalIndia @GoI_MeitY @NeGD_GoI @nasscom #ai #aiuniversity #MachineLearning #INDIAai
-
Vector Databases and AI Infrastructure in India
By
–
@jeevprabnivash @vespaengine @qdrant_engine @SingleStoreDB @_DigitalIndia @GoI_MeitY @NeGD_GoI @nasscom #vector #Database #DataAnalytics #machinelearning #INDIAai
-
Vector Databases Power for Large Language Models
By
–
Discover the power of vector databases for Large Language Models! Vector databases can find visually similar images, comparable documents, and enhance your data analysis capabilities with ease. Read more to explore the world of vector databases: https://
rb.gy/t9p6e -
India’s AI and Machine Learning Education Initiative
By
–
@PMOIndia @dpradhanbjp @EduMinOfIndia @_DigitalIndia @GoI_MeitY @NeGD_GoI @nasscom #ai #education #MachineLearning #INDIAai
-
Product Hunt Launches for Machine Learning Community
By
–
Bringing Product Hunt to the ML community!
-

Generalization Gap in Visual Robotic Imitation Learning
By
–
Decomposing the Generalization Gap in Imitation Learning for Visual Robotic Manipulation paper page: https://
huggingface.co/papers/2307.03
659
… What makes generalization hard for imitation learning in visual robotic manipulation? This question is difficult to approach at face value, but the -
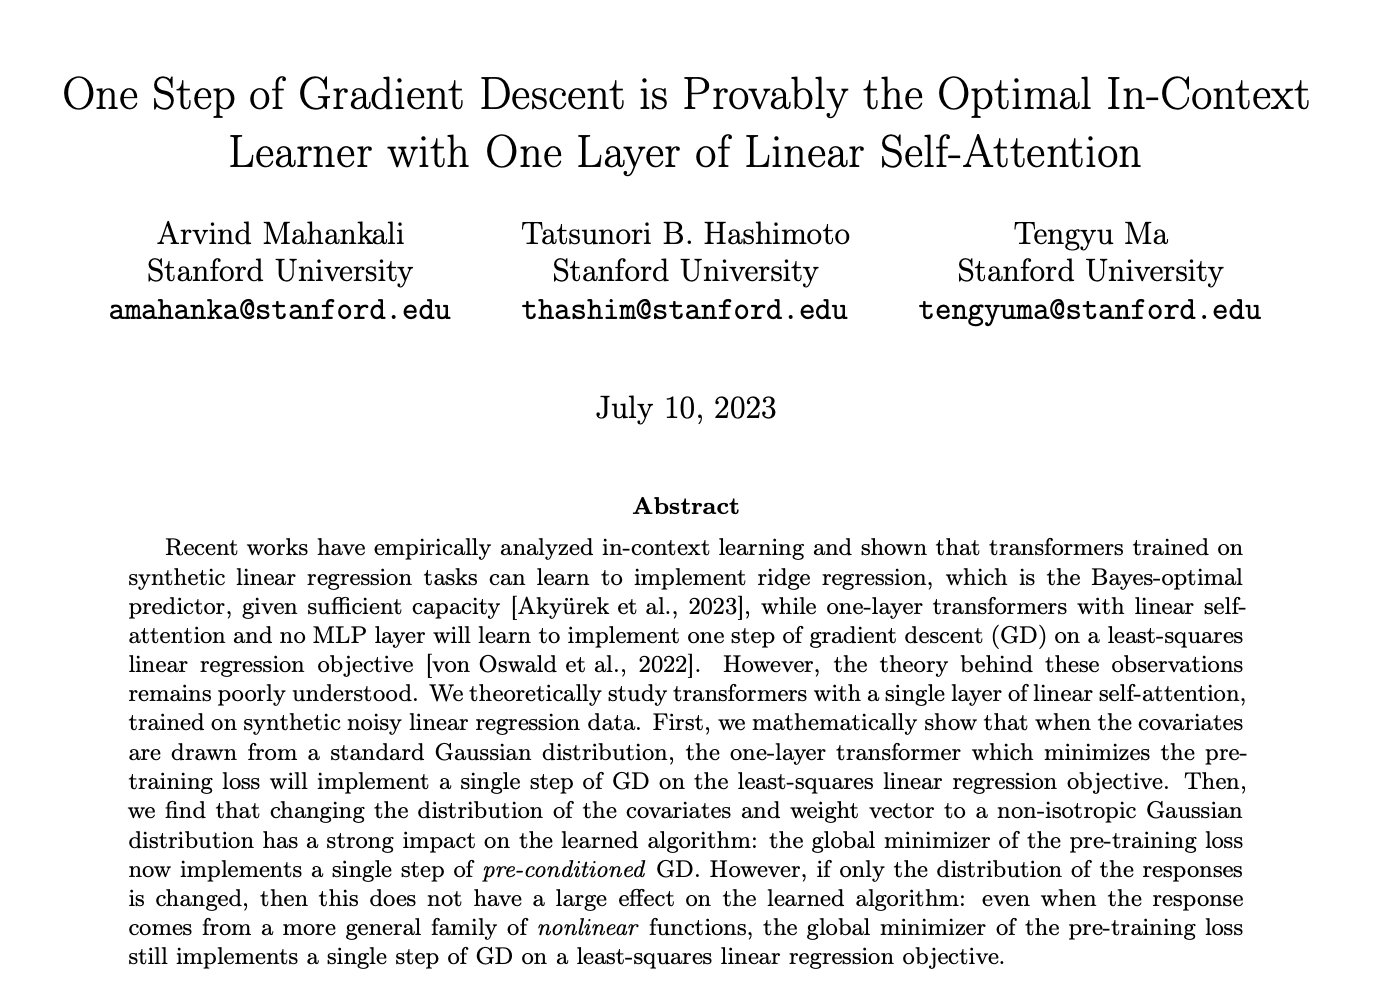
Gradient Descent as Optimal In-Context Learner in Linear Self-Attention
By
–
One Step of Gradient Descent is Provably the Optimal In-Context Learner with One Layer of Linear Self-Attention paper page: https://
huggingface.co/papers/2307.03
576
… Recent works have empirically analyzed in-context learning and shown that transformers trained on synthetic linear regression -
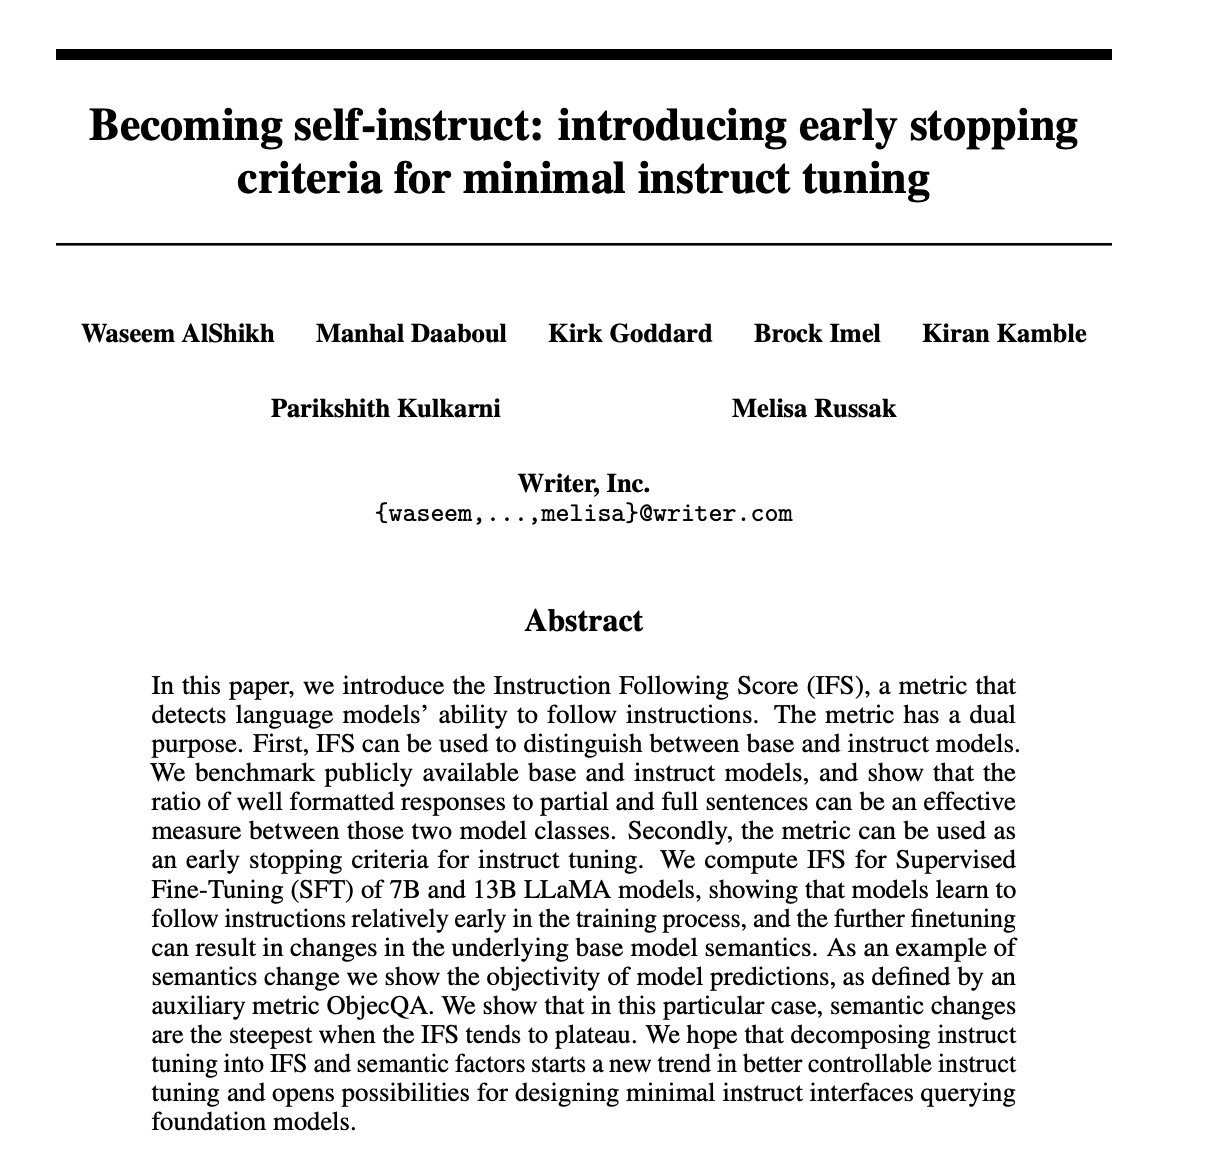
Self-Instruct: Early Stopping for Minimal Instruction Tuning
By
–
Becoming self-instruct: introducing early stopping criteria for minimal instruct tuning paper page: https://
huggingface.co/papers/2307.03
692
… introduce the Instruction Following Score (IFS), a metric that detects language models' ability to follow instructions. The metric has a dual purpose.