GPT4RoI: Instruction Tuning Large Language Model on Region-of-Interest paper page: https://
huggingface.co/papers/2307.03
601
… Instruction tuning large language model (LLM) on image-text pairs has achieved unprecedented vision-language multimodal abilities. However, their vision-language
MACHINE LEARNING
-

GPT4RoI: Instruction Tuning LLM on Region-of-Interest
By
–
-

BiPhone: Modeling Inter Language Phonetic Influences in Text
By
–
BiPhone: Modeling Inter Language Phonetic Influences in Text paper page: https://
huggingface.co/papers/2307.03
322
… A large number of people are forced to use the Web in a language they have low literacy in due to technology asymmetries. Written text in the second language (L2) from such users -
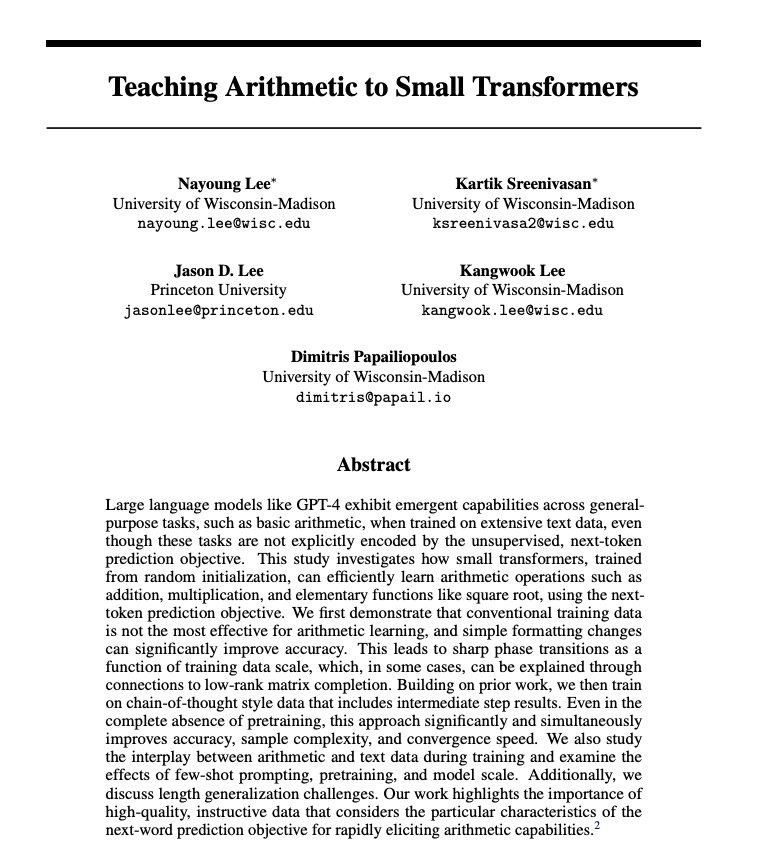
Teaching Arithmetic to Small Transformers
By
–
Teaching Arithmetic to Small Transformers paper page: https://
huggingface.co/papers/2307.03
381
… Large language models like GPT-4 exhibit emergent capabilities across general-purpose tasks, such as basic arithmetic, when trained on extensive text data, even though these tasks are not explicitly -
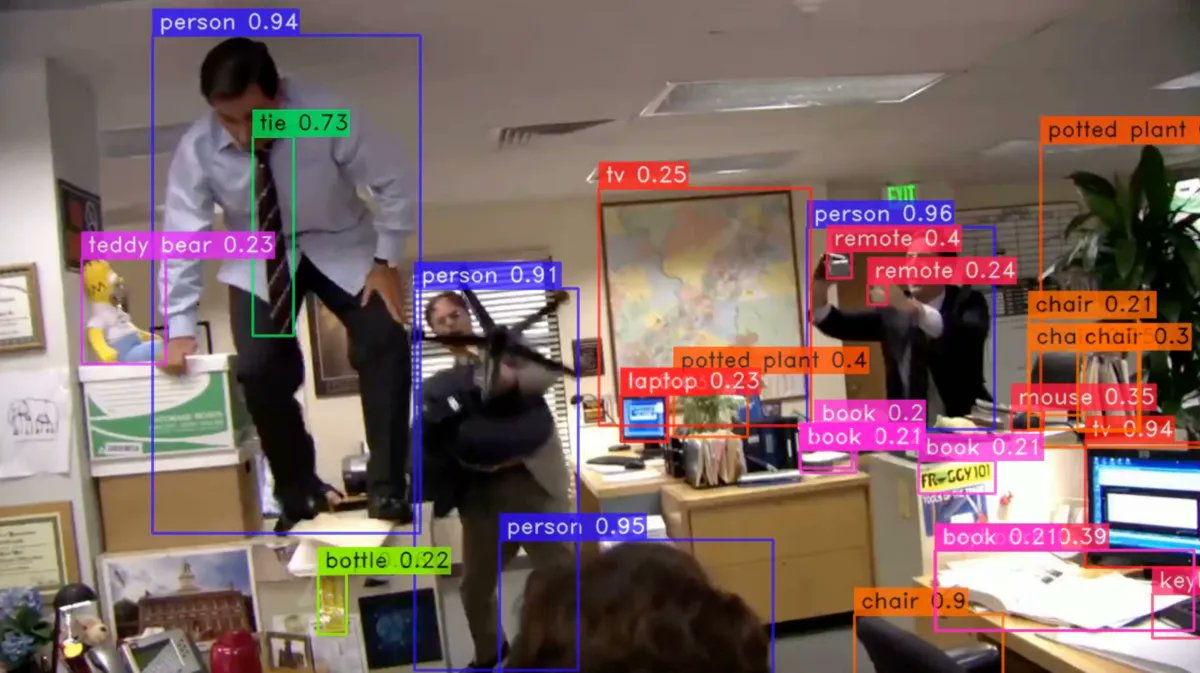
Computer Vision Newsletter #33: Artificial Intelligence and Deep Learning
By
–
Computer Vision Newsletter #33
https://bit.ly/3BImZrO #AI #MachineLearning #DeepLearning #LLMs #DataScience -
Harmonizing Human Creativity With Machine Learning
By
–
How To Harmonize Human Creativity With Machine Learning
#AI #AIio #BigData #ML #NLU #Futureofwork @chrismessina @ChristopherIsak @davidwkenny @debashis_dutta @petitegeek @fabiomoioli @GaryMarcus @asokan_telecom http://
ow.ly/7R9x30sw8B4 -
Sebastian Raschka Arrives in Austin for SciPy Conference Workshop
By
–
Just arrived in Austin and looking forward to attending SciPy once more! Ready and excited for my workshop on “Modern Deep Learning with PyTorch” tomorrow! https://
github.com/rasbt/scipy202
3-deeplearning
… -
Prompt and Process with Ethan Mollick AI Miniseries
By
–
Prompt and Process with Ethan Mollick (AI Miniseries)
#AI #GenerativeAI #machinelearning
CC @Khulood_Almani @amalmerzouk @Analytics_699 @MargaretSiegien @baski_LA @Shi4Tech @CurieuxExplorer @KanezaDiane @ChuckDBrooks @FrRonconi @ingliguori @efipm https://
open.spotify.com/episode/4kbOCD
FbFqYLZpmLHEsAsD?si=uesawsgsS22m6izDVucMPw
… -

CS25: Transformers United – Stanford Machine Learning Course
By
–
CS25: Tranformers United! https://
stanford.io/466ZfLT #AI #MachineLearning #DeepLearning #LLMs #DataScience -
Focusing on Improving Modeling Performance Over Computational Performance
By
–
*the focus here is on improving modeling performance, not computational performance.
-
Position Interpolation Extends RoPE Context Windows to 32K Tokens
By
–
Rotary positional embeddings (aka RoPE) have been a recent cornerstone of modern LLM implementations since it supports flexible sequence lengths. In this paper, researchers propose Position Interpolation to increase RoPE-based context window sizes to 32,768 tokens 2/3