That's true, but you still have positional embeddings, and Q and K weights that are learned
MACHINE LEARNING
-
Fine-tuning RoBERTa for Sentiment Classification to 95% Accuracy
By
–
Then, you can boost that performance (on the same movie review sentiment classification dataset) to ~95% finetuning model = AutoModelForSequenceClassification.from_pretrained( "siebert/sentiment-roberta-large-english", num_labels=2)
-
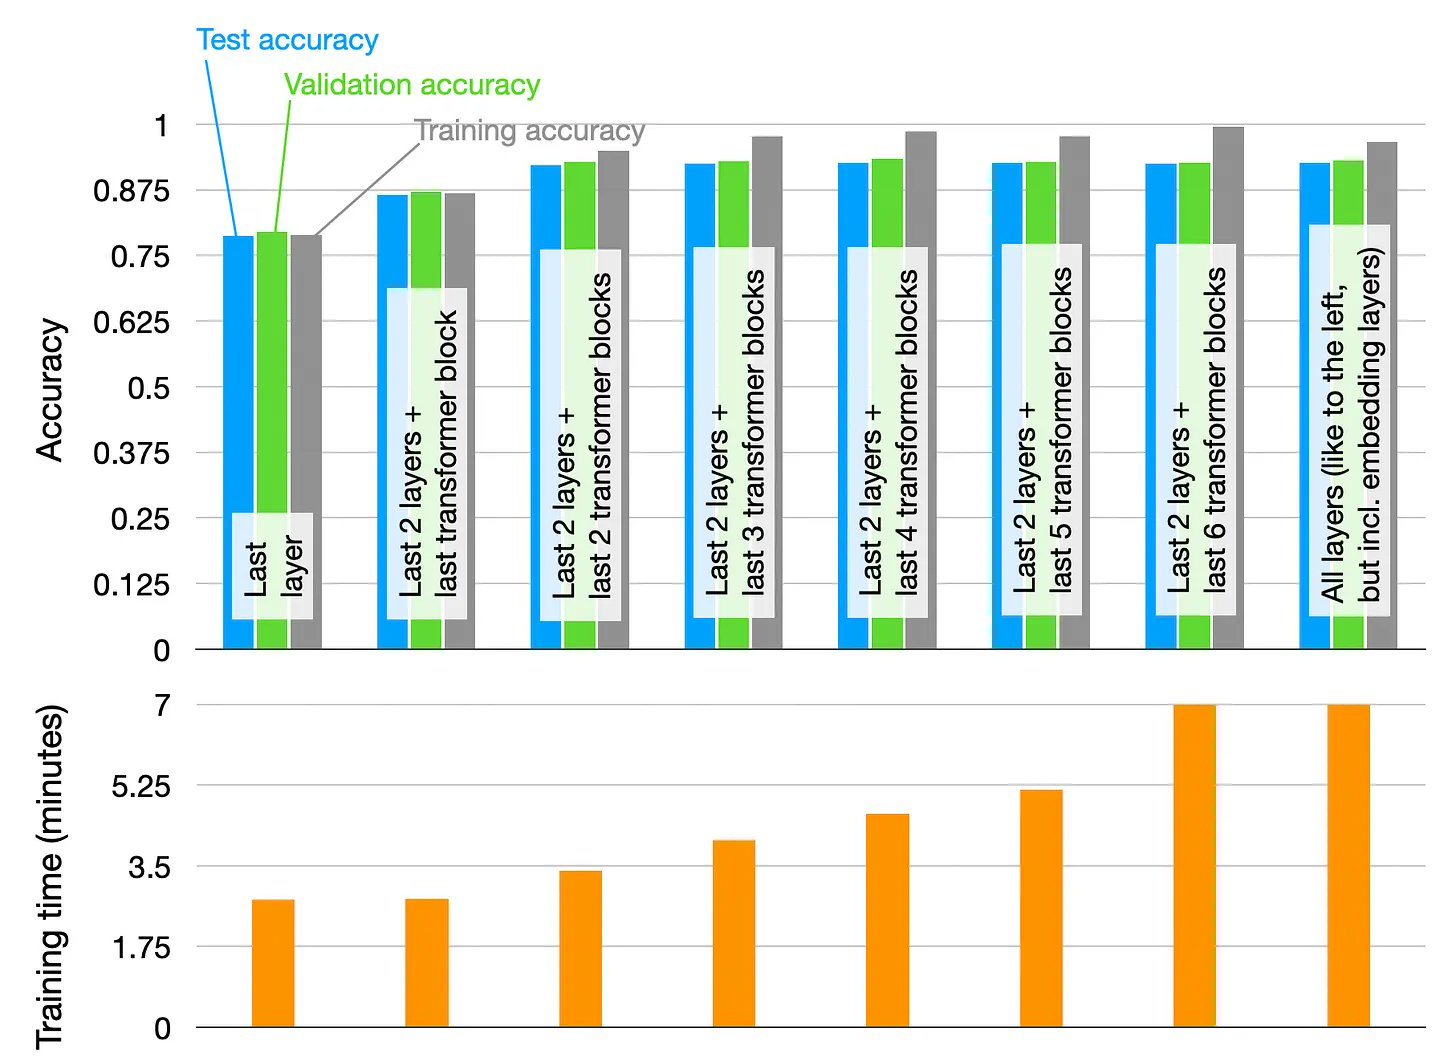
Ditching Word2Vec for Superior LLM Embeddings in Classification
By
–
I would ditch Word2Vec; the embeddings learned by LLMs are much better. For sentiment classification, you can start with DistilBERT as a base model and tune a few layers (see https://
magazine.sebastianraschka.com/p/finetuning-l
arge-language-models
…) 1/2 -

Probabilistic Machine Learning: Comprehensive Guide to Generative AI
By
–
Probabilistic #MachineLearning #GenerativeAI #AI @Khulood_Almani @Analytics_699 @GlenGilmore @MargaretSiegien @sallyeaves @baski_LA @ChuckDBrooks @HakomTimeSeries @labordeolivier @BetaMoroney @SabineVdL @KanezaDiane @MaiaGabunia @amalmerzouk https://
probml.github.io/pml-book/book2
.html?s=09
… -
RNN-based LLMs and information retention patterns
By
–
This is quite interesting … 1) I would expect that the opposite is true for, e.g., RNN-based LLMs like RWKV (since it's processing information sequentially, it might rather forget early information) 3/5
-
Transformer Architecture and Middle Document Retrieval Performance Bias
By
–
2) To my knowledge, there is no specific inductive bias in transformer-based LLM architectures that explains why the retrieval performance should be worse for text in the middle of the document. 4/5
-
LLM Attention Weights: Training Data Structure and Human Writing Patterns
By
–
I suspect it is all because of the training data and how humans write: the most important information is usually in the beginning or the end (think paper Abstracts and Conclusion sections), and it's then how LLMs parameterize the attention weights during training. 5/5
-
Long Context LLMs: Promise and the Middle Information Problem
By
–
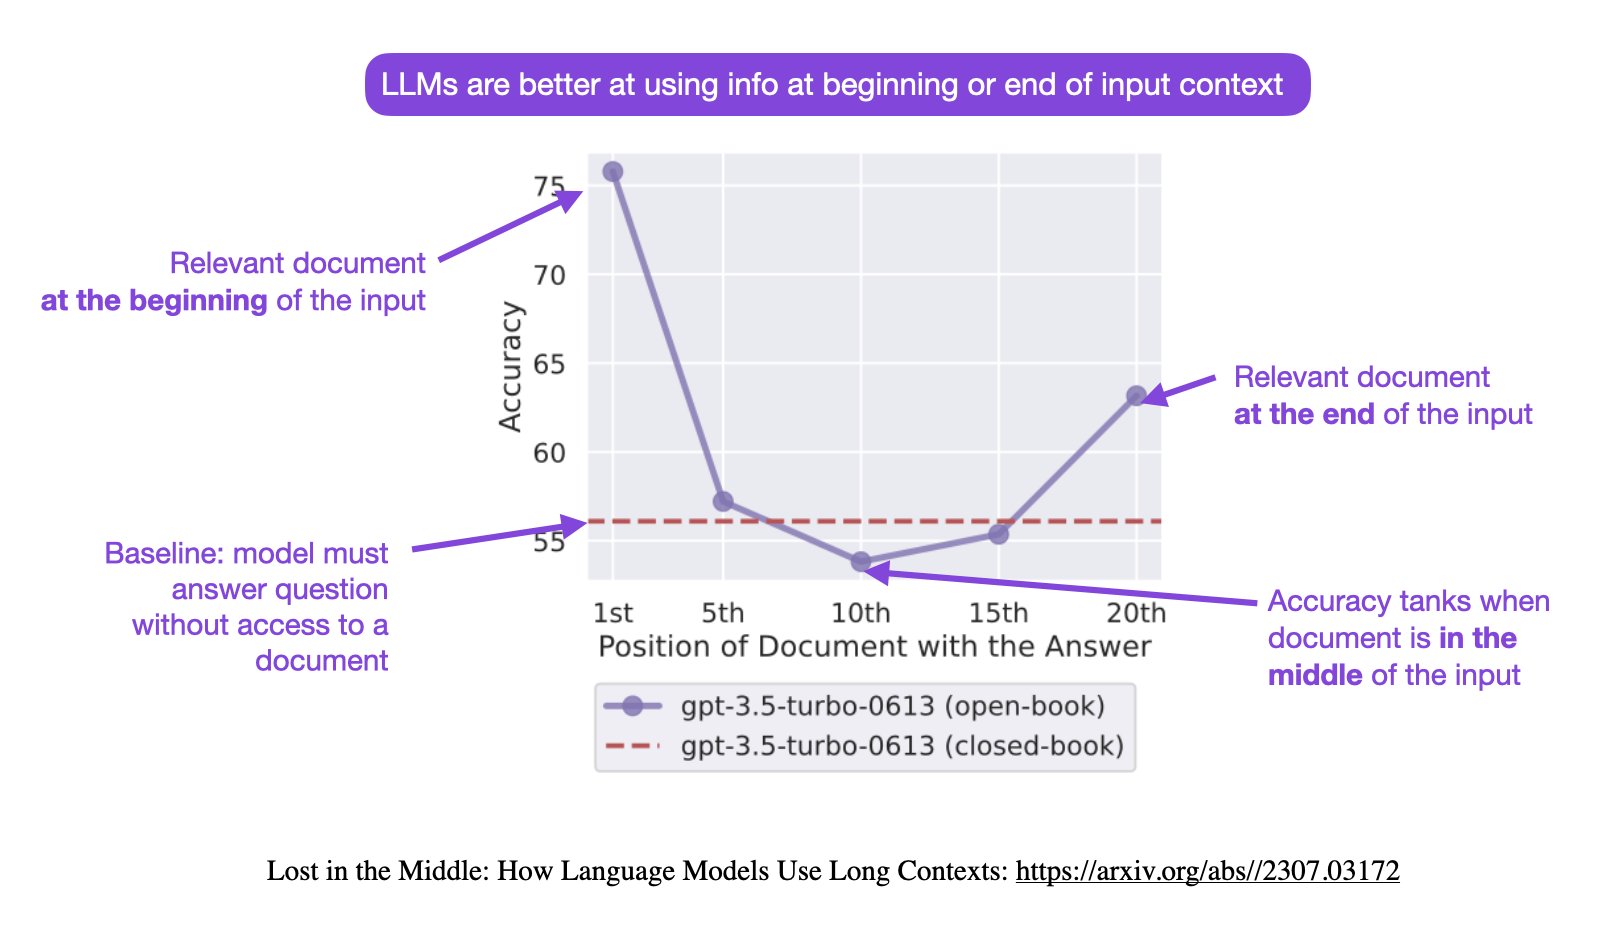
We have seen a new wave of LLMs for longer contexts: 1) RMT, 2) Hyena LLM & 3) LongNet There are several use-cases for such long LLMs but the elephant in the room is: How well do LLMs use these longer contexts? Turns out not so well if info is in the middle of the input.
1/5 -
LLMs Struggle Retrieving Information from Document Middle
By
–
According to "Lost in the Middle: How Language Models Use Long Contexts" (
https://
arxiv.org/abs/2307.03172) LLMs are good at retrieving information at the beginning of documents. They do less well in terms of retrieving information if its contained in the middle of a document. 2/5